The 95 Billion Dollar Dinner Plate Chip
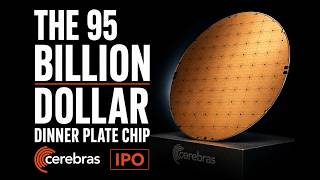
Cerebras Systems built a dinner-plate-sized chip with 4 trillion transistors that runs AI inference 21 times faster than NVIDIA's best GPU at one-third the cost. The WSE-3 solves the 80-year yield problem by cramming 970,000 cores onto a single die with 44 GB of on-chip memory. The company just IPO'd at $95 billion and signed a $20 billion deal with OpenAI.
Chapters
You know, when we usually picture a computer chip, our brains instantly default to this, um, this tiny, delicate little square of silicon.
Right, yeah, like a fingernail.
Exactly. You know the kind. Something you'd practically need a pair of tweezers to hold. It's this microscopic piece of engineering tucked away under a massive cooling fan inside your laptop.
Well, and that's the mental model we've all been conditioned to accept, right? Since the the dawn of personal computing, really. I mean, miniaturization has always been the absolute goal.
Right. Smaller is better.
Huh.
But today, I want you to completely erase that image from your mind.
Oh, totally.
Instead, I want you to picture a single, solid, unbroken piece of silicon, but it's the size of a dinner plate.
A literal dinner plate.
Yeah. A massive, gold-colored square stretching over 8 inches across.
It genuinely looks like a prop from a science fiction film. I mean, when you look at the physical object, it just, it doesn't compute with our current technological reality. It's completely alien.
It really is. And honestly, when the engineers first plugged this massive plate of silicon in for a test run, it literally went up in smoke.
Yeah, that's a true story.
It caught fire in the lab. They had to calmly report it to their board of directors as a thermal event.
A thermal event, which is just a masterclass in corporate understatement. You know?
Nothing to see here.
It's a very polite way of telling their investors, hey, we might be violating violating the fundamental laws of thermodynamics.
But here is why you listening right now need to care about that massive, sometimes flaming dinner plate of silicon.
Yeah.
Because the company that built it, Cerebras Systems, just recently took that exact same technology to Wall Street.
And the result was staggering.
Yeah. They triggered a jaw-dropping $95 billion public debut. Wow. We are talking about the biggest US tech IPO since Snowflake.
It's an absolutely massive valuation for a hardware company. And the crazy thing is it's entirely built on a piece of technology that fundamentally challenges, well, basically how we have built computers for the last 80 years.
So whether you are prepping for a major tech strategy meeting this week, or, you know, you are just insanely curious about the future of artificial intelligence and the massive physical engines that actually run it. Exactly. This deep dive is for you. We are bypassing all the dense engineering jargon today to get straight to the aha moments. We want to understand what a $95 billion idea actually looks like under a microscope.
We've got a really fascinating mission today. We are going to explore exactly how Cerebras broke an 80-year-old rule of semiconductor physics.
Which is wild.
Yeah, solving something called the yield problem, which the entire industry literally considered physically impossible.
And we're also gonna look at why this giant chip design solves the single biggest bottleneck in AI today. Plus, we'll dig into the mechanics of their staggering $20 billion relationship with OpenAI.
Right. And because we have to look at the full picture here, we are going to dive into the intense debate happening right now among retail investors.
The skeptics.
Exactly. The debate about whether Cerebras can truly take on the undisputed multi-trillion-dollar king of AI hardware, Which is of course NVIDIA.
It is a classic David versus Goliath story. But in this case, David's slingshot is a 46,000 square millimeter processor packing 4 trillion transistors.
That's a big slingshot.
Okay, let's unpack this because before we can even begin to understand a $95 billion valuation, we have to understand the fundamental law of physics they had to break.
Right.
And to do that, we need to look at the physical reality of how every other chip on the planet is actually made. Like the actual manufacturing process?
Well, let's start with the standard recipe for semiconductor manufacturing. I mean, it's a process that has been refined over decades by companies like TSMC and Intel.
Okay.
You start with a raw circular silicon wafer. It's usually about 300 millimeters across. So picture a perfectly mirrored 12-inch vinyl record, but made of pure silicon.
Okay. I've seen pictures of those. And then you basically, um, you use light to draw on it, right?
In essence, yeah. It's called photolithography.
Yeah.
You run that circular wafer through hundreds of incredibly complex fabrication steps.
Uh-huh.
You're using extreme ultraviolet light to etch microscopic transistor patterns onto the silicon. You are basically building complex 3-dimensional cities of logic gates at an atomic scale.
Right. But once that 12-inch wafer is fully processed, once all those little cities are built, nobody uses the whole circle.
No, absolutely not.
The standard practice is to chop it up. You slice it into hundreds of tiny, individual rectangular chips.
You dice it, then you test those tiny rectangles, package the good ones, and well, those become the processors inside your phone or your laptop or the massive server farms running the internet.
So if we look at NVIDIA's flagship AI chip, the H100, that is considered a massive, powerful chip by traditional standards.
Very much so.
Our sources say the H100 die is 814 square millimeters.
Right. And that is considered absolutely massive in the traditional semiconductor world. In fact, 814 square millimeters pushes right up against what the industry calls the reticle limit.
Okay, wait, reticle limit? Let me guess, that's the physical limitation of the manufacturing equipment.
Yes.
Like the lens can only focus light onto a canvas of a certain size before it gets blurry at the edges.
That is a highly accurate way to think about it, actually. The lithography machines that project the light patterns, they can only expose an area of roughly 850 square millimeters in single flash.
Oh, wow.
So NVIDIA essentially maxed out the canvas size allowed by the standard machinery.
Okay. But 814 square millimeters is still just a small fraction of that whole 300-millimeter circular wafer.
Very small.
So the obvious question here is why slice it up at all? I mean, if you are an AI company and you were desperate for more compute power, why didn't NVIDIA or Intel just say, hey, let's leave the whole 12-inch wafer intact. Let's not cut it up. Let's just wire it all together and use it as one giant super chip.
Right. It seems like the obvious solution, but they didn't because of a fundamental roadblock known in the industry as the yield problem.
The yield problem.
Yes. This is the 80-year-old rule of semiconductor physics we are talking about. You have to consider the environment where these chips are fabricated.
They're building clean rooms, right?
Pristine clean rooms, hundreds of times cleaner than a hospital operating room. But, you know, perfection is physically impossible at the atomic scale.
Like dust particles or microscopic impurities in the silicon itself.
Exactly. Tiny lithography alignment errors, maybe a stray molecule of photoresist. They just happen. Defects are just a mathematical reality of manufacturing at the nanometer scale.
Right.
And historically, the rule of thumb was brutally simple. Bigger chips mean worse yields.
Okay, that makes sense. Because if I have a tiny chip, say the size of a postage stamp, and a microscopic defect lands on it during manufacturing, I just throw that one broken chip in the trash.
Exactly.
But the other 300 postage stamps I cut from that same wafer are probably completely fine.
And that is the entire economic foundation of the semiconductor industry right there. You expect to throw some away. But if you try to make your chip bigger, say the size of a playing card, the probability that a random defect will land somewhere on your chip increases dramatically. Ugh.
I see where this leads. So if your chip is the entire 12-inch wafer—
The chance of getting a perfect, defect-free wafer is essentially zero.
Wow.
It is statistically impossible. A single microscopic defect, literally one stray molecule, would ruin the entire dinner plate.
And you'd have to throw the whole thing out.
Right. Therefore, a wafer-scale chip was considered economically and physically impossible. The yield, which is the percentage of usable products you get off the manufacturing line, would be zero. You'd go bankrupt trying to sell them.
So Cerebras looked at this 80-year-old ironclad rule of physics and economics, and they were just like, we're doing it anyway.
Pretty much.
They left the wafer whole. They inverted the entire paradigm. They were taking that 300mm circular wafer and cutting the largest possible square out of it. It is a single unbroken piece of silicon measuring 46,225 square millimeters.
Yeah. And just to put that into stark perspective, that is roughly 56 times larger than NVIDIA's H100.
56 times.
56 times the physical area.
But wait, if perfection is impossible and they know defects are going to happen on a canvas that massive, how is this a viable business? How do they not just throw every single 46,000 square millimeter wafer in the trash?
Well, what's fascinating here is how they completely reimagined the architecture. They didn't try to achieve impossible perfection in manufacturing.
They didn't build cleaner cleanroom.
No. Instead, they designed a system that assumes defects are a guaranteed reality and they simply route around them. The secret is Extreme microscopic defect tolerance.
Okay, let me stop you there because NVIDIA and AMD use defect tolerance too, right? I mean, that, that isn't a new concept. If NVIDIA chip has a broken part, they just turn it off.
They do. Modern GPUs are entirely designed with redundant processing cores. Take that NVIDIA H100 we mentioned. Physically, the silicon is etched with 144 cores, what NVIDIA calls streaming multiprocessors or SMs.
Right.
But the commercial product they actually sell to a data center only requires 132 of those cores to be active.
Ah, so if a speck of dust hits the chip during manufacturing and it kills one or two of those cores, NVIDIA just permanently disables the broken ones.
Exactly.
They can still sell the chip as a top-tier H100 because they only needed 132 to work in the first place.
That is core-level redundancy. It saves millions of dollars in discarded silicon.
Yeah.
But here's the critical difference in scale. An H100 core is relatively large. If a defect hits it, you lose a substantial chunk of valuable silicon real estate.
Okay.
Cerebras took this concept and pushed it to an absolute extreme. Before they committed to building the giant wafer, they designed an entirely new microscopically small AI core.
How small? Give me the dimensions here.
Each individual compute core on the latest Cerebras wafer-scale engine, the WSE-3, is about 0.05 square millimeters.
0.05 square millimeters. Wait, so if the NVIDIA core is large, this Cerebras core is what, maybe 1% the size?
Roughly 1% the size of an NVIDIA H100 core. Yes. It is a tiny, highly specialized unit of math processing.
Wow.
And because they are so astonishingly small, Cerebras can fit an unfathomable number of them onto their giant 46,000 square millimeter canvas. The WSE-3 has 970,000 of these microscopic fault-tolerant cores.
Nearly a million distinct processing cores on one plate of silicon. That number is hard to even wrap your head around. But I think I see the mathematical genius here. If you have nearly a million cores, your redundancy buffer must be massive.
It completely flips the math of the yield problem upside down. Out of those 970,000 physical cores baked into the silicon, they only need 900,000 to actually pass inspection.
To sell the product as fully functional.
Right. That gives them 70,000 spare cores to play with across the wafer. Oh!
So if a defect like a speck of dust or an etching error hits the Cerebras wafer, it doesn't knock out a massive chunk of the processor, it just kills one microscopic 0.05 square millimeter core.
Exactly. Let's look at the data from our sources for an apples-to-apples comparison. This is on TSMC's 5-nanometer manufacturing process.
Okay.
Say you have a standard defect rate on a wafer. If you manufacture 72 traditional GPUs on that circular wafer, those defects might knock out 361 square millimeters of total die space across the entire batch.
Because each defect ruins a much larger core.
Right.
Okay. So you lose 361 square millimeters of valuable silicon to the trash can.
But on the single Cerebras wafer, applying that exact same defect rate, they only lose about 2.2 square millimeters of total silicon area.
Wait, 2.2 versus 361?
Yes.
The traditional GPU approach actually loses over 160 times more silicon area to defects than the Cerebras approach, simply because the Cerebras blast radius for a defect is so tiny.
That's the math. And because of this microscopic architecture, Cerebras achieves an astonishing 93% silicon utilization on their final shipped product.
That's incredible.
It is actually a higher utilization rate than the leading traditional GPUs today, despite Cerebras building the physically largest chip in human history.
Okay, so the math makes sense for the physical real estate, but having 70,000 spare cores is only half the battle, right? This is a computer processor. Data has to flow.
Yes.
If I have a million cores arranged in a huge grid and a random hundred of them are dead because of dust particles, how do the working ones talk to each other? Doesn't the data just hit a dead end?
This is perhaps the greatest engineering triumph of the WaferScale engine. It's their routing architecture. The communication fabric connecting all 970,000 cores isn't just a dumb set of wires. It is intelligent. At the hardware level.
Wait, how does hardware have intelligence before the software even loads?
Through built-in logic gates embedded directly into the physical interconnect wires. When you first plug the Cerebras system into the wall and supply power, the hardware conducts a localized heartbeat check.
Like a diagnostic?
Yes. Every single core sends a ping to its immediate neighbors.
It's taking roll call.
A microscopic roll call. And if a core doesn't respond because a defect ruined it, the surrounding interconnects use hardware multiplexers to dynamically reconfigure the communication pathways.
Oh, wow.
They literally switch the tracks. They map out the entire wafer, identify the dead zones, and route the communication links around them.
So it dynamically routes around the broken physical hardware. Mm-hmm. And the software has no idea.
The software never sees it. The reconfiguration happens in a single clock cycle.
That's insane.
By the time you load your AI model onto the machine, the operating system just sees one massive, unified, perfectly working processor with 900,000 cores.
That is brilliant. It completely changes how you think about chip design. I mean, think of a traditional chip like a city with one massive central highway.
Okay, I like this.
If a giant sinkhole, a manufacturing defect, opens up in the middle of that highway, the whole city shuts down. You can't get to work. You have to abandon the city.
You throw the chip away.
Exactly. But Cerebras didn't build a highway. They built a sprawling city with a million tiny side streets. If a sinkhole appears on one block, the built-in traffic lights just naturally route the cars around the block without slowing down the overall flow. The city keeps functioning perfectly.
It's a highly resilient mesh network etched directly into a piece of silicon. The logic is elegant.
Okay, the logic is elegant on a whiteboard. But as incredible as that side street analogy sounds, I have to push back a little here.
Fair enough.
We are talking about 4 trillion transistors on one single unbroken plate.
Yeah.
4 trillion. You pump electricity into that. It's not just a routing problem. It's a massive plumbing problem. Electricity goes in, heat has to come out.
Yes, it does.
That sounds like a recipe for an absolute meltdown.
Yeah.
How does that not just melt through the floor of the data center?
And that deduction brings us perfectly to the messy physical reality of hardware startups. Mm-hmm. Because you are entirely correct to be worried about the heat. You can build all the side streets you want, but if the city is on fire, It doesn't matter.
Right.
And frankly, the engineers at Cerebras were terrified of the heat too.
Which leads us to the thermal event.
Yeah.
Because we move from the elegant theoretical physics of routing traffic around microscopic potholes straight into the visceral reality of things literally catching fire.
It is the harsh reality of taking an impossible idea out of the simulation phase and plugging it into a real 480-volt wall outlet. Running that much electricity through an unbroken 300-millimeter wafer generates a staggering, almost localized sun level of heat.
Let's talk about the team crazy enough to try this. Who looks at a dinner plate of silicon packing 4 trillion transistors and says, yeah, let's plug that in.
Well, the founding team wasn't a group of naive software developers. They were seasoned veterans in the deep hardware and systems space. We're talking Andrew Feldman, Gary Lauterbach, Sean Lai, Michael James, and JP Fricker. They officially founded Cerebras in 2015.
And Andrew Feldman, the CEO, his background is super interesting. Our sources from Foundation Capital point out that he basically grew up on the Stanford campus.
He did.
His dad was a professor and he spent his childhood just hanging around Nobel laureates in physics and math.
He was imprinted early on with an understanding of what true paradigm-shifting brilliance looks like. But beyond academia, he has a track record of severe entrepreneurial ambition.
Like what?
Before Cerebras, he and Gary Lauderbach founded a company called C-Micro, which was a pioneer in energy-efficient microservers. They eventually sold that company to AMD for $357 million.
Oh, wow.
And before that, Feldman was an executive at Force 10 Networks, which sold to Dell for $800 million.
So he's not a rookie taking a wild swing. He has, as Steve Fasalo from Foundation Capital described it in the sources, a massive chip on his shoulder and a heart full of disobedience. I love that specific phrasing.
It's perfect because it takes a profound level of disobedience to look at the entire multibillion-dollar semiconductor industry, Intel, TSMC, SMD, Samsung, and tell them, you've been cutting the pizza wrong for 80 years. Stop cutting it.
And remember the macroeconomic context of 2015 and 2016 when they were pitching this to venture capitalists on Sand Hill Road. Investors were terrified of semiconductor startups.
Absolutely terrified.
The previous wave of hardware investments in the 2000s had delivered nothing but spectacular capital-intensive losses. The prevailing wisdom in Silicon Valley was that Software eats the world and hardware is just a low margin commoditized race to the bottom. Mm-hmm.
Betting on a brand new custom-built hardware architecture was viewed as career suicide for a VC back then. Furthermore, in 2016, AI was still largely a research science project. It hadn't hit the mainstream enterprise yet.
Right. There was no ChatGPT.
Exactly. Researchers were using NVIDIA GPUs mostly by accident because they realized the parallel processing power intended for rendering video game graphics happened to be less terrible at matrix multiplication than standard CPUs.
Nobody had purpose-built a machine just for neural networks, but Foundation Capital backed them anyway, largely because of what they termed unreasonable ambition. Felbin wasn't pitching a 10% improvement on a GPU. He wanted to build a generational N-of-1 company.
So they secure the funding, they take up residence at Foundation Capital, they spend years figuring out the defect tolerance routing, they work with TSMC to manufacture the first giant wafer, and then they have to power it up.
And that's when the laws of thermodynamics thermodynamics pushback: the fire.
The first prototype literally went up in smoke on its initial power-up. As you mentioned in the intro, the engineering team calmly labeled this to their board of directors as a thermal event.
Which is just a masterful piece of corporate spin. We didn't have a massive electrical fire, Steve. We merely experienced a localized thermal event.
It is humorous in retrospect, but it highlights the sheer physical scale of the engineering problem they had to solve. To put real numbers to it, a single current-generation Cerebras CS-3 system requires about 23 kilowatts of power.
Wait, hold on. 23 kilowatts for one system? That is insane.
It's massive.
A powerful home space heater uses about 1.5 kilowatts. So you're basically running 15 massive space heaters at maximum blast and concentrating all of that thermal energy onto an area the size of a dinner plate.
And all of that electrical power turns directly into heat. You cannot cool 23 kilowatts of concentrated thermal mass with a standard computer fan blowing air across a heatsink.
No, the silicon would just melt.
It would melt into slag in seconds. Cerebras had to completely design a proprietary internal water cooling system. They route fluid directly across the back of the wafer to pull the heat away just to keep the chip from destroying itself.
The sources mentioned that the power dissipation numbers they were proposing were so audacious that foundation Foundation Capital actually called in a firm called Exponent.
Yes, Exponent is a highly specialized engineering and scientific consulting firm. Foundation Capital needed third-party confirmation that Cerebras wasn't literally trying to break the second law of thermodynamics.
Hey, can you guys check this math to make sure this startup isn't violating the fundamental laws of the universe? It's a hell of a due diligence call.
Well, as the investor Steve Vasalo noted, the true discipline of an elite engineer is knowing which rules you can bend, like the 80-year-old manufacturing yield rule, and which rules you absolutely have to respect, like the laws of physics and thermodynamics.
Right.
You can trick a manufacturing line, but you cannot trick heat.
And it wasn't just technical and physical hurdles they had to overcome. It was competitive ones. They were a tiny hardware startup going up against absolute giants with infinite resources. There was this great anecdote in the sources about Feldman's mindset during his SiMicro days that I think perfectly explains how Cerebras operates today in the shadow of NVIDIA.
Ah, you're referring to the Netone story. It's a classic example of asymmetric business warfare.
Exactly. So Feldman was trying to win a major enterprise deal with a massive Japanese channel partner called Netone, but his primary competitor for the deal was Cisco. Absolute goliath in the networking space.
Right.
And Cisco is out there wooing the Netone executives by putting them on private planes, taking them to lavish dinners, entertaining them on corporate yachts.
Classic enterprise sales tactics from an incumbent. Overwhelming financial force designed to make the startup look small and risky.
But Feldman obviously doesn't have a private yacht budget. He's running a startup. So what does he do? He invites the CEO of NetHone over to his modest house for a backyard BBQ. Just a simple human touch.
Yeah.
And later, the CEO told Feldman that in decades of doing business with Cisco, no one had ever once invited him into their home. That one authentic human gesture secured the massive deal.
It is a revealing story about leadership. It shows a fundamental strategy of asymmetrical warfare. You don't fight Goliath head on where he is strongest. You don't try to outspend Cisco on yachts, and you don't try to beat NVIDIA by building a slightly better GPU.
Right.
You show up in ways and places that Goliath fundamentally cannot.
Which brings us precisely to the core of the technology. They survived the fires, they built the complex water cooling systems, they solved the impossible yield problem.
Uh-huh.
But why? We haven't actually answered the most important question here.
That's true.
Why go through all of this agonizing trouble, risk millions of dollars, and fight the laws of physics just to make the chip physically bigger?
Because of a concept in computer architecture known as the memory wall. And if you understand the memory wall, you understand exactly why Cerebras is valued at $95 billion today.
Here's where it gets really interesting. Because this is the single biggest bottleneck in artificial intelligence today, right? It is not about how fast the computer chip can think. It's about how fast it can grab its notes to start thinking.
That is a highly accurate conceptualization. Let's break down how a large language model, an LLM, actually operates when generating text. Yeah. Whether you are typing a prompt into ChatGPT, Anthropic's Claude, or Meta's Llama, the model generates responses sequentially, one token at a time.
Right.
A token is basically a word. Or a fragment of a word.
So, it reads my prompt, calculates the mathematical probability of the next most likely word, prints it, and then calculates the next most likely word after that.
Precisely. But here is the critical mechanical detail. To predict that single next word, the processor has to read through the entire massive neural network.
Wait, for every single word?
For every single word. It has to load all of the model's weights or parameters. For a massive frontier model, we are talking about hundreds of billions of individual parameters that dictate the logic of the AI.
And those parameters are essentially the AI's memory. It's the knowledge it gained during its training phase. Where is all that memory actually physically stored inside a server?
In a traditional AI setup using NVIDIA GPUs, the compute logic cores are on the GPU silicon itself. But the massive amount of memory needed to hold those hundreds of billions of parameters is located in something called high-bandwidth memory, or HBM.
And HBM isn't on the logic chip itself, is it?
No, it is located slightly off the main processing chip. It is packaged very close by, usually on the same interposer board, but it is physically separate from the compute cores.
Okay, wait, why? If the compute cores need the memory constantly, like for every single word, why doesn't NVIDIA just put the memory directly on the compute chip?
Because of the physical differences in memory technology. HBM is a type of DRAM, dynamic random access memory. It uses a single transistor and a capacitor to store a bit of data.
Okay.
It is incredibly dense, meaning you can pack gigabytes of memory into a small physical space, but because of how it's built, it's relatively slow to access.
And what's the alternative?
The alternative is SRAM, static random access memory. SRAM uses a complex flip-flop circuit of typically 6 transistors to store a single bit of data. It doesn't need to be constantly refreshed like DRAM. Because of this, SRAM is blisteringly fast. It operates at the exact same speed as the compute logic.
So why not just SRAM for everything? I mean, if it's faster.
Because it takes 6 transistors per bit, it physically takes up way too much space on a silicon die. If Nvidia tried to put 80GB of SRAM onto an H100 chip, the chip would have to be, well, it would have to be the size of a dinner plate.
Oh, I see the connection now. Nvidia is trapped by the reticle limit. Because their chip can only be 814mm², they don't have the physical real estate to put the fast SRAM memory memory on the chip.
Exactly.
They have to use the dense, slower HBM memory.
Yeah.
And they have to stick it outside the compute cores.
Yes. So for every single word an LLM generates, the compute core has to reach out across the physical wires to that external HBM memory.
It has to go get the data.
Right. It grabs the entire massive model weight data, pulls it across the interposer, brings it into the compute core, does the matrix multiplication. Spits out the word, flushes the memory, and then does it all over again for the next word.
This data movement must take an enormous amount of time relative to the speed of the processor.
It does. It consumes vast amounts of electrical power just moving electrons back and forth, and it fundamentally limits how fast the model can generate text.
Wow.
The compute cores inside an NVIDIA GPU are incredibly fast, but they spend a massive percentage of their time just sitting idle, starved for data, waiting for the memory to arrive from the HBM. This physical barrier between compute and memory is what the industry calls the memory wall.
Okay, let's crystallize this with an analogy. The ideal state, what you want, is like having every single reference book you need for a massive research paper already open on a giant desk right in front of you. You just glance down, read, and write.
That is the ideal state of pure compute.
Yes. But the traditional GPU approach with HBM memory is like having a tiny desk. You have to put on your shoes, walk out of your office, walk across the campus quad to the library, find the specific book, read one sentence, walk all the way back across campus to your desk, write down one word.
And then walk entirely back to the library for the next sentence.
Exactly. Even if you are the fastest reader and writer in the world, the walking back and forth is what takes all the time.
That is a perfect visualization of the memory wall. The walking distance, the physical transport of data across silicon is the ultimate bottleneck.
So how does the sprawling silicon city of Cerebras solve this?
Cerebras solves it by putting the entire library directly on the desk. Because they broke the yield rule, their chip is massive, 46,225 square millimeters. They finally have the physical real estate to put the blisteringly fast SRAM memory directly on the silicon.
Right next to the cores.
Physically interspersed right next to the compute cores. They keep everything on chip.
No walking across campus, no external HBM.
None. The WaferScale Engine 3 has a staggering 44GB of on-chip SRAM. And because it's right there on the chip distributed among the cores, the speed at which the compute logic can access that memory is difficult to comprehend. It delivers 21 petabytes per second of memory bandwidth.
Wait, petabytes with a P?
Yes, 21 petabytes per second. To give you some numerical context, that is 7,000 times the memory bandwidth of an NVIDIA H100 GPU.
7,000 times faster memory access. Okay, whenever I see a number like that in enterprise tech, a multiplier that huge, my immediate thought is, what's the catch? You don't just get a 7,000x multiplier over the most valuable company on earth without sacrificing something else entirely. What are they trading off to get that speed?
The trade-off is the physical complexity we just spent 20 minutes discussing. You have to invent an entirely new manufacturing paradigm.
Right, the yield problem.
Exactly. You have to build a machine that consumes 23 kilowatts of power and requires proprietary internal plumbing to prevent a thermal event. NVIDIA's approach is modular, standardized, and easily manufactured by the millions. Cerebra's approach is a bespoke, massive undertaking.
But if you can stomach that physical complexity, the performance gains are undeniable. And it's not just the memory access, right? It's how the cores talk to each other.
Exactly. The interconnect bandwidth, how fast the 900,000 cores share data with each other across that giant wafer is 3,715 times faster than the network interconnects used to link multiple standard GPUs together.
So what does 7,000 times more memory bandwidth actually mean for the end user? For the person typing a prompt into an AI? What is the real-world application here?
The real-world impact is inference speed. Inference is the industry term for how fast the trained model generates an answer for you. If we connect this to the bigger picture of where the AI industry is heading, we are currently moving away from simple question-and-answer chatbots toward complex reasoning models and autonomous AI agents.
Right, like OpenAI's newer reasoning models, the ones that pause and think for a minute before they output an answer.
Exactly. Those autonomous agents don't just generate one paragraph for you, they execute reasoning loops. They generate tens of thousands of tokens internally browsing the web, writing Python code, testing that code, seeing an error, rewriting the code all behind the scenes before showing you the final result.
If your hardware is bottlenecked by the memory wall, wall, and the AI has to walk to the library for every single word of that internal reasoning loop.
Waiting for a complex agentic task to complete on a traditional GPU cluster could take 20 to 30 minutes. The math just breaks down. It is untenable for real-time applications.
Nobody's going to sit and stare at a loading screen for 30 minutes while their AI assistant tries to book a flight or debug a script.
But with Cerebras, because the memory bandwidth is so vast and the memory wall is destroyed, that wait time collapses entirely. Let's look at the independent benchmarks from Semi Analysis provided in our research sources.
Yeah.
When running Meta's Llama 370B model in a complex reasoning scenario, the Cerebras CS-3 system was clocked at over 21 times faster than NVIDIA's absolute newest flagship DGX B200 Blackwell GPU.
Wait, 21 times faster than Blackwell? NVIDIA's Blackwell is supposed to be the absolute cutting edge of traditional GPU compute.
It is. It is. And Cerebras is an order of magnitude faster for this specific inference workload. If we look at specific throughput speeds for Meta's Llama 4 Maverick model, which is a massive 400 billion parameter model, Cerebras hits over 2,500 tokens per second per user.
2,500 tokens per second. I, let's see, if I read maybe 5 or 6 words a second, the AI is generating text hundreds of times faster than a human can physically process.
It. Meanwhile, the NVIDIA Blackwell system running that exact same Llama 4 Maverick model hits about 1,000 tokens per second. Still incredibly fast, but less than half the speed of the wafer-scale engine.
Wow.
And the most critical data point, Cerebras achieves this 21x speed advantage at roughly one-third the cost and one-third the total power consumption of the NVIDIA Blackwell system.
Faster, substantially cheaper. Cerebra is cheaper and vastly less power-hungry at the data center level. I mean, it explains why serious enterprise companies are starting to adopt it. The sources mentioned AlphaSense, which is a major financial intelligence platform. They reported processing 100 times more financial documents in half the time compared to their legacy GPU setup.
We also see massive gains in the life sciences. The Mayo Clinic is running complex cancer drug response prediction models many hundreds of times faster on Cerebra's hardware than on conventional GPUs.
That's amazing. Amazing.
When you completely remove the memory wall, workloads that were previously impractically slow suddenly become real-time interactive tools.
Okay. So the physical hardware is clearly a beast. It's a sprawling city of silicon that reads its internal library instantly. But if we are being realistic about the tech industry, hardware dominance is only half the battle, maybe even less than half, because the entire AI industry fundamentally runs on NVIDIA software.
This is the critical pivot in the Cerebra story. You are talking about NVIDIA's deepest moat, CUD.
CUD, Compute Unified Device Architecture, NVIDIA's proprietary parallel computing platform. From my understanding, basically every AI developer on earth knows it. All the major machine learning frameworks are optimized for it, and it has a 15-year head start.
That's right.
If Cerebra shows up and says, hey, we built a giant, amazing chip, but you have to learn an entirely new, incredibly complex programming language to use it. Developers are gonna run the other way. Nobody wants to rewrite millions lines of code. So how does a hardware startup compete against a deeply entrenched software monopoly?
That is the multi-billion dollar question. And Cerebras's answer is an architectural design they call the software illusion. They realized very early on that to beat NVIDIA, they couldn't just have superior silicon. They had to make their massive supercomputer incredibly simple to program. It had to be frictionless for the developer.
So how do they achieve that? How do you make a 4 trillion transistor plate of silicon easy to program?
To understand the elegance of their solution, you first have to understand the agonizing pain of programming traditional GPU clusters.
Okay, lay it on me.
Let's say you are a researcher trying to train a massive AI model, something with 175 billion parameters.
Okay, like a GPT-3 size model.
Exactly. That model will not fit on a single NVIDIA GPU. Not even close. An H100 GPU might have 80 gigabytes of HBM memory. A 175-billion-parameter model needs hundreds of gigabytes of memory just to store the weights, let alone the activation states and gradients required during training.
So if it doesn't fit on one chip, you have to chop the model up and spread it across multiple GPUs.
Exactly. This is called model parallelism or sharding. You have to mathematically distribute the neural network across hundreds or thousands of individual GPUs. GPUs. But now, those discrete GPUs have to constantly talk to each other over networking cables to synchronize their math.
Because if GPU number 4 updates a parameter, GPU number 800 needs to know about it before it does its next calculation.
Precisely. And managing that synchronization requires writing incredibly complex distributed systems glue code. You have to write code that explicitly tells the system how to slice the data, when to send it across the network, how to handle latency, and how to manage parameter servers.
It sounds like a networking nightmare.
Our sources note that training a standard 175-billion-parameter model on a cluster of 4,000 GPUs takes approximately 20,000 lines of highly specialized distributed training code.
20,000 lines?
Yes. It requires an entire team of systems engineers just to manage the networking overhead and the data flow between the chips. The machine learning researcher spends more time fighting the hardware network than tuning the AI.
20,000 lines of code. Code just to manage the hardware communication.
Yeah.
So what is the experience like on a Cerebra system?
On Cerebras, doing that exact same 175 billion parameter training run takes just 565 lines of code.
Wait, 20,000 lines down to 565? That is a massive reduction in complexity. How is that mechanically possible?
It is possible because of the immense physical size of the wafer-scale engine and a proprietary architecture they developed called weight streaming. Let's walk through the mechanics. We established that the WSE-3 has 44 gigabytes of memory directly on the chip.
Right.
But for a truly massive frontier-level model, say a multi-trillion parameter model, even 44 gigabytes of SRAM isn't enough to hold everything at once.
Right. If I'm a developer, I'm used to chopping my model up to fit on 80 GB GPUs. If you're telling me Cerebras can train a multi-trillion parameter model without sharding, the math doesn't work. The WSE-3 only has 44 gigabytes. Where are they putting the data?
This is where they disaggregate the memory from the compute for training workloads. They built massive external memory cabinets called Memory X Units. These units can hold up to 1,200 terabytes of model parameters. That is enough physical capacity to hold a 24 trillion parameter model.
Okay, but hang on. If you move the memory off the chip into an external cabinet, didn't you just recreate the memory wall we spent all that time talking about? Now the chip has to walk to the library again.
A brilliant observation, but no, you don't recreate the wall because the mechanics of training are different from the mechanics of inference. Here is the genius of the weight streaming architecture. The external memory XUnit doesn't send the whole model at once. It streams the weights, the parameters into the giant wafer-scale engine, one single neural network layer at a time.
Oh, like an assembly line.
Exactly. The MemoryX cabinet streams Layer 1 into the wafer. The wafer, utilizing its massive 21 petabytes per second internal bandwidth, instantly calculates the gradients, which are essentially the mathematical adjustments needed to make the AI smarter.
Right.
The wafer then streams those gradients back to the MemoryX unit to update the master weights. Then it streams in Layer 2.
Oh, I see the mechanism. Because the entire wafer-scale engine acts as one single massive processor. It can ingest an entire layer of a trillion-parameter model all at once.
Yes.
You never have to chop the model up into tiny pieces and spread it across thousands of individual chips.
You completely eliminate the need for complex data parallelism or model sharding. The software doesn't need to know about 4,000 individual GPUs. The software just sees one magical gigantic chip that is perfectly capable of handling the entire layer.
So to a machine learning engineer, writing code for a massive cluster of Cerebras systems feels exactly the same as writing code for a single machine on their laptop.
That is the software illusion. It hides all the physical complexity of the hardware. You just write standard PyTorch code, PyTorch being the primary open-source machine learning framework developed by Meta that almost all researchers use today. Ah. You write your PyTorch script, you hit run, and the Cerebras compiler handles the rest. No distributed glue code required. This allows a single machine learning engineer to develop, debug, and train trillion-parameter models alone, which is an unheard-of feat in the GPU world.
And they're proving this scales to a massive degree. This isn't just a whiteboard theory anymore. Look at the Condor Galaxy project.
Yes, their massive partnership with G42, the Abu Dhabi-based technology holding group. This is where the sheer compute scale gets truly astronomical.
Our sources outline the timeline here. They started by building Condor Galaxy One, CG-1, which was a 4 exaflop AI supercomputer. Then they built Condor Galaxy Two, and recently they announced Condor Galaxy Three being built in Dallas, Texas.
We should probably define exaflop for clarity, as it's a term thrown around a lot in supercomputing. FLOPs stands for floating point operations per second. It's a measure of mathematical calculation speed. An exaflop is 1 quintillion operations per second. That is a 1 followed by 18 zeros.
A billion, billion calculations per second. Wow.
Correct. And Condor Galaxy 3 alone is powered by 64 of these new Cerebra CS-3 systems, delivering an astonishing 8 exaflops of AI compute. But their vision is even bigger than a single data center.
Right. The sources indicate they are building a global network of 9 interconnected AI supercomputers, targeting a combined capacity of 36 exaflops. They have live deployments in the US, the UAE, and they recently formalized the framework for the Condor Galaxy India AI supercomputer.
And what's crucial for the listener to understand is how accessible this massive compute is becoming. You don't have to be a sovereign nation state or a multi-billion-dollar tech monopoly to use it.
Exactly. You, the listener, can rent this power right now. You don't have to buy a massive server rack and install proprietary water cooling in your garage.
No, thankfully.
Cerebras launched a cloud developer tier. You can access their 21x inference speeds via API through cloud providers like Portkey or Vercel's AI Gateway.
And the pricing model is is incredibly disruptive to the industry too. Looking at the developer tier, you can run Meta's open-source Llama 3.18B model for just 10 cents per million tokens.
Wait, 10 cents? For a million tokens? Let's put that in perspective. A million tokens is roughly 750,000 words. You could generate the equivalent text of the entire Harry Potter series, read and processed instantly, for the price of a single dime.
It's absurd.
And you can do it at 2,200 tokens a second. That changes the fundamental economics of building AI applications.
It does. When inference becomes that fast and that cheap, the bottleneck shifts from the hardware limitations back to the software developer's imagination. Entirely new application architectures like continuous recursive agentic loops become economically viable overnight.
So let's look at where all of this leads. We've covered the physics of the radical limit, the lab fires and water cooling, the smashing of the memory wall, and the elegance of the software illusion. But all of this, the 7,000x memory speed, the software simplicity, it doesn't actually matter if you can't build a sustainable, heavily capitalized business around it. For nearly a decade, Cerebras was essentially a brilliant private science experiment. But to actually dethrone a trillion-dollar goliath like NVIDIA, they needed public capital at an unprecedented scale.
Yeah.
Which recently forced them onto Wall Street.
Yes. The initial public offering, the crucible where public markets validate or violently reject a decade of private technological development.
Uh, where there is where there is massive hype, there is intense scrutiny. Let's look at the actual financials of this IPO, because the numbers are staggering. Cerebras priced their IPO at $185 a share. It opened on the market at $350 and closed its first day of trading at $311.07.
That's a huge jump!
That netted them a market capitalization of approximately $95 billion.
As we mentioned in the intro, it was the largest US tech IPO since Snowflake in 2020. But a valuation like that doesn't happen in a vacuum. The underlying revenue growth is what fueled that explosion in public interest. In 2022, Cerebras generated $24.6 million in total revenue. By 2025, that figure skyrocketed to an estimated $510 million.
From $24 million to half a billion in 3 years. That is the kind of hockey stick trajectory that gets institutional investors foaming at the mouth. But what was the specific turning point? What flipped the switch from an interesting niche hardware startup to a $95 billion behemoth?
The turning point was a massive, highly public validation from the single most important player in the generative AI industry, OpenAI.
Right. In January, OpenAI signed a multi-year compute agreement with Cerebras worth $20 billion. That is not a typo. $20 billion.
The agreement secures 750 megawatts of computing capacity through 2028. It is a profound strategic statement. When the premier AI lab in the world, the creators of ChatGPT, a company deeply partnered with Microsoft and historically heavily reliant on NVIDIA's infrastructure, when they make a $20 billion forward-looking bet on your alternative hardware, the entire global market takes notice.
It's the ultimate stamp of approval. And it wasn't just a corporate deal. Early individual backers saw massive personal windfalls. Walls. Sam Altman and Greg Brockman from OpenAI were early angel investors in Cerebras years ago.
Yes, they were.
The IPO made their personal stakes worth tens of millions of dollars. Plus, OpenAI itself received a massive chunk of warrants in Cerebras as part of a loan agreement.
But the sheer scale of capital raises an important macroeconomic question regarding market liquidity and the broader IPO landscape. Because Cerebras isn't the only giant tech company waiting in the wings to go public.
Oh right, the multi-trillion-dollar Elikans Exactly.
The tech IPO market has been largely frozen for years due to high interest rates. Cerebras broke the ice, but look at who is lined up directly behind them. SpaceX, OpenAI itself, and Anthropic. All of them are gearing up for potential massive IPOs.
And those are deeply capital-intensive companies. SpaceX is targeting a $1.75 trillion valuation. OpenAI is targeting around $852 billion. Anthropic is hovering around $800 billion.
The combined fundraising demand from just those 3 entities could easily exceed $150 billion of fresh capital. Institutional investors will need to allocate capital at a scale with absolutely no precedent in financial history. The question is, can the public market support all of this AI infrastructure at once? Will there be enough cash liquidity left over for anyone else?
It's a valid macro fear.
Mm-hmm.
But let's zoom back in and play devil's advocate for a second on Cerebras specifically, because a $95 billion valuation based on $510 million in revenue is, well, it's a very aggressive multiple. And we've got folks on Reddit, specifically the WallStreetBets community, reading through the S-1 filings and pointing out some very real structural risks to this company.
Retail investors, especially communities dedicated to deep dive financial analysis, are often the first to poke holes in a Silicon Valley hype narrative. What are their primary concerns regarding Cerebras?
So I was reading through this massive due diligence thread Analyzing the IPO, risk number 1 that they point out is customer concentration. Specifically, the G42 dependency we mentioned earlier.
Ah, yes, the Abu Dhabi-based technology partnership that built the Condor Galaxy supercomputers.
Right. Before this massive $20 billion OpenAI deal hit the books, Cerebras was overwhelmingly dependent on G42 for its survival. The sources note that in 2024, G42 accounted for a staggering 85% of Cerebras' total revenue.
That is an extremely dangerous concentration of revenue in a single customer. In traditional finance, that is a massive red flag. If that relationship sours or if G42 pivots their strategy, Cerebris's financials collapse overnight.
And it wasn't just a business risk, it became a geopolitical one. That deep tie to a United Arab Emirates company actually triggered a formal review by CFIUS, the Committee on Foreign Investment in the United States.
For context, CFIUS is the interagency committee authorized to review transactions involving foreign investment in the US. US, specifically to determine the effect on national security.
Right. And with AI chips being viewed as critical national security infrastructure, the US government was heavily scrutinizing the technology transfer to the Middle East.
It is important to note the resolution there impartially. To satisfy US regulators and alleviate those national security concerns, Cerebras had to officially restructure G42's stake into non-voting shares. Furthermore, the US government continues to closely monitor and restrict advanced AI chip exports to certain global regions.
That makes sense.
Cerebras operates Condor Galaxy-1 strictly under US laws to ensure the technology isn't misused or accessed by restricted actors.
It's a complex geopolitical tightrope to walk when your hardware is this powerful. And risk number 2 that the Redditors pointed out is purely physical, manufacturing constraints. Cerebras doesn't build their own chips, chips. They are what's called a fabless semiconductor company. They just design the blueprints. They rely entirely on TSMC, Taiwan Semiconductor Manufacturing Company, to actually fabricate these giant wafers.
And specifically, they rely on TSMC's 5-nanometer process node to build the WSE-3.
Right. And as one heavily upvoted Redditor pointed out, TSMC is currently reducing capacity on those older 5-nanometer manufacturing lines. They are physically tearing down the equipment to retrofit their factories for newer, more advanced 3nm and 2nm processes for Apple and Nvidia.
The mechanical retooling of a semiconductor fab is a massive, multi-billion-dollar undertaking involving new extreme ultraviolet lithography machines.
So if TSMC pivots their manufacturing capacity away from 5nm, Cerebras is uniquely vulnerable, because nobody else on Earth can manufacture a wafer-scale chip them. You can't just call up Intel or Samsung and say, hey, can you retool your entire factory to build this weird dinner plate? Cerebras is completely locked into TSMC's specific tooling.
It is a highly valid supply chain vulnerability. The wafer-scale approach, by its very nature, requires such bespoke manufacturing techniques that it limits their options to the absolute cutting edge of TSMC fabrication. If TSMC deprioritizes them in favor of a massive Apple iPhone order, Cerebras physically cannot produce product.
And then there is risk number 3, the biggest one. The immovable object we keep circling back to. NVIDIA's moat.
CUDA. The stickiness of the software ecosystem.
Exactly. One developer on Reddit summed up the bear case perfectly. They wrote, Cerebras tech looks amazing on paper, but NVIDIA's strength isn't just the physical GPU, it's the entire ecosystem. Almost every AI lab on Earth already optimizes their workflows around CUDA. Even if Cerebras shows massive efficiency gains in specific benchmarks, the real question is adoption at scale. Will developers actually switch?
That is the crux of the argument against any NVIDIA competitor. A technically faster chip fundamentally does not matter if the global engineering industry refuses to learn how to use it. Software stickiness, muscle memory, and existing codebases are the most powerful forces in enterprise technology.
So given all those massive risks, the 85% customer concentration with G42, The terrifying manufacturing bottleneck at TSMC, and the seemingly immovable object of NVIDIA's software moat. How do you justify a $95 billion valuation?
You justify it with the OpenAI contract and the raw, undeniable economics of inference. While the risks you outlined are entirely real and valid, a $20 billion commitment from OpenAI offers a massive, multi-year counterweight to the G42 concentration concern. Returns. It instantly diversifies their revenue with the most prestigious high-volume client in the world.
Okay, that solves the business risk, but what about the software risk? How do they beat CUD?
On the software side, the industry's massive shift from training AI models to serving AI models inference changes the entire dynamic. When you are initially training models, deep CUD optimization is absolutely paramount. You need that fine-grained control. Right. But when you are simply serving an already trained model to millions of users' Inference, the software stack is much, much simpler.
Ah, so if I'm just running a prompt through Llama to get an answer, I don't need to rewrite the entire world's code to do it on Cerebras. I'm just running weights through an engine.
Precisely. The barrier to entry drops significantly. And as we discussed earlier, in the realm of inference, Cerebras is offering 21 times the speed at a third of the cost. When you are a company running hundreds of millions of AI queries a day, like an OpenAI, a Google, or a Perplexity, switching to a chip that saves you billions of dollars in electricity and delivers answers instantly, the economic gravity becomes simply too strong to ignore.
Wow. Yeah.
The enterprise debate shifts from, is it hard to switch, to we will go out of business if we don't switch.
We can't afford not to switch. That is an incredibly powerful place to be as a hardware vendor.
Absolutely.
So let's step back and look at the massive journey we've just been on. We started with a genuinely crazy idea. Taking an 80-year-old fundamental rule of semiconductor physics, that bigger chips mean exponentially worse yields, and completely ignoring it.
They chose to design an architecture that expected defects, rather than living in fear of them.
Right. And that disobedience led to prototypes literally catching fire in the lab, forcing them to invent proprietary water cooling just to keep the silicon from melting. But they pushed through, and they birthed the wafer-scale engine. A chip that put the library on the desk, unlocking 7,000 times more memory bandwidth and completely shattering the memory wall that holds back every traditional GPU.
Which ultimately allowed them to simplify the absolute nightmare of distributed software down to a few hundred lines of code, democratize access at 10 cents a million tokens, and secure a $95 billion public valuation backed by the most important players in the AI ecosystem.
And here is why all of this complex physics and finance matters directly to you listening right now. If you use AI in any capacity in your daily life, if you use tools like ChatGPT to write emails, if you use coding assistants like Klein to build software, or if you are beginning to build complex agentic workflows that string multiple AI tasks together in the background, the speed, the capability, and the cost of those tools over the next decade will be decided by this exact war.
It is the foundational physical layer that dictates the software layer.
It is. It is the battle between NVIDIA's massive sprawling clusters of thousands of distinct GPUs tied together with miles of complex networking cables versus Cerebras's elegant, continuous giant dinner plates of silicon. Whoever wins that hardware war dictates what AI can do for you tomorrow.
And as we wrap up this deep dive, I wanna leave you with one final broader conceptual thought to mull over. We've spent this entire time heavily focused on the engineering, the heat dissipation, and the financial economics of Wall Street. But consider the biological parallel to what Cerebras is building.
Okay. A biological parallel to a piece of silicon. I'm listening.
Think about the human brain. Our brains do not operate by sending information across vast networks of discrete, physically separated components over miles of cables. Our brains are continuous, highly interconnected physical structures where memory storage and mathematical computation are fundamentally physically intertwined in the same tissue. If a single piece of silicon the size of a dinner plate can hold 4 trillion transistors, if it can route around its own damage, if it can process information almost instantly without the friction of external networks, and if it can scale to hold 24 trillion parameters on a single logical device. Will the physical future of artificial intelligence look less like building massive, sprawling industrial server farms and more like growing continuous physical artificial brains?
Now that is a thought But a giant golden brain on a dinner plate waiting to be plugged in. Thank you for joining us for this deep dive into the hardware that is building the future. We'll see you next time.
More from Charles


Founder Wisdom: the audiobook, version 2 (5 hours of stories from founders and CEOs)

8 CEO Questions I Love Asking: the audiobook (64 founders answer, in their own words)





