A website A/B test shows 45 clicks on the original page versus 67 on a redesign. A permutation test with 10,000 replicates yields a p-value of 0.016, suggesting the difference isn't random. But statistical significance doesn't mean the redesign is worth its cost.
Chapters
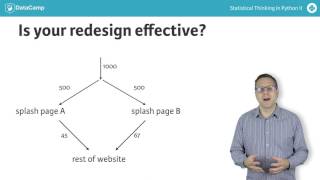
Imagine your company has proposed a redesign of the splash page of its website. They are interested in how many more users click through to the website for the redesign versus the original design. You devise a test. Take a set of 1,000 visitors to the site and direct 500 of them to the original splash page and 500 of them to the redesigned one. You determine whether or not each of them clicks through to the rest of the website. On the original page, which we'll call page A, 45 visitors click through and on the redesign page, page B, 67 visitors click through. This makes you happy because it is almost a 50% increase in the click through rate. But maybe there really is no difference between the effect of the two designs on the click through rate and the difference you saw is due to random chance. You want to check what is the probability that you would observe at least the observed difference in number of clicks through if that were the case? This is exactly the question you can address with a hypothesis test. A permutation test is a good choice here because you can simulate the result as if the redesign had no effect on the click through rate. Let's code it up in Python. For each splash page design we have a numpy array which contains one or zero values for whether or not a visitor clicked through. Next, we need to define a function difffrac for our test statistic. Ours is the difference of the fraction of visitors who clicked through. We can compute the fraction who clicked through by summing the entries in the arrays of ones and zeros and then dividing by the number of entries. Finally, we compute the observed value of the test statistic using this function difffrac. Now everything is in place to generate our permutation replicates of the test statistic. Using the permutation replicate function you wrote in the exercises, we will generate 10,000 replicates. We compute the p value as the number of replicates. Where the test statistic was at least as great as as what we observed, we get a value of 0.016 which is relatively small. So we might reasonably think that the redesign is a real improvement. This is an example of an AB test. AB testing is often used by organizations to see if a change in strategy results in different, hopefully better results. Generally, the null hypothesis in an A B test is that your test statistic is impervious to the change. A low p value implies that the change in strategy led to a change in performance. Once again, though, be warned that statistical significance does not mean practical significance. A difference in click through rate may be statistically significant, but if it is only a couple people per day, your marketing team may not consider the change worth the cost. A B testing is just a special case of the hypothesis testing framework we have already been working with a fun and informative one. Let's practice with some exercises.