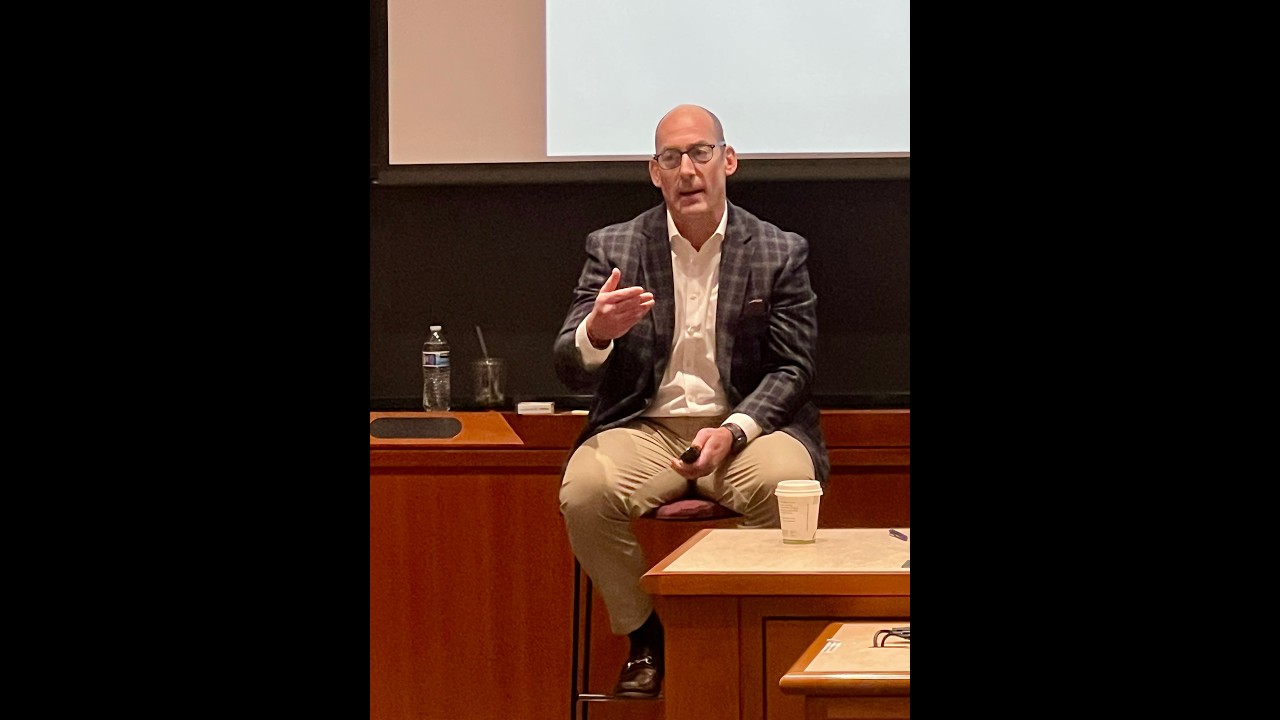
AI and Investing: David Trainer’s Presentation at Harvard Business School
29 Apr 2026 · 1 min
1:11
David Trainer, who's been working in machine learning since 2003, spent 20 years building technology to automate the reading of SEC filings. Companies file 200 to 500 page documents every quarter, and his team created explicit instructions to extract the critical data instead of hiring offshore workers to read them manually.
Chapters
More from David




youtube.com
Earnings Recap: Decoding Signals from SpaceX, Palantir, Merck, AMD, Caterpillar, McDonald’s, & More
2mo ago

youtube.com
Watch Our Earnings Recap: Market Heavyweights Apple, Microsoft, Amazon, Meta, Visa, and More
2mo ago



youtube.com
Earnings Recap: Top Insights from JPMorgan, Bank of America, Taiwan Semiconductor, Netflix, and More
2mo ago


youtube.com
The IPO Melt Up: How Smart Investors Use AI to Find Abnormal Investment Opportunities
3mo ago