How to Cut Your LLM Classification Costs by 90%
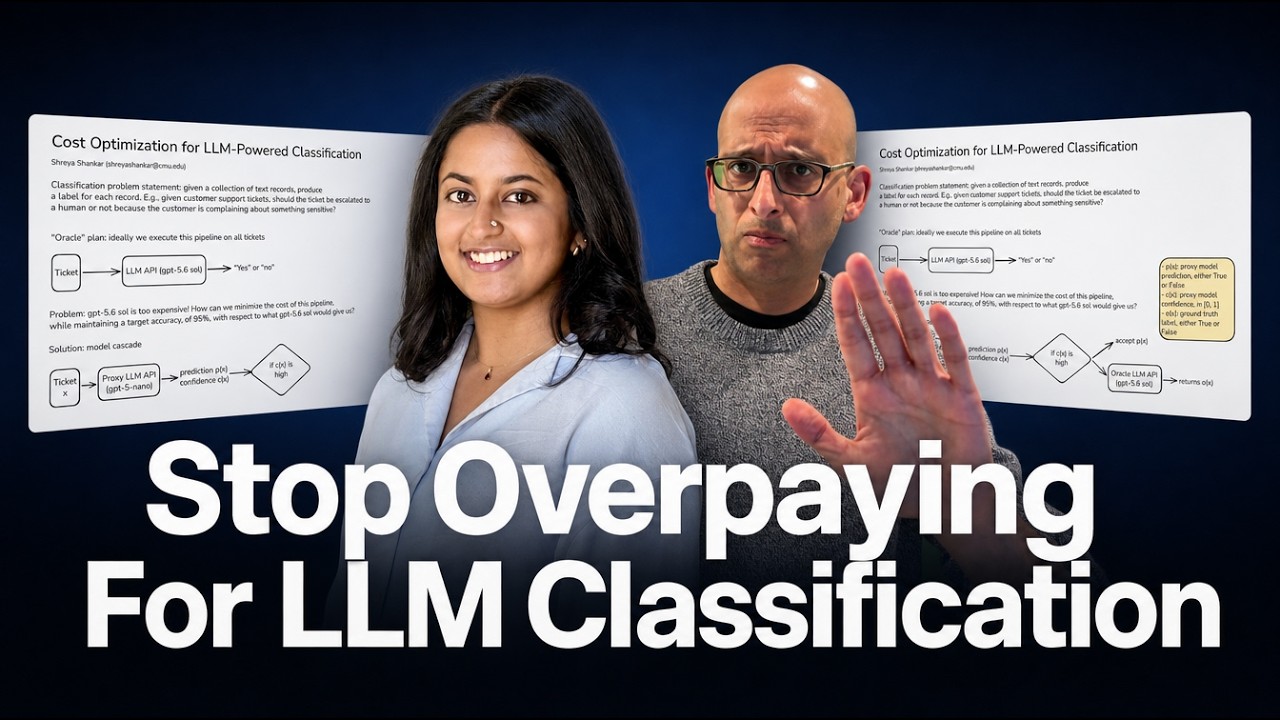
Shreyas shows how to cut LLM classification costs by 90% using a Model Cascade: route inputs through a cheap proxy model first, send only low-confidence cases to an expensive oracle. A simple offline sampling procedure finds the optimal confidence threshold to hit your accuracy target while minimizing cost.
Chapters
Welcome everybody. Shreyas is going to be talking about how to save money for LLM classification. It's actually like a very clever technique, but you're going to want to pay attention to this because there is a way that you can sort of hill climb your way into having a cheaper model for classification without sacrificing any performance without fine-tuning. But I think it's really interesting and important. Classification is becoming more and more important, like especially with things like model routing. we often want to do classification. And as token costs are going up, like model routing is really important. So I'll go ahead and kick it off.
Very excited to do this live whiteboard lecture on reducing cost for classification. Could be a total train wreck. So let's start with some basic motivation of broadly what is kind of classification. All right, classification problem statement. So the whole goal of classification, especially for LLMs, is if you have a collection of text records, say given a collection of text records, produce a label for each record, and this label is drawn from some sort of finite set. So let's make it really simple. Let's make it binary classification. So for example, if I have a collection of customer support tickets, customer support tickets, what do we want to classify, Hamel? You want to think of like binary classification task?
Customer support tickets. Yeah. Should it be handed— should it be escalated to human or not?
Give— should the ticket be escalated to a human or not? And we can have various criteria for escalation. Like maybe it has to do with billing or it has to do with like some more sensitive topic. So let's be even more precise then. Ticket be escalated to human or not because the customer's complaining about something sensitive like billing. All right, so hopefully people understand like this is a binary classification task, right? It's just a yes or no test. So an LLM in the ideal world would be given the customer support ticket and it would be prompted, hey, should we escalate to the human because it contains something sensitive? And then it would produce yes So let's draw out what that, what we'll call Oracle plan looks like. So given, I'm gonna call this the Oracle plan. So here I'm gonna draw what I think is the customer's, oh, that's not the right shape. So maybe this is like the ticket, customer support ticket. What happens to it? Well, it gets sent to a large language model, LLM, the label inside this is the LLM API, and then out comes some yes or no.
Yes.
Or no, but this is what our pipeline is going to look like. And let's be even more specific. So what LLM do we want to use? Ideally, we want to use some LLM that has good quality. It's not like a bad LLM. So I'm going to say that this is GPT-5.6. Let's say so. So everybody on the same page. So this is what we call the oracle plan. That is, we want to be able to execute this plan on every single ticket.
Yeah.
So that's what oracle plan means for us here. So ideally, we Execute pipeline on all. So one naive thing that is probably top of mind for everybody who has to pay personally for these calls is, wow, this is going to be really expensive. Like, let's say I am Walmart, or let's say that I'm not even Walmart, I'm like a mid-sized company. GPT-5.6 SOL is quite expensive, right? If you do some calculate back of envelope calculations, which I should have done in preparation for this lecture, I would guess that it would cost tens of thousands of dollars to be able to run this pipeline on, let's say, like a million customer support tickets. So depending on the length of the ticket, depending on whether you enable reasoning or not, basically you can imagine that the cost of this is going to blow up, especially if you do this at scale. Now, again, don't quote me on the exact numbers, but let's all assume that we do not want to pay for this. However, what we do want is to be able to maintain the accuracy. We really like GPT-5.6 SOL because it's high quality. So now let me give us a more concrete problem statement. So problem, GPT-5.6 SOL is too expensive. How can we reduce the cost of this pipeline while maintaining the same accuracy as what GPT-5.6 SOL would give us? Maintain the same accuracy, but we wanna do it much cheaper. Okay, so let's be even more precise here. We wanna reduce the cost of the pipeline. How can we, let's say, minimize the cost of the pipeline? So try to find the cheapest pipeline.
Yeah.
And maybe, you know, it's impossible to get 100% accuracy with respect to GPT-5.6 SOL. So here, remember, accuracy means we want to find a plan that agrees with GPT-5.6 SOL 100% of the time, or as much of the time as possible. So what we'll instead say is, while maintaining a target accuracy of 95% compared to, with respect to what GPT-5.6 SOL would give us.
We're not yet concerned about the accuracy of the 5.6 SOL, we're just saying how can we mimic 5.6 SOL?
Exactly. So, this is now our problem statement, and now let's get into at a very high level what the architecture of the pipeline is that's going to get us this accuracy. So, I'm going to call this a Model Cascade. Okay, so our solution is called a Model Cascade. What does a Model Cascade architecture look like? I'm going to copy this and I'm going to move it here. So, instead of running this expensive plan, what we're going to do is first send every ticket to a cheap LLM API. And let's say this is like a Nano model. And then what's going to happen? So Nano is going to tell us yes or no. So it's going to give us— I'm going to say prediction, and let's call this P. I'm going to call this ticket X, and I'm going to call this actually proxy LLM API. So that way when we say prediction P, it's like the proxy. It's going to tell us the prediction as well as confidence score. So I'll get into that a little bit. CX. And now we'll hit a decision point. So this is our decision triangle, and we're going to say if CX is high, if CX is high, then we accept PX. Otherwise, what we're going to do is we're going to ask the oracle. The oracle then will tell us, let's call it turns The yes using notation here, but let's just say at a high level, you know, PX is going to give us either yes or no. CX is a score between 0 and 1, and OX is also yes or no. So things to keep in mind, I'm going to make like a little pretend that this is a sticky note, right? So PX proxy model score 0 true or false, then 0, 1. So this means that it's going to be some probability score. OX Ground truth label, either true or false.
I know when people get confused by ground truth, like ground truth in this context means what the oracle would say, not what is the truth, like necessarily.
I think it's helpful to say ground truth, I found, when I teach this, because then like we just make that assumption and move forward. Like when I define accuracy, then it makes sense. It's with respect to O. How about that? Assumed ground truth label. So this is the high-level overview of a model cascade. Next thing I'm gonna do is let's Think about, okay, what are the ambiguous things in this cascade? So let's see. I want us to just assume for the sake of time that like, okay, we know how to get CX. If you're curious on how to get CX, all of the LLM API providers allow you to see the probabilities for each token. So you can get that directly from OpenAI or Anthropic or so forth. So let's assume that we know how to get CX. Now our question is, what does high mean? Like I said here, our decision threshold is If CX is high, that's extremely vague. We need an actual number here to compare CX to. So then this gets into the question of how are we going to construct the model cascade? Model cascade algorithm. So the first step of the cascade algorithm is find threshold, and let's call it tau. And we will do this in an offline way. Then the second step is to actually do the inference with this architecture. Run the cascade on all the tickets. So these are the 2 steps to being able to classify all of your tickets with a model cascade. So I'm going to start out now with how to find the threshold. So at a very high level, the answer is we're going to use samples. So I'm going to draw out— imagine that we have visualizing all of the proxy predictions. Here we are, and we start out with 0, and here is 1. Okay, and this is supposed to be C. So this is a line that is visualizing all of C. So all the proxy predictions have all these blue dots represent various different confidences. Let's get some even more. Let's get some in the middle. So here I've drawn out like what plausibly could be some sample of proxies scores. And the first step of the algorithm is going to be run P.
And so the blue dots are like different Tickets, right? Like different examples of tickets?
Yes, and then where they are in this line is the CX, or like the confidence that the proxy would say. So, what I'm going to say here is first step. So, step 1, what we're going to do is take a sample of tickets, and I typically like to use, you know, between 200 and 500, let's say 500 tickets, and run the proxy on each ticket. This is going to give us PXI and C, xi for— well, let's just call it 500 tickets. So obviously there's not 500 dots here, but let's imagine that there were 500 dots here. So the next step that I'm going to do is I'm going to label each ticket in the sample with oracle. So this will give us o for each i. All right, so concretely, maybe the oracle goes through and says this guy was good, this guy was good, this guy was good, This guy was bad. I'm really making this up. This guy was good. This guy was good.
And when you say good and bad, we're meaning like true or false. Should it be escalated to a human?
Let's say the oracle is saying the check is escalated and then the X is not escalated. So it doesn't mean like the proxy was correct or not. So now let's say this was bad. This one don't escalate. This one don't escalate. This one escalate, escalate. So you can imagine we keep going on so on and so forth. Like I really am making this up, but what the oracle is going to give us is some yes or no for every ticket in the sample. So now that we have that, what we're going to do is we are going to essentially simulate what would happen in the sample if we had different values of our threshold tau. So specifically for each possible C, X, a high in the sample. The first thing that we're going to do is simulate the model cascade with threshold tau equals C, record accuracy and cost. So this might be a little bit confusing. Specifically, what I'm saying is we will run this model cascade, we will sub in tau for this diamond here, and then we will get all of the outputs from the cascade. So now we have all these like Cs, we have 500 of them. And we can try for each one of these 500, what if we set tau to Cx_i? What will our accuracy of the cascade be? And what will the cost of the cascade be?
And so to reframe it, you pick a threshold. So tau is some threshold, let's say 0.8. And then you say, hey, if every time the confidence or the Cx is over or greater than equal to 0.8, what if we just route it to this small model? How often does it agree with the oracle?
Well, they all go through the small model first. So we're imagining, okay, we've set, we've simulate, we've set tau to 0.9. Now let's simulate what would happen if tau is 0.9. Anytime the confidence is over 0.9, we just accept. Otherwise, we will route it to the oracle. And then we will take all of those final predictions and compute the accuracy with respect to O of X on the sample. So note that, of course, anytime we query the oracle, we are essentially getting it correct. Like, the oracle is always going to be correct by how we've defined it. So really what we're trying to see is like making sure that the proxy is correct in the times that we accept that proxy's prediction.
So you have your target accuracy, which is 95%, and you're trying to see, okay, what threshold, like how low can you go in the threshold to still get to 95%?
First, what I want to do is give like sanity check of, for people to understand. So there is a trivial cascade that will give you 100% accuracy. What would tau be? In that case, in that case, we would just set tau to be 1. So if tau is 1, then confidence can never be over 1, and we would always route to the oracle. And then by definition, we'll get 100% accuracy. Okay, so I want people to really understand deeply here that this model cascade, we can set the threshold such that we meet the accuracy. While we're trying to reduce costs, great, like the lower we go, as Hamel said, which we'll get into, the better. Here we can just assume that we will meet the accuracy. We can always find some tau that meets the accuracy, and trivially that is tau equals 1. So now let's get into kind of correct. So now we've gotten the number of accuracies and costs for each possible c_i, and what we want to do at the end of this is return the c tau equals c_x_i with minimum cost that meets the accuracy target. So basically, remember for each CI we've recorded what the accuracy and the cost could be on the sample there, and if the accuracy is below like 95% or whatever target we've set, then throw it out. We'll never choose that CI as a threshold. We'll just choose the target that gives us the minimum cost.
So, why is it phrased here as with minimum cost? Is that the same thing as Saying with the minimum threshold, would that be the minimum cost?
Because I think it's not intuitive that minimum threshold actually leads to the lowest cost. But just imagine we have all these numbers, everybody's on the same page hopefully that, you know, we just want to return the tau that gave us the lowest cost that met the accuracy. Okay, so Hamel brought up a very good point, like minimum tau. So one thing that's very nice about this model cascade business is, let's see, suppose I Chose. And actually, oh, one thing I want to mention is that I want to redo p here to be if it's greater than tau, I will definitely have it be returning true. And if it's less than tau, I will have the proxy return false. So let's say that I've set this to be a possible tau. I'll call this tau 1. And then I am setting this guy to be a tau 2. Now something that's very interesting about accuracy is that the accuracy— basically, let's say that I have selected tau 2. My overall cost of my cascade when I select tau 2 is obviously going to be less than if I select tau 1. And this is actually hard to realize, so I'm going to say this again, right? If I select tau 2 for my decision point here, the overall cost is going to be less than if I select tau 1.
And that's because in tau 2, because there are more dots to the right of tau 2, and those dots all go to Smaller proxy, that's why it's cheaper?
Yes. So realize that this tau is like everything on the right of this tau is accepted by the proxy. Everything to the left of the tau is what gets labeled by the oracle. So by definition, right, the lower of a threshold that we could find, the happier that we will be, right? Because we are gonna find something lower cost. Ideally, we find something over here because that means we can accept all of these dots. Greater than the threshold. However, in practice, this is not the case because the proxy is not always accurate, right? For many of these middle confidence dots, the proxy may not be accurate. We will not meet our target accuracy. The lower threshold, the more cost saving that you'll have. Of course, you have to take care to make sure we meet the accuracy on the sample, but we want to find a lower threshold. So one thing that we can do to make this a more efficient algorithm is to instead write something here. What we're going to do is we can Sort cxi ascending, and then we can return first the xi that meets accuracy target. So that way we don't have to check all the possible cxi.
Sort the cxi ascending, do you mean you pick the tau equal to a certain cxi and then you set the taus?
Let's say set tau temporary equals cxi with threshold tau temp. So all we're doing here is like iterating through distinct values of cxi, and then we're trying to test whether the tau at C_x_i would give us the target.
Picking random tao's, you might as well just use the confidence interval, the numbers actually observed in your data, because those are the only ones that are going to make a difference at those specific thresholds anyways.
Yeah, so the optimization you can have in this tau finding technique is you can sort the C_x_i's and then start checking from the lowest, then the second lowest, and the third lowest, and so forth, and just stop as soon as you've met the target accuracy. Because that will be, you know, as low as you can go on that sample. But I want to quickly go over, you know, how we will run the cascade on all of the tickets. And this is not too complicated because you already know what a cascade looks like. But the second question, right, is how to run the cascade on all the tickets. And here the pseudocode is hopefully not too challenging. So we're given, given, now we have a tau that we've got from sample 1. We have all support Tickets X, we have proxy PX, and we have O X. Then our algorithm is just first run proxy P on all tickets, select the tickets for which CXI is less than tau, and then run oracle O on all tickets from step two, and then Return the predict for tickets with C_x_i greater than tau, 3, for low confidence. Again, this is really just running this architecture that I have shown you up here. You literally like run the proxy on everything if it's greater than tau, except otherwise you run the oracle. That's how simple it is. I want to mention some caveats. This procedure is not guaranteed to give you the target accuracy on all of the tickets. Why we're only finding it on samples, right? This is going to be a best estimate approach that we can get to trying to match the target accuracy. There are some ways that we can think about having some statistical guarantees on accuracy. Our Python package, this paper that we wrote, it's called Bargain. So you can just use that off the shelf. And this has some extensions to get statistical accuracy guarantees on the resulting cascade. Don't worry about what that means. If you really care about it, you can use this. The way that you would at a high level approach that, for all the statistically minded folks in the room, is to instead of naively recording the accuracy and cost for the samples, what we do is like we use concentration inequalities to estimate what accuracy might be given the sample size. You can use your favorite concentration inequality to do this. And then the other thing that I wanted to mention is there's a lot of interesting kind of research questions on how one might do this sampling. So you can get away with simply taking like a random sample of tickets, but often when you are doing random sampling, sometimes the sampling is a little bit wasteful. Like for example, a lot of these low confidence points are probably not gonna be correct, so those samples are a little bit wasteful. So you can think about doing more like stratified sampling or importance sampling. We, in the SPARGAN paper, we propose like an adaptive sampling algorithm. So there's a lot of really interesting stuff you can do there with sampling. Then finally, I'll, Last thing I'll mention is that this technique worked really, really well in practice. Like, we're able to get, like, cutting 90% of the cost or more on, like, a wide variety of classification tasks. And this is, like, just using the nano prediction model. Like, it just, it works very well for a sample. So for many of the documents.
So a lot of people are thinking about— this is meta, it's a meta question because, okay, people are thinking a lot about model routers, especially encoding agents, when they don't want to be using Fable for everything or Opus 5 for everything. And basically they want an LLM to decide, okay, like they need an LLM or something to classify what subagents should use. Have you heard of, or do you think you could try this for your router to like lower costs?
So I think the one thing I don't like about routers is they're very black box to us. Like we have no idea, like, you know, what accuracy we're getting, even like if we define a target or like an oracle, we have absolutely no idea. what accuracy we're gonna get when we use the model router. One thing that I really like about model cascades, right, is you have some sort of estimate. You know that it's like a sample-driven approach to trying to find this routing threshold. And so it's probably gonna work. It's fit to your data, so it's probably going to work better. Another thing I'll mention is that this really only works well for like classification, and it could also be, you know, multi-way classification, because what you need really good confidence scores. And so the confidence scores are much better calibrated for classification-oriented tasks, or when you're trying to predict like one have 10 classes, and so you just get the logits for like 10 different tokens, and then you're able to get the probability in this way. So unfortunately, you know, for open-ended tasks, I don't think we have very well-calibrated probabilities, and so therefore we're not often able to find taus that can meet the accuracy target at all. So that's why I like model cascades, because it tells us a little bit more about whether we can get the accuracy for our specific data, and it works very, very well for filters, classifiers. I would be a little bit hesitant to try to do it on an open-ended task because I don't know how we would get the confidence scores there. And perhaps model routing there is a better approach.
I have a super, super technical question. Bear with me for a moment. So do we really trust the confidence there from a Nano model and also the prediction? Because in my experience, wasn't able to trust the confidence If I run the prediction on the same text, sometimes it got yes, sometimes it got no. We're not even changing the prediction head, transforming to predicting text to predicting a label. What Shreya is presenting is like, you don't have to have any confidence in the confidence. She's telling you, look, like the model is producing this logit. It's basically a black box number, which hopefully has some signal in it. And we don't know how much signal it has, frankly. So we're going to do some experiments and measure how much we can trust this signal. Can we trust it? The accuracy is not correlated at all with the confidence. Let's say it's all over the place. As you slide tau up, like, it doesn't actually lead to higher agreement with the oracle because maybe because something messy is going on. Okay. You observe like tremendous noise in this thing. And so you would decide as a data scientist, like, you can't do this. For this particular problem, we can't approximate this oracle. So basically like, yeah, it's a black box. You should treat it with skepticism. And the whole point of doing the model cascade is for you to observe, like to do this data analysis to decide how much you trust it. Maybe Shreya has a different way of—
Let's assume in this worst case scenario that these confidence scores are fully random. At random, it could be correct or not correct. What will happen in our step 1 of sampling? What will happen is we will try to set the tau to be some threshold. We will simulate the model cascade. We will compute the accuracy and cost on that sample. The accuracy will not meet the target because the confidence are all wrong. And so what will end up happening is we will never find some threshold that meets the target accuracy. And then we'll say, oh, sorry, we couldn't find anything, right? So the procedure is not going to kind of lie to you. Because we are simulating on different confidence thresholds. Now for it to find a confidence threshold, it has to do well, and then you're okay. So like, I think a lot of people don't realize that it's okay if the confidence scores, you have no idea what's happening there. Because by going through this process of simulating what would happen if I selected a threshold, we will inevitably figure out if there's a threshold at all that meets the accuracy target.
I work through it very carefully, like an example of this, to make sure I understand it. That's the best way to understand this, honestly, is to kind of like do a little bit of an experiment. And like, there's that GitHub repo. Also, I know you, you mentioned like, hey, like this seems like a lot of information. This is a tip. It's like, okay, we're gonna send you this recording. The Chrome extension from Claude, ask Claude to download the video and just like ask questions of like, hey, what do they mean by this? What is this? It'll help you like work through what we said a little bit slower. So yeah, thank you.
Well, thanks everyone.










