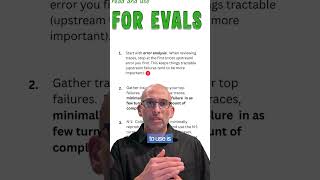
Hamel Husain shows how to analyze model traces without wasting time. Stop at the first error in the chain, collapse multi-turn failures into single turns, and collect the prompts that led there as reusable test cases.
Chapters
Looking at traces is really important if you're building an AI product so that you can write the right evals, but it's really easy to get lost in traces. This is part 10 of a 12-part series on evals. Today we're going to talk about how you can read and use traces correctly. So number 1 is you want to start with error analysis, and when you are reviewing traces for error analysis, what you want to do is look at your trace and stop at the first error you see. So you want to stop at the most upstream error, and the reason for this is that LLM workflows tend to be causal. Good heuristic to use is just stop at the first error you see and take note of that and move on. The second thing you want to do is if you do find an error and you're trying to create a test case from that trace, try to minimally reproduce that error in as few turns as possible. So let's say in this example on the flashcard, it's taken 3 turns before we hit the error. Can you minimally reproduce that same error in just 1 turn? That's always a good idea if you can do it. Another way to collect data from traces is you can gather the n 1 traces that led to the error. So in the flashcard, you'll see the first 3 of these turns can be used as a way to invoke the same error. Another way that you can use traces is to modify existing ones. So what you can do is you can use another LLM to change the trace in valid ways to give yourself more data. And lastly, the most advanced technique is to use another LLM to simulate a user, but this is really hard to do correctly, so use this carefully. If you're interested in this topic as well as learning more, about evals, I put a link in the comments that gives you access to all these flashcards as well as other resources.