Why Generic Eval Metrics Waste Your Time

14 Oct 2026 · 1 min
0:44

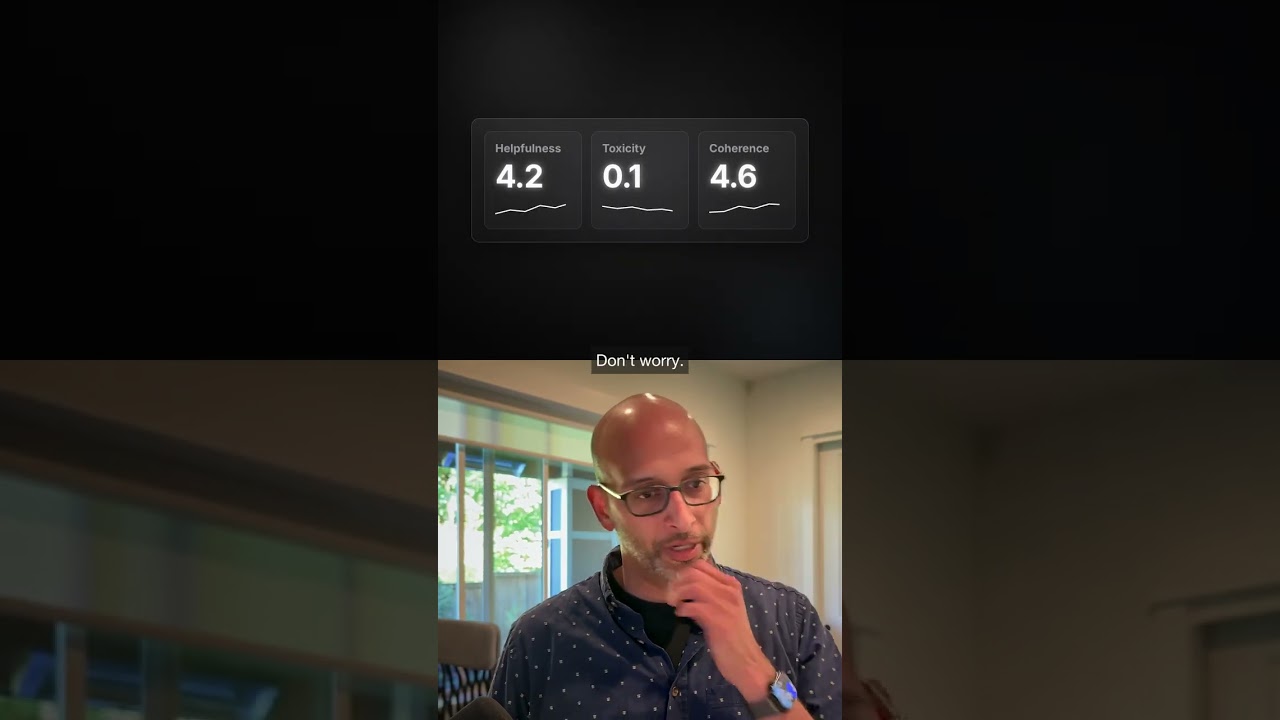
In this brief monologue, Hamel Husain argues that the widespread reliance on generic helpfulness and toxicity scores—often offered as plug‑and‑play evaluation tools by vendors—fails to address the specific challenges of real applications. He explains that these one‑size‑fits‑all prompts and dashboards rarely align with the most critical problems teams actually face, leading them astray. The resulting focus on metric dashboards consumes mental energy and meeting time that could be better spent solving genuine issues in the product.
Chapters

More from Hamel

0:47
youtube.com

Stop Splitting One Task Across Multiple Agents

18h ago
3:23
youtube.com

How To Decide Who Owns AI Evals

18h ago
0:41
youtube.com

The Two Biggest Mistakes Teams Make With Evals

1d ago
3:16
youtube.com

Can One Model Run Your App And Evals?

1d ago
21:18
youtube.com

How to Ace AI Eval Interview Questions (for Engineers & PMs)

2d ago
0:31
youtube.com

Not Every Bug Needs an Eval

3d ago
47:59
youtube.com

Can Claude Build Your Evals?

3d ago
0:46
youtube.com

How to Get Your Team to Care About Evals

4d ago
12:47
youtube.com

7 Most Common AI Eval Mistakes (From Teaching 5K+ Engineers & PMs)

4d ago
40:01
youtube.com

How To Test AI Agents With Simulations

6d ago
0:43
youtube.com

Why Your LLM Judge Should Say Pass or Fail, Not 1 to 5

1w ago
See all content