Andrew Ng introduces convolutional neural networks and why they matter for computer vision tasks like self-driving cars and face recognition. A fully connected network on a high-resolution image creates billions of parameters, making it impractical. Convolution solves this by reducing the parameters needed to process large images.
Chapters
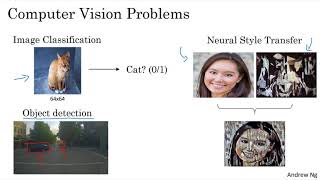
Welcome to this course on convolution neural networks. Computer vision is one of the areas that's been advancing rapidly thanks to deep learning. Deep learning computer vision is now helping self driving cars figure out where are the other cars and the pedestrians around it, so as to avoid them. It's making face recognition work much better than ever before. So that perhaps some of you will soon, or perhaps already be able to unlock a phone, unlock even a door using just your face. And if you look on your cell phone, I bet you have many apps that show you pictures of food, or pictures of a hotel, or just fun pictures of scenery. And some of the companies that build those apps are using deep learning to help show you the most attractive, the most beautiful or the most relevant pictures. And I think deep learning is even enabling new types of art to be created. So I think the two reasons I'm excited about deep learning for computer vision and why I think you might be too. First, rapid advances in computer vision are enabling brand new applications to be built that just weren't possible a few years ago. And by learning these tools, perhaps you will be able to invent some of these new products and applications. Second, even if you don't end up building computer vision systems per se, I found that because the computer vision research community has been so creative and so inventive in coming up with new neural network architectures and new algorithms, it has actually inspired or created a lot of cross fertilization into other areas as well. For example, when I was working on speech recognition, I sometimes actually took inspiration from ideas from computer vision and borrowed them into the speech literature. So even if you don't end up working on computer vision, I hope that you find some of the ideas you learned about in this course helpful for some of your algorithms and your your architectures. So with that, let's get started. Here are some examples of computer vision problems we'll study in this course. You've already seen image classification, sometimes also called image recognition, where you might take as input sequence say a 64 by 64 image and try to figure out is that a cat? Another example of a computer vision problem is object detection. So if you're building a self driving car, maybe you don't just need to figure out if there are other cars in this image, but instead you need to figure out the position of the other cars in this picture so that your car can avoid them. So in object detection, usually we have to not just figure out that these other objects, say cars in the picture, but also draw boxes around them or have some other way of recognizing where in the picture are these objects. And notice also in this example that there can be multiple cars in the same picture, or at least every one of them within a certain distance of your car. Here's another example, maybe a more fun one, is neural style transfer. Let's say you have a picture and you want this picture repainted in a different style. So neural style transfer, you have a content image and you have a style image. The image on the right is actually a Picasso, and you can have a neural network put them together to repaint the content image, that is the image on the left, but in the style of the image on the right, and you end up with the image at the bottom. So albums like this are enabling new types of artwork to be created. And in this course you learn how to do this yourself as well. One of the challenges of computer vision problems is that the inputs can get really big. For example, in previous courses you've worked with 64 by 64 images. And so that's 64 by 64 by 3 because there are three color channels. And if you multiply that out, that's 1, 2, 2, 8, 8. So X, the input features has dimension 1, 2, 2, 8th, 8. And that's not too bad. But 64 by 64 is actually a very small image. If you work with larger images, maybe this is a thousand pixel by thousand pixel image, and that's actually just one megapixel. But the dimension of the input features will be thousand by thousand by three, because you have three RGB channels and that's three million. And if you are viewing this on a smaller screen, this might not be apparent, but this is actually a low res 64 by 64 image. And this is a high res 30,000 by thousand image. But if you have 3 million input features, then this means that X here will be 3 million dimensional. And so if in the first hidden layer, maybe you have just a thousand hidden units, then the total number of weights, that is the matrix W1. If you use a standard fully connected network like we have in causes one or two, this matrix will be a 1000 by 3 million dimensional matrix, right? Because X is now R by 3 million 3M I'm using to denote 3 million. And this means that this matrix here will have 3 billion parameters, which is just very, very large. And with that many parameters, it's difficult to get enough data to prevent the neural network from overfitting. And also the computational requirements and memory requirements to train a neural network with 3 billion parameters. Is just a bit infeasible. But for computer vision applications, you don't want to be stuck using only tiny little images. You want to use large images. To do that, you need to better implement the convolution operation, which is one of the fundamental building blocks of convolutional neural networks. Let's see what this means and how you can implement this in the next video, and we'll illustrate convolutions using the example of edge detection.