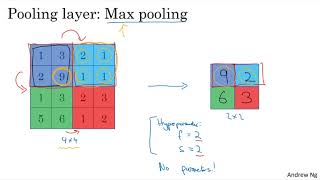
Max pooling reduces spatial dimensions by taking the maximum value in each filter window. With a 4x4 input, F=2 and S=2 produces a 2x2 output. Pooling has no learnable parameters and preserves the number of channels.
Chapters
Other than convolutional layers, confidence often also use pooling layers to reduce the size of the representation to speed up computation, as well as make some of the features it detects a bit more robust. Let's take a look. Let's go through an example of pooling and then we'll talk about why you might want to do this. Suppose you have a four by four input and you want to apply a type of pooling called max pooling. And the output of this particular implementation of max pooling will be a 2x2 output. And the way you do that is quite simple. Take your 4x4 input and break it into different regions. And I'm going to color the four regions as follows. And then in the output, which is 2x2, each of the outputs will just be the max from the correspondingly shaded region. So in the upper left, I guess the max of these four numbers is 9. Upper right, the max of the blue numbers is 2. Lower left, the biggest number is 6, and lower right, the biggest number is 3. So to compute each of the numbers on the right, we took the max over a two by two region. So this is as if you're applying a filter size of two, because you're taking two by two regions and you're taking a stride of two. So these are actually the hyperparameters of max pooling. Because we start from this filter size, it's like a two by two region that gives you the nine. And then you step it over two steps to look at this region to give you the two. And then for the next row you step it down two steps to give you the six. And then step it to the right by two steps to give you three. So because the squares are two by two, F is equal to two. And because you, you know, stride by 2s is equal to two. So here's the intuition behind what max pooling is doing. If you think of this 4 by 4 input as some set of features, you know, maybe not. If you think of this four by four region as some set of features, deactivations in some layer of the neural network, then a large number means that it's maybe detected a particular feature, right? So the upper left hand quadrant has this particular feature, maybe a vertical edge or maybe an eye or a whisker, if you're trying to detect the cat. But you know, clearly that feature exists in the upper left hand quadrant, whereas this feature, maybe there's a cat eye detector, whereas this feature doesn't really exist in the upper right hand quadrant. So what the max operation does is so long as the feature is detected anywhere in one of these quadrants, it then remains preserved in the output of max pooling. So what the max operator does is really says, you know, if this feature is detected anywhere in this filter, then keep a high number. But if this feature is not detected, so maybe if this feature doesn't exist in the upper right hand quadrant, then the max of all those numbers is still itself quite small. So maybe that's the intuition behind max pooling. But I have to admit I think the main reason people use max pooling is because it's been found a lot of in a lot of experiments to work well. And the intuition I just described, despite it being often cited, I don't know if anyone fully knows if that's the real underlying reason. I don't know if anyone knows that that's the real underlying reason that max pooling works well in confidence. Um, one interesting property of max pooling is that it has a set of hyperparameters, but it has no parameters to learn. Right? There's actually nothing for gradient descent to learn once you've fixed FNs. It's just a fixed computation and gradient descent doesn't change anything. Let's go through an example with some different hyperparameters. Here we're going to use, here you have a five by five input and we're going to apply max pooling with a filter size that's 3 by 3. So F is equal to 3 and let's use a stride of 1. So in this case the output size is going to be three by three. And the formulas we had developed in the previous videos for figuring out the output size for a conv layer, those formulas also work for max pooling so that n +2p -f over s4 +1. That that formula also works for figuring out the output size of max Boolean. But in this example let's compute each of the elements of this three by three output. The upper left hand elements, we're going to look over that region. So notice this is a 3 by 3 region because the filter size is 3 and to the max there. So that's going to be nine. And then we're shifted over by one because we're taking a stride of one so that max in the blue box is nine. Let's shift that over again. The max of the blue box is 5 and then let's go on to the next row. A stride of one. So we're just stepping down by one step. So Max in that region is nine. Max in that region is nine. Max in that region. Oh, there are two fives, but the max is a five. And then finally, max in that is eight. Max in that is six. And max in that, there's a nine in the lower right hand corner. Okay, so this, with this set of high parameters, F equals 3s equals 1 gives that output shown on it. Now, so far I've shown max pooling on a 2D input. If you have a 3D input, then the output will have the same dimension. So, for example, if you have 5 by 5 by 2, then the output will be 3 by 3 by 2. And the way you compute max pooling is you perform the computation we just described on each of the channels independently. So, you know, the first channel, which is shown here on top, is still the same. And then for the second channel, I guess this one that I just drew at the bottom, you would do the same computation on that slice of this volume. And that gives you, you know, this second slice. And more generally, if this was 5 by 5 by some number of channels, the output would be 3 by 3 by that same number of channels. And the max pool income putation is done independently on each of these NC channels. So that's max pooling. Um, there's one other type of pooling that isn't used very often, but I'll mention briefly, which is average pooling. So it does pretty much what you'd expect, which is instead of taking the maxes within each filter, you take the average. So in this example, the average of the numbers in purple is 3.75, then that's 1.25 and 4 and 2. And so this is average pooling. With Hyperparameters, F equals 2, S equals 2. We can choose other hyperparameters as well. So these days, max pooling is used much more often than average pooling, with one exception, which is sometimes very deep in the neural network. You might use average pooling to collapse your representation from some say 7 by 7 by 1000 and average over all the spatial extents to get 1 by 1 by 1000. We'll see an example of this later. But you see max pooling used much more in the neural network than average pooling. So just to summarize, the hyperparameters for pooling are F the filter size and S the stride. And maybe common choices of parameters might be f equals 2, s equals 2. This is used quite often. And this has the effect of roughly shrinking the height and width by a factor of about 2. And the common choice of hyperparameters might be f equals 2, s equals 2. And this has the effect of shrinking the height and width of the representation by a factor of 2. Have also seen F equals 3s equals 2 used. And then the other hyperparameter is just, you know, the binary bit that says are you using max pooling or are you using average pooling? If you want, you can add an extra hyperparameter for the padding, although this is very, very rarely used. When you do max pooling, usually you do not use any padding, although there is one exception that we'll see next week as well. But for the most part, max. Max pooling usually does not use any padding. So the most common value of P by far is P equals zero. And the input of max pooling is that you input a volume of size that NH by NW by nc and it would output a volume of size given by this, right? So assuming this, there's no padding by NW minus F over S plus 14 by NC and so the number of input channels is equal to the number of output channels because pooling applies to each of your channels independently. One thing to note about pooling is that there are no parameters to learn. So when, when we, when you implement backprop, you find that there are no parameters that backprop will adapt through max pooling. Instead, they're just these hyper parameters that you set once, maybe set once by hand, or set using cross validation, and then beyond that, you know, you're done, and it's just a fixed function that the neural network computes in one of the layers and there is actually nothing to learn. It's just a fixed function. So that's it for pooling in the. So that's it for pooling. You now know how to build convolutional layers and pooling layers. In the next video, let's see a more complex example of a convnet, one that will also allow us to introduce fully connected layers.










