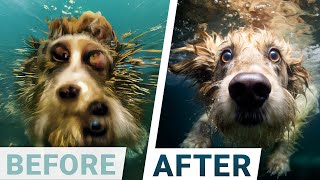
Dr. Zsolnai shows how Midjourney version 5 generates images from text prompts, comparing it to DALL-E 2 and Stable Diffusion. The quality jump in a year is dramatic: photorealism, character design, and game environments look nearly indistinguishable from human work. Hands still break, but everything else got terrifyingly good.
Chapters
Dear fellow scholars, this is Two Minute Papers with Dr. Zsolnai. Today we will celebrate how far we have come. Not so long ago I made these pictures with OpenAI's text to image AI DALL E2 and I was elated. These are really cool and have tons of personality. And if then someone told me that just a few months later I will get results from a newer system that makes these pale in comparison, I wouldn't have believed a word of it. And my goodness, that is exactly what happened. You see, this is the midjourney text to Image AI and I was stunned when I found out that the first version of it appeared in February 2022, just a bit more than a year ago. And today we are on version 5 and we are here to celebrate how far we have come. These results are simply unbelievable. So first, let's have a look at a Fox scientist with version one. Well, these results are not great. It is still remarkable that a machine can give us something like this. But if I didn't tell you that this should be a Fox scientist casting a magic spell, I don't think you would have guessed. And it is not a question of getting a good randomized run, because we can try over and over again. And brace yourselves for some Picasso ish results. These aren't much better, perhaps even worse. And now hold on to your papers, fellow scholars. And here come the results with version 5. Oh my goodness. Wow, look at that quality. I cannot believe what I am seeing here. Because what you see here is progress. In just one year we can even request more or less stylized images and it delivers over and over again. And I have to note that this was not a very elaborately written prompt. I just asked for a stern looking fox in a lab coat casting a magic spell. What's more, there is a separate model that we can use in midjourney that is specifically tailored for Japanese anime and and illustrative styles. And that one delivers too. And I am truly shocked to find out that looking at the new results, the one that I previously thought was a legendary image really pales in comparison. And this System can generate 10,000 better ones every single day. Wow, my mind is blown. Now we are going to explore four more categories with eye poppingly beautiful results. First, video Game Environment Concepts. This is version one. Taking a crack at it. This is not the eye poppingly beautiful result, that's for sure. And can you tell what the prompt was? Neither can I, unless I look. Yes, we were looking for a mountainous location in a fantasy world with low polygon Models. It does have a certain mood and I kinda like some of them. But. But I cannot wait to see the results with the new version. Look, now we're talking. Or if we feel that the game needs some more adventure here, we can let our imagination take over and ask, for instance, for a palace. Hmm, that looks good. I like this one too. 2. Next up, photorealism. Oh boy, is it good at that. If you are looking for a funny image of a dog that is a little lost underwater, I would like to ask you if you are ready to see the results with version 1. Not for the faint of heart. So, are you ready? Are you sure? Ok, here we go. Oh my. Everything everywhere. Not great. So what do we get today, a year later? What? These look ridiculously detailed. Now that is what I call an incredible improvement. It nailed the depiction of the frightened eyes of this poor dog. And now little AI. I'd like an incomplete humanoid Android, please. Version one. And then version five. I'll tell you some more about imperfections in a moment. But I am stunned. I cannot recover from the fact that all this improvement took place in just one year. Loving it. 3. After photorealism, how about a little art? A pixie girl in an underwater dreamland. By now you know the drill. Version one, you know what to expect. Yes, roughly that. Now the new version. Whoa. How is that even possible? These are so good. Imaginative even. And we don't have to hunt for too long for these results. The technique delivers over and over again. Sorry, I know I keep saying this, but all this improvement in just one year is absolutely stunning. Can you even imagine what we will be able to do with this? Two more years and papers down the line. Now, for after art, how about photos of people? This time I won't bore you with the version one results. Let's go straight to the new ones. Since we can control these results with our text prompts in each case, we can keep the scene and the lighting fixed and just change the appearance of the test subject. If we decide that we don't like the long straight hair, we can ask for curly hair instead. Or change the test subject entirely. It feels like we can do absolutely anything today. Now, if you're interested, as Midjourney requires a subscription as a substitute, you can also use Stable Diffusion for free on the web or run it on your own hardware to get similar results. What is even more mind blowing is that you can even run it on your own phone. Then all the computation for this takes place in your pocket. You can carry it anywhere you want. And unleash your creativity on the go. And all this for free for everyone. Fantastic. We will have several episodes coming on Stable diffusion, so if that is something that you find interesting, consider subscribing and click the bell icon to make sure not to miss it. And to think that all this is going to get faster and easier over time. Now, as promised, I'd like to show you that not even this amazing current version is perfect, although hands and interactions with hands are still a problem. If we rerun the prompts with version 5 a few times, it usually gets them right, except in one scholarly case. What is the scholarly case, you ask? Well, like creating an icon for a robot hand holding on to papers. I don't know what that would be useful for. Do you have any ideas? This did not go too well. Look, this AI can do anything you want, but it still can't hold on to its papers. What a time to be alive. So what do you think? What would you use this for? Let me know in the comments below. This video has been supported by weights and biases. Look at this. They have a great community forum that aims to make you the best machine learning engineer you can be. You see, I always get messages from you fellow scholars telling me that you have been inspired by the series but don't really know where to start. And here it is. In this forum you can share your projects, ask for advice, look for collaborators and more. Make sure to visit WNB me paperforum and say hi or just click the link in the video description. Our thanks to Weights and Biases for their long standing support and for helping us make better videos for you. Thanks for watching and for your generous support and I'll see you next time.