New Open AI Leak! (And Other AI News)
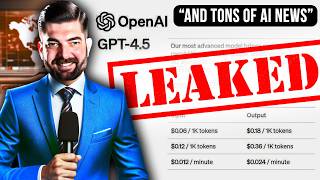
Matt Wolf covers AI news from December 2023: an unconfirmed Reddit leak claims OpenAI is working on GPT-4.5 with audio and video support, Google releases Gemini Pro and NotebookLM, and Mistral drops Mixtral of Experts, a new open-source model architecture.
Chapters
I got a new sweater from Microsoft. It's actually the Windows XP old background. I thought it was pretty cool. Anyway, I got a lot of AI news that I want to cover with you and show off some really cool stuff. So let's just jump right into it, starting with the news that maybe we have a leak on the next version of GPT with GPT 4.5. Now this isn't confirmed 100%. This was found on Reddit. We can see the URL up here is some sort of draft, but according to this leaked screenshot here, GPT 4.5 is going to be the most advanced model with audio, vision, video and 3D alongside complex reasoning and cross modal understanding. And under this API pricing list here they've got GPT4.5, GPT4.5, 64K and GPT 4.5 audio and speech. We also see a link that looks like it's a vision and 3D pricing calculator here. So based on what we're seeing on this screenshot, if true, we'll be able to use video and 3D with the GPT4.5 API API, which means we'll most likely get those things in chat GPT as well. A couple things I find very interesting about this is that the pricing here seems extremely high, especially when you compare it to the GPT4 turbo model that they just released last month. In November you could see GPT4 and GPT4 Vision where $0.01 per 1000 tokens input and $0.03 per 1000 tokens output. Compare that to GPT 4.5 at $0.06, six times the cost for input and $0.18 for 1000 tokens output. And the 64,000 context window version is $0.12 per thousand tokens and $0.36 per thousand tokens output, 12 times increase in cost. And what I even find more interesting is that GPT4 Turbo seemingly is 128,000 context window, while 4.5 drops down to a 64,000 context window, or half of what GPT4 Turbo is. Again, this is a leak that was found on Reddit. Nobody at OpenAI has confirmed this, but it's always fun to kind of speculate on what we're going to get next from some of these tools. Speaking of OpenAI, there's this theory going around right now where GPT4 might actually perform worse during the winter months, and the reason being that GPT4 was trained on all of this data on the Internet, and based on the data it was trained on, people tend to take more time off in December and tend to be a little bit lazier in December. The theory on this is that maybe GPT4 adopted some of those traits because it's essentially acting based on all of its training data. You can see Ethan Mollick here says omg the AI winter break hypothesis may actually be true. There was some idle speculation that GPT4 might perform worse in December because it learned to do less work over the holidays. Here's a post from Rob lynch here where it says GPT4 Turbo over the API produces shorter completions when it thinks it's December versus when it thinks it's May. So they updated the system prompt to tell GPT that it was May and it actually performed better than when the system prompt believed it was December. So if you feel like ChatGPT or GPT4 is giving you shorter responses and just overall being lazier with how it's responding, it may be this winter holiday hypothesis that they've got Also while on the topic of OpenAI, Axel Springer and OpenAI are partnering to deepen the beneficial use of AI in journalism. Basically what this is is that the media company Axel Springer, which is a news outlet that owns brands like Politico, Business Insider, Build and Welt, are going to partner with ChatGPT to keep ChatGPT up to date on the news so you can prompt and ask questions about current events and news with ChatGPT and it will use these media properties content for that updated information on the news. This is interesting because it really is a full circle moment here. If you think this Axel Springer sounds familiar in the context of OpenAI, that's because, well, back in July a bunch of top publishers were planning on suing AI firms. This article isn't new. This is from July 24th here, but the New York Times, News Corp. Axel Springer, Meredith owner AIC and others are in the process of forming a coalition to take on AI giants like Google and OpenAI. So what a difference five months can make. Back in July 2023, Axel Springer wants to sue OpenAI for using their content. Fast forward to December 2023. OpenAI and Axel Springer are partnering to make sure that Axel Springer's content is included inside of OpenAI's responses. Pretty wild turn of events there. Also, if you're somebody that's been wanting to get into ChatGPT plus but haven't been able to because it's been shut down, well, apparently Sam Altman and the OpenAI team found more GPUs and now ChatGPT plus subscriptions have been re enabled. So if you're not a Plus member and you've been wanting to be one, you can do it now. Now, in last week's news video, I was very critical of how Google handled their launch of Gemini. They made a video that was less than honest about what they were doing. They made it look like a whole bunch of video footage was being inputted. And then in real time, Gemini was giving responses. But it turns out what we're hearing was narrated over completely different prompts were used and they used images and not video. And that wasn't abundantly clear in that video, making me and a lot of other people who watched that video a little bit frustrated with how it was handled. Well, a few days ago, Greg Technology here on his YouTube channel demoed that you can mostly do all the same stuff they were doing in that Gemini video with GPT4 Vision right now. Now, I will tell you full transparency. I am speeding this up because when he does show off things on camera and he waits for the response from GPT, it does take a little bit of time and I'm closing those gaps a little bit. So check this out. What gesture am I doing? You are making a heart shape with your hands. What game am I playing? You are playing rock, paper, scissors. I drew this. Can you tell me what I what is that? The drawing appears to be of a duck or a similar bird on water. So many of the most impressive things that came out of the Gemini demo we can do right now, today with ChatGPT vision and actually do it with video. And Google definitely got heat for that demo. Almost every single news source was reporting on the fact that it was faked or they weren't super clear with how this content was produced. And Google's response was in the following week, they released a whole bunch of new AI stuff that people can use. For example, they launched Notebook lm, which in my opinion is actually a pretty dang handy tool. With Notebook lm, you can actually drag and drop a bunch of files like PDFs and Google Docs and then use their little search box or prompt box here to use what you uploaded to get responses. So it's a great tool for things like research and for students to upload all of their notes from class and then to sit there and have a conversation and find specific information from the documents that you uploaded. It also will give some suggested actions after you upload your notes, like summarize to note, add quotes, suggest related ideas, and help me understand. In this example here, they select all of their notes, click a button to create an outline and then it creates an outline based on all six of these documents that they had notes for. Now tools like Claude and Chat GPT can do this, but this is very purpose built for this and from what I can tell probably does a bit better of a job at finding specific information from within the docs. I personally haven't used NotebookLM yet. I'm still on the waiting list, but it is rolling out to people now. If you join the waiting list. Google also announced that their Gemini Pro API is available so developers can actually start developing with this API today. It's got a 32,000 context window which gets you about 24,000 words input and output and it's actually free to use right now. However it will cost some money pretty soon. Now it's free within limits. As long as your tool is doing less than 60 requests per minute, you can use the API right now for free. So I imagine a whole bunch of new apps are going to pop up pretty soon that are using Gemini Pro in the back end instead of something like the GPT API or Claude's API. Comparing the Gemini Pro pricing, it appears to be less expensive than the GPT4 pricing, with GPT4 Turbo being about 1 penny per thousand tokens and Gemini Pro being.00025 cents per 1000 tokens. And even compared to GPT 3.5 Turbo which is 0.001 per 1000 tokens, this is still quite a bit less expensive. And while still on the topic of Google, this week Google also released Music fx. It used to be called Music LM and they rebranded to Music fx. But we can type whatever we want in here and let it generate some music for us. My previous tests I've tried early 2000s pop, punk, anthem. So let's try that and here's what we get from it. Definitely much better than what we were getting out of Music LM before and also quite a big leap above what we were getting from something like Stable Audio. We have some extra settings here. We get our seed, we can actually change the track length all the way up to 70 seconds and we have the option to turn on looping, which will be great for making videos where you don't know how long the video is going to be, but you want music in the background, make the music loop. We can download our music here and then over here. It gives us dropdowns on these various areas so that we can tweak it a little bit. So I can change early 2000s to 1990s change pop punk to indie pop. And instead of anthem, I could use this slider to change it to insanely slow normal speed really fast. Let's just go fast. 1990s indie pop fast. We get something that sounds like this. I'm impressed with what they're doing. You can find this one over@aitestkitchen.with google.com and it's called Music FX. Like I said, Google made a lot of announcements this week. They also rolled out Imagen 2 for Vertex AI customers. This image model supposedly is good at text rendering in multiple languages. It's good at logo generation and visual question and answering for generating captions from images and for getting informative text responses to questions about image details. Here's some example prompts with their output A mosaic inspired portrait of a person, their features formed by a collection of small colorful tiles. A studio portrait of a man with a grizzly beard eating a sandwich with his hands. Dramatic skewed angled photography. Film noir. Here's some examples of text rendering where they made a tube of toothpaste with the word symbol on it. They made a cup of yogurt with the word delicious on it. Here's some logo generations they were able to make with it. Apparently Snapchat is already using this model, Shutterstock is using this model and Canva is using this model. A shot of a 32 year old female up and coming conservationist in a jungle. Athletic with short curly hair and a warm smile, a jellyfish on a dark blue background, small canvas oil painting of an orange on a chopping board, et cetera. Here's some more examples of the realism where you can see they specifically honed in on the hands. It's got inpainting where you can add stuff into the image out painting, essentially uncropping the image, making it bigger and having it fill and the rest of the details. So it's pretty cool. But it doesn't seem to have a front end user interface for just anybody yet. If you want to use Imagen 2 to generate images, you're going to have to use one of the tools that uses it, like a Canva or a shutterstock or something like that. There is no front end user interface that directly creates images with Imagen 2 yet that I'm aware of. If I'm wrong, let me know in the comments and point people to where they can use it as well. Now, speaking of AI images, Wirestock just rolled out a cool new feature and they happen to be the sponsor of today's video. If you're not familiar with Wirestock. They are a single platform where you can upload your photographs, your unique images and your AI generated images to one platform and it will distribute them to all of the stock photography websites that are available. And yes, they do allow you to upload AI generated images. They even have an AI image generator built in. Because some of the stock photo sites, sites like Imago, Adobe Stock 123, RF, Dreams, Time and Freepik, all do allow you to sell AI generated images. But about that new feature I was telling you about, they just rolled out a tool called Themes for Premium users where you can train a custom style into their image generator. And if other people use your style, you can earn income because they use that style. Inside of wirestock, I can click on the Themes button, click on Create a new Theme, and I can upload a minimum of 10 images that all have a similar style to them and it will train this custom theme. Some examples of existing themes, you've got this female warriors theme here, this macro butterfly theme that anybody can use, this retro collage theme. And if I click Use on one of these themes, I could enter any prompt I want, make sure the proper theme is selected, click Generate and generate my own images that follow that specific theme that I just selected. So if you like to generate AI art or generate your own custom AI art styles, a site like Wirestock helps you earn extra income from that work that you're putting into those AI images. You can learn more by going to Wirestock IO or using the link in the description. And if you do decide to upgrade to a premium account to create things like your own custom themes, make sure you use the coupon code MATT20 for an extra 20% off. Again, check it out over at Wirestock IO. Use coupon code MAT20 and start turning those AI generated images and themes into a little passive income stream. Thank you once again to Wirestock for sponsoring this video. Now, while we're on the topic of AI art, Midjourney actually had a nice little update this week. I learned about this from Nick St. Pierre here over on X. They're now giving some people the ability to create images directly from the Midjourney website. You don't need to use Discord anymore. However, there is a catch. You have had to have generated over 10,000 images with midjourney already and be one of their power users in order to use this feature. I double checked. I've only generated about 2,500 images myself so far. But luckily Nick here gives us a nice overview of what this new website looks like. In other Midjourney news, Alijules was once again on the Mid Journey Office Hours this week where they announced that they're about ready to Release Midjourney version 6. They've already finished an internal rating party where the people inside of Midjourney pick between a whole bunch of sets of two images to decide which image is better. And it further trains Midjourney to get to the style they're looking for. And they're about to start doing an external rating party where us Midjourney users get to pick between two midjourney version 6 images and further tune it in on the styles that we like from Midjourney. According to the Office hours, the first external rating party is possibly happening Friday and Saturday of this week. So by the time you see this video, it might already be happening. And if you're into AI art and Midjourney, I highly recommend being a part of this Midjourney rating party because a, you get to be a part of sort of fine tuning the model and steering the direction where it goes, but B, you also get a little sneak peek into what we can expect from Midjourney version 6. Stability AI released a new model this week called Stable 0123. This is a model where you can upload a 2D image and it will try to turn that 2D image into a 3D image. Here's an example where they uploaded this image of a dinosaur here. Their older model here was the result where it generated that same dinosaur from multiple angles. But you can see it's got some funkiness going on. Here's their new stable 0123, where still a little bit of funkiness. Got a little extra leg grown out of the leg, but for the most part it did a pretty good job of finding different angles on this dinosaur. So from this 2D image, it generates all of these other angles, and once it has all of these other angles, it's able to then generate a 3D image and sort of fill in the gaps. And once again, as has been a theme with Stability AI lately, they're releasing it for non commercial use. They used to be some of the biggest proponents of open sourcing everything. Now almost everything they put out is not for commercial use. While we're on the topic of Stability AI, it kind of seems like Stability is trying to figure out how to monetize and make more money off of what they're doing. Most of how they generated revenue in the past was through APIs, and it sounds like now they're going to sort of flat fee the APIs. So there's a few tiers here. There's the non commercial tier, which is pretty much anybody can use these tools for free if they're using them for research and non commercial purposes. If you do want to use it for more commercial purposes, you can pay 20 bucks a month. And as long as you have, I believe, less than a million dollars a year in revenue or less than a million users, you can stay on this professional tier before kind of having to go to some sort of custom enterprise pricing for larger tier customers. They do also say here though, if you wish to use our core models commercially but find the cost to be a barrier, we have some discounts available to support these circumstances. Please contact us to learn more. So from my understanding, for 20 bucks a month, as long as you have under a million dollars or a million users, you could use their APIs in your tools. That to me seems really, really cheap, but I might also not be understanding this correctly. This week Anthropic also rolled out a new update where you can now add Claude to Google Sheets. This allows you to do things like generate prompts directly inside of cells. However, I've personally followed their instructions step by step. Tried it multiple times, uninstalled it, reinstalled it, done everything I can think of. I haven't been able to get it to work for me. Whenever I come up to extensions Claude for sheets, it only gives me the option for help. When I click on that, it gives me instructions. I follow these instructions. Still doesn't work. Did some googling and asking around on how to fix it. Everybody keeps saying refresh the sheets and it should work. I refresh the sheets. I even close out of the sheets and get back into it. No matter what I do, no other options other than help show up. So I don't know what I'm doing wrong here. But I cannot get Claude for sheets to work at all. And when I read the reviews pretty much other people are saying that they have the same problem, would not load. Extension just gives the option to help. Extension is not loading in the extension tab, it just shows help. Supposedly a few people have gotten it to work. This person says you have to refresh the sheet doesn't work. So while cool, Claude needs to get it together with the installation process because it's not working right now. This week a unique large language model came out called Mixtral of Experts. This is from the French company Mistral AI and it's actually an open source model that performs better than llama 2 in most cases and better than GPT 3.5 in most cases. But what's really interesting about this one is sort of how it works. It approaches large language models in a completely different way. I kind of want to break it down for you because I actually think this is the future of how large language models are going to work. It's much more efficient. So I made this simple little diagram here to try to best explain it. So here's you right here. You give it a text input, you ask it a question, you give it a prompt, you do whatever you do. When you ask it this question, it then sends it to a router. And there's a whole bunch of smaller language models essentially that have different expertise in different areas. So, you know, maybe this one is trained and really good at code, and maybe this one's really good at creative writing, and maybe this one's really good at facts. And each of these models is trained on a much smaller data set, but more specific to different areas. Now, when you ask this text input, it goes to this router and then the router decides what two best experts should it pass this prompt to. So based on your question, it'll determine, okay, this is a coding related question and we also need facts in that code. So it sends your prompt to expert number one and expert number three. Expert number one and expert number three both reply and send the information back. Once it goes back, it essentially combines and summarizes the responses from those two experts and then sends the information back to you. Now this is an oversimplification of how this works, but I honestly think this is the future. Having one giant large language model where you send it a prompt and then it has to sift through all this data to find the response. Having a whole bunch of more finely tuned models with various domain knowledge makes more sense. You have where you enter the prompt and AI then figures out, okay, what is the best model to ask this question to, sends it to just that model. It uses way less compute, way less processing power because it's just searching that sort of domain knowledge and then sending the answer back to the user. It's a much more interesting way to go about it. It's a lot more efficient. And each of these experts can be essentially trained in different areas and specialize in different areas. And over time I imagine the models will just have more and more and more experts with more and more domain knowledge. So that's mixtral from Mistral and I think it's a pretty exciting open source large language model that we can Play with now. Moving on to Meta News, Meta launched their audio box and gave us a demo where we can actually play with it now. And it has a bunch of cool features in it, like you can train your own voice in it and then generate more speech with your voice. You can create novel voices and actually describe the speaking voice that you want it to sound like. You can restyle voices, you can generate sound effects, you can erase things from existing audio, and you can even infill and replace things from existing audio. So if we do described voice, we give it a prompt and then we describe the speaking voice like a male with a deep voice speaks in a large cathedral and then click generate. Here's what we get subscribe to Matt Wolf on YouTube. And here's another variation. Subscribe to Matt Wolf on YouTube. And that's just 16 capabilities that you can play with. Something that I'll probably have to do a deeper dive video on later because I don't want this video to be 45 minutes long. But I'll make sure it's linked up in the description so you can play around with it yourself. Speaking of Meta, Meta just rolled out a new update to their Ray Ban sunglasses, which I happen to have a pair of right here. The new update actually adds vision to this. It uses llama2. You can ask llama2 questions, but now you can ask questions about what you're seeing with the glasses. So I can put these glasses on and say, hey, Meta, what am I looking at right now? It'll give me a description or have Meta translate text on a sign for me. My glasses just talk to me. Apparently they're rolling it out to people in the US right now. I've checked my app multiple times. I've updated the app, I've updated the firmware on the glasses. The option still doesn't show up for me. Once it does show up, I'll probably demo it in a future video, but I don't have access to. I just know they seem to be rolling it out to people because a bunch of articles have told me they're rolling it out to people now. I've done videos in the past about nerfs, and I've talked about Gaussian splatting. And these are basically techniques where you can take photos around a room or even video around a room, let an AI process those photos or videos, and then it actually creates an environment that you can move around in like you see on the screen here. Well, Google just released some new research called Smurf Streamable Memory efficient radiance fields for real time large scene exploration, which is seemingly an even better model than what we got from Nerfs and even better than what we're getting out of Gajan Splats. They even have some demos where you can see it in real time yourself. So let's click on this kitchen Lego here and I'll do desktop with a strong gpu. And you can see I can move around this object, move in closer, move out further, and the detail on the object and everything around the object is really, really good. I mean, just like Nerfs, if we zoom out too far, you get this crazy effect, which in my opinion is still kind of a cool effect. But when you zoom in, you get so much detail. That just seems a lot better than what we were getting out of Nerfs and a little bit better than what we're getting out of Gaussian Splats. And it's really, really smooth. I don't believe we can generate our own yet. I don't see any access to code. We just have the paper, a video that explains it, and some demos that we can test. This is going to be kind of fun to recreate environments from the real world and bring them into a digital world and maybe use them in virtual reality or use them in Unreal Engine or things like that. I can see a lot of fun use cases for this. This week, Instagram rolled out their generative AI powered background editing. This is something that they announced back at their meta event not too long ago. It's just finally rolled out into the app. You can upload an image and remove the background. Snapchat also rolled out an AI extend feature where you can upload an image, tell it to extend the image, and it will fill in the gaps from the original image. And finally, Tesla showed off their new Optimus Gen 2 humanoid robot. And it's pretty impressive looking. You can see how smooth it looks. I mean, the way it moves its head around is borderline creepy. It walks 30% faster than the old version. It's actually got articulated toe sections. It weighs a lot less, got much better balance, is capable of doing squats, has brand new hands. That face movement is just crazy though. Tactile sensing. It's picking up a raw egg and not breaking it. You can see the sensors in the fingers, can tell how much to squeeze it so it doesn't break. Oh, yeah. And it can also dance better than most humans can. And that's what I got for you today. If you love nerding out with me about AI and staying in the loop on the latest AI news and all the coolest AI tools. Check out Futurtools IO. I update it every day with really, really cool AI tools. It's organized in a way where you can find anything you need just by doing a quick search. If you're a YouTuber, you type YouTube and it will show you 115 tools that'll help you with your YouTube journey. I also keep the AI news page up to date on a daily basis and have a free newsletter where I'll send you the most important AI news from the week and the coolest AI tools from the week directly to your email inbox. You can find it all over at FutureTools IE and once again, I'm about 10,000 subscribers away from 500,000 once I hit it. I'm giving away five of these Meta Ray Ban sunglasses that I mentioned earlier in this video to five random subscribers. If you're already subscribed, you're entered to win. If you're not subscribed yet, do it now and maybe I'll hook you up with a pair of sunglasses. Oh, and if you like this video, give it a thumbs up. It'll make sure more videos like this show up in your YouTube feed. Thank you so much for tuning in. Thanks again to Wirestock for sponsoring this video. I really, really appreciate you. Hope you learned something. I'll see you in the next video. Bye bye.










