TU Wien Rendering #23 - Monte Carlo Integration: The Solution
This content was created by LARRUZ. This content was uploaded by LARRUZ. This is a YouTube video titled "TU Wien Rendering #23 - Monte Carlo Integration: The Solution" created on May 15, 2015. It is a lecture discussing Monte Carlo integration techniques, including mathematical explanations and practical applications in rendering, with examples and code implementation insights.
Chapters
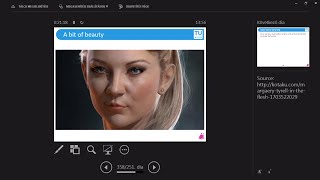
We encountered some problems. So we wanted to integrate this function two times sine squared of x from 0 to PI. And through engineering or through mathematics, we realized that this should be PI. And what we did is that we ran the code that would integrate this through Monte Carlo integration, and we got one instead. So the there is some problem, there is some insufficient knowledge that we have that we have to remedy in some way. So why don't we take a look at another example which will reveal what we did wrong. So let's integrate this unbelievably difficult function from 1 to 0. Obviously, this is x squared over 2. And the brackets show you that we have to substitute this from 1 to 5. What we get in the end is 12. Now let's do Monte Carlo integration. Let's pretend that we cannot integrate this function as we would like to analytically. So I take three completely random samples of this function. What does it mean that I evaluate F at 1. Now, if I evaluate this X at 1, I obviously get 1. I evaluate it at 3 and I also get F3. So I have three samples now, and what I do is I simply average that. So this is 1 plus 3 plus 5 over 3. The end result is 3. But it shouldn't be that, right? Because the end result through analytic integration is exactly four times that. So something is definitely wrong with this multicolored integration scheme. So what we know is that 3 is exactly 1/4 of 2. So we see that there is a difference of a factor of four. And if you take a closer look at the integration domain, then you will see that four is exactly the size of the integration domain we are integrating from one to five. So just empirically, if we don't. This is one angle to look at the problem and to solve it, you will see multiple angles. This is more like the engineering way of solving things. You don't know how to derive the full and correct solution. But you see that there is a factor of four. Four is the size of the integration domain. Well, why don't we multiply with that and see what happens? And obviously it works. So if we multiply with the size of the integration domain, we get the result that we're looking for. So let's change the code. I multiply the previous function with the integration domain, which is from 0 to PI, and this is what I multiply. And obviously I will get PI as a net result, which is the correct solution for the previous integral. Now, this is great, and this looks very simple, and apparently this technique seems to work, but we still don't really know what is happening here. So we should use some black magic, or mathematics if you will, to see what is going on under the hood. So imagine that we sample a function with a uniform distribution on 0pi. What does it mean? I have an interval from 0 to PI and I generate random numbers on it. And every single number has the very same probability. So this function would look like 1, 1 over PI regardless of x in the parameter. Because it doesn't matter which part of the domain I choose, it will have the same probability that we chosen. Now what we are essentially doing is integrating a function F multiplied by this sampling probability. Why? Because imagine that some regions of the function would have zero probability to be sampled. So imagine that I'm integrating from 0 to PI, but I will only take samples from 0 to 2. So there's a region in the function that I'm never going to visit and I don't integrate this part. So that's one intuition. The other intuition is that if I draw samples not with uniform distribution, but with a different distribution, then in the average that I compute, some regions of the function will be overrepresented because I have a higher chance of sampling those. So what we are doing is multiplying this F with the sampling probability P of x. Now this P of X is in this case one over PI, the uniform distribution, which is obviously a constant. So get out of my integral and in the end we have the integral of the function over PI. But this is not what I'm looking for. I just want to integrate the function itself. So I need to make this PI disappear. So I have this one over PI multiplier. What do I need to multiply with to get only this function? What should the question mark be? Excellent. Exactly. So I just killed this one over PI multiplier, which is this p of x sampling distribution. And if you take a look, then yes, this is also the size of the integration domain. So this is a bit more rigorous, a bit more rigorous way to understand what is going on. This is through a derivation, not just empirical stuff. What should I multiply with? We know a bit more about what is happening. I have a sampling distribution that I need to get rid of. So if I have the one over PI multiplier, I got the one incorrectly. And if I lose this scalar multiplier that I'm looking for, then I will get to the correct solution. Let's examine the whole thing a bit more deeply in different angles. I would like to show you how to solve the same problem in Multiple different angles. So super quick probability theory recap. We have an expected value. This is what we're looking for. What is an expected value? The expected value is means that there's a value of something and there's a probability of getting these values. So let's take the expected value of the dice flow. How does it work? I can roll from one to six and they all have the same probability. All rolls have the same probability 1/6. So the values are 1, 2 up to 6 and the probabilities are all the same 1, 6. And if I add this up that this says that the expected value of a dice roll is 3.5. Well, this means that if I would need to guess what the next dice roll would be, then this would be the best value in order to minimize the error from the expected outcome. Now if we would like to compute the expected value of something, then this means that I take the values that this something can take and I multiply it with the probabilities for this event. For instance, it is impossible to roll seven with the dice. So theoretically you could put as the something A7 in there, but it would have zero probability. Therefore it would never show up in the sum. And this is the discrete case. For the continuous case, we don't really need to do anything very serious. We just change the summation to integration. So we are not using the least sum, but we are integrating continuous functions and we're using continuous sampling distributions. Now let's introduce this notation. What I'm looking for is the expected value of this function F of X after an n amount of samples. Because in multicolored integration you need to add more and more samples to get a more faithful representation of the integral. Now what this means is F is the something and P is the sampling distribution. What we can do is that we can create a discrete sum that takes samples of this function and then multiplies with the size of the domain. And obviously, since we are taking the sum, we need to divide by N because the more sample n is the number of samples, the more samples we take from the function the the larger the number we will get. So this is the average part. Now you have to take a look at always keep looking at the relevant quantities. So the expected value of this F does mean that in the integration I multiply it with this sampling probability. And on the right side in the Monte Carlo estimate, I will have the same quantity as on the left side. So if I'm looking for the expected value of X, then I will sample F. Now if you Take a look. Then you can see that this is just an approximation. This is not exactly the interval that we're looking for. But there is a multitude of theorems in computer science that show you that if you could use an infinite amount of samples, then you would approach the actual integral. And most courses on Monte Carlo integration show you different ways of proving this. But this is not what we are too interested in. We would just believe that this is what is happening. It's actually very intuitive why this is happening. You remember seeing this sine wave that we sampled with all these blue and red dots. So you could see that if you have a lot of samples, you can, you will get a good estimation of the area under the curve. Now let's try to use different sampling distributions and in a few minutes you will see why this would be a good idea in some cases. So I would like to integrate this F of X and I am now doing the transformation, that is the identity transformation. I didn't do anything for my F of X, I multiplied by P of X and then I divided by. So this is almost like a scalar multiplier. And then I divide in the same number, I get the very same thing. But if I would like to write that this is the expected value of something, then this will look a bit different because F P is the something and P of X is the sampling probability distribution. So what we have now is the expected value of F over P. And the question is, what is the Monte Carlo estimator for this? And what we concluded in the previous slides that this should be the very same quantity as what I see in the expected value. So I will be sampling F over. So I'm not only sampling F, I'm sampling F over an arbitrarily chosen probability distribution. Now there are some good readings on how to do this well and why this is useful. So if you would like to know more about this, please read some of these documents. They are really well written and that's a rare thing nowadays because I've seen lots of not so well written guides on Monte Carlo integration. I need you to look for a very long time to find something that has the quality that I should give out for other people to study. Now let's solve the actual example that we had previously with this formula. So F over p times P. So I am still integrating only F. And the sampling distribution was this 2 times sine squared X. This was the function that we wanted to integrate. And one over PI is the sampling distribution probability, sorry, uniform distribution over 1 to PI. So I'm getting back the integral of the original function. So I'm looking for the expected value that's f over P. So I'm going to sample in my code F. Let's put this in source code. If you look here, I now divide by this sampling distribution so it's 1 over B minus A. So this means 1 over PI, B and A. This A should have been zero in this case. So I apologize for the differences in the code. I put the 2.5 in there because if you always the A is always zero, then you may write code that works for integration from zero to something, but not one to something. So this is a cool thing to check if you have implemented this. So I apologize. This A should be zero, but if you compute the actual result that you would be looking for, then you will get your PI. So this is the F, the first term in the sum in line 36. And after the division we have the P. Okay, wonderful. So this works. And from multiple angles we now understand how exactly this thing is working. Now, if you write a good Monte Carlo integration routine and you solve the rendering equation with this, what you will see is that as you add more samples, you will see first the really noisy image. And then as you add more and more samples, this noise will slowly clean up. And if you think back in the previous lecture of mine, we have talked about over and underestimations of the intercom and this is exactly what shows up also in images. If we are troubles. Before I converge, I will get values that are larger than the actual intensities and I will get values that are smaller. So this is what shows up visually as noise. So what you are looking for is always this samples per pixel metric. And when you have a noisy image, you would need to know how many samples I have used per pixel. And if it's still noisy, then you would need to add more samples. This is also some visualization on the evolution of an image after Hundreds and then 100,000 samples depending on the algorithm. There's multiple ways of solving rendering equation. You could have smarter algorithms that take longer to compute one sample because. Because they are doing some smart magic that this would mean that you would need less samples per pixel to get the converged image. And the first algorithm that we will study is actually a naive algorithm. It's called path tracing. And it usually needs a tremendous amount of samples to compute an image. But since it is a simple algorithm, you can use your GPU or CPU to dish out a lot of samples per pixels in Every second. Now a bit of a beauty break. This is what we can get if we implement such a path tracer. This was rendered with Lux render and some recent example. Does anyone know who this is? Just raise your hand. Okay. Half of the people. Okay, excellent. So. So this is actually Margaery Tyrell from the Game of Thrones. And if anyone tells me any spoilers, I will go on rampage. Okay, so please. And this is actuality. Because the Game of Thrones is running, obviously we all love the show and there's also scheme being rendered, so there's tons of subsurface gallery. And you can solve this with a single path tracer that we will put together the theoretical part in the second half of this lecture and then we will implement in the next lecture. So when I see renders like this, what I feel is only comparable to religious spiritual wonder. It is absolutely amazing that we can compute something like this using only mathematics and these very simple tools that I have shown. And the other really cool thing is that we are writing these algorithms, we are creating products that use these algorithms and these are given to world class artists who are just as good of an artist as we are engineers. And they are also giving it their best to create more and more faithful models and we can work together to create stuff like that. So this is absolutely amazing.










