Deep Learning Deep Dive Episode #2: DALL-E and friends in image generation
Andrej Karpathy and Justin Johnson break down DALL-E's technical architecture, from quantization methods like Gumbel-Softmax and VQ-VAE to VQ-GAN's use of perceptual and adversarial losses for sharper images. They discuss multimodal conditioning, transformer innovations for scaling, and why OpenAI's training dataset remains opaque.
Chapters
Okay, so Justin, should we start at DALL·E or—
Yeah, yeah, so let's start at DALL·E.
Yeah, so this paper came out very early in the year, January 5th. So can you recall sort of when you— on a high level, how would you summarize DALL·E, I guess? And what did you think of it on a high level before we go in?
Yeah, so DALL·E is at a high level is building this big system that takes as input a sentence and then can generate a piece of text from prompt that depicts the content of that sentence using, you know, big neural networks and actually using the same 400 million image-text dataset that was used for the CLIP project that we talked about last week. So my initial impression is that this is obviously a really exciting problem domain. We care a lot about being able to generate content with neural networks and being able to specify and control that content through natural language is super appealing because Natural language is this amazing natural label space that humans talk to each other with all the time. And of course, it makes sense to try to generate images or manipulate images using language. So I love the problem statement. And of course, my initial impression are that the results are amazing, that this is clearly the best, the best text-to-image project that anyone has ever done.
Yep, I think that's right. Actually, you know what's interesting for me when I saw this for the first time is I worked on image captioning when I was doing my PhD, and Fei-Fei pitched me this idea that, you know, image captioning is images to text. Why don't you go backwards? Just take the text description and generate the image. And I was like, haha, Fei-Fei, that's like a really funny idea, but that's not going to happen. Although at the time, all I had available to me was the Microsoft COCO dataset. And so that was probably not set up for success. But here OpenAI, of course, has this like massive dataset of 400 million image-text pairs, and they sort of That's what partly makes it work, I think.
Yeah, I mean, actually, I kind of like that idea as well, right? Actually, my first paper during my PhD was using, like, sort of text image retrieval. And then the last paper during my PhD was finally getting to this problem of text image generation. I wasn't actually using full natural language text, though, as they are in this paper. Instead, I was using this intermediate representation called a scene graph. But I always wanted to get it to work with text. And I'm kind of excited that that's where people seem to get to be now.
Yeah. So let's maybe step through like how they did it. Of course, like there's no paper available that OpenAI has released yet. So all we have is a blog post, but I think we actually have like a pretty good guess of what's under the hood, except for a few details just based on the description.
Yeah. And basically all of this comes from about like 2 or 3 paragraphs in the blog post where they have just a tiny bit of details of how they actually do it. But it feels like if you've been following along with the literature, we can kind of guess as to how this is working.
Yeah. I mean, basically, like, it seems to me like OpenAI has basically one single code base that trains a transformer. And, you know, it's just a sequence of integers, right, that's being modeled. And now you can change the semantics of what those integers mean. Like in this case, some of the integers are going to represent text. Some of them are going to represent image patches. You know, in some other cases, it's just text or say just image patches. And so you can sort of reconfigure what your integers mean. But at the end of the day, it's just sequences of integers that are being trained on. So from that perspective, I think this is just a plug-and-play GPT, except for the semantics, of course, of, you know, what those integers mean in this case.
And that's exactly where things get tricky, right? Because we know how to take text and encode that as integers using something like byte-pair encoding or sentence piece encodings. But now the tricky part is how do we represent images or in this case chunks of images as integers in a way that they could be modeled with an autoregressive model? So like one kind of lame way is you can treat the pixels of the image as independent, like the individual pixels of the image as independent units to be modeled by your autoregressive model. But that's not going to scale, right? Because if you want to generate high-resolution images of like 256 by 256, that's just way too much context to try to model with a giant brute force autoregressive transformer model. So instead, they need to do something clever and find some way to generate, to model chunks of images as integers. Using some kind of smart encoding.
Yep. And actually, like, another fun point is last time when we were talking about CLIP, you were talking about the envy that the vision people feel to NLP people and that it didn't used to be that way, right? So vision people— sorry, NLP people used to look at vision and with jealousy, I suppose. And now we're looking backwards. And so we're actually borrowing NLP tech to generate these images, right? Like we're using transformers, which were originally developed in vision. And we're thinking about— sorry, in NLP. And we're thinking about, okay, how can we rephrase images into sequences of integers so we can borrow all of the tech? Like, it's basically that.
Yeah, exactly, right? So there's been obviously a lot of— so what's almost striking about the one thing that kind of struck me about this project from the beginning is that it's a little bit a divergence from how we've seen image generation in other contexts. So I think most of the noise around generating images and especially generating really high-resolution, high-quality images Most of the ways that people have done that the past couple of years have been with GANs. Because GANs are kind of parallel decoders, they generate all the pixels of the output image in parallel. So we can use like a convolutional network to kind of process everything in parallel and actually work on fairly high-resolution images. And that's actually where most— it seems like most of the research community's attention on generating images has been in the last couple of years. But so then one of the first things that struck me from this, this DALL-E project is that it's kind of not— is that it's not using GANs. Instead, it's using these autoregressive models, which are— have a lot of great properties, but they're not GANs.
Yep. Yeah, for sure. So like it used to be that if you want really nice high-resolution images, you basically have to reach for a GAN. And that's changing now with some of the latest crop models like VQ-VAE-2s and friends. And of course, this is using all of that same technology or very related. Yeah. All right. So let's maybe just go through the blog post and just kind of like look at, you know, what they've said here and any comments and thoughts that come up maybe.
Yeah, definitely.
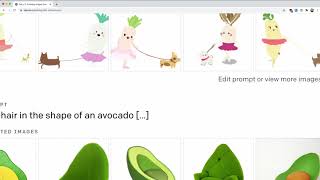
Yeah. So the first thing is DALL·E is a 12 billion parameter model GPT-3. So I guess 12 billion, just to put it in context, GPT-2 was about 1.5 billion. GPT-3 was 175 billion. So this is somewhere in between GPT-2 and GPT-3. Somewhat small model, I guess, compared to GPT-3. And then they sort of like hit you with just the results right away. So, you know, an illustration of a baby daikon radish in a tutu walking a dog. And, you know, this just goes on and on, I think, of course, like throughout the blog post. I think it would be kind of interesting to talk about, you know, some of these results I'm really impressed with and some of them I'm not like basically impressed with at all. And they're all just kind of like mishmashed together. And I don't know that they've done like a great job like discussing just how big of a deal any of these rows are.
Yeah, definitely. I think they were— I think they were in some cases very strategic with the choices of examples that they put. One thing that actually struck me— I mean, so first off, the examples that they choose right at the beginning are quite striking. So one big problem that we always have in generative models is this notion of like compositional generalization, that when we talk about sentences, there's many parts that all kind of fit together orthogonally. So in this first example of an illustration of a baby daikon in a radish— of a baby daikon radish in a tutu walking a dog, the reason why this type of result feels really impressive is because we feel like probably there are not a lot of images of this exact sentence on the internet. So the only way that the model could be successful is that it's seen a lot of illustrations, it's seen a lot of daikon radishes, it's seen a lot of tutus, it's seen a lot of dogs. And in order to generate this result, it needs to composite all of those notions together, which had been learned separately, and then put them together into make this image. So to me, this— but what's kind of— so that's really impressive is whenever I see this sort of compositional generalization in generative models.
Yeah, for sure. Like basically you can think about, okay, there's a few things like there's a location, there's some kind of a texture, there's some kind of a size, there's a few attributes that can vary for different objects that may or may not be sort of in the scene. And then you cannot witness the full possible cross-product of all the ways that these can interact in an image. You only have a few sparse examples of that. And what you're really hoping for is that your model sort of fills in the blanks correctly at test time. And that's what this model appears to be doing quite effectively.
Yeah, exactly. Now, one example, but I think some of these examples are maybe perhaps less impressive than the others. I think the avocado chair is actually maybe a less impressive example to me. Because for avocado chair, there's sort of like two components which are being put together, avocado and chair. And that seems kind of unusual. Like, I don't think I've ever personally seen a chair in the shape of an avocado in my life before. But in this dataset of 400 million images of who knows where they are coming from on the web, I would not be surprised if there are some examples of avocado chair in the internet somewhere.
Yeah, it's like, it's like you have to kind of basically consider the, the distance to a nearest neighbor in the training set. And that's almost like how proportional your surprise should be conditioned on it working well. And so yeah, in this case, I kind of agree with you. So let's go to the one that actually I thought was the best. And when I was tweeting about this for the first time, that's the one I included, which is the storefront that has the word OpenAI written on it. And that actually was quite impressive to me. And the reason it's impressive, of course, is, I mean, we're compositing arbitrary text on arbitrary images. And of course, the words OpenAI exactly have not been on any storefronts. And so to me, this is just this learned compositing. And the other thing is, you know, to what extent can you just put in arbitrary text and render it on these surfaces? Because you have to remember that with the byte pair encodings that they're using at the input, you've got lots— like all these different— like, does the model basically learn a rendering for all the different possible byte pair encoding like snippets of text and how to render them and stitch them up and make a consistent sort of visual appearance for them. So to me, this is like, again, this notion of compositionality really showing here that this works at all for arbitrary byte pair encoding tokens.
Yeah, I agree. I was also completely blown away by these text examples. I thought that was absolutely shocking that that can work. But I think there was another facet of this test— text example that I found really interesting. Which is that this, this example of the storefront is the first one that's really attempting photorealism. The previous two are a little bit abstract. And now in this more photorealistic examples, you can actually see that some of the textures, some of the low-level textures and edges are actually a little bit over-smoothed and a little bit swimmy in this third example. And I think if you look carefully through a lot of the examples, you'll actually see, I think, this a little bit dreamy, over-smooth quality in a lot of the images. So I think that causes them to shy away a little bit from showing really photorealistic results. But when you're looking at more abstract results of like avocado chairs or illustrations of radishes or X-ray images or mesh renderings or cross-sections or whatever, anything that's a little bit more artistic, actually this oversmooth nature of the images being generated I think actually helps to sell the result a little bit more. So that's a little bit aside— an aside based on— but I thought that was interesting that they're kind of using this facet of the model's generated images to their advantage a little bit.
Yeah, for sure. For the abstract paintings, this helps. But for anything like real-worldy, it doesn't help. And it actually exposes basically what is kind of a flaw almost in modeling. And that is the use of the VQ-VAE, which sort of uses this simple reconstruction loss. And indeed, that actually really queues up the next sort of work in this line of work that we're seeing here, which is the VQ-GANs, um, that actually, um, you know, could be expected to work much better in this case.
Yeah, exactly. Um, so then after they kind of hit you with these 3 examples at the beginning, then they give you a little bit of a— a little bit of a taste for how the model actually works. Um, so they tell us that it's a— it's a transformer language model. It receives both the text and the image, uh, as a bunch of tokens. Um, but the way that this kind of works is the text comes in as a set of tokens using standard text-byte pair encodings. But now the image comes in in an interesting way. So then the image is a— they're modeling 256 by 256 images, which is kind of medium to high resolution for generative models these days. But this 256 by 256 image gets compressed down to a much lower resolution, 32 by 32 grid of discrete latent codes. And this is coming out of this V— this discrete VAE, which we'll get into more. But I think this is really the magic that makes this all work, is actually the discrete latent codes for the images.
Yeah, basically we're going to take 256 by 256 images and we're going to truncate them into patches. These patches are, I guess, 8, 8 by 8. Yeah. And basically we are translating an image that is 256 by 256 by 3, 3 for RGB, of numbers from 0 to 255. We are translating that into an integer description. So we have a 32 by 32 grid of integers instead, and they're taken from a vocabulary of small patch, sort of discrete patch elements. And the codebook they use for images is of size— I'm trying to remember or try to find it— 8,192 kind of possible discrete patches.
Yeah. Yeah. So this is amazing, right? Because now we've got our image, we can turn it into integers, and then we can— we know how to model sequences of integers with a big transformer-based language model. So that kind of gives you— and then once you— because we get this big compression factor on image, then even once we put the text and all these image patches together, we've only got 1280 tokens, which is within the realm of possibility for big, uh, for big transformer models right now. But the trick here is that now, you know, we've got to jointly learn both these image encodings and the other parts of the model that are working on top of it. And this is a big technical challenge because usually neural networks are pretty good at learning latent representations for things. But usually there's, they're continuous representations that are differentiable and we can learn via gradient descent. But now learning these discrete representations, these discrete codebook entries, is not something that's so trivial to learn via gradient descent. So whenever you, so it's actually very rare to see like discrete integers in the middle of a machine learning model. It's pretty common to see them either at the input or the output, but not in the middle.
Yeah. So this is where they sort of go into a bit of a technical detail on the side of this post here and they sort of talk about, okay, similar to VQ-VAEs, we basically train this vocabulary of patches using this flavor of discrete VAE that was pre-trained using continuous relaxation. So this, and then they cite the Gumbel Softmax paper and the Concrete Distribution paper. So they did not release details here, but, but they basically use one of two flavors of like ways of training this, uh, this autoencoder with basically the bottleneck layer being a discrete variable.
Um, yeah, exactly. So then the V— so then, so then basically this is where the technical innovation comes in a little bit because, uh, then you go and read this VQ-VAE paper and that gives you one approach for model— for learning, uh, discrete latent variables in the middle of a VQ-VAE— in the middle of a VAE-like model. But then you read the Gumbel Softmax paper and this gives you a different way of dealing with discreteness in the middle of a neural network. So then here's where we need to be a little bit creative and try to fill in the gaps and figure out what— how exactly can the Gumbel Softmax be used to improve this existing VQ-VAE.
Yeah, so maybe like, maybe how should we do this? We should probably maybe finish up with DALL·E, the blog post, and then we'll recurse into some VQ-VAEs. What do you think?
Exactly, exactly. So then we've got these two, so we've got these two interesting pieces, VQ-VAE and Gumbel Softmax, and we'll put those on the stack.
Yeah. So for now, we just assume we can basically translate every image into a 32x32 grid of integers, and then we can plug this into this transformer. The other thing to actually point out here is these are all trained separately. This is not a nice end-to-end model as you would typically like. There's a pre-training stage where you train your VQ-VAE, and now you have a translator from images to, you know, these integer patches. And then, then as a second step, you optimize the transformer basically for sequence modeling. And then as a third step, actually, they use CLIP for re-ranking. We'll get to that later. But basically there's three completely separate pre-trained components here working in tandem without it being trained end-to-end, which is kind of, you know, interesting and not super common, I suppose.
Yeah, pretty common for models of this flavor, but it'd be interesting to think about ways to try to join these— train these things jointly in the future.
Okay. So what else do we have in this? In this blog post here.
Then after that, they're basically showing us examples of things, of things that it can do.
Yeah, actually one thing with the examples that I found fascinating, and this is similar to CLIP, is you see that they're trying to like really hack the prompts. Like they're really doing quite a bit of prompt engineering because the wordings are awkward in some cases.
Yeah, definitely. Another thing that I, so right, for example, they repeat the phrases a lot. So in the top example, a pentagonal green clock, a green clock in the shape of a pentagon. So the input text is actually like the same information, but repeated in two different ways.
Yeah, what's up with that?
Yes, there's definitely some heavy prompt engineering going on. Another thing I found interesting in the prompts, like first off, I love the interactive UI here where you can go in and like change the nouns, change some of the adjectives to play around with this compositional generalization. But one thing I found kind of funny is that sometimes when you change one of the nouns, in these like slots you're allowed to change, some of the other parts of the prompt text also change, which feels kind of over-engineered, like quite heavily engineered on the prompt side to me.
Interesting. Yeah, but okay, so they just have a lot of examples, examples, examples, and they're pretty impressive examples, by the way. And my favorites are anything that renders text, because again, to me, this is showing, you know, that these bipartite encodings, that there's like this general rendering function that preserves style. And I think that should be pretty hard to learn and you will not see like those specific examples in the training set or it's at least very unlikely. And some of them are not like as amazing. Like there was a, what was the one with the glass or something? It was a bunch of glasses on the table or something like that. And I was like, okay, this is like every, there's probably like 1% of your training set is just that.
Yeah. I thought it was interesting that they do try to highlight a little bit of failure modes. So like in the example with like showing clocks with different numbers of polygonal faces, then you can ask it to generate a clock in the shape of an octagon. But then if you go and look at, they don't always have 8 sides. Sometimes it gives you 7 sides or 6 sides instead of 8. And this kind of failure mode, you know, whenever you're looking at papers, we often talk about cherry picking. And cherry picking is where you're showing kind of intentionally good results to make it look like your model is doing good. But this idea of like showing failure modes, but they don't fail too badly is sometimes called lemon picking. You're like showing things that fail, but it fails in like a reasonable way. But like I can definitely imagine there probably are prompts where this thing catastrophically fails and gives you like complete garbage pixels. And they don't really mention anything about whether or not it does that or under what circumstances.
Yeah. One other interesting point, just kind of like scrolling maybe to the end of the blog post almost, is they actually always generate 512 samples and then they re-rank them with CLIP. And then only show the top 32. So actually the 512 minus 32 are probably pretty poor samples, and they discard them after generation. And so it's kind of like pretty fascinating and interesting that you really need this rejection sampling step at the end, that you can't trust your likelihood model to just like give you good samples just like directly. You need like a separate re-ranker, just like in VQ-VAE. They use the probability, I believe, of like different classes under an ImageNet model. To clean up their predictions, which is kind of weird. Isn't it weird?
I mean, it's kind of weird, but it also— like, I've read some explanations of this in a couple places. One problem is that when you're doing a likelihood-based generative model like they are in this setting, then the generative model is trying to cover the entire space of all possible outputs that could exist. And that's a really hard— that's a really hard problem to solve. And but we as humans don't need to see the full distribution of all possible outputs that could exist. We just want to see like 10 good samples. So then a discriminative model is sort of saying like, okay, yeah, you were trying— you gave me all these things that we're trying to cover the full space, but I just want to find the ones that are maybe most representative or best samples, not necessarily covering the whole space.
Yeah, the other, the other potential reason for using this is that these autoregressive models, when they're generating, of course, they generate a small patch and then they plug it in and then they generate another patch and so on. And in the process, if you happen to sample a low-likelihood patch, you can actually throw off the rest of the generation process and you will get a garbled mess. So these things are not like super stable to— in face of this. And so maybe that's also like one reason why you might want to re-rank at the end. I guess what is the comparison? Like say like if a human is like generating an image, typically you have an eraser. So, you know, if you're feeling artistic and you make a mistake, you can go in and you can just erase it because it doesn't— your discriminative model is like, that looks wrong, and you can fix it. But an autoregressive model can't fix. And so it's creative and it's trying its best. But if it puts in a bad patch, then there's no way of fixing it. So it looks at it at the end and then it decides, okay, that was— that did not work.
Yeah, I think it's also— it's also kind of emblematic of the fact that these models really generate in a way that's very different from we do. Because I think that, you know, when I'm a person and I'm writing a paper or trying to generate a figure or whatever, I start with some vague picture in my head of what I want it to look like. And then I kind of fill in the details and shuffle things around. And I'm kind of working at some higher-level semantic space. At least I feel like I am when I'm designing pieces of content. But these autoregressive models don't really get to do that. They're just sort of generating one patch at a time, conditioned on the previous patches. And there's not necessarily like a global idea that they're shooting for from the beginning.
Yeah, it's a very strange mode of operation, actually, the fact that you can't go back and fix things and so on. And you can't iterate on your result. And it's not obvious how you would structure that. Like, for example, well, I mean, I can come up with a few bad ideas. Like, you could do several passes and you can sort of sample in some noise and you can give your model an opportunity to sort of generate the output multiple times and with some augmentation for noise or whatnot. I don't know. There's like some gross ways of doing it, maybe.
Yeah, I mean, kind of some models that do coarse-to-fine modeling, we'll see that in VQ-VAE2 that kind of start from a low-resolution thing then gradually increase the resolution. And that kind of gets this flavor of correcting your mistakes or starting in the abstract and making things better. But it feels not quite the same as what we're doing as people because we're not like starting with a blurry, low-resolution picture of what we want to create in our mind. It's more like we start with some— we're operating in some semantic space, it feels like. And then we— you kind of think like, "Oh, I'm going to write a paper about this topic." And then I expand that out to a couple more subtopics. And then each of those subtopics, I expand out into more topics. And then eventually I— then only do you generate words after months of thinking about these things in a semantic space.
It's almost an interesting problem. I mean, yeah, how you could actually mimic a human artist, I suppose, and how they go about generating images and what that would look like. Obviously, it would not look patch to patch from top left to bottom right. That's kind of crazy. But it's not obvious how you set that up as an optimization problem. And okay, now maybe you need to reach for reinforcement learning to actually optimize this or something crazy like that.
Yeah, definitely. But I guess even setting those issues aside, I'm kind of struck that this is one— another kind of problem with these autoregressive models is they're very slow at inference time, right? Because you need to sequentially sample one patch and then conditioned on the output of one patch, you need to go back and sample the next patch. So these autoregressive models have a little bit of a weird flavor where they're fairly fast in training because in training you can do all these things simultaneously. But then at inference time, they're actually much, much slower than they are in training because you need to generate the patches one at a time. So that a little bit inverts what we usually want for neural networks, is that we don't really care so much if they're slow at training, and we care more that they're going to be fast at inference. So another thing that kind of strikes me with this paper, with this project as a whole, is that yeah, I think the VQ-VAE is, or like this discrete latent codes, is an amazing way to get transformers to work on modeling images of high resolution. But it's probably not very practical for generating images in real time. And I wonder if that's something that we can improve further.
Oh, yeah, for sure. And that's unfortunate because, as you mentioned, basically you would want this to run fast in inference time. There are a few papers that sort of improve the quality, sort of the inference speed of these models. The one that comes to mind is the parallel WaveNet paper where you have the exact same issue. You train basically using an autoregressive model because the training is really fast with these models. But at inference time, they don't want to, of course, do that because they're sampling audio and it would take way too long. So they actually distill that probability distribution into an inverse autoregressive flow model, which has the opposite, basically, pros and cons. So it's really fast at inference time, but it's much slower at training time to evaluate the likelihood. So it's kind of interesting that you can do that as well. Yeah, I haven't seen too much of it.
Yeah, but that said, like, you know, it makes me feel like we've simultaneously come a long way, but there's also so much farther to go because it's amazing that we're getting these image results from language. The results are really cool, but like eventually we want to be able to have computers that like generate entire videos or entire video games or entire movies or books for us. And it feels like we need like probably several orders of magnitude, like if we're going to scale things up in this way. We're going to need many orders of magnitude before we can generate a whole high-resolution video from text. Or maybe different— so it's unclear whether that'll happen with brute force scaling of these existing approaches or whether there's going to be some huge algorithmic change that will make things much more efficient.
Yeah, you're right. You're sort of getting at the image generation aspect of this and the use of autoregressive models is not, you know, you really don't want to do that if you want to have a— if you want to generate entire movies potentially in this naive framework. But this is where it is headed. I mean, image generation more generally. And by the way, like DALL·E is basically image generation paper or result. It's just conditioned on text in this like quite simple way, I suppose. But really like the interesting sort of thread of work over the last few years, I want to say, is these improvements in image generation. And that has made major strides. Like we're looking at these images and okay, they're a little bit, you know, they've got this like little quality you know, they're very smooth and so on. And we know where that's coming from. But we also are starting to get an understanding of like how we're going to fix that. And so I'm actually pretty bullish on generating entire videos conditioned on arbitrary information and having that work pretty well. And that's, I think, pretty exciting.
Yeah, definitely. And I think that's where a lot of people are hoping this will go. But I think another thing that's interesting is a lot of papers that you see that work on image generation often do like class conditional generation or even unconditional image generation. And to me, that's kind of a useless problem in a way. Like, it feels very rare that you'd ever want a neural network to just generate images from you— for you from scratch from some prior distribution. What's much more interesting is conditional generation where you can give the model very detailed information about what it ought to generate. So for that reason, I really like this, this image and this, this text-guided generation that feels much more practical, right? Like, and then there's also some nice examples later on that I, that I really liked. That are doing kind of joint image plus text conditioning, right? Where they give you— where you give it the prompt, like the exact same cat on the top as a sketch on the bottom, and then give it like the pixels of the top half and then have it generate image for the rest half.
Yeah, absolutely. Like what comes to mind for me is this like Photoshop++. I mean, in Photoshop++, you don't, you know, you don't use the brush tool. You're like speaking to the computer. You want the sky a bit like redder and you want this person to be larger and whatnot, right? Like you're just talking to the computer and that should just totally work in a few years probably.
But then like at a high level, that's kind of how I would have to interact with Photoshop anyway because I don't know how to use Photoshop. So if I would have to like hire or work with a graphic designer who does know how to use Photoshop, then I would interact with that person through natural language and maybe sketches and images. And that feels like kind of where we're hoping to get in like Photoshop a few generations from now.
Yeah, I'm kind of hoping that Photoshop of the future has a natural language interface. You should just be able to describe in words what you want. I want to see— I want to take this image. I want, you know, to modify the scene in various ways. And I think we probably can build technology that does that. Having seen some of these results and how quickly they're progressing, there's nothing like fundamentally like limiting it, I think.
Well, except for the massive compute, right? Like, I mean, I'm kind of bullish in the long run, but I'm not quite sure how this is going to play out in the short run. Because something like, you know, DALL·E is an amazing result. It's by far the best image, like most general image generation I've seen out there. But this is still quite a lot of compute, both to train it and even at inference time. So I'm also bullish on this sort of long term, but I have a hard time kind of estimating when we'll get these kind of applications for real.
I mean, I just feel like, okay, we're going to get more compute that we're always getting more compute. So I don't know that this is going to be like a fundamental issue. And, you know, we were generating MNIST images just like 3 years ago, and now we're generating these large images. And then the VQGAN paper that we probably won't get time to get to this time around, but those are megapixel images generated and they look pretty good. So in the future, I want to have a movie on demand where I want to remix 3 existing movies and then I want to condition it further and I want to like make up my own scenes, condition natural language. And I want all of that to just work.
Yeah, me too. That'll be awesome. Okay, cool. But before we, before we get too ahead of ourselves, do we want to get back a little bit technical and move on to one of these fractal recursions?
All right. And yeah, we should, we should start to recurse. I think like one more interesting thing. I'm just trying to like read between the lines of what happened here at OpenAI. Like my impression is basically like they wanted to work on images and text. They somehow collected this massive dataset of 400 million image-text text pairs, which I thought was impossible. Turns out apparently possible. And it's a fairly high-quality dataset. And then they worked on CLIP, which really showed that when you train this contrastive losses of image-text embeddings, you can actually get extremely good representations and all kinds of zero-shot results, which is really impressive. And then, you know, you can, of course, with the same dataset, you don't have to set it up as image and text as a pair. Go to a score, you can set it up as image goes to text or text goes to image. And image going to text is image captioning, and we've seen those results, but we have not seen text goes to image executed well. And so this was kind of, um, what DALL·E sort of came to, uh, just kind of like reading between the lines. And again, to generate, um, images in this autoregressive format, that, um, you do need to break up images and represent them as a sequence of integers. And that's the core technical piece I think that is interesting here. And of course DALL·E is using the Gumball Softmax paper, but making it work also is a huge hyperparameter exercise potentially. Like I was trying to re-implement the Gumball Softmax and I was medium successful. I didn't try super hard, but it's not just trivial. So they found a way to scale it up and get it to work, which is nice.
Yeah, I think another technical point of DALL·E that we did not touch on is that this is actually not a fully vanilla transformer that they're using for the autoregressive modeling at the end, because they're actually using pretty interesting sparsity patterns in the transformer at the end that makes this thing work better.
Okay, great. Yeah, thank you for actually mentioning that. I forgot. Yeah, they do mention briefly, and again, we have to read between the lines because they don't give us the details, but I'm pretty sure this is an axial attention paper-based a model where you alternate different layers and you don't attend to the full image. You only attend to long rows and then columns and then patches and you sort of alternate that. So over time you cover the entire sort of space that you want to attend to, but you sort of do it one at a time so your matrices don't get too large and everything doesn't get too slow.
Yeah, exactly. And this is actually an area where I expect transformers to be used more, right? So one thing that people often say about why it's nice to use transformers in vision is that they don't bake in any inductive biases around the spatial structure of images, and it learns it all from scratch. And that's great, but it doesn't really scale. So in this case, we actually are putting back in some inductive bias that we know about the 2-dimensional grid structure of images, but not putting it in as convolution in the model, but instead putting it in, in like the receptive fields that these different attention units are allowed to attend over. And this, I think, is a slightly underrepresented feature of Transformers. Not just are they like really general architectures for operating on sets of elements, but they also can deal with basically arbitrary sparsity patterns among those sets of elements that we can define dynamically at runtime. And I think that's a really, maybe slightly underappreciated aspect of transformers.
Yeah, I often see people like basically saying that, oh, transformers have this big issue that they're O(n²) in their attention mask. And it's like not really an issue because it's like so trivial to mask it in whatever way you want. But okay.
All right. All right. So then which one should we recurse into? ImageGPT or VQ-VAE? Yeah.
So I thought it was kind of interesting to talk about ImageGPT briefly before we go into VQ-VAE, because ImageGPT was, it was a GPT model again on images. So it was GPT generating images instead of generating text, but it was done pixel per pixel. So the way we translate an image into a sequence of integers is not patch by patch. It's pixel by pixel. And in particular, they take every single RGB triplet and they discretize it using k-means into 512 possible words. And so it was kind of interesting to me that, you know, that discretization was per pixel, but it was just a GPT model. And so to me, this is kind of like an extension where, okay, we're not on the level of individual pixels, we're going to go up a level to patches and then put the GPT autoregressive model on the patches. And have a different model for decoding the actual patches to get slightly higher resolution.
Yeah, exactly. But it's also slightly— but then they're using a slightly smarter method than— but then VQ-VAE uses a much smarter method than k-means to generate these patches.
Right?
So one thing that you could imagine doing is instead of clustering the RGB values as they do in ImageGPT, you could imagine extracting all 8x8 patches of images from your training dataset and then clustering those with k-means to now get sort of quantized 8x8 patches. And then you could imagine kind of building a GPT-like model that autoregressively works on top of these 8x8 patches that you learn from k-means with patches on the dataset. But that's not going to— but that's not really— that doesn't give you contextual modeling. Maybe we'll get there more with VQ-VAE. But I guess the point is that if you want to work on patches, applying the same k-means idea that they use in ImageGPT is not trivial to extend to patches.
Yeah, I think like your idea actually is a pretty strong baseline that maybe they could have used in the VQ-VA work because basically we're just using vector quantization on the input layer instead of having a sort of encoder-decoder and using a vector quantization layer on the middle of the bottleneck. Like that would have been kind of an interesting baseline where you really just make the encoder and the decoder be like a linear layer or like actually like just a pass-through, like a no-op. And then you recover k-means Basically.
Yeah, exactly. I expect that wouldn't work too well. Like you'd get probably pretty bad artifacts at the boundaries of these patches. But it would have been an interesting baseline to see. But that said, like apart from that, like in the ImageGPT paper, it was a bit of a, like the point of the paper was a little bit different. They, it seems like they were not focusing so much on the quality of the results they can generate. They're trying to instead use generative modeling as a pre-training task. To learn really powerful visual features. So even though the model ends up looking kind of similar, the kind of task and the goal is a little bit different.
Yeah, I think— yeah, that's a good point. That's for sure. Yeah, they basically like have all these linear probes and they're trying to just see whether the representation that they're learning, because it's an unsupervised sort of like— or self-supervised objective, I suppose, to model these images. You don't need the labels. And does that give you pretty nice features to hang off supervised tasks off of?
And then also, as I was rereading ImageGPT after reading CLIP and DALL·E, I noticed one line about the data they train on is that they train on 1 million unlabeled images from the web. And I wonder if that was some precursor to the dataset that they eventually collected for DALL·E and CLIP.
Okay. Interesting. Okay. So to me, okay. Yeah. So to me, ImageGPT basically was like a good pointer because what we're going to just because, you know, we're using GPT to model images. And now with this paper, we're not going pixel by pixel, we're going patch by patch. So let's now maybe talk about how we actually translate patches of 8 by 8, like little patches of 8 by 8 by 3 into integers of a discrete codebook. We have 8,192 elements and each possible 8 by 8 by 3 patch will have a discrete like one-hot, encoding into one of these tokens. So how do we do that?
Well, that's easy. We do an autoencoder, right? We know that we— right, we have an autoencoder. The input is going to be the image. There's going to be some hidden layer in the middle that's a bit— a big grid of integers. And then from that grid of integers, we'll reconstruct in the decoder and train it with an L2 loss. Why is this not going to work?
Yeah, it sounds like a pretty good plan. So basically we're going to do k-means except we're going to do it in the middle, in the bottom leg of an autoencoder. Which is kind of interesting. So that's the VQ-VAE at least approach. So maybe we can start there. Okay, let me pull up the paper.
But like really, I mean, this is basically doing the pipeline that we just talked about, right? Like it's basically an autoencoder, like a convolutional autoencoder that bottlenecks in the middle through some discrete integer codes.
Yep. Okay, so I have the paper open and this is a paper from 2017 or so. Yeah, 20— oh, 2018, something like that.
Yeah, end of 2017 on ArXiv and I think it was published in 2018.
Yeah, so this is like a really nice paper obviously and it has this like— VAE implementation— sorry, like interpretation— that I don't think was like sold super well in the paper. But that's okay. And yeah, basically the setup is we take an image, we do a convolutional encoder, then we— I mean, I guess Figure 1 is really good. You take your— and then you basically have some kind of an encoding vector z_e that came out of the ConvNet. You try to pair it up with the nearest basically quantized encoding, uh, codebook element, and then you snap it basically to the quantized version, and then you decode only using the quantized versions. And then when you do backward pass, you use a straight-through estimator, which is a fancy way of saying that you— once your quantized vectors have a gradient, you are just going to distribute that gradient equally to all the things that sort of like snapped to you and then continue backpropagation. And the whole thing is sort of arranged in loss function number 3 and this loss— formula number 3. And this loss function basically has a reconstruction cost. So we want to, you know, take in an image, go through the bottleneck, and then reconstruct the same image, or in this case, the patch. And then in the middle, we have basically this K-means objective.
Yeah, exactly. And this K-means objective is a little bit funny the way they framed it in the paper, because basically they have this loss where the code— like, you have these— because there's basically two things that are happening. The encoder is predicting these codes for every part of every patch in the image, and then you've got a codebook, which is where you snap the predicted codes onto the entries of the codebook. So now we need to get gradients for two things. One, we need to get gradients onto the entries of the codebook, and then second, we need to get gradients onto the predictions from the encoder. And the way that they do this is conceptually a little bit simple. So they kind of like say that for each codebook entry, we find the patch— we find the predictions that were matched to that codebook entry, and we're going to kind of pull them together. So the codebook entry should get closer to the predictions that match to it, And then similarly, the predictions should get closer to the codebook entry that it was nearest to.
Yeah, and we were talking very briefly actually before this about why this objective is separated out into two terms. Like in k-means, you're just trying to move the clusters towards data points and sort of in this case, because the data points are a function of the image, the data points closer to the clusters. Like why don't you just have a single MSE loss here, like a single a single term, they split up into two and they use a stop gradient for, for one of the terms twice. Like, what's up with that? They never justify it, nor do any of the other papers that follow. They always just copy paste it. And it confuses me a lot because it's not obvious to me why this is not a single term.
Yeah, exactly. So like, because basically we've got this pretty standard looking L2 objective term. We've got like an x and a y, and then you're looking at a norm of x minus y, like a squared norm of x minus y. But instead of putting this as one sort of normal L2 loss term, instead they split it up into two terms. One will stop gradient on one, one will stop gradient on the other. And like, one of the only reasons I can think that you might want to do that is because it lets you put different paths, different amounts of gradient back into the two inputs, which is kind of this beta scalar that they have here. So that was one interpretation, but then I'm also kind of confused because they later say that the beta actually is not too sensitive to the value of beta. And in fact, even like setting beta equal to like 1 would work. And if you set beta equals to 1, it looks like this objective devolves to a more standard L2 loss.
Yeah, so that part was not obvious to me why this is 2 terms instead of 1, because they are mathematically equivalent except for the constant factor of beta, which, like you mentioned, can range in different things— to be different things. And when beta equals 1, you can just have a single term. So it's kind of confusing and never fully explained. The other thing that was slightly confusing in the way this paper was written is that typically when you do your VAEs, you want to basically optimize for the ELBO, the evidence lower bound, and it has two terms. It has the reconstruction component and it has the, your posterior should equal to the prior, the KL divergence between the prior and posterior, so that you are sort of pushing the posterior, you know, to equal the prior. And here you sort of don't have like an explicit objective for this second like regularizing term. It's only sort of like an outcome of the way you move the clusters. And actually, like, it's kind of weird because you're— because these are discrete variables, your prior is that each— or like the typical prior you would want to use is that each cluster should activate with roughly the same probability. But that's not what k-means will give you. Like, if you just do k-means solution, if you just run k-means and then you assign your data points to your clusters, And then you look at the distribution that you get, it's not a uniform. It's some kind of a weird thing, right? That's definitely not guaranteed to be uniform. So you are not optimizing the actual VAE objective. And this is not like really discussed in any way.
I mean, it sort of is a VAE only in the most trivial of senses, right? So like the, like you said, the features of a VAE are usually that you have like stochasticity in your latent variables. And here there's no stochasticity in the latent variables. They just do a hard assignment. And say the latent variable is going to be equal to the nearest neighbor of the quantized thing. So there's no stochasticity in the latent variables. And then the prior is this, like, uniform over all the codebook entries. So then if you look at the KL divergence between the distribution over the z and the prior, then it just collapses to a constant term. So there's no need to explicitly optimize this. So I think it was a little bit of, like, a Trojan horse to call this a VAE. It, like, because it feels like in 2017, VAEs were, like, super trendy. And really, this is just a discrete autoencoder is how I think about it.
I mean, I basically agree with that. And the other piece of jank here that they don't talk about at all is, okay, so I implemented this. I re-implemented it. I think you have as well as of this morning, right?
Yeah, I think your implementation is better though. Okay, thank you.
How? But okay, let's talk about that later. But one thing that was jank, like right away my implementation did not work. Just the first time I tried it, it just did not work. And I realized it was not working because you have the exact same problem you have when you run k-means with dead clusters. Sometimes if you initialize your clusters not well, then some clusters may not get assigned any data points, and then there is no update for that cluster. That cluster has— can't be moved to the mean of the data points it's responsible for because there are no data points to take the mean of. Does it make sense?
Yeah.
And so this objective suffers from the same issue.
I mean, it's almost like the dead ReLU problem that we sometimes talk about in ConvNets.
Right. And like they don't talk about it at all. So when I implemented my own version, I actually had to do this very gross, basically data-dependent initialization scheme where in the first forward pass I take my batch, I run explicit run of K-means, and I use that to initialize my vocabulary of embeddings. And that sort of worked, but if you're not careful at initialization, you will get basically very low cluster usage and many clusters will just be dead and they will never get an update. And this is kind of concerning. It's not discussed at all.
I mean, almost the DALL-E paper sort of mentions this, right? In the side note to the DALL-E paper, they say like, oh, once we get away from the straight-through estimator and instead use a scumble softmax relaxation, then we can avoid heuristics with dead clusters. But this is only mentioned in like a footnote to DALL-E blog post and doesn't actually show up in any of the VQ-VAE papers that I read.
Yep. Yeah, so I do consider that to be a gross thing because basically there's no like entropy terms sort of make— trying to get these clusters to be alive, which is different from the Gumbel softmax because in Gumbel softmax we actually have an explicit term that will try to get your softmax to be diffuse. So, so maybe actually we can talk about— we can go over to that paper at some point. Is there anything else on VQ-VAE?
Yeah, I mean, I guess— I mean, we kind of like talked about some gross things in the VQ-VAE paper, but I actually really like this paper. In general. Like, I think it's a really nice idea. I think that this was one of the— I mean, maybe it's just my own bias in the papers that I'm reading, but to me, this is one of the first papers I read that felt like it was really successful in learning discrete latent variables in the middle of a model. And that seems— I mean, yeah, there's some grossness in the way that they do it and some tricky details, but the fact that it works at all is pretty nice. And that kind of gets us a little— And like kind of the bigger picture reason of why this gets me excited is it moves you toward this idea of like symbolic abstraction. That like neural networks are usually working on vectors, but we as humans feel like we're working on discrete concepts and shuffling them around in our mind. And then there's this big question of how can we get discrete concepts to emerge from a neural network? And VQ-VAE at least feels like is a step in that direction.
But I think like the interesting thing is like reasoning not by analogy to like what we seem to be doing, but like what are the computational benefits of this sweetness, if any. And so that's kind of like what I've been trying to think about is what is the computational benefit of having this discrete latent space? And I was like trying to think through like, okay, so these are kind of like in autoencoder— sorry, in autoregressive models, this is where we're going to plug them in. And so why does it actually make a difference that these are discrete things sort of at your input and at the output you can just have a softmax? And I feel like it has to— it has like some nice benefits with basically what I would describe maybe like an error correction towards like a fixed set of possibilities because there's no real need. Like you can have an autoregressive model that is completely continuous. There's completely no issue with that. You can have a nice defined likelihood. You have a mixture of Gaussians, whatever you want at the output. And I think everything would basically work, but we seem to be using discrete inputs and integers at the input of these GPTs. Why is that? And I'm thinking that if you just try to train these GPTs on continuous variables, then when you are plugging them in and recursing, you are probably going to just— I mean, the whole thing is going to explode, basically. And maybe it's somewhat related, but probably not related to the reason we use digital logic in chips. Like, we use digital logic because there's all this, like, noise and so on. And you always want to, like, quantize at each step. So that you can plug components together serially. And that's kind of like what's going on here, like you want to use digital logic in the neural nets because of its sort of like almost error correction properties. Does it make any sense?
Yeah, and I think the same thing shows up in like human language too, that we have a set of words that we can write down in the dictionary, but each one of us pronounces words in a very different way, but we all kind of understand them as being the same symbol or being the same object, even though the sounds that that each of us produces to like make different words is very different due to our accents or whatever. But we all kind of regress to this set of discrete concepts that kind of has this error-correcting concept.
Mm-hmm. Yeah.
But I had another interpretation for why I think this discreteness is really good in generative models. And that has to do more with this notion of mode splitting, right? Because when you have generative models, like there's often fundamental uncertainty in what you should generate. So the canonical example is like when you're generating an edge, then like do we have like maybe a lot of dark pixels and there's going to be some sharp transition to bright pixels at somewhere. And in real images, that transition will be very sharp in many cases, and you'll see a sharp transition between dark pixels and light pixels. But now the exact position of that edge is going to be uncertain. And if you're looking at this, trying to model this image not in terms of edges and edge patterns, but in terms of generating pixels one at a time, then you need to make a choice for each pixel that you're about to generate. Should this pixel be black or should this pixel be white? And the average case is, you know, maybe some probability black and some probability white. And if you're modeling these things with continuous variables, then you'll probably output some gray color instead.
Well, that's only—
the gray color—
I mean, that's only if you like have a bad form of likelihood, like maybe you're using unimodal Gaussian when you shouldn't be, right?
Yeah, exactly. And then I think later autoregressive models, like more advanced versions of PixelCNN, did fix this where they're kind of predicting multiple cluster— multiple like multimodal Gaussians instead of unimodal Gaussians, but it gets kind of hairy. And I think that when you're using categorical stuff, it kind of like this mode splitting problem gets solved for you in a much clean— in a very clean way.
Yeah, I mean, but there is kind of like an alternate like model that maybe I would be like pretty tempted to train where forget the whole VQ-VAE part, or maybe just train an autoencoder and then take your latent vectors, and that latent vector is a compression even though it's continuous valued, and you could try to set up a transformer on continuous, you know, on the continuous vectors. And I mean, everything would just work sort of, but it would probably not give very good results.
Yeah, hard to say. Actually, in the VQ-VAE paper, they do— they have a couple citations to earlier works that do things like that, where they train a continuous VAE and then learn some autoregressive model on top of the continuous latent space. I actually have not read those papers. I feel that I should, but I wonder whether revisiting those ideas in the language of transformers and all the machinery we have now actually could get that to work better than they did in 2016.
Okay. All right. But so basically on the high level, I actually do like the VQ-VAE paper quite a bit as well. I do think it's like a little bit sketchy and it's got this kind of grossness to it, I think, in that your clusters have to be very clever, you know, very carefully monitored, I suppose, during training because there's no entropy term really pushing them to be alive. But on a high level, we are taking small patches of images and we are turning them into integers, and then we are taking integers and reconstructing back the original patch. And then the loss is just trying to, you know, make sure that no information was lost, that we're trying to reconstruct, you know, the input. And the quantization is done at this bottleneck layer using basically vector quantization or like kind of a k-means-inspired algorithm where we are snapping to these quantized versions or embeddings depending on the distance and using a straight-through estimator to actually recover the end-to-end differentiability.
Yeah, definitely. So then should we move on to VQ-VAE2?
Yes. OK, VQ-VAE2. OK, cool. Yeah, I guess we can.
I think this one's pretty short, actually.
Yeah, I think so too. So VQ-VA2 was a nice follow-up. And yeah, I'm trying to remember all the, all the changes. I mean, obviously they have two levels of VQ-VA now, if I remember correctly.
Or up to three in the case of the 1024 images, right? But this is like a, this is like classic problem. This is like classic trick in computer vision is to do like hierarchical multi-scale modeling. So you do like a low-resolution thing, then condition on the low-resolution thing, you get a high-resolution thing and do this so on and so forth. And this is kind of a standard trick in lots of places in computer vision, and they make it work for this particular category of discrete autoencoders.
Yeah, so it's kind of like a, yo dog, I heard you like VQ-VAs kind of paper. So I put a VQ-VA on your VQ-VA, and then I repeat it a few times. I mean, it does make sense, and the results are quite, quite strong. But yeah.
Yeah, there's that. They also use a much more powerful autoregressive model. So I think the first VQ-VAE model was using a fairly vanilla PixelCNN, and now in the VQ-VAE 2, they say they're using something like PixelSNAIL. It's not clear that they're using exactly PixelSNAIL, but something quite like it. So the differences between that and the more classical PixelCNN are that it uses— actually has some masking, which gives some multiplicative interaction between the inputs, which looks a little bit like a transformer.
[Speaker:ANDREJ KARPATHY] Yeah, it's like an embedding.
Yeah, basically, the PixelSnail decoder that they're using in this paper actually looks a little bit like a proto-transformer to me in several ways.
No, exactly. And the other piece that I thought was kind of interesting for VQ-VAE is, like we mentioned, this re-ranking. So they actually do have a re-ranking step that they very briefly talk about. So when they generate their images, they basically first generate a few possibilities, and then they re-rank them, and they take only the images that basically have a low entropy prediction from a pre-trained ImageNet model, making the assumption that things look better, like visually to a human eye, as a sample from the model if, if basically a separate ImageNet classifier thinks that it is, you know, some, some class with high probability.
Yeah, definitely. And I think that's a pretty, uh, important for the results that they're getting. Yeah, I mean, another thing I thought interesting on the decoder, right, like it, it has a lot of properties that look like Transformer. They've got these residual connections, they got multi-headed self-attention, they actually have a deep residual network of 1x1 convolutions at the end, which looks a lot like the feed-forward network we see in Transformers. Um, and then what I thought was really interesting is they kind of were aware of Transformers at this time. So this paper even cited the Image Transformer that was an ICML 2018 paper. That was kind of applying standard transformer architecture on pixels. And they cited that as a powerful autoregressive model, blah, blah, blah, blah, blah. But I found it kind of interesting that they did not just turn the crank and just do a transformer on the autoregressive model at this time.
Yeah, I mean, this is an older paper now, right? This is 2000— what is this, 18 or so?
Yeah, yeah, this was, this was 2018, but this was like, attention is all you need was out there. I think BERT might have been out there. People were starting to apply transformers for autoregressive modeling in images. So those ideas were in the air, but they didn't just use it wholesale like they're doing in DALL·E.
I mean, they probably had a codebase for PixelSnail. Is that really like what it comes down to?
Yeah, yeah, I think so.
It was ready to go, so just swap it in, I suppose. Right. Okay, yeah, so VQ-VAE-2 was nice and basically just like stacks up VQ-VAEs. Let's go to, but basically It really just stacking them up hierarchically and trying to get more high-resolution results, but quite successfully so. So that was nice to see. So now maybe we could talk about the alternative to VQ-VA, which is all the Gumbel softmax work.
Yeah.
And this is what DALL·E presumably uses, although we do not know the details.
Yeah, so Gumbel softmax is one of these papers that introduces this like pretty basic mathematical trick that the first time you see it, you're like, holy shit, why haven't I seen this before? And it's based around this idea that actually is really old about like how do we sample from categorical distributions. And like this is a thing we need to do on computers all the time. Like we have probabilities, they sum to 1, we want to sample from this categorical distribution. And it turns out there's this cool mathematical trick called the Gumbel sampling trick. Where you can take the log probabilities of a categorical distribution, add independent noise of a very particular form sampled from this Gumbel distribution, just add this independently to all the log probabilities of your categorical distribution, and then take an argmax of the log probs plus the Gumbel noise, and taking an argmax of this thing happens to give you a sample from the categorical distribution. This is like, I— some tricky algebra, like not obvious at all, But like the citation here is back to 1954. And I think this actually is sometimes how like, even if you like, you go to NumPy and NumPy gives you some multinomial sampling function, I think this actually might be how multinomial sampling works in numerical libraries sometimes.
Interesting. And then of course, once you have— once you've reparameterized this, then you can take your argmax and you can soften it using a softmax. And then everything is nice and differentiable and trainable. Although there are some trade-offs depending on the setting of your temperature, and now you have to worry about this temperature parameter of like how peaky your softmax is and how close it is to the actual sample. And you're sort of like trading off bias and variance with a few choices that you make here.
Yeah, exactly. And then basically, this was coming around this time, I think in 2017, where people were starting to use softmax all over the place to model kind of like attention-like mechanisms in many contexts, with the idea that like, you know, instead of selecting one thing, we kind of produce a distribution over all the things and sum them up. But this is doing something slightly different where this is taking as input a distribution over all the things and then giving you as output a soft approximation to a sample from your input distribution, which is kind of subtle and a little bit confusing the first time you see it.
Yeah, for sure. No, it took me some time to like wrap my head around it. I do like that it is fairly straightforward once you're implementing it. Because I mean, this is like very, very straightforward. You take, you have a fully connected layer, you add this Gumbel noise, you, and you basically softmax it. You also add temperature, but basically it ends up being like very straightforward to implement. And there's no codebooks. There's no like, you know, it's cleaner, I think, than what we saw with BQVA in my opinion.
Yeah. So it's almost an alternative to something like REINFORCE that we use in other contexts. Right? Because like in REINFORCE, you have this similar notion where you have like maybe a distribution over many things you want to try, then you want to sample one of those things to actually try and then see how well it does. And then with REINFORCE, you kind of need to draw a lot of samples, and the ones that did well, you'll end up weighting upwards in the probability, and the ones that did poorly, you'll weight downwards in the probability. And now Gumball Softmax is kind of solving kind of similar API to REINFORCE, but with different different mathematical properties.
And one thing I like about this is when you're optimizing sort of the ELBO, you actually end up basically with— because you have these logits, you can actually just like regularize into the prior, and the prior is just a uniform distribution. So you basically get this like nice regularizing effect just kind of like by default and for free, where in this like very nice form, unlike in the VQ-VA, where all the— where all these sort of like dimensions of this categorical variable, like they want to be active by default with like a small weight. They really want to turn on and they really want to be sampled and used. And then of course the end-to-end objective is sort of like massaging which ones are actually used and to what extent and so on. But you always have this like bias towards uniform use that's in the objective.
Yeah. And then even if, even if like something or like put another way, if one of these samples actually gets dead, then like it'll get little bits of probability in the sample sometimes and then we'll get a little bit of gradient and then maybe reactivate as well.
Right. Yeah. So, so I kind of like that because if something ends up being dead for whatever reason, it will actually feel this regularization towards being active and at some point it will activate and then hopefully the downstream decoder will like use it in some way or whatnot. But basically all the dimensions want to be active by default.
Yeah. So I think another notable thing about the Gumbel Softmax paper is that there were actually two papers that came out like exactly the same time with exactly the same idea. So there's this one, which is the Gumbel Softmax paper, and another one called the Concrete Distribution, which proposes the exact same idea at almost exactly the same time.
Almost exactly the same, but I was actually like skimming it again today, and I saw that the Concrete Distribution paper cites the Gumbel Softmax paper, and they actually talk about like some differences, but it was very brief, like 3 sentences, and to be honest, I didn't fully follow what they were saying, but they did not seem to think it's identical. But actually, basically, I didn't fully follow. Yeah.
I think one— I could be wrong, but my recollection is that the Gumbel softmax paper also talked about like a hard version of the Gumbel softmax using a straight-through estimator.
Yeah, this is the Gumbel softmax paper.
Yeah, so there's the Gumbel softmax straight-through, which is where you actually have a hard sample in the forward pass, but then in the backward pass, you treat the gradients as if they had been from the soft version of Gumbel softmax. Whereas, as I recall, Concrete Distribution didn't have experiments of this flavor, but maybe I was wrong.
Yeah, yeah, yeah, could be. So basically, like, my big question is, like, reading DALL·E and referring to this work is, I think for me, everything is, like, well-determined except, okay, did you use the straight-through estimator? Like, did you use the hard or the soft version of Gumbel softmax? And what did you do with the temperature and how did you anneal it or did you learn it? Like, those are my questions. That probably is just not specified in the DALL·E paper. And then that would be enough to, I think, reimplement.
Yeah. So, I mean, maybe to put this a little bit more explicitly, we could talk about, you know, if you think about this for a little bit, you can kind of come up with a straightforward way to put Gumbel softmax into the VQ-VAE and then get what looks like they're claiming to do in DALL·E. And they're a little bit dual, right? So in the original VQ-VAE paper, you're at the end of your encoder. The encoder is predicting a vector. And that vector is then like, is then the same dimension as the entries in your codebook. And then that vector that you're predicting is getting matched against all of the codebook entries, and then you snap to the nearest neighbor. Now if you're swapping in Gumbel Softmax instead, then at the end of the decoder it outputs a score for each of the elements in the codebook, and that score says how much do I want to use each element in the codebook. And then you select the elements by passing through this Gumbel softmax. And then the output from the quantization step is this linear combination of the entries in the codebook that are weighted by the output you get from Gumbel softmax.
Yeah, no, it totally makes sense. Like when I was implementing this repo that I have on GitHub now, deep vector quantization, and I was reimplementing these techniques just sort of to learn, I was trying to make the Gumbel quantize layer and the vector quantize layer the VQ-VA sort of quantized layer look as similar as possible. And then the, you can just sort of like visually see that they're extremely related and you can find all kinds of like in-betweens that I haven't seen in papers. And I tried one of the in-betweens, which was along the lines of what you were describing and it did not work. But I'm pretty sure you just have to like torture it to make it work. But yeah, basically, yeah, it's kind of interesting that way.
Yeah, I just think it's like, it's kind of interesting that there's a nice duality between the two, because in like the VQ-VAE, the encoder is saying, this is the vector that I want, and I want to find a quantized vector that is close to this prediction. And then in the Gumbel softmax, it's instead saying like, which of the existing codebook entries do I want?
Mm-hmm. Yeah.
Yeah, it's kind of like— and one thing here that I think is a little bit tricky with the Gumbel softmax version of the VQ-VAE is that like normally when a neural network is like predicting a distribution over something, that something is not changing at the same time, right? Like when you're training an ImageNet model, the definitions of the categories are not changing over the course of training. But that's not the case if you're using this Gumbel softmax, because then the encoder is predicting these distributions over codebook entries. But what are the codebook— like what do each of those slots in the distribution mean— are sort of changing as well over the course of training.
This is during Gumbel Softmax training?
Yeah. I mean, this is more, this is more like thinking about the encoder as kind of a classification model, but it's a classification model over the codebook entries.
Right, exactly. Yeah. Where, where those are derived like in a more roundabout way in the VQ-VAE by this matching to the K-Nearest Elements basically, and then actually like discretizing it or sharpening it basically to just like the closest single cluster.
Yeah, exactly. And then when you think about it this way, you can also imagine kind of in-between variants as well. Like you could imagine that the encoder is predicting a vector and then you try to match that vector with all the codebook entries. And then based on the distances or some matching function, it generates a distribution over the codebook vectors. Then you sample from that distribution using Gumbel softmax. There's, there's like many sort of other ways you could imagine combining these things together.
Yeah. So this is actually the version I tried to implement. I took inspiration from CLIP. And basically my encoder outputted L2-normalized vectors and my codebook was L2-normalized vectors. And I did a dot product between them to get like sort of similarities. I added a temperature and then I softmaxed the rows and that was sort of like the probabilities. And I did not get that to work very well. But, and then it was probably sort of like fed into the Gumbel softmax. But yeah, anyway, so there's a lot of hyperparameters here to tune. But I think ultimately like when I actually did implement these two approaches, like they were giving me very, very similar results. Similar results. The Gumbel Softmax was giving me slightly worse results, but I think there's a few more hyperparameters to tune, and I just wasn't— I didn't like really subject it to like high-throughput screening here, so I wasn't able to sort of find a good spot here.
Yeah, I also did a kind of little toy implementation of these two variants to understand them, and I think I didn't get quite as far as you. I got to the point where both of them, the loss was going down, and that was good, but the loss— so I was able to do like one epoch of CIFAR training for both either the Gumbel Softmax version or the VQ-VAE version. I got loss to go down, but loss went down more on the VQ-VAE version.
Okay, great.
This is really good science here. So definitely some hyperparameters to tune here.
Okay, cool. So I guess we were in the weeds for a little bit. So let's pull out, I guess, and what is the big picture here? So we're looking at DALL·E and the cool new thing is how do you basically sample patch by patch these images? These patches are represented using discrete elements. The question is how you train this discrete element codebook. And we saw that there's two classes of approaches, the VQ-VAE and sort of the Gumbel softmax class. And DALL-E uses sort of one of them. And they both sort of work, but both have to be sort of like tuned to make it work. And so we have a way to basically encode patches into integers and vice versa. And so this is helpful. But I think the remaining issue kind of from this work right now is that the images we are getting in the reconstructions are very blurry, basically. And they've got these like pastely blurry colors and they don't look perceptually nice. And so is that accurate summary so far?
Yeah, I think that's, I think that's pretty accurate summary so far.
Yeah. So we basically want to keep this discrete codebook quality, but we want these patches to also look perceptually, you know, nice. And that's where this last, last paper is, and I don't think we'll have time to really go into detail. Like, I think we could do an entire Clubhouse on just this paper, probably, because it's quite nice. But basically, they swap out the VQ-VAE for a VQ-GAN. And so basically, we are generating these pastely wrong-looking things perceptually. So let's fix that by appending again and perceptual losses, and let's mix them together and get— use a discriminator to basically get more perceptually nicer looking things to the human eye.
Yeah, exactly. So this is the paper, "Taming Transformers for High-Resolution Image Synthesis," that just showed up on Archive fairly recently. And they use a kind of similar pipeline actually as DALL-E, I think. But they're using their VQ-VAE, they replace with this VQGAN. And they basically make two changes in VQGAN compared to the VQ-VAE that we already saw. One is that rather than training this thing with an L2 reconstruction loss on pixel values. Instead, they're training it to do reconstruction in terms of feature similarity in a pre-trained VGG that we usually call a perceptual loss. And the second is that it's also being trained adversarially with a discriminator, which hopefully helps to overcome some of this dreamy quality.
I was actually looking into the code base, and I could have been reading it wrong, but they actually have 3 terms for the reconstruction. They actually have an L1 term instead of an L2 term on the pixels. Then they have the GAN loss and then they have the perceptual loss. So yeah, maybe I wasn't—
Oh, interesting. Well, or it could be— I think it's more likely to be a case where the code doesn't match the paper. That happens quite a lot.
Yeah. So I'm not sure exactly what happened there, but there definitely is a torch.abs of— there's like an L1 loss in the pixels. I don't know what to tell you, but okay. Yeah.
Yeah. So, but then after that, it kind of looks pretty similar to what I imagine the DALL·E is doing. So they learn this, this latent codebook, this discrete codebook. The way that they do it is hopefully a little bit nicer with the GAN. But then after that, they train a transformer to do both unconditional image modeling as well as conditional image synthesis.
Yeah. And what I love about this paper, by the way, is just like the rough idea here, like we have these two classes of approaches to generate, to generate modeling. I think like the mode seeking, which are GANs, and the mode covering, which are these likelihood-based models. And here we are actually mix and matching the strengths of both approaches. We are using a mode seeking approach again for the low-level information, the patches, but we are using a mode covering approach for the higher-level components of the sort of like image and its global structure, which I think is actually quite a brilliant and a really good idea. And I think it sort of like plays to the strengths of both approaches in that sense, because GANs are not very good at this like global level structure because they sort of collapse. And we don't have that problem here because we are using these likelihood-based models.
Yeah, I agree. I think another reason I like this paper is that they're really leaning into the multimodal nature of the transformer and they're doing conditional generation in— by conditioning on all kinds of interesting stuff. So in DALL·E, we saw that they're inputting text and outputting image at the end of the day. And in this, in this VQGAN paper, they're doing input all kinds of different things and then output an image. So they input like, they do outpainting that we already kind of saw. They condition on a depth image. They condition on a semantic label map. They condition on like a set of key points for where like someone's like shoulders and arms and legs are. They do conditioning on low-resolution image. They do conditioning on an edge map. And they, I think, I think it's really nice that they just kind of lean into the fact that a transformer is a very natural way to mix together data of different modalities.
Yeah, I think that's a really good point that it's almost like a pretty like crazy extensions of DALL·E in that sense, in terms of like how you play with the conditioning. But yeah, for me, I think the most interesting part is this combination of GAN and autoencoder. And a likelihood-based model on top. And I think we're going to be seeing much more of that sort of going forward to get perceptually good-looking things and also globally coherent things at the same time. So yeah, I mean, the images definitely look much better. So we don't see any of the blurriness, the pastelness. I mean, these are, you know, game-quality things, but they're GANs on only patch level. And it's probably likely that the GAN is dropping modes on these patches, but you will not be able to tell because we're only after, you know, visual fidelity and these patches look good. And so you're not going to be able to tell just from a few samples that, hey, you haven't like fully covered the distribution of all the possible patches, which is what these likelihood-based models are like way too distracted with, especially in the case of images where, you know, there's just like a lot of noise around. These are like really noisy patches. Patches of like random junk. This is actually, by the way, a very different setting than what we see in natural language because in images you have all this like noise basically, whereas in natural language everything is like a very compressed domain. It's like quite noise-free. And so I think this noise like does not like mix well with these likelihood-based models that try to like cover all the modes.
Yeah, like in some sense in for images, there's so many possibilities of what you could generate and most of them are going to be garbage. That like as long as you can latch onto a couple of reasonable modes, you're going to get beautiful images. Whereas in natural language, it's just like there's not too many reasonable— like you don't have as many choices for how you're going to complete a sentence.
Yeah, exactly. So actually, like the two domains are different in basically the amount of noise that they have. Like, I think like vision is a very noisy domain where only a few things like really matter. And a lot of it is just like, hey, here's a tree of like completely random foliage that is basically like you useful to nothing. And then in natural language, almost everything is deliberate and placed there for a purpose. I think to a first-degree approximation, that's true.
Yeah, definitely. Another kind of subtle point I liked about this paper is that they're actually able to reuse the same VQGAN for all these different downstream tasks, which I thought was really cool. That because, because, you know, we talked in DALL·E that these models have these multi-stage training pipelines where like first you're training this discrete latent codebook. And then you're training an autoregressive thing on top of it, well, you can actually train the discrete latent codebook once, and that discrete latent codebook is now a really good descriptor for natural images, and then reuse that same latent codebook for all these different downstream applications that they're showing. And that seems like pretty practically useful.
Mm-hmm, great. And in terms of like making these images and these patches perceptually, um, pleasing to the eye, I suppose, um, so they are using GANs, which of course are quite standard. We know that they sort of produce nice-looking things. Perceptual losses also are quite interesting and have been around for a while. You've actually had a paper with perceptual losses like way back when, right? When they were—
Yeah, back in 2016.
Yeah.
And I'm actually still surprised that for these perceptual losses, people still use VGGNets. I have no idea why. They just work better for some reason for perceptual losses. Do you understand why this is true?
Oh yeah. I think that's because VGG does very little downsampling in the first couple of layers. So like usually you get a lot of juice from like the first or second stage of VGG, and that's where most of the juice in a perceptual loss comes out. But what's very special about VGG is those first two conv layers are operating at the original image resolution. So they're not throwing away any resolution whatsoever. And then the second stage is operating at 2x downsampled. So that's, um, so and that's quite in stark contrast to the way that most other classification models work. So like in a ResNet, you're getting like super aggressive downsampling by like factor of 4 pretty quickly within the stem. So there's actually not much computation being done on the original image resolution.
Okay. I didn't attribute it to the resolution. I thought it maybe has to do something with like, you know, the residual structure or whatnot. Like for example, when people do all these visualization of intermediate features of ConvNets and so on, Inception models are very often used or VGGNets give you like nice visualizations and so on and ResNets just do not. So there's something like odd, like very weird symmetry breaking properties of these different ResNets and how good they are for for example, feature representation visualization or for perceptual losses for some reason. Maybe that's false.
You know, I'm not fully sure I agree. Like, I've done some work on like some recent— one of my students has been working on like inverting object detectors and those all use ResNets as backbones and we can get like pretty reasonable looking stuff out of ResNets as well. So I'm not totally sure that I buy that.
All right. Well, it's pleasant to see VGGNet around because of course it is like fairly old ConvStack technology deprecated multiple times now with I suppose ResNets and now maybe Transformers or so on. So it's kind of nice when they pop out once in a while still.
I mean, but, but I mean, one kind of funny story there is that when I was first trying to re-implement some of the style transfer stuff with perceptual losses in PyTorch, I found that I had a hard time getting it to work with the PyTorch VGG model. And I actually got things to work much better when I used the Karen Simonian's VGG model from back in the day. So I had like ported over those weights over to PyTorch and then I could get it to work. And then I had a harder time getting it to work with the VGG, with the TorchVision model. So maybe the hyperparameters were wrong. Maybe the normalization is different on the inputs, but you know, that made it work for me at least. Interesting.
Special VGGNet.
Yeah.
Okay. But otherwise, like these perceptual losses also, I think are quite interesting because we, Basically, like, instead of using an L2 loss on the pixels, we are using perceptual loss, which is really just like these losses on the intermediate features of pre-trained ConvNets that were pre-trained on ImageNet, which I think is kind of interesting that this works. And these features are used all over the place, not just for perceptual losses, but for example, for detecting out-of-distribution data, for, you know, style and all this kind of stuff as well. So very interesting kind of use of pre-trained models, in my opinion, that keeps coming back in various forms.
Yeah, definitely. But they're super expensive, right? Because the flip side, you know, we said that VGG operates at the original image resolution. Well, then it's a ton of flops, a ton of memory, a ton of compute. So even though it's like maybe only a couple lines of code to implement, it actually makes your training a lot slower, which is unfortunate.
Makes sense. The price you pay. But at test time, things are looking quite good.
So yes.
All right, cool. So that's sort of like the arc. So I would potentially expect like a DALL·E, um, uprev using basically a VQGAN. I think that could work potentially quite nicely. And, uh, yeah, I look forward to like further work, I suppose, on image generation, uh, in general and really sampling very high-resolution images and doing it very efficiently at inference time and conditioning them on all kinds of crazy stuff and ultimately on natural language. So we can just like describe what we want images of. And so I think we went really quickly, really far from just like sampling various MNISTs and VAEs and so on. And I think there's going to be a lot of activity here because I just don't see how it plateaus. Like with extra compute and with more architectural tweaks, like there's so many, you know, pieces of puzzles here to play with and reconfigure that I think it's quite exciting and will obviously move pretty quickly.
Yeah. Yeah, it seems like we've come a long way really fast on this problem. So I remember like looking at some of the first papers that were doing text-to-image generation on COCO dataset from like not that many years ago. I was like shocked that they can get like an image of a flower and control what color is the flower going to be. And that was like holy shit moment in like 2016 or 2017. And now it's just like not very far later, we're getting these amazing results from DALL·E. And, uh, yeah, it's like you said earlier, I think that there's not much upper bound on this and it'll probably improve very quickly as we go forward.
And it's in a setting where you have infinite data because we do have infinite, like, sort of unlabeled things. So training these massive generative models, uh, on this data, I think we're going to get like beautiful, basically dreams of visual things. It's going to be so trippy. Like if people like DeepDream, like just wait for what's coming. It's going to be crazy, I think. Yeah.
Like in some sense, the, the, the, the end game here is like deprecating all content creation in every other area. Right? Like, there's huge industries that are like, how do you model the physics of the real world in order to get really realistic graphics of things? Then we need to like measure, model all the particles in the world, model the interactions between light and shadow and surfaces, do a lot of calculation on 3D structures out in the world. And that's a— there's definitely a place for that. But one possible future is that maybe all of that gets deprecated with stacks of Conv layers or self-attention layers inside some future version of DALL·E.
I guess one question I also have is like, to what extent can we encode some, you know, inductive biases into some of these architectures like NeRF style? Because everything we're talking about is just patches. But like, world is made of 3D geometry that's like consistent over time. And, you know, things make sort of sense on a physical and rendering layer. So is there no place to actually, you know, have these models slightly grounded in the three-dimensional physics that we occupy?
Yeah, definitely. They had a couple examples of like in DALL·E where they like tell it to look at an object from different viewpoints and they claim it has a little bit of 3D sense because that kind of works. But that doesn't feel like the right thing to do. And I think that maybe if we think about moving, not modeling, not just images, but generating videos instead, then I feel once we move to videos and you want consistent geometry across viewpoints, you want those, you want objects that can move and deform over time, that's where we might see inductive biases of 3D space and time coming more into these models.
So as a concrete example, why can't I have my encoder basically construct a 3-dimensional scene and then use a NeRF-like renderer to, for my decoder or something like that?
Yeah, there actually have been some papers that are starting to do that. One of the earlier ones was HoloGAN. Where it's like the— you have kind of an encoder that predicts this 3D structure, and then from the 3D structure you can render it down from multiple viewpoints. And then you train this with an adversarial type of approach where if whatever viewpoint you render the, the 3D latent variables from, it should look like a realistic thing. So there's definitely been a lot of work in this like single image 3D or single image neural rendering, and that's something I could imagine going forward the next couple years.
Yeah, I think, yeah, because there's like so many biases you could definitely encode. Like, you know, there's a lot of papers, for example, for image to depth to delta pose in a video to like extrinsics and intrinsics and just like outputting that based on the video. And, you know, having these more, you know, having these more explicit three-dimensional representations that then re-render into different image views. And I think I'm like really slightly interested in those kinds of areas just because you know, of the Tesla connection and so on. Like, I have infinity videos from 8 cameras surround, and they do come from very sort of like 3-dimensional reality, and they are temporally contiguous and so on. And so I potentially don't want to, you know, it like feels interesting that way, but it's a very sort of like structured input that you may not just find on YouTube.
Yeah, definitely. But I think the interesting part will be getting this to work on like any video, right? Like, you could imagine a very bespoke system that works with a particular camera system on a Tesla or some other rig. Um, but I think getting this to work on any long-form video would be really interesting because this is basically how we learn too. We like get this long-form visual input through our eyes over the course of our lives. And from these like raw photons hitting our retina, we're able to reconstruct in our brain a 3D model of the world and the objects in it and how they're going to evolve. Um, and, and that feels like we, I want this to work on, on not just images and text, but really on video at the end of the day.
Yeah, I think something like that. Yeah, basically I'm not sure if we're going to need that in this final model. I think it's going to be really interesting is whether these transformers can actually learn that internally without us having to represent it explicitly or if— and yeah, I don't know, maybe that's just a bitter lesson of how this will turn out, right? Is maybe just a big enough transformer with enough compute, just trained on enough video will just sort of like re-represent it without your projections needed.
Maybe that's kind of the big toss-up question for me. Like, it seems like transformers are great. It's not clear how well they're going to scale. Like, we saw even in things like ImageGP— in DALL-E, they had to do some tricks to get the transformers to scale, right? We got to use these latent codes. We need to compress the images. We need to use these sparse attention structures. And even with all those tricks, they're still working at fairly low-resolution images of 256 by 256. Like, I don't know about you, but I'd be pretty sad if I had to watch an entire movie at that resolution.
I don't think that's— I don't think there's danger of that. There's plenty of ways to speed this up if you really have to. I'm not like super concerned about that, I think. Okay.
Yes, I think that's pretty much all the technical meat we wanted to get through today, right?
I think so. Yeah. So yeah, overall, very exciting work. Image generation getting much better. We can condition it on lots of things and we can now sample like pretty like high-res images and it's going to videos, it's going to some pretty crazy conditioning. And the jury's out on whether we are going to need slightly more explicit models that worry about physics and geometry in explicit terms, or if we just throw a big enough transformer at it and have it figure it out just like it figures out that, you know, you don't— you just plug in positional encodings. You don't have to like tell it that that images are made up of patches arranged in a 2D grid doesn't seem to be as necessary, especially if you train on large enough datasets. So maybe it's not clear whether that's going to be needed. And in fact, any explicit structure you put into your neural net eventually upper bounds you in some ways. And there's going to be some ways in which it breaks. Like me as a human, I can go into— I mostly live in a 3-dimensional world, but I can probably operate in all kinds of other weird conditions and my brain doesn't break when there's a mirror in the scene that breaks all kinds of reprojection, you know, things. And so, yeah, maybe that's just like the way to go, but I think we're going to find out.
Yeah, definitely. And I think that's exciting days going forward.
All right, cool. So maybe let's try to get into like a little bit of an audience component here. What do you think?
Yeah, sounds good.
So yeah, people can just raise a hand if they'd like to sort of come in, participate. And just kind of like chat about any of the topics we've talked about. And just— Justin, did you make me your moderator? Oh, you didn't.
Oh, I made— I made— I made the wrong view a moderator. So let me make the— okay. Now, now both of you is a moderator.
Okay, great. Thank you. All right, let's, let's invite up Arvind. He's done actually quite a bit of work on this.
Arvind.
Thanks, Andrej Karpathy. Actually, I just joined in when you guys were discussing about the loss function of VQ-VAE, where it had two different terms and you were confused about like whether— why didn't they just club it into one thing?
Yeah, what's up with that?
Actually, if you read the appendix of the VQ-VAE 1 paper, Um, there is like a replacement— I mean, there is an alternate implementation for the, uh, the second term. I mean, yeah, the EMA, actually the first term. Yeah, yeah, where you can just use the, uh, XEMA, and I think that's the version they use for BQB too. Uh, yeah, I, I guess that's basically the reason they make the distinction between the two terms.
Yeah, I think Why use EMA here when you can just use gradient? Like, why? Where's this EMA coming from?
Oh, is this inspired by k-means, uh, like the algorithm itself? Um, and but the real reason I guess is mostly that it's more stable. Maybe you're— I mean, I didn't actually really look into details of your, like, your recent repo, but My guess is if you try the EMA version, you might have a lot more stable training.
Interesting. That was not super clear from the paper. Yeah, I saw this appendix that there is this EMA solution to the second term, but it wasn't very clear from the text why you would prefer the EMA solution. But I think stability definitely makes sense.
I mean, it still doesn't really make sense. Why should it be more stable or converge faster?
I don't have a principal reason. It's more like it's— I just know that it's more stable based on what they used in VQA2, but they didn't release the code for VQA2.
Okay. Yeah, I didn't implement it actually mostly because I just thought it was gross. Like, it's just, you know, implementation-like noise. It's just if I can use the simpler thing, like, I prefer to use the simplest thing that works. So I didn't want to have these explicit updates updates, just gross.
Uh-huh.
Um, but yeah, that's a good point. So basically, like you're saying that they separate out the two terms because one of the two terms can be optimized using explicit sort of EMA loss instead of just typical backward pass with your gradients, and that's probably why they separate it out. Um, but otherwise, if you're just using backward pass, you can just have a single term and everything should be fine.
Yeah, exactly.
Yeah. Okay.
Yeah, thank you. Let's see. Let's say hi to Reza.
Here is an excellent deep dive there. Really heard that question for you with regard to the transformers. So almost all of these models that we discussed really use it foundationally. And it was built for machine translation, and then we use it for language modeling really productively. And now all of these mappings from captions and images in both directions, it really feels like the transformer could have some innovation for the sake of dealing with images. This is something that you talked about a little bit as well when you said, well, look, in the image world, you have the ability to create. And in the image world, most things are noise. A lot of things can be thrown out. In the natural language world, it's much more crisp. Transformers live in that crisp world. And yet, we're— almost feels like we're shoehorning images into them and then really amazingly surprised at how well they're doing. Which is awesome and I love it, but how much room is there for innovation in the transformer itself here? Let's say we fix DALL·E and then try and come up with a better transformer.
What would we do here?
That's an interesting question.
Yeah, I think for me, one thing that— so I think that self-attention is super foundational and fundamental primitive that is not going to go away. But I think that the transformer architecture is pretty much in its infancy. And like the exact formulation of the transformer that most people are using is not— is basically the same as that from the original Vaswani et al. paper. So like, for example, in images, we know that multiscale modeling is really important. That's something that comes up over and over again. So I could imagine some version of an image transformer in the future that maybe puts in some notion of pooling or some notion of skip connections across multiple resolutions. Where, you know, you, you remember, like, you have one model that works on big— one part that works on big patches, another part that works on smaller, many more smaller patches, and does different forms of structured attention over different, differently sized patches. So that's one thing that I could imagine augmenting the transformer with to be better, better suited for images.
Yeah, I mean, there's a lot of ways. I think it's kind of interesting because, like, it's almost like, like, some people actually feel that that leaving the transformer in its purest sort of form is very pleasing because you are not encoding any of the information whatsoever. And you don't want to encode information typically. So actually they sort of like strive for simplicity and they're actually very happy that the transformer looks identical whether you're plugging in text or image patches, just the same. If you really want to make your transformer, you know, conform more to the images, you are going to do things like, okay, I'm going to have a multiscale layout like VQ-VA2. I'm going to have relative positional encodings. I'm going to have these axial attentions over rows and columns and patches. So there's a lot of like ways to play with the system and, you know, mask out your transformer and whatnot. But yeah, I think all of them probably like work a little bit, but they make your codebase like much more gross. So at the end of the day, like, are you trying to produce beautiful, pretty good results or do you just really want to squeeze out the juice with a more complex repo? And that's sort of like up to you, but there are ways to, I think, change it and make it encode some of the image biases into the architecture. And also, I do agree with Justin that I think this is like complete infancy with respect to transformer models. And there's a huge amount of papers coming out that play with all the details of just the entire setup and the entire architecture. I can't keep track of all those papers. In my count, there's like 30 or 40 at this point. Point. So I'm just kind of like waiting out for it to shake out a little bit. And whatever people end up starting to use slowly is what you sort of need to wait for that signal.
Yeah.
So I'm going to try and figure this out along with one of the creators of the Transformer. You guys are more than welcome to join that session as well. I'm going to open myself to the audience now to allow for other questions.
Yeah. Thank you. Actually, one more I wanted to mention briefly because Arvind was up just now. Let me just— Arvind was up just now. He has a paper where he puts a transformer on the— like, he takes a ResNet-50, if I remember correctly, and he leaves convolutions in most of the network, and then he swaps out convolutions only at the very end, I believe, for the last 3 layers or so. So he's actually using convolutions because convolutions are totally fine and they make total sense for images. They have very nice inductive biases. And so you want to use that for the first few layers where it makes sense, but you use a transformer for the more global all-to-all comms at the later part of the network. And that worked quite nicely for him and his sort of ablative experiments. So there's a lot of ways to sort of like make the beautiful transformer architecture more gross for images, but it's not obvious if you want to do it. Let's say hi to Vlad.
Great discussion. So I joined a little bit late, but I was wondering if you guys talked about the data that they used to train this. That to me, I remember when I originally saw this blog post, this was my biggest question. And then I guess if you look at this, you can infer a lot of interesting things about the, you know, like how they did it, like the architecture, various tricks. But it seems like the biggest thing that they are not talking about, as far as I remember, is the data. And I guess it seems like there's, there's a— it's interesting that the thing that they can—
that they seem to be—
well, not the thing that they seem to hold, uh, uh, hold back and keep proprietary is is the data, I think it's— I guess, is there some kind of deeper conclusion to be made from that? Like, is that the secret sauce for getting all of this to work, do you think?
Yeah, we sort of talked about this briefly in our first session on CLIP when we did it last week. Absolutely. That is the secret sauce. They don't go into detail. And that makes all of this work, in my opinion. Because otherwise, how are you going to train these models if you don't have this beautiful data set of images and text pairs. That's the hard part. I don't even know how to scrape it, how to clean it, how to curate it. A lot of work probably went into massaging and curating that dataset. So yeah, what do you think, Justin?
Yeah, absolutely. I think we covered this last week a lot more that in the DALL-E blog post, they completely punt on the data aspect and they forward to CLIP. And then in the CLIP paper, they give you like two paragraphs about how they constructed this dataset. And to me, like the variety of interesting stuff in the data is going to bound what you can do at generation time. So the fact that they're able to get all these amazing results of like things on storefronts and all these different like images of blocks and X-ray photos of capybaras and all this crazy stuff, this is only going to work if you have that kind of visual variety and linguistic variety in the training dataset. And they give us very little detail on how that was constructed. So I agree, that's the secret sauce.
Yeah, I was looking at the images and I was trying to to find patterns in the stuff that they generate. I don't know, to me sometimes felt like some of the images, they feel very cartoonish. I was wondering if maybe they were somehow their dataset was enriched for that.
I'm not sure.
Yeah, I mean, I really wish they did release the dataset. I mean, I think like the entire community would of course benefit out of these massive datasets because they really make deep learning work and it really gives you an edge. So Google, for example, has this like JFT-300M, et cetera. Et cetera, right? Like, I don't believe these are released datasets. But, you know, like the ViT paper, for example, the original transformer sort of that got good results on ImageNet was trained on JFT-300. And so no one can reproduce that experiment if you're outside of Google. So—
Yeah, I really wish they would release at least the version of this on a different dataset. Like, they can keep their complicated data. Keep their best dataset proprietary, but if they had at least like a smaller version of it so that, you know, you can, you can, you can kind of at least reproduce some of it.
But I mean, to their credit, I don't think it's necessarily just being proprietary to hide things and make things harder for other people. I think it's because there's like, it's, it's potentially dangerous to release data because there's a lot of questions around what are you allowed to do different, what, what kinds of things are you allowed to do with different kinds of data? And by not releasing it, you're kind of obfuscating what data you used and maybe protecting yourself, maybe covering your ass a little bit.
You know, I think this is probably like there's a lot of practical issues, first of all, with releasing datasets of this scale, but I don't think those are insurmountable. I think it's almost like the potentially the legal problems are really holding it back. I mean, but I have no idea. Cool.
Interesting. Thank you.
Unfortunate, I will say, for the community. Thank you, Vlad. I think unfortunate for the community for sure, because this is the fuel, right, for all the for all the neural nets. So it's not clear how we make progress as a community if we do not have datasets like this available to us in a common format. So I think it's almost like there should be some kind of a nonprofit that tries to accumulate and release datasets that have all the correct sort of legal terms, and it would sort of lift all the boats in the entire industry probably. But this unfortunately does not exist. Let's pause it more. Let's see how I do Smerty.
Hi there.
Hey, how's it going, Stephen?
With the way that we were talking through this and we can kind of have the benefit of hindsight and we can look at the VQ-VAE paper and then, you know, version 2 of that. I'm happy to also see the representation learning with contrastive projection.
Predictive Coding.
It's from Aaron Van Den Hoorn, who is one of the main authors on both of these UVAE papers. And what you and Justin were talking through about how, you know, how do we learn these latent representations for images, for other things like that, it's kind of interesting to follow one of the authors' thinking because I think this paper kind of represents his exploration of that. The idea here is a predictive of coding for like the future latent representations of the model. And he ends up testing this in speech, images, text, and reinforcement learning. And it seems to work well for all of them. But obviously it doesn't kind of factor in as heavily in VQ-VAE. I was just wondering if you've seen that paper and if that was like fueling any of your thoughts.
Yeah, I recall seeing that paper. Were they doing it for the purposes of representation learning or was it for purposes of, say, model-based RL or— I'm trying to recall.
Yeah, it was initially just a latent representation that would then be used for other tasks. So essentially the equivalent of the pre-training layers that we're looking at now.
So it's a form of like— yeah, go ahead, sorry.
Oh, one example is speaker detection. And also for pulling out— essentially, they only do it for similar image chunks. But many of the things that I guess we turn to these far more intensive language model-ish style pre-trainers now. But the beauty of this is that it is very, very light. They purposely kind of restrict themselves to very simple models to show that it's quite effective.
Yeah, I think it's an interesting idea. So basically, you use something like a VQ-VAE or something like that to get your intermediate representations and then you are trying to predict the future of that intermediate representation in some kind of a streaming content like video or something like that. And this is for purposes of representation learning mostly?
Exactly.
Yeah.
Yeah, I think it's— I mean, the temporal consistency and predicting the future and so on has been used, um, in this form forever basically. Um, but I still haven't seen sort of like a, conclusive evidence that it also is very competitive with what we have as state-of-the-art, I suppose. But the idea has been around for a very long time.
Yeah, I kind of see the predictive coding as almost a different way to get discreteness into these neural representations, because whether you're trying to predict the future state of an object or in more general settings of multiview contrastive learning where you've just got like multiple views onto a piece of data, whether it's a piece of text and an image that should correspond, or an image and the future of that image that should correspond. In either way, the contrastive learning boils down to a kind of classification-looking problem where now the classes are dynamically defined by the data. So to me, it feels like another way to make use of this fact that classification works really well and we want to get things discrete somehow in the model, and a different way to use that technical insight for learning good features.
And another approach, of course, is for model-based RL. I think that is very interesting, and there are some papers on this. Even including very recent papers where you are sort of dreaming rollouts and learning from the dream rollouts instead of like real rollouts. In fact, Google had a blog post on this like 3, like a few days ago, didn't it? So I also think that is kind of interesting because you're sort of playing out dynamics in your head and you're sort of like figuring out what the optimal strategy is on the model instead of real-world interactions, which of course are very expensive.
I can't remember if any of the DreamRollout papers did something akin to what CLIP has been used here for re-ranking. Like, haven't they done dreaming and then re-ranking of such dreams? Because that's one of the other issues with this. When we're using the models to essentially generate continuations of the space, just like with BQ-VAE or these other techniques, you can't necessarily— the full space is not necessarily representative of the space that you actually want to be sampling. So have any of the Dream methods done that?
Yeah, not to my knowledge. There was— I'm pretty sure there was a Google post on this, so we should all read that post. I think it's an open tab in one of my other 100 tabs. Yeah, I haven't seen it.
I'll hop on and let others talk. Thanks, guys.
Thank you. Okay, let's say hi to Quran, maybe.
Thanks for the reading group. It seems like it's coming back every week, so that's good. I guess my question is around scale and I guess the role of scale in a lot of these papers and work. I think maybe as a motivating example, there's a paper I saw recently from Chris Manning's lab about emergent structure that comes into these transformer models for language, things like parse trees and stuff that are implicitly represented by these models as you scale them up. So I'm wondering if you have thoughts on, I guess, the role of scale when it comes to multimodal data. And I think, Andrej Karpathy, to your point about images having a lot of noise, do you think there's some counterpart there that we could try to explore and maybe some inductive bias there that we could put in potentially and also like these types of probes, right? Like there's linear probes that are pretty popular in language, but what is the corresponding kind of vision version of that?
Yeah. Yeah, I really, I just found the paper you're talking about from Chris Manning. I haven't read it in detail, but it's talking about, as I understand, emergent structure, right? Like you train this big transformer model on a bunch of unstructured text and then in its representation, somehow it learns something like a parse tree.
Right, right.
These kind of discrete structures that you were also referring to earlier, I think.
Yeah, and to me, like, I really like this idea. So, like, a lot of times when you, when you, like, talk to linguists or something, they'll say, like, "Oh, we know language has all this structure, so therefore we should bake in this kind of structure into the internals of the model." But in, like, a bitter lesson sort of way, the more structure, the more structure you bake in, the more you're going to be limited by it when the data doesn't actually fit that baked-in structure. So I think that this is maybe the better way to go, is to say like we're going to train a fairly big generic model that assumes as little structure as possible, and then it should learn useful structure in the data that we're learning, whether it's parse trees and images or some other interesting sort of structure in other sorts of data. So I like this general direction quite a lot, and I'm slightly opposed to baking in too much structure from the get-go into the models.
Yeah, I think I would definitely agree with that. I mean, I think if By the way, people may not be familiar, but The Bitter Lesson is a great post, a blog post by Richard Sutton that everyone should read. And I think I basically kind of agree with the sentiment of that post. And I am very— I just love that we're seeing this convergence across all the different areas of AI to, you know, models like basically the transformer architecture and it working really well across the board in all of these different scenarios and cases and data types. And so I love the simplicity of that and I don't want to mess with it too quickly. So I'm definitely a big fan of just like really massive transformers scaled up and squeezing out all the juice from that and feeding it like infinity data and seeing magic happen. So I'm always like by default on that side of things. That said, like, of course, if you are trying to make something work in practice, you will cut corners and you will make your code codebase a bit more gross, but I guess that's okay. But yeah, by default, not a huge fan of these papers that bake in more explicit structure. The bang for the buck really has to be there basically. And in many cases that may be true. Awesome. Yeah.
Yeah. I think it's interesting that they're pretty noise resistant as well. A lot of the data seems like it's scraped off the internet and stuff. They seem to work pretty well despite that. But yeah, thanks so much.
I'll drop off. Yeah, that's a great question. Thank you. All right, cool. Justin, I think we're coming up to basically 2 hours, which is like a pretty long time. What do you think?
Yeah. Yeah, and it's like after midnight on Eastern time zone.
Justin, are you there?
Oh yeah, I was muted. Yeah. Man, amazing we got through 2 hours without someone being muted when they thought they weren't.
Yeah, so we went through quite a few papers, quite a few stuff. So yeah, I think interesting work. And yeah, maybe we just call it.
Yeah, I think we could do that.
Any other closing statements or?
Yeah, I think we're going to see more big models on— I mean, I think for a lot of these things, like we're looking at DALL·E now and we're shocked at what it can do. And we're sort of shocked at the size of the— maybe not the raw size of the model compared to GPT-3, but this feels like a big model and a big dataset and it can do a lot of things. But if history teaches us anything, it's that we'll look back on this paper 3 or 4 or 5 years from now and we'll think how primitive it was. And it's always interesting to think like, you know, at any point in time, future you 5 years from now is going to think that this current state-of-the-art thing is so primitive, but what's going to be primitive about it? And what exciting things will be developed in the next 5 years that will deprecate this? And like, is this the kind of model that like people, like grad, individual grad students will be training on their bedroom computer, like overnight a couple of years from now? I think it could be. And that's pretty exciting to think about. Yeah.
I think like if we're reflecting, you're reflecting 5 years back, like if you reflect 10 years, 10 years back, it's 2011, AlexNet hasn't even happened. 10 years ago. So I mean, a lot happened since then, you know, like the entire industry, the entire field changed, right? So if we are going to see more and now we have even more people basically in AI, right? And the community has grown. So if we're going to see anything like the delta from the last 10 years to now going forward 10 years, then like you can't even like really guess like what that's going to look like. I mean, you know, during the time of AlexNet, everyone was training like restricted Boltzmann machines on MATLAB on MNIST. So that's a massive leap going from that to the images in the papers that we're looking at today. So that's pretty exciting. So it would be pretty hard to anticipate that we'd be here, I think, 10 years from then.
Yeah, definitely. But exciting to see where we'll get to. So I guess thanks everyone for tuning in and maybe we'll do this again sometime.
Yeah. Okay.
Thanks everyone.
Bye.
More from Andrej

Skill Issue: Andrej Karpathy on Code Agents, AutoResearch, and the Loopy Era of AI










Andrej Karpathy: Tesla AI, Self-Driving, Optimus, Aliens, and AGI | Lex Fridman Podcast #333