How Investors Think About Data [Founders Fund, Sequoia, Bain, Zero Prime Ventures]
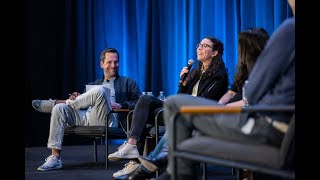
In this Data Council panel, partners from Sequoia (Lauren Reeder), bcv (Slater), Founders Fund (Lee Marie) and a moderator discuss the current state and future opportunities in the modern data stack (MDS). They begin by introducing their backgrounds—ranging from data science at Square to product leadership at Segment and engineering at Scale AI—highlighting their focus on early‑stage data, dev‑tools, and AI investments. The conversation moves to whether the MDS still has gaps, with consensus that many problems remain unsolved (e.g., better tools for business users, Python‑centric tooling, and top‑of‑stack analytics beyond Tableau/Looker). They describe their mental model for categorizing tools: problem‑centric rather than purely layer‑centric, emphasizing the base storage layer, transformation, and user‑facing problems. Specific market gaps identified include underserved business‑user analytics, the need for more interactive data applications, and the emerging “data apps” space that blends dashboards with internal operational tools. They discuss the potential for re‑bundling vertical analytics on top of warehouses, and the role of data contracts as a data‑quality layer beyond simple schemas. The panel then shifts to AI/LLM trends: rapid adoption of developer‑focused tools like GitHub Copilot, new AI‑powered creative products (RunwayML), and the broader impact on search (ChatGPT‑style interfaces, SEO disruption) and community knowledge bases (Stack Overflow). They explore the emerging LLMOps stack—prompt engineering, fine‑tuning, vector databases, plugins—and debate where prompt engineering ends and bespoke models begin. Finally, they offer founder advice: focus on unsolved problems, leverage nimbleness during AI breakthroughs, build complementary teams (design, sales) early, and stay passionate about the product and customers. The panel wraps up with a call to action for founders to identify real pain points and capitalize on the evolving data and AI landscape.
Chapters
Thanks for coming. You guys are great partners and supporters of Data Council, so thank you for that. I want to jump right in and let you introduce yourselves. You could do it better than I did. And please tell us about the last job that you had prior to getting into venture because I think that's particularly interesting and might be inspiring for the other geeks in the room.
I'm Slater, excited to be here. I'm a partner at bcv focused on tools for data teams for the most part. I kind of had a halfway job before this. I led data at Valor Equity which is a growth stage investment firm. But my last kind of true data job was at Square where I was a data scientist working mostly with the growth team.
Hi everybody. Lee Marie, investing at Founders Fund. Been there for about two years and look at dev tools, data and ML really across all stages but with a particular focus on early stage. Prior to Founders Fund I was one of the first engineers at Scale AI and then a product manager there and was mostly working on building out lidar annotation for self driving cars and other types of companies that use perception.
Hi, I'm Lauren and I'm a partner at Sequoia where I mostly focus on early stage teams, generally by engineers for engineers, whether it's data engineers, other engineers of all types. Prior to Sequoia I was at Segment where I ran the core product team. I was there for about six years and then before that worked at a tiny edtech startup that didn't go anywhere. That's about me.
Great. So I think the most common slide I've seen hashed and rehashed and joked about and teased is Matt Turk's Modern Data Stack or Modern Data Ecosystem MDS slide, which now has umpteen trillion logos on it and it's hard to track. Why are we here talking about investing in data? Hasn't everything already been built that needs to be built? And are there real gaps in this market anymore?
I mean just as one take on this, yeah, I think there's definitely more to do. I guess this framing for founders. Maybe instead of taking the magnifying glass and finding something, some space in the map that sort of hasn't been taken over by this explosion of companies. It's always kind of useful just to think about problems that remain unsolved, which there are a ton of, unless we feel as though we have no more problems in Data land. And the other thing I'd say is I think some stuff can be solved more or solved better. We had OLAP pre Snowflake we had data transformation pre dbt. As long as there are still problems to solve, I think there's more to do in Data land.
Absolutely. So one of the first market maps that I did, I guess probably really just a subset of the one that keeps getting referenced, but I just kept hearing these pitches for Data Platform and Data Tool and so I really needed to map each tool to what's the user, what's the use case? And so I do think there are always opportunities to make a better X, or to unbundle Y, or to bundle zone. But yeah, really focusing on the user and the differentiation.
Got it. And what mental model do you use to sort of understand and categorize the tools across this broader market? We have many tool companies who participate in Data Council, many who have grown up through the ranks, going from Data Council speaker to founder. How do you sort of look at Matt's map and how do you break it down in your head into the meaningful parts and components for you? Lauren?
I mean, I think about what problems they're solving for customers. I think similar to this later. And then we think about, hey, what's the base layer that everyone needs to store their data? And then what do you need to do to understand it? How do you utilize it? And think more from the perspective of what is the problem that you're solving than like, hey, I'm a data observability tool, like that can solve a lot of different problems.
And do you think that there's any specific gaps in this market? Are there things that are on your short list outside of AI, which we're going to save for later in the conversation, but specifically in the data infrastructure, tooling, mds, analytics world, or maybe even the machine learning world as well, because there's obviously meaningful tooling being built there. But what's on your short list in terms of things that you're actively looking out for? Founder came to pitch you a company today, like what's missing from. From your portfolio or for what's a gap in your thesis that you want to fill at this moment?
I think it's interesting if we look at actually the top of the stack, I feel like people are less well served today. If you look at tableau and looker, they've been stagnating for quite a while and I think there's a new generation of companies building. Oh, thank you.
That's okay.
You're good. It's on now. Thank you. I was just saying I think the top of the stack actually is the least well served. Like teams outside of the data world. And so building better tools to help data teams serve their customers. Tableau and Looker have been around for a really long time. There's not much that's happened there. And I think as we've built up more options of semantic layer, there's more to build on top of those tools as well as getting a little bit into AI. There's certainly new interfaces that can be built on top of that data too.
Yeah, I think sort of why now? Is always a great question to ask. And I mean I think one theme that we've seen at the conference, people are paying a lot for Snowflake. So as Slater said earlier, I think companies that promise to sort of unbundle OLAP, so like DuckDB's partner mother Duck had a great presentation yesterday on maybe we can sort of use the DuckDB query engine and reduce costs and not have to send all these queries to Snowflake. And then I think another great why now? Gotta get into the ML stuff Is this the advent of this LLM technology and how accessible it is. Can we rethink parts of the data stack with that as a first class citizen and can that be sort of a wedge into a differentiated product?
Yeah, I don't have time to add to that. I feel like it's what users or user groups are like somewhat underserved or could be better served. And so I agree with Lauren's point that there is the business user is maybe a little bit less well served today than they were in the past, which is interesting. I also think the Python side of the ecosystem is still kind of underserved relative to the SQL side. So some interesting things there, I think.
Well, let's stay at the top of the stack for a minute because Lauren mentioned the applications that are being built now on top of these tooling, this more developed tooling. It feels to me like it's taken us kind of 10 years to get here where we now have the data ETL'd and cleaned and transformed and sitting in warehouses. And it almost feels to me like there's this next phase of development where now we have to figure out what to do with the data. So I mean, I think reverse ETL is a little bit of a manifestation of this. Right? It's not, it's almost not its own category. It's that we realize that the data pipeline actually extends to the right of the data warehouse and now we get to do all kinds of cool things with the data and we never thought of that before or weren't ready for it. Quite honestly. When you think about, you know, sort of that as a framing or even building on top of Snowflake, what do you think about this data apps category? Like, what does that really mean and how do you sort of suss out opportunities in that space in terms of getting the user closer to end users that might get a little bit further and further away from the actual infrastructure teams who have done all the ETL ing for the last little bit?
I feel like data applications is almost like two different things in my head. There's what I would call the better than a dashboard part, which is like, can I have something that's more interactive? I could run some scripts on data. I can do more than I could with a purely passive dashboard. And then there's also this internal ops use case which is much more complex. I'm building something that an ops team is going to use internally. It's going to get used by a fulfillment team or a sales team or something like that. And they're really just super different with different users, different buyers, different problems to solve. The write back problem doesn't matter for the better than a dashboard piece. It matters a ton if you're building internal applications. So I don't know. I think of them as different categories, but I think they're both valuable. Like both things that should happen.
Yeah, I agree. I think we'll actually see a huge expansion in what it means to be a data app. I think the most basic data apps so far have been analytics tools, dashboards and like a little bit more complicated things for ops teams. But because building a machine learning team has been so hard, there hasn't been a whole lot of apps with data to personalize them or data to drive new features. But now I think that the bar has come down. So much for getting access to a lot of these AI models, whether it's large language models or others. I think we'll see a lot more interesting functionality with data in applications. So it'll have probably a whole different meaning in a couple of years.
Yeah, I mean I love the paradigm of now we have so much standardization in the data stack. You as an app can just plug into the data warehouse and just provide a lot of stuff out of the box and especially a lot of stuff. People know SQL. So yeah, I think ML is an exciting area. User analytics, experimentation. Just plug right into the data stack. Onboarding time is super low.
Sort of a little bit in conjunction with that or opposed to that counter to that. Do you have a sense that I think it might have been Tristan Handy who talked about the rebundling of analytics, for instance. And do you have the sense that raw data sitting inside these systems that might be a little bit harder to make use of, coming out will give way to more verticalized applications? Like, for instance? I mean, I think the classic example is Google Analytics, right? And it used to be very easy for any of us, even those who aren't technical, to sort of understand the conceptual framework of web traffic and site visitors because we had an idiot proof tool and UX that just walked us through that. Now we're landing all this raw data and events and, and stuff inside, you know, generic horizontal scalable data stores. And to get the context out of that data, you know, with Tableau, it's not, might not be the same experience obviously as something that's as tightly baked as a ga. So I'm wondering if you have opinions on that and sort of which way we're headed perhaps there.
Yeah, I mean, I think this actually kind of goes back to Lauren's point about like there was this business user who was very happy with their 20 dashboards in GA or whatever set of things they were looking at. And I mean, I'm going to just like parrot Tristan's gospel on this because I think he's right, which is like that person has like a worse experience now that everything is gated by knowing SQL and knowing where to find the tables and stuff like that. And so, yeah, I think there's an interesting opportunity to like go look at all of the verticalized analytics that existed 10 years ago, rebuild that, put it on top of the warehouse so you actually have row level stuff because like, you know, the thing that was annoying about GA or other vertical tools I felt like is they worked great when you could answer the question in the tool. And then the second that you couldn't and you just wanted to have access to the underlying data, like it either didn't exist or you couldn't get access to it. It was very gated in that way. But I think you could literally have both now where like it's your own data, it's in Snowflake or your warehouse, you can get at it. But there is a good story for the business user to.
Yeah, I think the other benefit that you get with the warehouse world is you have context from a bunch of other data sources. And I think now that we're rebuilding on top of that, hopefully we'll have much richer context with both easy to use tools and customizable tools.
Well, you mentioned machine learning use cases and how some of that is advancing our understanding and the way that we sort of store and process data and we'll get to that. But one last question which is a little clickbaity, a little important and definitely top of mind on folks in this room. Are data contracts a thing? Is this some fresh magic or are we really just talking about schemas, which we've had forever? Any hot takes or opinions on this world of data contracts and how hot it is right now? And Chad is here and has joined us and gave a talk which I wasn't able to listen to unfortunately. I'll catch the recording. But we have lots of thought leadership around this area and I'm curious in terms of your perspective as investors, how you sort of look at the space.
I think it's just a good reminder that data quality is still a big challenge. We have all these tools that do help out a lot, but they're still kind of this last mile. And just declaring a schema maybe doesn't capture all the conversations between data consumers and producers that need to happen. And then maybe there is sort of a useful level of abstraction where people can test and make sure that there aren't regressions as data's coming in versus just syncing directly. But yeah, I mean, I think it's an exciting sort of take on data quality and excited to see what tools come out of it.
Cool. Well, let's move on into some more of the ML AI stuff. Lee Marie, you wrote a blog post which seems like an eternity ago, but you reminded me it was only June of last year. You sort of talked about your aha moment when you had programmer friends who told you that GitHub Copilot was actually something special. And you might have been a little bit incredulous prior tell us about that moment, what that meant for you and sort of how you're looking at the category now to kick us off.
Absolutely. So yeah, I think it was kind of just an aha moment in that when Copilot first came out, I'll admit I was just very skeptical. I was like, oh, maybe this is nice for people that are learning how to code. It'll help auto complete some of their words. That's great. Then I'm catching up with a portfolio company, one that I consider having very strong top of the line engineering team. They're all using Copilot. I was just blown away. And they're like, we're using it for free right now, but we would pay so much money if they decided they were going to just take it away from us. So I think that that was kind of the start of I really need to understand what this technology is capable of if it's already capable of taking an A programmer and saving them. I don't know more than 25% of the time that they spend writing code. So really excited about things, especially in the devtool space. I think kind of given the success of Copilot there's a lot of adjacent areas where it becomes very feasible to unlock. So I have a company that I'm working with called Grit where they essentially solve common tech debt tasks right out of the box. So one thing that they can do is take your code base that's written in JavaScript, migrate it to TypeScript and then the way that that works, it's an AI developer so it submits a PR to your code base and then you're commenting on that PR and an LLM is making those changes. So I think that there's all these really cool pockets of devtools where this just becomes a 10x better product than we could do before. And then yeah, I think unit testing is another really cool area thinking about how to just utilize this for enterprises. Whether it's like Copilot on Prem, something that Codeium is doing, another portfolio company and then yeah, let's see, just all different types of code review. You could imagine like auto completing dsl really unlimited devtools possibilities.
Yeah, it's very amazing that that coding and developer related tooling has been hit quickest by the space and the developments of LLMs. Obviously there's also the other classic use cases. Jasper is here this morning. Copy AI the marketing generation collateral which is obviously catching on like wildfire. Also image generation, what other categories are we excited about? And we'll spend time talking about the dev tooling one and come back to that. I want to put a pin in that. But before we do that, what other sort of high level spaces are you excited about in terms of seeing the applications technology?
There are so many I feel like you could just pick any application and this technology will probably be able to apply to it. Whether it's the language model side, whether it's image generation or otherwise. You've got everything from. One that I find particularly fascinating is Runway ML which they work with film studios to do the animation and production and you just can film a video of yourself kind of like dancing around and it will generate the background, it will turn you into whatever character you want to be. They had a really interesting proof point where they helped bring the design team for the film everywhere, everywhere, anywhere, everywhere, all at once. I think I still got it wrong. From like 300 people down to seven animators using just their tool, which is an incredible proof of just how effective it can be. Watching that film, I did not know that it was any different than what traditional animation looks like. So there's creative tools, which I think is in a category that was really unexpected to have AI have an impact in beyond just the general structured data that traditional ML has been able to tackle. Slater, if you have others.
Yeah, I agree. I mean I think there's a ton, right. There's all sorts of like so many industries are so like document preparation oriented. There's like a tons of, tons of things to do in like legal or medical or you know, all of these workflows that are very doc oriented. But I do think code is like the one that I like think about the most because it's just so many things are like one or two degrees removed from like, can I write code to do this? It's kind of the like, you know. Yeah, like if software's eating the world and AI is eating software, like, I think there'll be a lot of like second order things there too.
And what do you think about the LLMs replacing search use cases? I mean, let's talk about that again before we sort of stay high up before we go deeper in the stock, which I want to get to. But like, is there existential threat to search based on ChatGPT?
Absolutely, yeah. I mean, so the sort of new paradigm, and I'm sure a lot of you have seen the most mainstream example of this now is Bing's new sort of ChatGPT interface. But essentially it's a new search experience. You're talking with somebody and they're giving you a summary and you might not visit a webpage. And so like traditional ads, it just doesn't work. And traditional SEO doesn't work. You might imagine a world where you might pay to get your data weighted more in this ML model that ends up getting spit back out to you. And so yeah, I think it's something that all of the big companies that are involved in search are thinking about heavily. I thought this was really interesting. A few days ago I read bing has had 1 million new daily active users just from the Bing preview. And that to me I was kind of surprised because in some ways I do still like the traditional search experience where I'm getting to look through links and I'm getting to develop my own opinion. But then I talk to my parents or some of my friends and they love the experience of chatting with somebody. And so, yeah, it's kind of unintuitive. But this sort of new paradigm is something that a lot of people prefer over traditional search.
Yeah, I mean, I think information retrieval will get a ton better. But to your point, the most interesting thing is could the entire paradigm of search change? Because search is built in this time when it's like the goal is to find docs that humans have created or find resources that humans have created as opposed to being able to generate something. So even again, just going back to the coding use case, I find that a lot of my old flow was like, I don't know how to solve this problem. I'm going to go search for something on Stack Overflow. I'll do the synthesis in my head. But now the AI can do the synthesis for me. It's just like, tell me how to do this without installing image magic. Something else can do the thinking for me, which is interesting.
But I guess the thing that worries me about this, and I'm glad you brought up Stack Overflow because it's so relevant to those of us in this room. What about the death of Stack Overflow? And so if we can continue to go to the LLMs which sort of were originally seeded with all this great content from Stack or Quora or wherever, but people stop going to those sites to contribute for new developments and new libraries and new things in the future. Like have we sort of, you know, cut off our own nose despite our face? And we've relied on this UGC being created for decades, like 15 years anyway, to support and to seed all these algos and is there some existential crisis where we sort of end that process and there's no more virtue of virtuous content loop created? Anyone concerned about that or is it just me?
Yeah, you can achieve immortality by contributing to the training set. Right? Like that's how you can do that. But I mean, I think that this is maybe going in a slightly different direction, but I feel like, I notice how a lot of that stuff, stuff stopped becoming public a few years ago. You have to be part of some discord or some Slack group. It's not like a public subreddit. Stack Overflow is still pretty public. So I mean, interesting way, I feel like, I don't know, there's lots of different ways that sort of like the corpus of what's available could change. And I don't know, having an AI help me mine all of human knowledge in some domain, it feels like a good. That's the thing I want.
I think in some ways human intelligence is also generative. We take in a bunch of contexts, then we figure out how to draw the connections between them and then spit out an answer. How the world works and we test it against the real world. And if that's what these machine learning models or LLMs are doing themselves, then it's not that different from how we think. So I think it's a question of how good do they get? Because I think at some point all content will be generated and that's the world we're going towards. And if they're good enough, then we'll be great. And if they're not good enough, then we'll just have to keep generating our own content too.
Yeah, well, one of the things I took away from the AI panel this morning especially was the quick, the speed to which every panelist was really wanting to talk about training on your own data sets. We know already that the LLMs, they give us, they sort of rise the floor. Maybe they give you 80% utilization and sort of a particular problem, like right out of the box. But everyone kind of already is already accepting that we need to be able to. Whether it's prompt engineer, prompt engineering is not a real. It's not a real engineer, by the way. Didn't know if you guys knew that. Whether it's prompt engineering or fine tuning or input processing or output, there's sort of these ways that you can build utility coming in and out of the model, but obviously seeding it or training it with our own data is critical. Does the reality of that change how you think about data strategy and how you would encourage your startups to be thinking about data strategy and how they might be contributing to the future value chain, so to speak, of how these AI models and systems will be especially useful,
I might actually disagree that prompt engineering is not real engineering, because I think as context windows get bigger, it's the only thing that you can do that's different with your interaction with an LLM is the prompt that you give it. And as contact windows get bigger and there's more information you can give to it, you actually want to be pretty careful and really thoughtful about what information you do give. So if we're at the point down the line where you can program some logic into what you give a prompt, that could be interesting. I don't know if that's what we'll end up. And right now, yes, prompt engineering is generally Very basic, largely because there's just not much you can give. But if we are in a future, we can give more. I think it could be much more interesting than it is today. But anyway, I'll let others answer the rest of it.
Are you interested in companies that simply wrap open API?
No. I mean, well, I think it needs to be part of it. I think it's part of the picture, but you also have the rest of the product and the workflow and everything else that someone interacts with. I think search is maybe like the purest implementation of or product that you can build off of LLM. There's a few others, but most products will require much more than just prompt engineering on an LLM.
Yeah, it seems to me like we're still exploring in terms again of this surface area around the LLM. Where does prompt engineering give way to fine tuning? Where does that give way to. Oh, I need my own bespoke model and I should start from scratch, right. I think. I feel like we're still turning the knobs and dials and sort of figuring out exactly how we're going to extrapolate the value that we need. You know, which brings up the point that these LLMs are not really like made to run at Internet scale. So it's like what, what other infrastructure tooling, you know, since we're mostly tool builders here, do we believe it's going to emerge around the LLM to sort of make it, you know, Internet ready, Internet scale and foolproof from an application development standpoint? What are you, what are you watching in that category?
Yeah, I guess every company that I work with is thinking about this right now, because I think now is the time to honestly make sure that you're recording the right data that you need, because you will probably need to edit the current foundation model or whatever you end up using, whether it's fine tuning or using something like a retro model. This is a really cool paper from DeepMind, basically where you can create this database of things to teach your LLM and it will bring it into the prompt depending on what's contextually relevant. But there's just so many different techniques so that you can fine tune something and make it your own and create a copilot for whatever product that you're building. So yeah, maybe something like a vector database ends up being used to store and act on embeddings, or maybe there's some other middle layer that helps set a lot of this up.
Yeah, I feel like we'll eventually figure out how to separate the generative piece from the information retrieval piece. And that will probably be the path which people find ways of putting their own data into the system. There's lots of interesting approaches to that, but that separation to me feels like the thing where we don't want to store all this information in the model weights. We want to find some way of separating those things out or putting it
all in your prompts seems really challenging with the current version of prompting.
Yeah, it feels to me like we're still Even though the LLMs are game changing and again they sort of raise the floor by 80%, the fine tuning loop actually looks a lot like the same old MLOps loop of training your bespoke model in the first place. You need clean data, fresh data, labeled data. And so all the same things that sort of go into the fine tuning loop are basically things that we've been discussing and we found a hard time with, quite honestly, in the ML world over the years. So it seems to me like there might be some miniaturization, if you will, of the MLOps world that sort of becomes the LLMOps world. Do you agree or is there something I'm missing there?
I think something like that will happen, but like from a customer perspective, I feel like the closer to zero shot you can get, the better experience it is for that customer, especially even if it's a story where later on you're going to refine the model a little bit. I do think that especially if you're doing anything vertical oriented, the closer to zero shot you can get, the better.
What about the plugins? We should address the plugins because they're so fresh and new and I'm still on the wait list. I don't know about you guys, but like I had a question typed up from last week to ask you guys, like when is OpenAI going to buy Zapier before or after the conference? And then they released the whole plugin thing, so I can't even ask that question anymore. But this is like the app store of the iPhone. Will the impact be any less significant?
I didn't realize you had written that question before the launch. That's pretty good. But it's interesting because when I saw the question I did actually think about it, even with the plugin launch because, oh, maybe Zapier has a ton of integrations, but I do think OpenAI seems to want to stay more on the infrastructure side and so theoretically we'd want to provide this sort of technology to many zapiers. So zapier and then also sort of the LMFIR zapiers that are being built right now. But yeah, I mean, it definitely shows that they are continuing not to just stay in the pure foundation model layer of the stack, but starting to move a layer up from that. Yeah.
We had Sam Altman come by our office last week and he talked a bit about plugins. And one of the things that I think is not to be underestimated is that OpenAI is incredibly ambitious. And if you look at the most valuable company, it's not aws, it's Apple, it's the App Store. And so I think they will build where the money is, but I think their philosophy so far has been to build things that are generally available for everyone. So they're not going to build vertical solutions on top of this, most likely, but I think they're going to go for wherever they think that they can build the biggest business.
Well, we're essentially out of time. But in closing, like, address the audience in a way that could give them some advice or help or expertise. Right. You talk to a lot of engineer founders, each of you, every week, as do I. And I'm sure there's patterns and failure modes and common pitfalls that you can advise folks against. Like, for the folks here who are thinking about taking the plunge and to start a company, what kind of advice would you give them? In parting,
I feel like I'll say this sort of maybe isn't theme, but just like finding a real problem that remains unsolved is the core thing. And it's also great if you have some type of fit for that problem, there's some reason why it should be you. That's one of those things that's true as a fundamental and also true for how investors think about companies. And then, yeah, finally, I feel like moments of dislocation, like having new, like this explosion of AI tech, are always really interesting for founders because your advantage is nimbleness. And there's probably all sorts of things that are doable now that weren't doable just like two years ago. And it's an exciting time.
Yeah, I agree with all that advice. I mean, I think with engineer founders in particular, and I work with a ton of technical founders and I love it because I was an engineer. Doubling down on what makes you special and great, I think is ultimately like the main advice. But then as you grow your company, having an open mind to sort of people that can compliment you. Not necessarily saying that you as a founder have to be great at everything, but I think some of the more important hires that we made early on at scale. We hired a designer even before I got hired. And then we hired a salesperson in our first 10 people. And just having that complimentary expertise to compliment Alex, who is an excellent technical founder, was huge. And so that's probably one common failure mode that I see, because you are so smart. And, I mean, I make the same mistake sometimes, like, oh, I can do it, and I can learn it, and I know it. But having that sort of complimentary team with you.
Yeah, absolutely agree with all of that. I think coming from the product world, one of the things that really matters, both I think, for in product and for founders, is to love what you're building and love your customer. Like, building a company is an unreasonable thing to do. It is unreasonably hard. You have to go up against this crazy competitive market with these huge incumbents often, and you only are starting with you and a couple people and a tiny bit of funding. And so in order to be able to make it through, you have to be driven by something beyond just wanting to make money or be rich and famous. It has to be something that you really love, I believe.
Yeah. Well said. Thank you for that advice. Well, that concludes the panel. Enjoy your afternoon, folks, and let's give the panelists a hand. It.
More from Lauren

OpenAI’s Deep Research Team on Why Reinforcement Learning is the Future for AI Agents
How Investors Think About Data [Founders Fund, Sequoia, Bain, Zero Prime Ventures]