Jellyfish shows how to track DORA metrics like deployment frequency, change lead time, failure rate, and time to restore service. The dashboard pulls data from CircleCI, Jira, and PagerDuty, then lets you filter by team, repo, or board to see where deployments are speeding up and failures are dropping.
Chapters
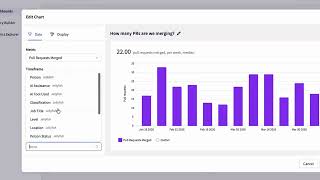
Today, we're going to take a look at Jettyfish DevOps metrics through the eyes of an engineering leader. Jettyfish DevOps metrics are housed in the delivery work area within our wider engineering management platform. We can see a set of core tracked DevOps metrics, which include those defined by DORA, So that's deployment rate, change lead time, change failure rate, and time to restore service. Each includes a time series visualization and a card overview that automatically calculates for the period I'm viewing. As an engineering leader, I'm always interested in how deployments are faring. In this example, Our deployments are tested and deployed to production automatically, with the data here being driven via an API call to CircleCI. I can see my team is averaging around 10 deployments a day, and the trend has been increasing. This suggests our process is improving over time. I want to ensure that the majority of the deployments are coming from R&D and innovation, not just keeping the lights on, so I can click into one of the bars and get a more detailed analysis. I can see the name of each deployment, when it occurred, whether the deployment was successful, which teams were involved, and if I click the source, I'll be sent to the deployment within CircleCI. I can also see a high-level overview of team deployment figures, and I'm happy to see that R&D Innovation makes up the majority of these deployments. Taking a quick glance at the other metrics, I can see two different types of lead time: Jellyfish allows me to define metrics that are most helpful for my team. Commit lead time, in this case the time from an individual commit to the deployment, has remained steady at around half an hour. Issue lead time, the time between work starting on an issue in Jira until the deployment when that work shipped, has fluctuated a bit more, with a large decrease after the summer months. This is right around the time we made an improvement in our internal process for which is great. Failure rate, which is powered by an API call to PagerDuty, is fairly sparse, indicating we did not experience that many failures. This is a positive signal that we're building quality software. When we do fail, time to restore service is also pretty low on average. Now that we've taken a top-level glance, I'm interested in understanding how specific segments of my organization are doing. If I open my filter tab, I can apply filters on the organizational level, but also on the repository level, or for a given Jira board, which is a handy way to slice and dice a more granular understanding of my organizational delivery. These filters are fully customizable and specific to your given development stack and team needs. I'm interested in how the engineering team has been cracking on, so I apply this filter. These key values are pretty powerful and can be applied to specific pipeline segments or bespoke team structures. That's all for today, but if you'd like to learn more about how Jellyfish can accelerate your DevOps approach, check out some of our resources via the links in the description, or book a live demo today.