Engineering at Stripe's scale - Stanislas Polu (Stripe)
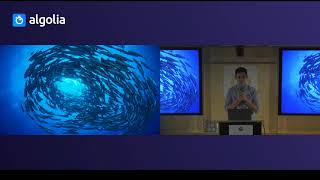
Stanislas Polu describes how Stripe's engineering culture shifted as it scaled from dozens to hundreds of engineers. Early on, every team email was CC'd to a shared list so a third engineer would always see conversations, fostering cross-org knowledge. As the company grew, this "flocking" dynamic broke down, requiring reorganizations and management layers.
Chapters
Hi guys, I am Stan. I'm working at Stripe. For the fun fact, I joined Stripe through the acquisition of a company that was the actual first non-US user of Stripe. And we see a pattern of early users of Stripe joining as a company to company. So if you've been using Stripe for a long time, we can talk about it. Acquisitions. So basically I wanted to give you some perspective on engineering at Stripe scale but from an IC perspective. So that's kind of my massive disclaimer here. I always wanted to stay an engineer. I never became a manager or product manager or whatever. And so I'm in no way an expert or whatever. I'm just a guy in the middle of that massive, massive hulk and I'm just looking at what's happening. For the past 3 years. And so I joined 3 years ago, 2015. I think it's interesting to start there and to give you a perspective on what was the state of Stripe at that time. So we were around 180 people and 80 managers— 80 engineers. And when I was interviewing for— as we were joining the company, I realized that they had at that time no engineering manager at all, and no product manager at all. And it was kind of interesting to me and intriguing. So after we decided to join, I kind of asked my interviewer, I contacted them before I started, and I said, so you said you had no product manager and no engineering manager, and yet you were 80 engineers. So how on earth are you even capable of doing anything? How do you organize yourself? I think none of them were kind of able to give me a sensible answer at the time. They were just like, eh, you know. "Remember Stripe? It works." And I think it's only after 6 months or a year of like being part of that mess that I understood exactly what was happening. And so the first thing that was really interesting is, and it was very particular to Stripe, was a very incredibly strong trust among engineers. Which means that if you had a new engineer, somebody starting like today, If he decided or she decided to start a task, the whole engineering org would trust entirely that that person would be able to produce the results as fast and as good as anybody else. That also means that if you have two engineers working closely on the same kind of projects, even if we don't— I mean, people were kind of self-organizing around projects. And so if you have two people working on the same project, if one guy says, hey, I'm going to work on this, and the other one says, I'm going to work on that, They're not kind of looking over their shoulders to see that the other one was doing the right thing. Everybody really trusted themselves. And so it creates a kind of a local separation force. You don't kind of like couple yourself too much with people next to you. Then at a time we had a policy that we were pretty vocal about. Little less today. It's more become a usage and not a policy about open communication internally. And what it means is that we had us— I mean, we still have for every team within Stripe a set of mailing lists that we use and that we CC for every email that we send. And so basically that means that as a member of a team, everything you, any email that you send about whatever you're working on, you generally CC a list. And it's used in a way that is interesting because other people that are not necessarily, so it's useful within the team and also other people outside of the team can subscribe to that list and just hear, I mean, to get updates about what's happening and get a good sense of what the team is doing through the emails that are communicate among and with the team. And so it doesn't mean that kind of some people— sorry, the nice property that it gave is that within the engineering org team is that for any pair of engineers sending an email, there would exist a third engineer that would read the two emails. That doesn't mean that somebody somewhere was reading all the emails. I mean, it doesn't mean that the mailing lists were a partition of the engineering org. There was a lot of overlap. But it means that for any pair of emails, somebody would read those two emails. And so it was kind of ingrained in the culture at the time that if you saw that two engineers that are not necessarily working on the same thing kind of diverge in some way or were saying something that was slightly contradictory, you would just reach out to them and say, hey guys, you said this, you said that. Maybe you should talk together because it's seems to be quite another line there. And so that creates kind of a long-range attraction among the engineering org, right? Because if you kind of diverging at remote outskirts of the org, somebody will try to pull you towards the org. And finally, something that I found always real and true for Stripe, and it's still true today, is that we have a clearly stated mission and a pretty simple product to relate to as an engineer. Basically, the vision for Stripe is pretty straightforward. We want to build— we want to make it as seamless as possible for any merchants in any country to accept money from any customer in any country and maybe pay out some funds to a service provider in any country as well. So we want to create kind of that massive platform of money movement that works everywhere. And so as an engineer, you see that your— our API is kind of the abstractions of those money movements. And then the next, you quickly realize that there's a massive 3-dimensional matrix of country of the merchant, payment method, and payout method. And Stripe started with one box colored, which was US credit card ACH. And as we grow globally, we really kind of feel the need of coloring that matrix all over the place so that we really create that big global infrastructure. And so it's really easy for an engineer to see where we're going, what are the steps required there, what are the next steps. They're pretty easy to, to, to, to intuit. And so that created kind of a very clear alignment of all engineers. And so the magic thing is that if you take local separation, long-range attraction, and alignment, these are exactly the three characteristics of flocking behavior algorithms. So Flocking is like the behavior of birds or fish self-organizing themselves to go in a direction and avoiding obstacles and stuff. And so if you want to simulate that in a computer, what you use is those 3 things. You let some agent do local exploration, long-range interactions, and alignment, and then magically you simulate birds and fish. So in 2015, what the Stripe engineering org was, was kind of a bunch of fish self-organized and trying to find code to write. And the funny part is that it worked incredibly well. And we were really able to produce a lot of stuff with little overhead and very efficiently. So it was kind of a— I think that's an interesting perspective for a bunch of startups that are probably smaller than where we were at that time. And obviously, that unfortunately doesn't scale as we grow. I think the first and maybe the only aspect that broke is the long-range traction. Which means that circa 200 engineers, I would say, I think there was no longer somebody really— I mean, for any pair of emails sent, there was no longer somebody that existed to read the two emails. And so as soon— in a computer simulation, if you remove one of those criteria, the flock kind of disaggregates and becomes like a big mess. And so we became a big mess in some way. And naturally what we did is that we spun up an engineering organization to try to reorganize all of that. So I'm not going to dive into the details of each of those processes involved in spinning up an engineering organization, and I'm happy to answer questions on any of them. But I think what you go through as you build your engineering organization is really that you hire a bunch of people, you set up, as they mentioned, you set up a ladder. Know that you have a ladder. You can put managers that can relate people to ladders. And then you do a bunch of planning as an organization. And then you look back retrospectively and you say, eh, it worked kind of OK, but maybe not as great. And so you do a reorg. And then you execute your reorg and you continue from the start. You start hiring. You change the ladder. You hire a bunch of managers. And you keep planning. I think I went through 4 reorgs that involve my team directly. So it's maybe 1.2 reorg a year or something like that. And I think so one thing that I want to share to conclude is a tool that I— maybe a framework that I find interesting and you can use at a company level or even at a team level that is based on two very simple concepts. And the concepts are the following. Whatever the engineering org that you consider, I think that the maximal useful output of that organization is by construction and necessarily a concave curve. Meaning that as you pull people in an org, it becomes more coupled, more hard— harder to organize. And so the— you have a kind of a diminishing return of the additional people that you add to the org. The next engineer that's going to add will bring slightly little useful output to the org. It's not a critique of those poor engineers that are joining here. They have nothing wrong. It's just that we're humans and that's how we work. And the other thing that you can, like, see in engineering orgs as well is that if you consider a system that a team builds or even a product that a company builds, The minimal useful output to sustain the growth of that system is a convex curve, meaning that the bigger the system, the harder, the more complex it is. That's obvious. And the more complex it is, the harder the effort is to sustain its growth. If you think about a company and its product, the bigger and the more successful your product, the more customers you have and the more ask you have to maintain their own growth. And so you have to respond to their ask first to maintain that growth. And so the minimal useful output necessary to sustain growth of a system is a convex curve. And so if you take a concave curve and a convex curve that's all starting zero, the bad news is that they cross somewhere. And so, I mean, whatever the shape, right? I'm not saying that Y Combinator has a shape or another. It's just true. It's just a fact. They cross somewhere. And that Place is what I call the innovation coffin corner of engineering management. It's a pretty sad corner to be in, but you all get there at some point. And so the idea is that as an engineer, you never can go above the green curve because that's not possible. But you can certainly go on the right of the orange curve, which means that you're just like lagging behind the needs of your own product, or you're just lagging behind the need of your own architecture that you're maintaining. And once you get on the right of the orange curve, what you're going to do as an eng org is that you're going to reorganize and try to move back the org, change the shape of those curves a little bit such that you're back on the left of the orange curve. And as a company grows, as a team grows, as anything grows, you're generally going to take a journey from here to here. You'll probably go across here like this, but you always end up like around here. Around that corner. And once you're there, it's very hard to— I mean, it's very hard to realize that you're only fighting against your own growth, and you forget that you've lost any useful outputs to do innovation. And the main takeaway from that is that if you think about— and it's kind of a praise to startups— if you think about this, as a large company, you necessarily end up around there and you reorganize yourself. And it's not a fatality because you still have ways to recreate innovation, basically you can say, "Hey, you, you, and you, you go start on a new project." And that way you regenerate a small team of 3 people that starts from here. And so they have a lot of cycles to do innovation, which is great. But the really interesting takeaway is that innovation creation in large organization is a reactive process. And on the contrary, in a startup where you're generally around here, the innovation generation is an organic process. Because everybody— the product is not used that much and there's a lot of smart people together. And so you have a lot of free cycle to innovate. And so your innovation will come out from the organization naturally. And so I think that was kind of an interesting perspective to share today and a useful framework to use when you think about your own team. It might apply to 3 people as well as it applies to Stripe. Well, where we have 500 people, 1,000 people. And so This is all I had for you today. I'm Stan at Stripe, and I'm happy to answer any questions. And if you have questions afterwards, feel free to send me an email as well. Because everybody is plugging stuff for their company, I've got interesting news which is fresh from last week, which is that Stripe is hiring engineering managers and engineers in Europe. So if you're interested in joining Stripe as well, We are now hiring in Europe, which is kind of a pretty new thing. And so feel free to shoot me an email as well. Thank you. So thank you very much. Really interesting talk. Do you have any questions to ask Stanislas? Yes. Got one question about when you were 80. Were you just hiring senior devs and how were you going with junior devs and onboarding them and making them efficient right away and trustful right away? I think the 21st person at Stripe were out of school. So we were only people— I mean, when I joined, I was not out of school and there were some senior-ish people, but I was kind of among the most senior yet I had maybe 4 years of experience. And everybody at Stripe was out of school, basically. I think it's not a question of experience. It's, we had that luck of having those self-organizing forces for us. And it's a question of, yeah, being good enough and willing to do the thing. And that trust also was really important. It's hard to trust somebody new. It's very hard. But if it's really in your culture, it becomes easy. And then you've you've got a whole bunch of possibilities that opens to you. So it's not a good answer, but— Can you talk about your toolchain? Our toolchain at Stripe? Yeah. Yeah, we are kind of a— so Stripe was started officially 7 years ago or something like that. And so back in the days was Ruby and Mongo. And so we built a lot of tooling around those two technologies, which means we basically rewrote as much of code on top of them than the code needed to build, to conceive those technologies, I think. Ruby is interesting, especially at 400 engineers. It's a pretty unsafe language. And so you need to build a lot of tooling, probably some static type checking. That runs asynchronously and to ensure some form of safety, not a great safety, but some form of safety such that we can collaborate together as engineers. And Mongo has been, I think, really beneficial in the past from its flexibility. It's created a lot of challenge for kind of storage teams to scale that at our scale. But it's still working, I mean, it's still like operating pretty well. I don't know if that answers some of your questions. And so yeah, basically as a developer, your journey is that you create a PR. So we have a monolith of Ruby code. We have some of the repositories, but most of the code happens in Ruby in a monolith. So you basically create a PR on that monolith. You've got a pretty lengthy Jenkins job that runs a shit ton of tests because Ruby is unsafe. We compensate naturally in the early days by testing a lot. We don't do that much test, unit test. We do mostly functional test. Basically, you run a kind of a small version of the API during, in your test, and you try functional stuff that goes end to end. And so we have a lot of them. They take a lot of time to run then for that reasons. And so our integration time is pretty slow, which is a little bit of a pain as a developer actually. And then the deployment is pretty manual, still as of today. Basically, as an engineer, you're supposed to deploy yourself all the changes that you merge. We have some procedures and some tooling to help with that process, but it's still pretty artisanal, actually. I hope that answers some aspects of the question. Another question, yes. You said you would send emails around a distribution list. You don't use tools like Slack or something to have channels to to make that process easier? So we do, we do, we do, we do use Slack pretty extensively. I think it serves a different purpose. It serves the— if you have a team channel in Slack, the information is pretty transient. And so if you are among the team, you'll get access to that information because you're pretty attentive to your own team channel. If you are not part of the team, you're probably gonna miss a ton of information. So I think it serves the purpose of that asynchronous information flow that you can get from monitoring the team. I think also we had a very particular, we do still have a very particular email culture. We like to sometimes, pretty often, write pretty nicely conceived lengthy email to ask pretty precise question or share pretty detailed notes of meetings. And that's how the information circulates within the company. And I think it serves a slightly different purpose than Slack. Slack is much more instantaneous, and I think you cannot do away with just Slack. You need some form of asynchronous communication, especially for the communication beyond your team. That's how I would analyze that. Some people I have said, I have heard use Confluence. We use Confluence as well, but the editor is so shitty that we're sticking with email. Thank you. I agree with that. Last sentence. Sorry, Confiance. Thank you very much. Thanks.
More from Stanislas
AMA with Stanislas Polu, Co-Founder of Dust: Revolutionising Tech with AI Agents

Getting the Most From AI With Multiple Custom Agents ft Dust’s Gabriel Hubert and Stanislas Polu
Getting the Most From AI With Multiple Custom Agents ft Dust’s Gabriel Hubert and Stanislas Polu
dotAI 2024 - Stanislas Polu - LLMs reasoning and agentic capabilities over time
No GPU Before PMF // Stanislas Polu // AI in Production Conference Lightning Talk
[EXTRAIT] Décryptage du fonctionnement d’un LLM en 5min - par Stanislas Polu, CEO de Dust
Qdrant x Dust: How Vector Search helps make work work better - Stan Polu | Vector Space Talk #010