Stanislas Polu (Dust) and Roxanne Varza (Station F) fireside chat | Stripe AI Day—Paris
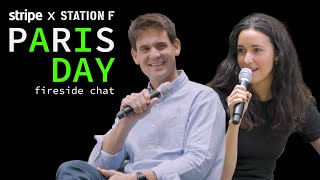
Stanislas Polu, co-founder of Dust, explains why the company pivoted from a developer platform to a team productivity tool using internal company data. Based in France for its math talent and CIFRE research pipeline, Dust targets tech firms of 100-500 employees and uses frontier models like GPT-4 over open-source alternatives to avoid hallucination issues.
Chapters
Stan, great to have you with us.
Thank you.
You told me I could ask you anything for this discussion.
We didn't prepare anything, so you can go wild.
Excellent. I will do just that. First of all, great demo. That was incredible. Where's Gabriel? That was amazing. Can you guys just applaud one more time? I loved it. That was like the first time I've seen anything—
I think it's a 75% British accent.
Yeah, it's true. No, that's like the first time we've seen anything from Dust because everyone knows you guys have been around. Nobody has really known what you guys have been up to. So now we're seeing it. Nobody asked this, but who's using the product today?
So we're working with, as Gabriel said, with a few design partners in Paris, between 100 and 500 people, tech companies, 3 or 4 of them. I mean, the list is not that long. So you have a good idea from there.
All right. So still kind of keeping it secret. But I want to also know the backstory to this. I know a little bit about the backstory, but definitely not enough. And I'm imagining other people here don't know enough. You were at Stripe. Well, you had a company. It was acquired by Stripe. You were at Stripe. You went to OpenAI. How did you end up doing this today? At what point did you say, I need to build this?
Yeah, I think the original motivation is one year ago, seeing that those— so it was pre-ChatGPT. Seeing that those models are already extremely powerful. They're available through an API. At the time, GPT-3 was available through the API. And realizing at the same time that not many people were actually using them. So as much a product problem as it was a research problem. Of course, the research problem is still a big problem. You want to make them better. But the fact that it was— those models were already at the level of ChatGPT today and nobody was realizing how useful they can be. And so that meant that there was kind of a big product issue to be solved. That was kind of a triggering motivation to go explore that.
So you could have gone so many different ways. What brought you to this?
Yeah, we started very differently. The first iteration of Dust was more developer-focused. It was a platform to create LLM apps. So by LLM app, I mean chaining of calls to models and external APIs. And I think it created a lot of interest from developers. But the question is, why didn't we stick with that, I guess, which is an interesting one. And at the same time, LangChain was popping up, and LangChain is probably much more well-known than Dust was, even if we could make a long argument of why the Dust of the time was much better than LangChain. But I think working on that for something like 6 months my gut feeling was that it would be very hard to capture long-term value from a product like that. Basically, if you think about developer tools that create value for developers, a good example is obviously GitHub. And in GitHub, the one thing that hooks you to the platform is the pull request. The pull request is kind of the social aspect on top of Git. Where you comment and you can review code, et cetera, et cetera. And when you see Git and you see GitHub, you see exactly where the value accrues. And I think in the world of infra tooling and developer tooling on top of LLMs, I couldn't quite see such a strong value creation or value proposition. And so there was always the expectation that people would probably graduate from the platform. And I think that's what, to some extent, we kind of see for our users that have been using us in the past, and also LangChain. LangChain has been great for demos, but it's a much harder question on whether you want to stay on such a framework when you go to production. When you go to production, your use case kind of becomes more specific, more silent, and so you generally want to just remove the framework and go towards the role model. So that's what is kind of a main fear that's led us to reinvent ourselves as Gabriel joined the project.
Super. All that in just one year. That's pretty incredible. And you guys, I mean, we're seeing this trend, kind of trend, of companies deciding to come from abroad and base themselves here. We've seen that with Poolside. I don't know if we can say we saw that with Mistral, but obviously Mistral's here, which is awesome. But you guys actually were in the Bay Area, both of you. You picked up and you came here to build the company. Tell me what that's about.
So it's not entirely true.
Oh, it's not true.
All right. I was at OpenAI, but I was working remotely from France. So technically, I was physically in France, even if my brain was maybe there. And Gabriel was at Alan, so pure French company. We were both at Stripe in the US before. But so it was still a very clear question on whether we wanted to to build a company there, on whether we wanted to build a company as a French or US top co. And I think for us there's many factors. The fact that we're physically present in France made just sense to build a French top co and build a French team. It's just simpler. We live in a world where I think investors do not care that much anymore about where the company is. There's a few countries where it's not true, but I think France is past that stage for good, which is great. And at the same time, there's an incredible talent pool in Paris. Whether it's on the product engineering side or on the research side, the talent pool is pretty deep and much less competitive than in the US. So I think it's a much favorable, much more favorable place to start a a startup, especially in AI.
Okay, so everyone talks about talent, talent, AI talent. You lived in the US, you studied in the US, you studied at Stanford, you studied at Polytechnique. Tell me what is so incredible about our talent here? What are they teaching here that they're not teaching somewhere else? What's this thing about talent?
So, I mean, there's two things. There's the French talent, which is global and is in the US as well. And I think we've very well recognized due to the way we've been taught during our studies. So there's a bunch of engineering schools, universities in French with a very strong mathematical background that's being indicated to everyone. And so French talent has been super well recognized in the AI world because of that kind of mass e-influence compared to the US or Britain. Um, and then there's the talent that is in Paris if you want to start a company in Paris. And there, uh, I have a theory about how we came to have, uh, a very deep AI research talent pool. And my hypothesis is the, uh, match made in heaven between the CIFRE system and the GAFA. Basically, it kind of created a large number of young researchers that were embedded during their PhDs inside of GAFA with access to very large clusters. So they kind of did their PhD with access to resources, which led them to become leaders of the AI research community. And so that is incredible because it's funny that it is the SIFR French system meeting the basically Facebook Meta AI and DeepMind because these are the two big labs in Paris. That created like a very large group of very strong and internationally recognized researchers.
Incredible. So it's the research, the research element that's really strong.
I think it's the research element for that talent pool. And then we've gone from— so we started our first company in Paris 10 years ago. I think the talent pool for product engineering, let's call it that way, kind of a full-stack type of engineers or engineers that are very good at building good products, was almost nonexistent 10 years ago. And now we've seen a bunch of very nice scaled-up and large companies going through that phase, and that created a talent pool, independent of research, but also present here. For us, it's been incredibly easy to hire, which is great. If we had wanted to build the same team that we have today— there are 8 of us, it's not that big— but if we had wanted to build build the same team in the US, in San Francisco, it would have been a nightmare. Total nightmare, I think. I'm pretty sure.
Interesting. And so obviously, I think everyone here agrees with you on the talent piece. What are the other strengths of this ecosystem for AI? What do you feel that France really has to offer for somebody that would be coming from abroad?
So that's a more complex question. So other than talent—
That's it? That's all we got?
Yeah. I think it's basically still a work in progress. I mean, the government is working hard on trying to create structural reforms that will help on that front. If you think about it today, if you're building a startup where you're going to have to do R&D. So I think the talent pool is really good. But if you want to use GPUs, you don't have any— you don't have a lot of incentives to do that in France because you generally don't want to operate those GPUs yourself. If you were to be able to operate them, then you would have the CIR, which would kick in, which is awesome. But I mean, nobody wants to operate GPUs, right? Not even OpenAI wants to operate GPUs. And so if you fall back to using GPUs through a cloud provider, you don't have that yet. So hopefully we'll get into a world where even that will be incentivized by France for you to create a company. But they're working out on it.
Okay, super. And what is the main downfall of this ecosystem? What is the one thing we have to fix here?
It depends on which side you are of the research boundary. For us, I don't see that many downfalls. I mean, you always have the kind of, hey, I'm not in SF, I'm not in the known, and everything happens there. But to some extent, a lot of that can be followed on Twitter. I think there is much deeper project here than most of the project that maybe happen in SF right now. And it almost feel like I mean, to me, it feels like being in Paris is a little bit like being in the Silicon Valley of 10 years ago. I mean, being in Silicon Valley, building a startup 10 years ago was contrarian. You were going against the flow. And it was exciting and stuff. And now, working in a startup in Silicon Valley is like the kind of standard way of thinking, basically. And so doing that from Paris is almost like being the Davids going against them, which is extremely exciting and energizing. Then if you, yeah, if you fall, if you fall, so on the product side, I think I don't see that many downfalls. And on the research side, obviously it's access to funding. It's much harder to find a billion dollars here than it is in the US, basically.
Very true. Very true. I love that you picked this contrarian spot to build your company, Stanislas Polu. Before I open it up to questions from everybody else, I just want to ask one last question. You have seen, I mean, you see everything that happens in AI and innovation. What is getting you really excited right now besides DUST? Obviously DUST is the most exciting. What gets you really excited and thrilled besides DUST?
Yeah, nothing in particular right now, but I think what gets me the most excited is the fact that this technology, those raw models that we all have access to through APIs, are still brand new. And we haven't even started scratching, exploring their capabilities in a sense. And so what I think excites me the most is that you don't need to be embedded within DeepMind. You don't need to be embedded within OpenAI to actually push the boundary of what you can do with that technology. I think there's so much that can be done by using the models through API, prompting, orchestrating its use in many different ways. Many of the most interesting papers lately, or last year, have been around that exactly. Yes, it's awesome to go from GPT-3 to GPT-4. It's awesome to go from GPT-4 to GPT-5. But the scaling laws tell us exactly what we're going to get. And it feels like we've been getting even more by doing chain-of-thoughts. We've got even more by doing consensus with chain-of-thoughts, which is just doing more API calls to the same model, but orchestrating how you use that in a different way. And so I'm really excited to see what we'll be able to do with the technology by just prodding it, playing with it. And I think there's still a lot to do.
Super. Well, I imagine you guys have some questions.
Hello.
Yeah.
So my question is about conversational interfaces. So I'm sure you know in human-computer interaction research, they are kind of skeptical about this mode of interaction because there's a higher cognitive charge for the user than interacting with a button. So I would be really interested to know what you think about it, to which extent it's central to LLMs to be conversational.
When we were raising money a couple months ago, whatever, and still now, but we were pitching that the conversational interface is not the the final interface. I agree with that. You can imagine a world where even a simple button click, when the cost of models will go down even more, a simple button click could generate hundreds of calls to a model to do an action and have an instant feedback. You can imagine interfaces that are based on LLMs that react much more intelligently to where the user is, what they want to do, who they are, etc., etc. So I completely buy the fact that the conversational API is kind of a, to me, the conversational API is like the Pong, is to LLM what Pong is to gaming, right? And so what we really want is the Doom 2, what we want is the Quake, what we want is the Civilization 3, like crazy shit where you're doing multiplayer and all the kind of crazy stuff happen. That we want for sure. But the train left the station a bit early. And so today people are accustomed to conversational API to interact with those models. So it's a bit hard for us as an example, it's a bit hard to try to backtrack from that. So it's a forced starting point, but completely agreed that there's probably much more to be explored. And if you're building a product that integrates AI inside an existing product, maybe there, the opportunity to create newer interfaces is even stronger. It's when you interact directly with agents. If you don't show a chat to begin with, people are going to be like, eh.
All right, another question.
Just a question, and you're an expert in this, so I value your feedback, but it feels like a lot of the cool models that are being released today are open source. So what's your take on integrating third-party technologies from private companies versus implementing open source models that are being released?
So they're cool because you can hack on them and you see a lot of excitement around that. The reason why we stick with front— let's call them frontier models like GPT-4 and Claude 2 is simply because when you're in the productivity setup and you have a retrieval-based answer that's getting generated, as an example, going from even GPT-3.5 Turbo to GPT-4 is a game changer. GPT-3.5 Turbo is a great model by open source standards, but it hallucinates a lot. And so if you're really going for productivity, you still kind of in the current state of affairs, you still need to go for the largest models. Obviously, it'll hopefully converge at some point, but right now I don't think we're quite there. It's super exciting to be able to run a 7 billion model on your laptop, But if you ask something slightly complex about data coming from a company to a 7B model, it'll just spew bullshit. And so I think we need that kind of convergence to happen for open source models to really be useful when you need a bit of reasoning, basically.
If I can ask just a short, small question, you mentioned Pong versus an Civilization or Doom. Building on the metaphor, if conversational AI is Pong, what is Doom 2?
It's up to us to figure it out, I guess.
Thanks.
My question is more about the use case. It's, for example, I have a website, I'm a SaaS company or another one, and I want to analyze my website. Do I need to upload my whole content? Or I don't know if it's possible. Also, first of all, is it possible to make it? And if it's possible, how? Yeah, so right now we've been focusing on internal data first. The reason why is because we're really excited about helping the productivity of the knowledge worker or the people working as teams. If we had focused on external data first, naturally the fit becomes something like externally facing teams. So I think that's something that we will want to have as a capability, but it's not necessarily our core focus. Because the reason why we've, we've been excited about like internal data as well is because if you focus on a particular use case like customer support, which is kind of where that your question kind of leads a little bit, then it's gonna be super hard to fight against incumbents. I mean, Salesforce, Intercom, all of that, they all have a team of 20 people working on that. Maybe they won't go as fast as a startup, but their distribution is gonna be massive. And so the moment they figure it out, and it won't take a lot of time because at the end of the day, this technology is not that hard to use, you're gonna be faced in a distribution fight with them. And so that's gonna be a tough one to crack. Unless you have something very new. About. Well, thanks.
Yes, right here. Thanks. So I was a bit curious about how you see your defensibility in maybe 2 years. How is LLM growing and so on?
Yeah, that's obviously an interesting question. To be honest, we don't try to think too much about it because if you think Who do we want to address with that product? It's pretty simple. We want to address tech-ish companies because our stack, the stack we target, is a better fit for tech companies than old 5,000-people companies. Stripe is fine. Stripe is not old. And they run on that stack. But, and if you think about tech companies where the management wants to roll those models to their employees because they believe it's gonna be a change, a game changer in terms of productivity. If you think about that market, it's a humongous market already. So obviously, there's a lot of competition already from startups. There's gonna be competition from platforms that, on which business runs almost entirely. So if you think about Microsoft, when you run on Microsoft, generally you run on Microsoft only. You have Teams, you have whatever, Outlook, blah, blah, blah. When you run on Google, most of the time, if you're a tech company, you also have Notion, you also have Slack. So for all those companies that do not run on a single infrastructure, I think there's gonna be a need to have access to both Slack and Google Drive. So there, there's probably a long time before we'll see competition from, let's say, Google on our specific use case. Because if you have Drive, but you don't have Notion, and you don't have Slack, it kind of sucks. And so I think there's going to be a lot of competition. There's a lot of competition from startups. But at the same time, the market is so, so, so, so, so, so deep that our main problem for us today is really try to find the product that clicks with our users. And even if there are 5 other startups doing the same time in the same markets, we won't see each other basically. And today we haven't seen any case of people we talk to and they say, "Ah, we're comparing you with that other product." Because that market is so big. So that's a problem basically for future us. I think I agree that it's a very important problem, but we try to sequence them in a way that is not too crazy.
Super. That's all the time we have. Thank you so much, Stan. Thank you so much. Thank you.
More from Stanislas
AMA with Stanislas Polu, Co-Founder of Dust: Revolutionising Tech with AI Agents

Getting the Most From AI With Multiple Custom Agents ft Dust’s Gabriel Hubert and Stanislas Polu
Getting the Most From AI With Multiple Custom Agents ft Dust’s Gabriel Hubert and Stanislas Polu
dotAI 2024 - Stanislas Polu - LLMs reasoning and agentic capabilities over time
No GPU Before PMF // Stanislas Polu // AI in Production Conference Lightning Talk
[EXTRAIT] Décryptage du fonctionnement d’un LLM en 5min - par Stanislas Polu, CEO de Dust
Qdrant x Dust: How Vector Search helps make work work better - Stan Polu | Vector Space Talk #010