A CTO explains why Opus 5 broke their production systems. The model regresses on 80% of use cases that worked in Opus 4.8, caused server downtime during script execution, and lacks documentation to help teams adapt. They now trust GPT-5.6 Sol ten times more.
Chapters
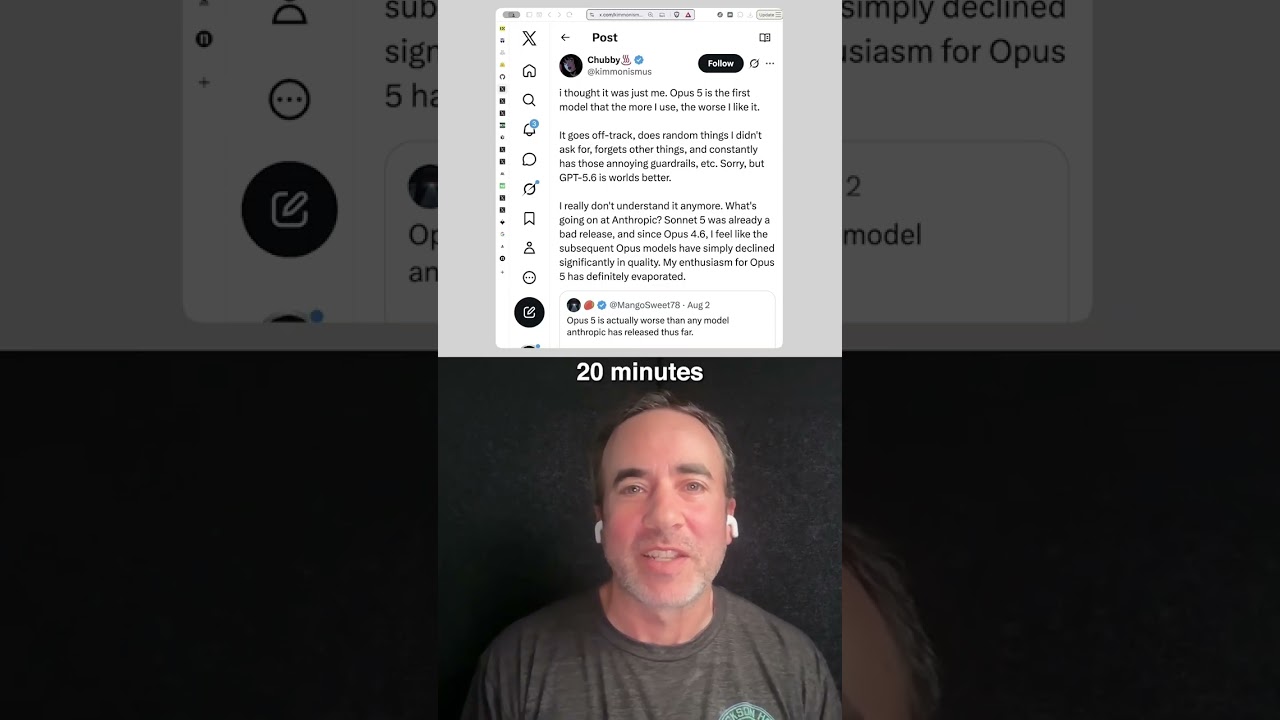
Jonathan, what do you think of the latest Opus 5 from a CTO perspective, given all the media around it? It's kind of like a love-hate relationship. I've been using it and testing it more in different cases and seeing how it performs with some of these changes, like the concise output and some of the system prompt updates we made. For the most part, it's probably about on par, maybe a little bit worse than Opus 4.8. The problem is you just never know when it's going to make a mistake and it's not predictable, like what kind of guardrails you should put around it. And Almost every session I have, I've become comfortable with like, oh, it's going to tell me at the end of session, it's like broke something and fixed it. And like yesterday, it like took down one of our servers and like was trying to run a script on it. It's like, I thought I could run it on there, but then it took the server down. So then I put the server back up and I'm like, okay, I could see the downtime of like 20 minutes that we had. It's like, okay, no big deal. We got through this. We got the job done, but it's just always taking it like a divergent turn like that, even with these fixes. And I think like what Boris had posted here, he's like, hey, don't you guys know that Opus 5 is like really good at these specific tasks over here? And the problem is that, you know, as a user of Claude Code, you You're using Opus 4.8, you've become accustomed to what it's good at. And then they release Opus 5 and then it breaks 80% and regresses 80% of those use cases and it's better on 20% of the use cases. And there's no instruction book. And like, you've got to like take your time, your tokens, and you got to figure this out. And that's like a really frustrating thing as a user. And I'd say overall, I'm leaning on Codex a lot more. Like if I know I need to get something done consistently, GPT-5.6 Sol is a great model. It can delegate to Terra and Luna really effectively. I would say, like, I trust GPT-5.6 Sol 10 times more than I trust Opus 5 to get the work done. Like, they really need to consider, like, I'm using your product, I'm using Cloud Code, I'm on to Opus 4.8, what's going to be my experience with that change to Opus 5? They don't seem to have the capability of putting themselves in customers' shoes and taking that data and understanding how we're going to be affected. That's really concerning. That is definitely a trust issue that we're all going to have with Anthropic as time goes on.