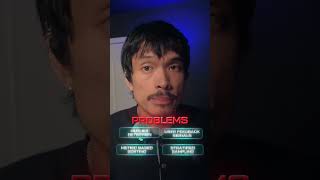
A speaker explains how randomly reviewing AI traces wastes time and offers better methods: outlier detection, user feedback signals, metric-based sorting, and stratified sampling to find the problems that actually matter.
Are you an AI builder struggling to bootstrap an evals process and you're just overwhelmed with the amount of production traces you have to review? It can be really cumbersome to review traces randomly, especially when most traces don't have an error. This is one of the common issues when people get into evals and rigorous error analysis. There are some sampling strategies to help you find traces that are more likely to reveal your problems. Number one is outlier detection. Sort by any sort of metric response length latency tool calls. Number two user feedback signals Prioritize the traces with negative feedback. Look at the support cases or tickets where the users are showing some sort of emotionality. Number three metric based sorting so review both your high and low scores. Number four is stratified sampling so grouping your traces by key dimensions User type feature query category so that's how you efficiently sample production traces for review to bootstrap your evals process as quickly as possible.