Robert Ta reviews OX Alpha, a new free multimodal model with a 1 million-token context window that claims not to train on user data. In benchmarks against Fable 5 and others, OX Alpha wins on several tasks but notably skips testing against Opus 5, raising questions about how it actually performs.
Chapters
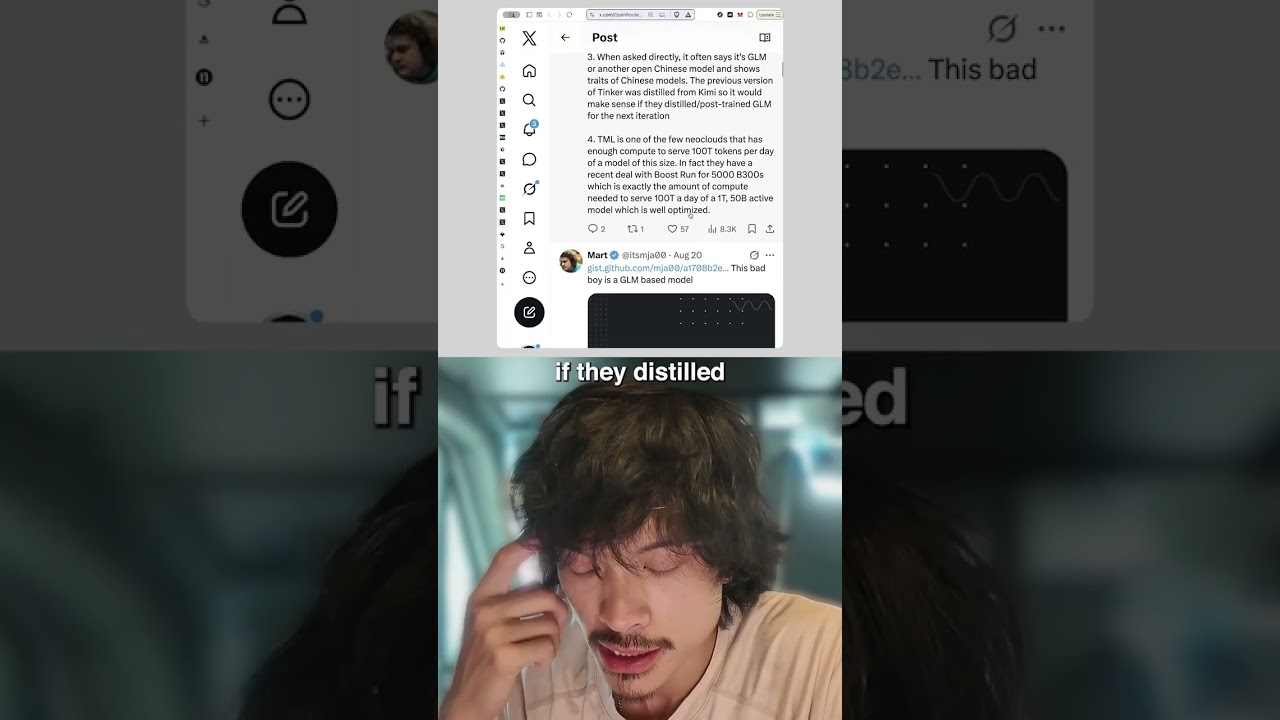
New stealth model drops, OX Alpha. OX Alpha is a frontier model built for efficient coding, sustained agentic work, and real-world production use. 1 million token context window, text, image, and video input. Notes for this stealth model, it is free. This time the provider does not train on your prompts or completions. To me, that's a signal from market, which is people are hearing, we want to keep our IP, our IP. I'm a business. I'm buying your intelligence. I want to keep my IP, my IP. And you saw that botch with the Fable 5 release where they kind of went against their zero data retention deals by collecting data under the guise of safety. And it might be safety. I don't know. They have more data points that they're maybe not showing the public, but that's what I see. Raghav says, this is probably Thinking Machines Labs' next version of Tinker. It's not a Chinese model as it speaks freely about Tiananmen Massacre and Taiwan. Tinker is one of the few large open models, which is highly multimodal, including video input. When asked directly, it often says it's GLM or another open Chinese model and shows traits of Chinese models. A previous version of Tinker was distilled from Kimmy, so it would make sense if they distilled post-trained GLM for the next iteration. OX or OxAlpha benchmarks against the competition. This is how it looks at a high level. The ones it's bad at: SCC bounded memory spilling, Vulture persistent analysis catch. I would say nobody's really solved memory, but against Fable 5. 5 tasks, OxAlpha had the edge. 3, both solved cleanly. 1, Stable-5 had the edge. 1, neither solved. Against GLM-5, 5 tasks, OxAlpha had the edge. 3, both solved cleanly. 1, GLM-5 had the edge. Against 5.6 SOL, 7 tasks, OxAlpha had the edge. And 1, both solved cleanly. 2, GPT-5 had the edge. And versus Groq-4, 4 tasks, OxAlpha had the edge. 4, both solved cleanly. And 2, Groq-4 had the edge. Very interesting to see that they don't even bother benchmarking against OpenSpy in their flagship article here. They probably think it's so crap. Like we don't even need to benchmark against that crap anymore. Let's just benchmark against the other ones.