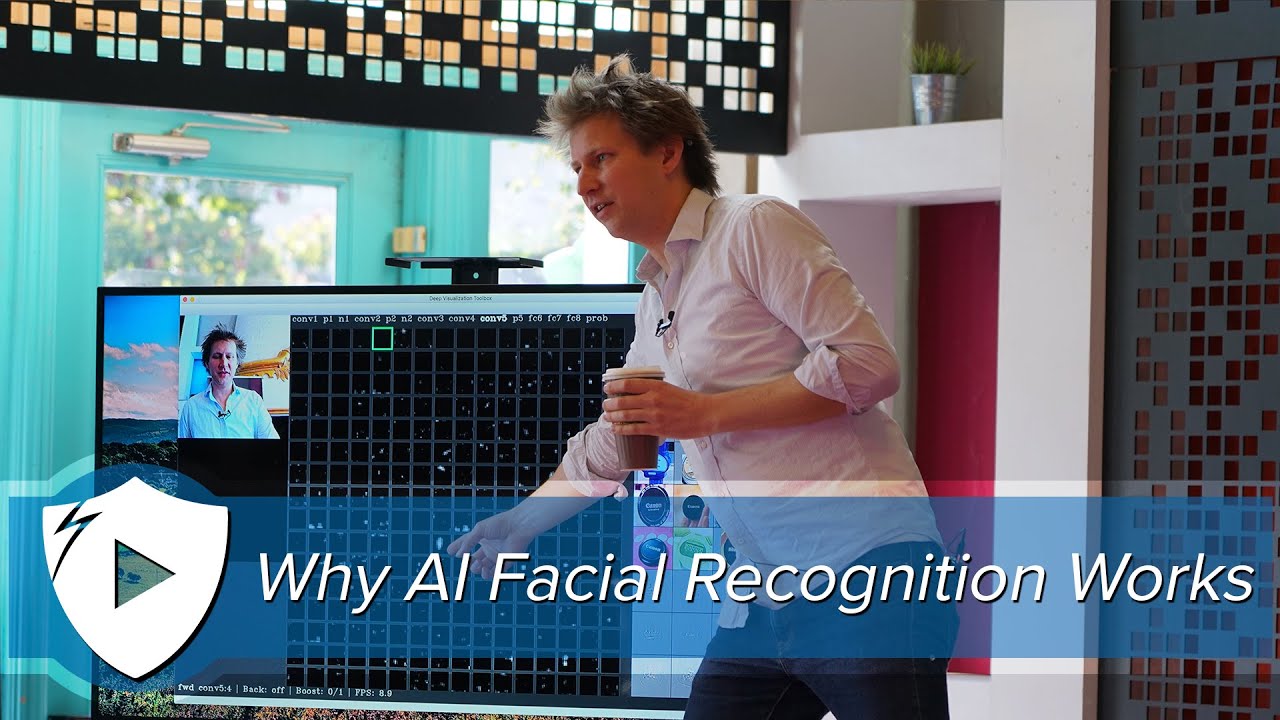
Jason Yosinski demonstrates how neural networks trained on image recognition develop internal neurons that detect faces, seatbelts, cowboy hats, and other concepts without explicit labels. A face detector emerges because recognizing faces helps the network spot seatbelts, which often appear as gray stripes beneath faces.
Chapters
If it somehow learns to detect human faces, and then it sees a gray stripe underneath a human face in the right proportions, the correct size of stripe compared to the face, then maybe that's a seatbelt. There's other categories too, like a cowboy hat. So the network learns to recognize cowboy hats. The point is the network learns the concept of human faces simply because it makes it better at its job, which is recognizing other categories. OK, so let's— oh, some other fun stuff. This is the first layer, like I said. Simple patterns. These are all very simple patterns. I'll show you some more complicated patterns. So up here in the 5th layer— okay, so here's the 5th convolutional layer. By this layer, the network learns some pretty abstract stuff. So in fact, there's a few pattern detectors here that are for faces. I can scroll down to one of my favorites here. It's this guy here. Cool. So that should be a face detector. Can you see it, like, following my face left and right? Sort of? Yeah? I can point it at you guys. We can see if it'll— if you have faces too. Okay. So first thing, if it's blurry, it doesn't work very well. If the faces are tiny— so here you can see to the network, all your faces in the back are quite small. So it's actually not really firing there at all. But if we point it to people whose faces are bigger to the network, we can see it fires for multiple people. A couple of you there. Anyone else want to try? Yeah. Okay. Okay. So it's a face detector. Cool, right? So the question is, why does the network learn a face detector? It could be the answer— the answer could be that we trained it to learn faces. But actually, this network, we never trained it to learn faces. There's no category in ImageNet for humans. So actually, it's kind of weird. Humans are just like background, background to the network. So why would the network learn faces? Well, we did teach it to learn some other categories that are quite human-related. So one of them that I like is seatbelt. Why is seatbelt a category? I don't know. I didn't make the dataset. So think about like in pixel space, Just from an abstract art perspective or whatever, what does a seatbelt look like? A seatbelt. So a seatbelt— imagine I'm wearing a seatbelt and you can see it right here. It's basically like this gray stripe, right? So what happens to the network if it goes around saying every gray stripe is a seatbelt? Well, let's see here. Let's just imagine we had this random picture as input to the network. So how many, like, sort of sideways gray stripes or, like, approximately gray stripes you can see, right? There's, like, some stripe there. There's some stripe there. There's some stripe there and there. Yeah. So if the network goes around saying every, like, gray stripe it sees is a seatbelt, it'll be mostly wrong. On the other hand, if it somehow learns to detect human faces and then it sees a gray stripe, like, underneath a human face in the right proportions, the correct size of stripe compared to the face, then, like, maybe that's a seatbelt. There's other categories too, like a cowboy hat. So the network learns to recognize cowboy hats. Cowboy hats are pretty simple, but, like, a cowboy hat is usually right on top of a human face. The point is the network learns the concept of human faces simply because it makes it better at its job, which is recognizing other categories. All right. We can see— we can find some other fun, fun— Neurons in here. There's one that recognizes text. So does anyone have any simple thing with text on it? Here. Here, here. This is perfect. Okay, good. Okay, so see if you can find the neuron. It's somewhere in here. It'll be responding when you see, like, letters on the screen. See anything? It's not a ton of text. Someone's pointing, but I can't tell where you're pointing. It's all good. So the one I'm thinking of is right here, number 4. So there's not too much text here. In fact, it's just this guy here. Maybe I'll try some— There are so many things that we wrote in these. You wrote— OK. So it's definitely more tuned for printed text than handwritten text. Okay, there you go. There you go. Okay, I'm just going to pause that. Thanks. So again, here's a neuron halfway through this network that's doing something really cool. We have one that detects faces, even though we never told it to detect faces. Now we have one detecting text. Follow-up question, why in the world would it learn to detect text? So it's the same story I told you before about the seatbelt. It turns out there are certain categories in ImageNet, like camera lens, and here, parking meter. So camera lens in particular, what's a camera lens? So in pixel space, kind of looks like camera lenses are mostly just like black circles. Right. So if the network goes around calling every black circle a camera lens, it's going to be mostly wrong because there are lots of circular black things in the world. But if it finds a black circle where there's some text right in the middle, Suddenly black circle plus text equals camera lens. So now by detecting text, it's becoming good at its original job of detecting camera lenses. I think there was a question. Oh. Yeah, come up. Come up. Sure. It's always fun. Like in different talks, I try to find different things. Usually— Anyone from Canadian University of Alberta so we can send a doctor for a physical exam? Yeah, yeah, here, here. Try it. So depending on the talk, it's always fun to try to find something to use for these demos. Is it working? The back. The back. OK. So in the front, you can see this text is kind of responding. I can't see what's at the top. Oh, it says Draper. Yeah, yeah, exactly. On the back, it's relatively more full of text. The more you play around with this, the more you can find out. For example, if you move it too much, it ends up being blurry. And because the text is so small, even a couple pixels of blurriness basically destroys its ability to see. Fortunately, the data set it's trained on is mostly photos that are quite crisp from Flickr and so on. In the most desperate talks, I have to pull out my driver's license or something. So glad we can avoid that. Thank you.