the cost of ultra-fast inference. when a single model copy requires 8 racks of wafers, a baseline de
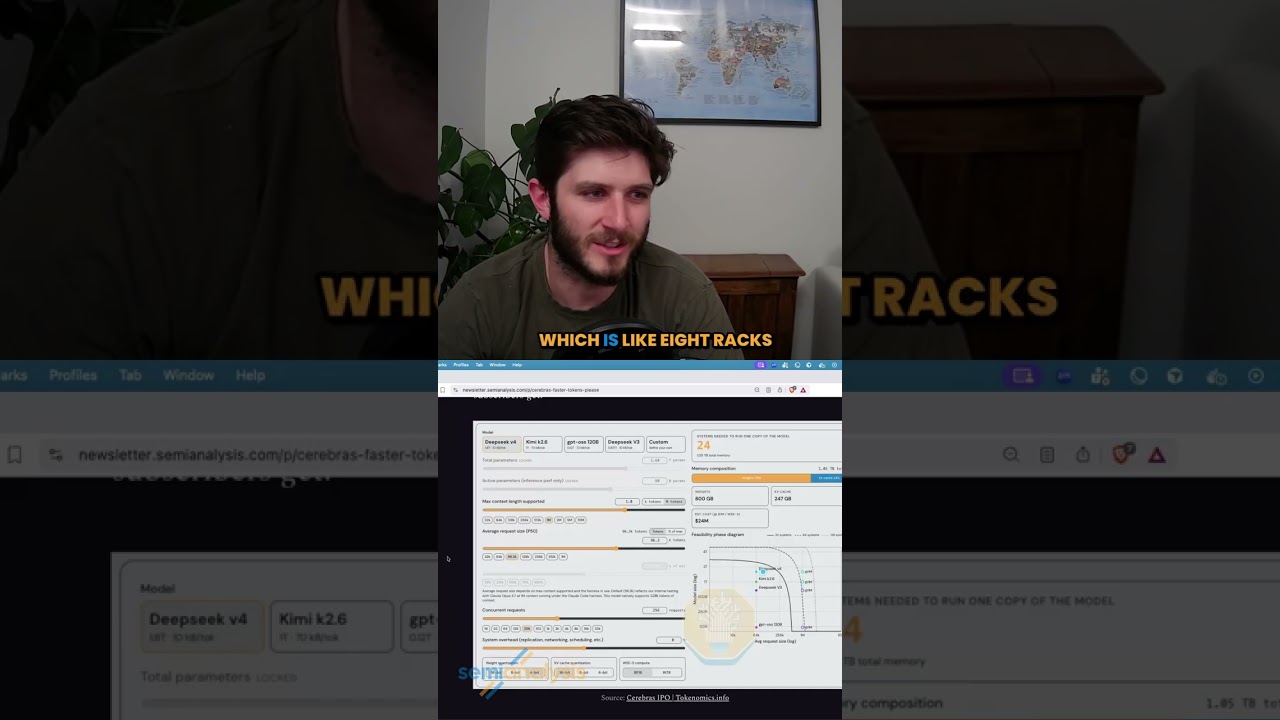
This content was created by Dylan Patel. This content was uploaded by Dylan Patel. This is a YouTube video (title: "the cost of ultra-fast inference. when a single model copy requires 8 racks of wafers, a baseline de", created 2026-05-29) containing a short technical discussion between two speakers (labelled SPEAKER A and SPEAKER B). The speakers compare the capital and deployment costs of running very large language models on wafer-scale systems versus GPU racks. Topics include per-system CapEx (e.g., ~$1M per WSC), resource requirements for supporting 256 concurrent users at million-token contexts using 4-bit weight quantization and 16-bit KV cache (estimated ~24 systems / $24M, or ~8 racks of Cerebras), and a broader estimate that meaningful adoption of wafer technology could require on the order of $100M — versus buying many GV300 racks which would provide more memory and KV cache capacity for multiple model copies. The excerpt is a practical cost and infrastructure trade-off discussion for ultra-fast inference deployments.
Chapters
More from Dylan









"It's like a zombie apocalypse, but you don't know how many waves of zombies are coming."