Jerry Liu, CEO of LlamaIndex, walks through building RAG applications that connect private data like PDFs and APIs to large language models. The core pipeline has three parts: data ingestion, indexing with vector databases, and retrieval. He covers common failure modes and how to evaluate and optimize RAG performance.
Chapters
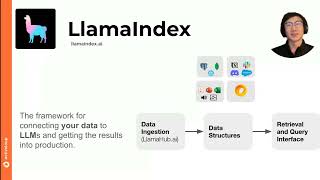
Hi, my name is Jerry Liu, co-founder and CEO of LlamaIndex, and today we'll talk about a developer journey for retrieval augmented generation. So super excited to do this talk today in conjunction with ActiveLoop. Um, that's me. So LlamaIndex, uh, is a data framework for connecting your data to LLMs and getting these results to production. Uh, at a high level, our whole mission is to help you build LLM applications over your own private data, whether you're an individual developer or an enterprise. You start off with some data sources. This can include PDFs, uh, APIs, services that you commonly use like Notion, Slack. It can include databases like structured databases, vector databases. And we want to get all this data into the language model so you can unlock the capabilities of something like ChatGPT over this data. And typically this involves 3 main components. One is data ingestion, loading the data from somewhere. And actually putting it into a storage system. So data structures is the part, uh, where we index, process, and actually embed your data so that it can be retrieved by a language model and retrieval system later on. And of course, the last piece is this retrieval and query interface, where given that the data is processed and stored in something like a vector database like ActiveLoop, we can then perform retrieval, give it fetch relevant context given the user task at hand. And build advanced query interfaces that replicate the magic of ChatGPT, uh, on its own. A quick overview of the agenda today. Uh, we'll first give an overview of what Retrieval Augmented Generation, or RAG, is, uh, plus LlamaIndex. And then we'll talk about the challenges with RAG. What are the failure modes? We'll talk a little bit about how to actually evaluate the performance of your RAG pipeline. And then we'll spend a good chunk of this talk talking about how to optimize your RAG pipeline.