Nvidia CTO Michael Kagan: Scaling Beyond Moore's Law to Million-GPU Clusters
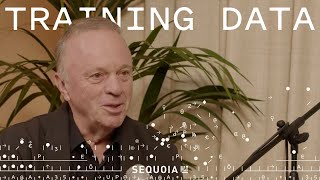
In this interview, Nvidia CTO Michael Kagan explains how Nvidia has moved beyond traditional Moore’s Law scaling by combining accelerated GPU computing with high‑performance networking, a strategy enabled by the 2019 acquisition of Mellanox. He distinguishes between scale‑up (building ever larger multi‑GPU nodes using NVLink/Envelink) and scale‑out (connecting many such nodes into a single data‑center‑wide fabric). Kagan emphasizes that network characteristics—raw bandwidth, low latency, tight jitter distribution, and congestion control—are now the primary performance limiter for AI workloads. He describes the engineering challenges of constructing clusters of 100,000 + GPUs, including component failure rates, power and cooling constraints, and the need for sophisticated software orchestration. The conversation also covers the differing demands of training versus inference (compute‑heavy pre‑fill vs. memory‑heavy decode), the emergence of specialized GPU SKUs, and the importance of cross‑data‑center scaling where speed‑of‑light latency and congestion become critical. Kagan outlines Nvidia’s partnership with Intel to fuse general‑purpose (Von Neumann) and accelerated computing, and shares a broader vision of gigawatt‑scale, liquid‑cooled data centers, speculative future technologies (optical interconnects, AI‑driven physics discovery), and a “win‑win” cultural philosophy that has driven Nvidia’s 45× market‑cap growth since the Mellanox merger.
Chapters
One of the interesting things about Nvidia is the culture of win win. We are not after taking a bigger piece of existing pie. We are after baking our bigger pie for everybody. And our success is our customer success. Our success is not the failure of our competition. And I think fusing together conventional computing, Von Neumann machines and accelerated computing that provide with Nvidia, it actually gives Nvidia and Intel channels to the market or expanding the market and serving the markets that otherwise was more challenging.
Foreign.
We are delighted to hear today from one of the legends of the semiconductor industry, Michael Coggan, the CTO of Nvidia. Michael was formerly chief architect at intel and then co founder and CTO of Mellanox, which Nvidia acquired for $7 billion in March 2019. In the time since, Michael has been a major driver of Nvidia's dominance as the AI compute platform, in large part due to the role of Mellanox and Interconnect in driving chips beyond Moore's law. The AI race is ultimately a silicon race to squeeze the most intelligence possible out of each unit of silicon. And Michael takes us down a journey about how the compute frontier has evolved from squeezing more transistors onto a single chip to bringing together thousands and hundreds of thousands of chips into a single fabric connected by networking or an AI data center. Michael has been driving the compute frontier forward for more than four decades and we're honored to have him on today's show.
Okay, we're here with Michael Kagan, the CTO of Nvidia, currently the world's most valuable company. Michael, thank you for joining us.
Thank you. My pleasure.
So I thought where we could start. Our partner Sean likes to make the case about every six months that Nvidia would not be Nvidia without Mellanox. Mellanox is a company that you co founded some 25 years ago and have been a part of through this day. So can you kind of paint that picture for us? Why is it that the Mellanox acquisition was so critical to Nvidia?
You know, there is a huge transition in the world in terms of computing and need for computing, and it grows, grows exponentially. And one of the things that we usually estimate linearly, but the world was exponential and exponential growth now is actually accelerated. It used to be like Moore Law, which is basic silicon, and it was twice every other year. And regardless, the discussion that Moore Law in terms of physics is not quite running anymore once the AI kicked in, which was in the 2010, 2011 and kicked in when GPU from graphic processing unit became general processing unit, actually where it's running. Workloads were the first time the AI workload was run on the gpu. Taking advantage of the programmability and parallel nature of this machine, the requirements for performance started to grow up at much higher coefficient. So the models started to go up in terms of size and capacity, 2x every three months, which requires now 10x or 16x a year performance growth versus old school of twice every other year. And in order to grow this scale, you need to innovate and you need to develop solutions at much higher scale than just basic component. And that's where network kicks in, that's where network is. And there are multiple layers of scaling performance that requires high speed networks and high performance networks. The one is what we call scale up. Basically if you going back to the CPU days, scaling up was more low, more transistors and also some advances in the microarchitecture like out of order execution and at some point multi core and so on and so forth. But so this is the basic building block of computing in the GPU world. The basic building block is the gpu. And in order to scale it up more than you can do on a single piece of silicon, with a lot of advances that we are doing with the microarchitecture and advanced technologies, you actually need to do something on the scale of, on the, on the sort of multi core cpu but at much larger scale. And that's what we are doing with Envelink. This is a scale up solution. So our gpu, what we call GPU today is a rock size machine. Yeah, you need the forklift to lift it. Yeah. So you know, if you order just GPU on Amazon, just don't wonder that you'll show up this huge rack of.
Yeah, people think chip, but it's really a system.
Right. So. And that's just one gpu.
Yeah.
Okay, so basic building block. A very basic computer that application software is running on is this gpu. And it is not just silicon, it's not just hardware, it's not just wires. But there is also software layer that exposes CUDA as the API. And that's what actually enables to prepare pretty much seamlessly scale. I'm simplifying a little bit the story, but seamlessly scale from one component that used to be single GPU all the way up to 72 maintaining the same software interface. And once you get this building block as big as it conceivably can be built in terms of power, cost efficiency, then you start scaling out and scale out is it means you take many of these building blocks, connect them together, and now on the algorithm level, on the application level, you actually split your application to multiple pieces running in parallel on these big machines. And that's again where network comes in. And there is a. So if you talk about scale up, we basically made memory like domain to go beyond single compute node and a single, single gpu. And that's actually the first thing where Mellanox technology comes in. Because before Melanie's acquisition, the scaling up of Nvidia with the NVLink was limited to a single node machine going outside of single compute node. If the 72 GPUs are, it's actually 36 computers, each one has two GPUs and they're wired together. So present all this as a single GPU getting connectivity outside of the single node. It's not just plugging in the wire to the, to the connector. It's a lot of software, it's a lot of technology within the network how to make multiple nodes to work as the single machine. And that's where Mellanox first just immediate in terms of, you know, the, the way we go upstream, that's, that's the first one. The second one is the how do you split the operation across multiple machine, multiple machines? And the way to do it, if I have a task that it takes one GPU to do one second, if I want to accelerate it, I split it to 10 to, you know, thousand pieces and send each piece to different gpu. And now in one millisecond I get done whatever I was doing in the second. But you know, you need to communicate this partial job, split, split, split the task. Then you need to consolidate the results. And every time you are and you run this, you know, multiple times, you have multiple iterations or multiple applications running to us. So that there is a part of doing communication, part of doing computation. Now the thing is that you want to split it to as many pieces as you possibly can, because that's your speed up factor. But then if your communication is actually blocking you, you waste time, you waste energy, you waste everything. So what you need to do, you need to have a very fast communication. So you split it to the many, many pieces. And so each piece takes very little time. But then there is another piece that is communicated and you need to feed it this time. So that's just pure bandwidth. And another thing is that when you tune your application, you tune your application so that communication can be hidden behind computation. And it means that if Communication for some reason gets longer, then everybody waits. So it means that what you need to do in the network, you need to have not only just raw performance, like what called HERO numbers. You know, I can get to that many gigabits per second. I also need to make sure that no matter who communicate to whom, the latency, the time it takes is distribution is very narrow. So if you look at other network technologies or other network products, you know, you go to the HERO numbers, you know, sending bit from one place to another. It's basically physics. Yeah, it's, it's pretty much close to everyone. You know, we are a little bit better, but that's not the big advantage. But when you do it thousands of times and it takes the same time to do it, versus very wide distribution of other technologies, then machine becomes less efficient. So instead of being able to split your job to 1000 GPUs, you can split it only to 10 GPUs because you need to accommodate for the jitter on the network within the computation phase. So inherently, network determines the performance of this cluster. And we look at this data center as basically a single unit of computing. Yeah. Okay. Single unit computing means that you look at this, you start architecting your components, your software and your hardware. At the point where this is the data center, this is 100,000 GPUs that we want to make them work together. We need to make multiple chips, compute chips, two network chips, five. So this is a scale just in terms of what's the impact and what's the investment you need to make to create this single unit of computing. So that's where Mellanox technology came in. And another aspect of this is there is a, we talked about network that connects the GPUs to run the task. But there is a other side of this machine which is customer facing. So this machine needs to serve multiple tenants. And this machine needs to run operating system. Every computer runs operating system. Another part of the Mellanox technologies is what we call Bluefield DPU data processing unit, which is actually the computed platform to run the operating system of the data center. In conventional computer, we have a CPU that runs operating system and runs application software. And there's many things we can talk about, you know, the advantage versus disadvantage. But there are two key things. One is how much time do you spend on your general purpose computing to run the application? You need to, you want to maximize it. Another thing is how do you isolate your infrastructure computing from the application computing? Because you know, viruses and the cyber attacks and so on and so forth. And being able to run infrastructure computing on different computing platform actually reduces significantly the attack front versus especially in the side channel attacks versus what happens if you run it on the same computer. If you remember there was a five or six. Well actually almost 10 years ago there was this meltdown and all these cyber attacks of the side channel on CPUs and this cannot happen or the attack surface is reduced significantly when you run the different. So on the other side of the network we have also technology. So that's what makes data center to be more efficient. And I, well, I may be not objective, but I do agree that this merger of Mellanox and Nvidia and it actually goes both ways. I don't think that networking business of now it's Nvidia previously Mailox could have been growing that significantly as we grew. Now I think we are the fastest growing Ethernet business, let alone NVLink and InfiniBand. But just Ethernet business is the fastest growing business ever.
What are the things that break as you get to 100,000, maybe eventually million GPU clusters. And how do you use software to help design around that?
It's a multi stage challenge. One of the things that you.
Need.
To keep in mind. It's not very obvious for all the engineers that when you design the machine or think how to operate it well, you have these components and they're working. And now just let's figure out, okay, so the thing is that the hardware component works at 99.999 whatever percent of the time. And it's usually okay if you are dealing with single box with a couple of them. But if you are building 100,000 component machine, 100 GPUs machine, which means in terms of components there is a millions of them, the chance that everything works is zero. So something is definitely broken and you need to design it both from hardware and from software perspective to keep going, to keep going as efficient as you can. To keep you know, your performance, you keep your power efficiency and of course keep the service service running. So this is challenge number one. Even before you go to millions. It's this challenge actually starts at you know, a few few tens of thousands. That's number one. Number two is when you are running this workloads, it is really important to it. Sometimes you run single job on the entire entire data center and then it's, you know, you need to write the software and you need to provide all the interfaces to the software to place the different parts of the job jobs more efficiently building networks at this scale is a very different story than building network. Compute network on this scale is very different story than build just general purpose data center network. General purpose data center network is Internet. It's not a big deal. Well, it is a big deal, but it is different deal. You are serving loosely coupled collaborative microservices that create the service that you see as a customer from outside. Here you are running one single application on 100,000 machines.
Yeah. Is that specific to training workloads or is that also true with inference workloads?
It's true for everything. It depends to what scale. And the inference is yet another topic that we touched. Till recently, training was the key thing. A lot of GPUs and there is a very specific way of training is being done. You basically copy this way another model and multiple machines or multiple sets of machines and run them, then consolidate the results and so on and so forth. On the inference, the story is a little bit different. But the thing is that you need to provide the hooks on the hardware and on your low level software system software for application and for scheduler to place the job and place the different parts of the job in the most efficient way on the, you know, and as long as your machine fits a building, which is about 100,000 GPUs now talking about, you know, gigawatt, it's all power driven. Okay. The challenge is that for many reasons you want to split your workloads across multiple data centers. And sometimes data centers are at the distance of many kilometers, many miles, it may be across the continent. And this comes with yet another challenge, which is speed of light. Now, the latency variance between different parts of your machine is dramatically different. And what is even more challenging is that when you talk about networks, the congestion on the network is one of the key problems that deteriorate network performance. And managing congestion across such a latency difference. It's not like, you know, in old telco days, you put some box at the edge of your data center with a huge buffer and it's a shock absorber for congestion. Huge buffer is, is not good. Bigger is not better. There is famous statement from very famous Wuhan. And so we need to. And these buffers are basically, these devices are basically to isolate the external world from the internals. But when you want to run a single workload across data centers that are distance by kilometers, you need to be every machine on one side to be aware what, whom does it communicate to, whether it's short, short, short communication, long communication and adjust all the communication patterns accordingly. So you don't need these big buffers because big buffers is a jitter. Yeah. And so we have a, we have a technology we actually develop at recent technology. You know, all our ethernet network is Spectrum X and this is the device that we designed and developed based on the Spectrum switch that we put on the edge of the data center. And it provides all the information and telemetry needed for the endpoints to adjust for the congestion.
Can we talk a little bit more about training versus inference? How does the shape of workload defer when you're doing. I guess, I guess back prop is a lot more computationally intensive, forward pass less so. But like how does the workload differ? And then are you seeing customer demand start to shift from pre training towards inference or do you think it's still very training heavy right now?
And if I could just ask a quick follow up question with that. Will people be running inference workloads on the same data centers that they use for training or will these end up being two separate because they're different optimizations, people end up using two different sets of data centers.
Okay, yeah, that's a great question and let me start with the first one. Training has two phases. One is inference, which is just for propagation and then backpropagation to adjust the weights. And for data parallel training it's yet another phase to consolidate the results of the weights update across multiple model copies. So till recently it was main driver of the compute because till not very long ago it's maybe two years, which is ages. In the AI era the inference or AI was mainly perceptional. So you show the picture, that's a dog. You show you know, the photo of the person and his, that's, that's Michael and that's Sonia and that's so that's single path and that's it then came became generative AI where actually you get the recursive generation. So when you pause the prompt then it's not just one inference, it's many inferences. Because for every token, when you generate text or generate picture, for every new token you need to go through the entire machine all over again. So instead of one inter one shot intervals and then there is more and then now there is a reasoning which means machine starts, you know, sort of thinking. Yeah, if you ask me what time is it now? I can tell you it's easy, right? For times now. But if you ask me more complicated question then I need to think, I probably need to wait or compare multiple solutions or multiple paths. And every such a thing is Inference, every such thing is inference. And inference itself has actually two phases. One is much more compute intensive and the other one is memory intensive. It's what we call prefill because when you do the inference you have some sort of background which is prompt, which is some relevant data that you need to process and create the context to generate the answer. And this is very compute intensive. It's not much memory intensive. And the other part is actually generating the answer which is the decode part of the, of the inference where you generate token by token. Okay, well there are some technologies that you can generate more than one token, but it's still, you know, single path is much less than the final answer. So if you combine all these things together, inference, inference, demand for computing is not actually, not less than training. It's, it's, it's actually even more. And, and there are two reasons for this. One is that what I explained that there's a much more computing than it used to be for the inference. The other thing is, you know, you train model once but you infer many times. Yeah, you know, chatgpt, you know, billion of people or. Yeah, it's almost billion of people, right? There's customers, they are pounding them all the time in the same model. They trained it once, now they're making videos. So that's right, right now they're making videos and you can generate and you know, everybo is doing the inference. My wife, I think she talks to ChatGPT more than to me these days. Once she discovered this is her best friend. So in terms of things now to your question about machines, you can infer on the phone. Okay, so there is definitely going to be much smaller scale installations for, for inference. It's like mobile devices. If you look at the data center scale, at the data center scale and its efficiency of the programming programmability is much more viable than. Optimizations for hardware. And every hardware instance, it has its own, its own, its own cost and its own drawback. So as long as you don't identify and I don't think besides, you know this we actually did. It's very similar gpu. It's same programming model as a GPU for pre fill versus decode. I think, I don't remember it when it happened, but actually we announced that we are building the GPU SKU that is optimized for pre fill. So you will have it can do decode and decode. GPU can do pre fill but you can equip your data center with the SKUs or that pre fill versus SKUs that are for decode to optimize for typical use. But if your workload shifts for more decode or for more pre fill, you can use either one of them to compensate. And this is the importance of programmability. The same interfaces for GPUs. It's based on CUDA and UP, which is. That's what made Nvidia. Nvidia before Mellanox. Yeah, yeah.
Can I ask you a question about data center scaling? So for many decades we had Moore's law and chips got more and more dense and produced better and better performance. And then we ran into the laws of physics and chips just couldn't get more dense because their quantum mechanical properties caused them to break down. And so then we had to scale up to the rack level. Now we got to scale out to the data center level. Is there some analogous law of data center scaling that says when data centers get too big, the communication overhead causes the performance to break down? Or just said differently or maybe said more simply, is there a natural limit to how big data centers can get?
I think there is a practical limit of how much energy you can consume within given size of the data center.
If you were surrounded by nuclear power plants and the energy was available, would the data center itself perform form?
I don't know. I'm not an expert in the construction even. But if you surround, you know, there's a. There's energy coming in now the heat is going out. So there is a whole. We are now basically moved pretty much entirely to the liquid cooling.
Yeah.
And one of the reasons we did it is to enable much denser, denser compute power. We couldn't build as dense computing as we're building now with air cooling. So there's a whole bunch of technologies coming to help this more and more denser. Now the last big data center, which is like XAI scale is 100 or 150 megawatt. Now we're talking about gigawatt data centers. People talking about 10 gigawatt data centers. So there's a looking forward to build much bigger data centers.
Are you selling the data center centers to other space?
I think well, one of the things that determines the speed of data center deployment is how fast concrete gets stable. Fair enough.
So before starting Mellanox, you were at intel.
That's right.
16 years.
16 years.
Became chief architect. Nvidia and intel recently announced a partnership. Can you share a little bit about what the vision for that might be?
The starting point is that computing changed in last decade or a little bit More than decade. Nvidia started as the accelerated computing company. Video games was the first and then it evolved to AI which is the new way of data processing. So you cannot just general von Human machine just is not capable of being used as a platform to solve the problem. Like you know, programming one human machine is just explaining somebody what to do. Okay, I can explain many things and I can explain many people what to do, but I can't explain how to distinguish between, between cat and dog. Right. So there is a new challenges that AI solves and you need acceleration there. And our partnership with intel is actually fusing accelerated computing with the general purpose computing. Because general purpose computing is not going away. Everything will be accelerated. But we accelerate the purpose computing, we accelerate the applications, we accelerate. But so, so and you know, x86 is the architecture that is dominant there and you know, it would serve greatly both companies. That's actually one of the interesting things about Nvidia. It's the culture of win win. Okay? We are not after taking a bigger piece of existing pie. We are after baking our a bigger pie for everybody. And the success, our success is our customer success. Our success is not the failure of our competition. Our success is success of our customers and success of ecosystem. And I think fusing together conventional computing, Von Neumann machines and accelerated computing that provide with Nvidia is actually, it's probably open yet another dimension that I'm not sure what it is, but it basically gives on the practical short term view is this gives Nvidia and Intel channels to the market or expanding the market and serving the markets that otherwise was more challenging.
You mentioned the culture of Nvidia. So when Mellanox became part of Nvidia In 2019, the market cap of the combined company was about 100 billion, which is no joke. But the market cap today is about 4.5 trillion. And so 45x growth in value in six years is pretty phenomenal. How has that changed the culture of Nvidia? How is Nvidia different today now that it's one of the most admired companies in the world, if not the most admired versus six years ago.
Yeah, about this. When we just joined Jensen was in Israel and I presented him, you know, that's. I believe that 1 plus 1 will be 10 and I actually was off by factor of 4. So. But Mellanox and Nvidia in in a sense it's, it's, it's sort of similar. The culture very similar to begin with. But there are some, there's nothing absolutely similar. And I was the, the only founder that left in Melanox after Eyal resigned a few months after the acquisition. And my main focus at the beginning, you know, things. What do you think about in the shower? Was how to make sure that this acquisition will succeed. You know, Nvidia paid $7 billion for company that I founded. And it was all the mixed feelings that were there, but once it's done, it's done. Now I have to make it successful.
Yeah.
So eventually it worked. Most of the, most of the Israeli employees are state. I think it's 85 or 90% of original employees state. Actually Nvidia grew more than 2x in Israel in terms of manpower. Yeah. So we're growing and we are announcing that we are actually going to build a campus in Israel, new campus for Nvidia. And so that's where I think overall the merger was very successful. I did my best to make sure it succeeds. And besides the technology that I was looking at, this part of which is sort of technology, but it's technology and theology and there are many other things to make sure that people are comfortable that you know, from being in the center of Melanox, which is the headquarters on Israel, don't feel left, you know, somewhere in the far away. And Jensen basically emphasizes the networking is the critical part of Mellon Nvidia success. Yeah. And he's right. Yeah, yeah. So I think it was the. It's, it's, it's considered to be the most successful measure in the, in the history of the technology. I am, you guys probably track the things better than I am. But overall I think it was a great move.
Yeah.
What are the science fiction things that you spend your time thinking about? Just even wondering, like for example, optical interconnects. Do you think, do you think that will exist? Do you think AI will ever be better at physics than us and better at data center design than us?
Well, what I thinking if you look about science fiction is how to make history to be experimental science. You can physics try something and then see if it works and then try something else in history. Time goes one direction, but you have a good simulation of the world. You can my kids through experience. And we have an Earth 2 climate simulator. And with this type of technology we can actually simulate how what we do today will impact the global warming 50 years from now. Okay. So experimental science, you know, you, you try something, you see what happens 50 years later. So that's, that's, that's the science fiction part. Yeah. And you know, on the physics now we are moving from Reasoning and so on and so forth. Now once we get AI models to understand physics, we actually can learn physics. AI can teach us physics because the way we get to the laws of physics that we observe, theoretical physics, right, you observe some phenomena and you generalize it and you compose the rule that basically the law, the physics law that stays underneath of this phenomena. And AI is really great of generalizing and data processing and observing. So AI can help us to get to know some laws of physics that we don't even imagine now.
Yeah, Moore's law was 2x every two years. Huang plus Kagan's law is what is the slope and how long do you think you can sustain it?
Well, the slope is somewhere in the range of 10x or few orders of magnitude a year. And that's what we are doing by the way now since about two or three years ago, we accelerated our product introduction from every other year to every year. Now we introduce new, new wave of products every year and it's order of magnitude higher performance and it's not on the cheap level performance, it's on the machine that you can build with this performance. That's what we are looking at. It's single unit of computing. And how long it will stay, I don't know. I don't know. But we'll do our best to maintain it as long as needed and probably even accelerate. It's all about exponent. It's all about exponent. It's hard to imagine, you know, if you look at this mulo curves or any Rollo course, they usually plot it on the logarithmic scale so it looks like linear. But that's wrong thing to look. You can't predict what's going to happen. Who could predict that when iPhone was first introduced or smartphone was first introduced, you know, that's 15 years ago.
2007.
Yeah, 2007. Oh, 17 years ago. Okay. Who could, who could imagine that this smartphone, the least used function, at least for me, is a phone. Yeah, unless it's E commerce, it's, it's texting, it's news, it's mail, it's basically running, running your life from this machine. It's your authentication, your ID is there. So now who can imagine what's going to happen 10 years from now with all these developments that we are doing today? But we are building the platform for innovation.
What is your commentary on who can imagine Notwithstanding, what is the most optimistic view of our future with AI that you like to think about? What could AI do for the world? 5, 10, 15 years from now, Steve.
Jobs called computer to be the, the bicycle of. Of mind.
Yeah.
Okay, so AI is, it's maybe, I don't know if it's, if it's probably spaceship, because there's a lot of things that I would like to do, but I, I just don't have enough time, don't enough resources to do it with AI I will have it. And it doesn't mean that, you know, I will do twice as much. Maybe I do, I will do ten times as much. But the thing is that I will want to do 100 times as much as I want to do today. And that's where. And that's where. And you know, you go to any project leader and nobody says, you know, I have enough, I have enough manpower, I have enough resources. I don't need anymore. Okay, if you give him resources which is twice as efficient, he will do four times more and he will want to do 10 times more. So it's like electricity changes the world, right? Instead of using in the London, you still see this gas lamps and this infrastructure to use the gas as the source of energy. Who could think that once this electricity was invented, it will change the world that, you know, we can't live without electricity. The same, the same with AI Beautifully said.
Thank you so much for joining us today. I love this conversation.
Thank you, thank you, thank you for having me. It.
More from Sonya
Building the GitHub for RL Environments: Prime Intellect's Will Brown & Johannes Hagemann
Building the GitHub for RL Environments: Prime Intellect's Will Brown & Johannes Hagemann
Context Engineering Our Way to Long-Horizon Agents: LangChain’s Harrison Chase
Context Engineering Our Way to Long-Horizon Agents: LangChain’s Harrison Chase
How Ricursive Intelligence’s Founders are Using AI to Shape The Future of Chip Design
How Ricursive Intelligence’s Founders are Using AI to Shape The Future of Chip Design
Training General Robots for Any Task: Physical Intelligence’s Karol Hausman and Tobi Springenberg
Why the Next AI Revolution Will Happen Off-Screen: Samsara CEO Sanjit Biswas
Why the Next AI Revolution Will Happen Off-Screen: Samsara CEO Sanjit Biswas