Why Voice Will Be the Fundamental Interface for Tech ft ElevenLabs’ Mati Staniszewski
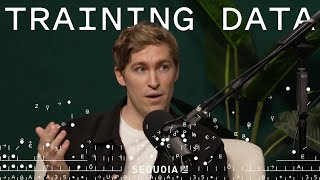
Mati Staniszewski, co-founder of ElevenLabs, traces the company's rise from a 2021 idea sparked by a poorly dubbed Polish movie to building a defensible voice-AI platform. ElevenLabs stayed ahead by focusing narrowly on audio and solving data scarcity, leading to viral moments like AI-generated laughter and Epic Games' Darth Vader agent. Staniszewski sees voice becoming the default interface for tech, with applications in education, healthcare, and customer support.
Chapters
Late 2021, the inspiration came from Peter was about to watch a movie with his. With his girlfriend. She didn't speak English, so they turned it up in Polish. And that kind of brought us back to something we grew up with, where every movie you watch in Polish, every foreign movie you watched in Polish has all the voices. So whether it's male voice or female voice, still narrated with one single character, like monotonous narration. It seems like a horrible experience and it still happens today. And it was like, wow, we think this will change.
Greetings. Today we're talking with Matty Stanischewski from eleven Labs about how they've carved out a defensible position in AI audio even as the big foundation model labs expand into voice as part of their push to multimodality. We dig into the technical differences between building voice AI versus text. It turns out they're surprisingly different in terms of the data and the architectures. Mati walks us through how ElevenLabs has stayed competitive by focusing narrowly on audio, including some of the specific engineering hurdles they've had to overcome and what enterprise customers actually care about. Beyond the benchmarks, we also explore the future of voice as an interface, the challenges of building AI agents that can handle real conversations, and AI's potential to break language barriers. Mati shares his thoughts on building a company in Europe and why he thinks we might hit human level voice interaction sooner than expected. We hope you enjoy the show. Matsi, welcome to the show.
Thank you for having me.
All right, first question. There was a school of thought a few years ago when ElevenLabs really started ripping that you guys are going to be roadkill for the foundation models and yet here you are still doing pretty well. What happened? How were you able to stave off the multimodality big foundation model labs and kind of carve out this really interesting position for yourselves.
It's exciting. Last few years and it's definitely true we still need to keep on our toes to be able to keep winning the Fido foundation models. But I think the usual and definitely true advice is staying focused and staying focused in our case on audio, both as a company, of course, the research and the product. But we ultimately stayed focused on the audio, which really helped. But the probably the biggest question under that question is through the years we've been able to build some of the best research models and outcompete the big labs. And here credit to my co founder, who I think is a genius, Piotr, who has been able to both do some of the first innovations in the space and then assemble a rockstar team that we have today at the company that is continually pushing what's possible in audio. And I was like, when we started, there was very little research done in audio. Most people focus on LLMs, some people focus on image a lot more easy to see the results frequently more exciting for people doing research to work in those fields. So there's a lot less focus put onto audio and the set of innovations that happened in the years prior. The diffusion models, the transformer models, weren't really applied to that domain in an efficient way. And we've been able to bring that in in those first years where for the first time the text to speech models were able to understand the context of the text and deliver that audio experience in just such a better tonality and emotion. So that was the starting point that really differentiated our work to other works, which was the true research innovation. But then fast following after that first piece was building all the product around it to be able to actually use that research. As we've seen so many times, it's not only the model that matters, it also matters how you deliver that experience to the user. And in our case, whether it's narrating and creating audiobooks, whether it's voiceovers, whether it's turning movies to other languages, whether it's adding text to speech and in the agents, or building the entire conversational experience, that layer keeps helping us to win across the foundational models and hyperscalers.
Okay, there's a lot here and we're going to come back and dig in on a bunch of aspects of that. But you mentioned your co founder, Peter. I believe you guys met in high school in Poland. Is that right? Can you kind of tell us the origin story of how you two got to know each other and then maybe the origin story of how this business came together?
I'm probably in the luckiest position ever. We met 15 years ago in high school. We started an IB class in Poland, in Warsaw, and took all the same classes, so. So kind of everything. And we hit it off pretty quickly on some of the mathematics classes. We both love mathematics, so we started both sitting together, spending a lot of time together. And that kind of morphed from outside the school time together as well. And then over the years, we kind of did it all from living together, studying together, working together, traveling together. And now 15 years in, we are still best friends. You know, the time is on our side, which does help us.
Has building a company together strengthened the.
Relationship or has there are ups and downs for sure. But I think it did, I think it did. I think it's battle tested it. Definitely battle tested it. And it was like, you know, when the company started taking off, it's hard to know how long the horizon of this intense work will happen. Initially was like, okay, this is the next four weeks. We just need to push, trust each other, that we'll do well on different aspects and just continue pushing. And then there was another four weeks, another four weeks. And then we realized actually this is going to be in the next 10 years. And there was just no real time for anything else. We were just like, just do 11 laps and nothing else. And over time, and I think this happened organically, but looking back, it definitely helped. We now try to still stay in close touch with what's happening in our personal lives, where we are in the world and spend some time together. Still speaking about work, but outside of the work context. And I think this was very healthy for now. I know Piotr for so long and I kind of seen him evolve personally through those years, but I can still stay in close touch to that as well.
It's important to make sure that your co founder and your executives and your team are able to bring their best self to work and not just completely ignoring everything that's happened on the personal front.
Exactly, yeah. And then to your second question, part of the inspiration for 11 Labs came, so maybe the longer story. So there are two parts. First, through the years when he was at Google, I was a palantir. We would do hack weekend projects together. Okay. So like trying to explore new technology for fun. And that was everything from building recommendation algorithms. So we tried to build this model where you would be presented with a few different things. And if you select one of those, the next set of things you're presented with gets closer and optimizes closer to your previous selection deployed. It had a lot of fun. Then we did the same with crypto. We tried to understand the risk in crypto and build like a risk analyzer for crypto. Very hard. They fully work. But, but, but, but it was good attempt in the first, one of the first crypto heights to, to try to provide like the analytics around it. And then we created a project in audio. So we created a project which analyzed how we speak and gave you tips on how to improve.
When Was this?
Early 2021. Okay. Early 2021. That was kind of the first opening. This is what's possible across audio space. This is the state of the art. These are the models that do diarization Understanding of speech. This is where the speech generation looks like. And then late 2021, the inspiration came from the. More of the aha moment from Poland from where you're from, where in this case, Peter was about to watch a movie with his girlfriend. She didn't speak English, so they turned it up in Polish. And that kind of brought us back to something we grew up with, where every movie you watch in Polish, every foreign movie watched in Polish has all the voices. So whether it's male voice or female voice, still narrated with one single character, like monotonous narration. It's like a horrible experience. And it still happens today. And it was like, wow, we think this will change, this will change. We think that technology and what will happen with some of the innovations will allow us to enjoy that content in the original delivery, in the original incredible voice. And let's make it happen and change it. Of course, then expanded since then, it's not only dubbing realized. The same problem exists across most content not being accessible in audio, just in English. How the dynamic interactions will evolve and of course how the audio will transmit the language barrier to.
Was there any particular paper or capability that you saw that made you think, okay, now is the time for this to change?
Well, attention is all you need. Is definitely one which was so crisp and clear in terms of what's possible. But maybe to give a different angle to the answer, I think the interesting piece was less so than the paper. There was this incredible open source repo. So that was slightly later in as we started discovering is it even possible? And there was a tortoise TTS effectively, which is an open source model that was kind of created at the time. It provided incredible results of replicating a voice and generating speech. It wasn't very stable, but it kind of have some glips into like, wow, this is incredible. And that was already as we were deeper into the company. So like maybe a first year in. So in 2022. But that was like another element of like, okay, this is possible. Some great ideas there. And then of course we've spent most of our time like, what other things we can innovate, start from scratch, bring the transformer diffusion into the audio space. And that kind of yielded just another level of human quality where you could actually feel like it's a human voice.
Yeah. Let's talk a bit about how you've actually built what you've built. As far as the product goes. What aspects of what works in text port directly over to audio and what's completely different, different skill Set different techniques. I'm curious how similar the two are and where some of the real differences are.
The first thing is there's kind of those three components that come into the model. There is the compute, there's the data, there's the model architecture. And the model architecture has some ideas, but it's very different. But then the data is also quite different in both in terms of what's accessible and how you need that data to be able to train the models. And in compute, the models are smaller, so you don't need as much compute, which allows us to, given a lot of the innovations need to happen on the model side or the data side, you can still outcompete foundational models rather.
Than just that big compute disadvantage.
Exactly. But the data was, I think, the first piece, which is different. Where in text you can reliably take the text that exists and it will work in audio, the data. First of all, there's much less of the high quality audio that actually would get you the result you need. And then the second, it frequently doesn't come with transcription or with a high accurate text of what was spoken. And that's kind of lacking in the space where you need to spend a lot of time. And then there's a third component, something that will be coming across in the current generation of models, which is not only what was said, so the transcript of the audio, but also how was it said, what emotions did you use, who said it, what are some of the nonverbal elements that were said that kind of almost doesn't exist, especially at the high quality. And that's where you need to spend a lot of time. That's where we've spent a lot of time in the early days too of being able to create effectively more of a speech to text model and like a pipeline with additional set of manual labelers to do that work. And that's very different from text where you just need to spend a lot more cycles. And then the model level, effectively you have this step of, in the first generation, a text to speech model of understanding the context and bringing that to emotion. But of course you need to kind of predict the next sound rather than the predict the next text token. And that both depends on the prior, but can also depend on what happens after. An easy example is like what a wonderful day. Let's say it's a passage of a book. Then you kind of think, okay, this is positive emotion, I should read it in a positive way. But if you have a what a wonderful day, I said sarcastically, then Suddenly it changes the entire meaning and you kind of need to adjust that in the audio delivery as well, put a punchline in the different spot. So that was definitely different. Where that contextual understanding was a tricky thing. And then the other model thing, that's very different, you have the text to speech element but then you have also the voice element. The. So the kind of the other innovation that we spend a lot of time working on is how can you create and represent voices to high accurate way of what was in the original. And we found like this decoding encoding way which was slightly different to the space. We weren't hard coding or predicting any specific features. So we weren't trying to optimize is the voice male or is the voice female or what's the age of the voice. Instead we effectively let the model decide what the characteristics should be and then it found a way to bring that into the speech. So now of course when you have the text to speech model, it will take the context of the text as one input and the second will take the voice as a second input. And based on the voice delivery, if it's more calm or dynamic, both of those will merge together and then give the kind of the end output which was course very different type of work than the text models.
Amazing. What sort of people have you needed to hire to be able to build this? I imagine it's a different skill set than most AI companies.
And it kind of changed over time. But I think the first difference, and this is probably less skill set difference but more approach difference. We've started fully remote. We wanted to hire the best researchers wherever they are. We knew where they are. There's probably like 50 to 100 great people in audio based at least on the open source work or the papers that they release or the companies that they worked in. That's what admirer. So the top of the funnel is pretty limited because so much fewer people worked on the research. So we decided let's attract them and get them into the company wherever, wherever they are. And that, that kind of really helped. The second thing was, you know, given, given we want to make it exciting for a lot of people to, to, to, to, to work. But also we think this is the best way to, to run a lot of the research. We try to make the, the, the researchers extremely close to, to deployment, to actually seeing the results of their work. So the cycle from being able to research something to bringing it in front of all the people is super short.
Yeah.
And you get immediate feedback of how then we have A kind of separate and research. We have research engineers that focus less on the innovation of the entire kind of new architecture of the models, but taking existing models, improving them, changing them, deploying them at scale. And here frequently you've seen other companies call our research engineers researchers, given that the work would be as complex in those companies. But that kind of really helped us to create a new innovation, bring that innovation, extend it and deploy it. And then the layer around the research that we've created is probably very different. Where we effectively have now a group of voice coaches, data labelers that are trained by voice coaches to understand the audio data, how to label that, how to label the emotions, and then they get re reviewed by the voice coaches, whether it's good or bad. Because most of the traditional companies didn't really support audio labeling in that same way. But I think the biggest difference is you needed to be excited about some part of the audio work to really be able to create and dedicate yourself to the level we want. And we're small, we're especially at the time, small company. You would be willing to embrace that independence, that high ownership that it takes, that you are effectively working on a specific research theme yourself. And of course there's some interaction, some guidance from others, but a lot of the heavy lifting is individual and creating that work, which takes a different mindset. And I think we've been able to. Now we have a team of 15 research and research engineers almost and they are incredible.
What have some of the major kind of step function changes in the quality of the product or the applicability of the product been over the last few years? I remember kind of early. I think it was early 2023ish when you guys started to explode or maybe late 2023, I forget. And it seemed like some of it was on the heels of the Harry Potter Balenciaga video that went viral, where it was an 11 Labs voice that was doing. Seems like you've had these moments in the consumer world where something goes viral and it traces back to you. But beyond that, from a product standpoint, what have been kind of the major inflection points that have opened up new markets or spurred more developer enthusiasm?
You know, it's the. What you mentioned is probably one of the key things we are trying to do and continuously even now we see this is like one of the key things to really get the adoption out there, which is have the prosumer deployment and actually bringing it to everyone out there when we create a new technology, showing to the world that it's possible and then kind of supplementing that of the top down, bringing it to the specific companies we work with. And the reason for this is kind of twofold. One is these groups of people are just so much more eager and quick to adopt and create that technology. And the second one, frequently when we create a lot of both the product and the research work, the set of use cases that might be created, we have of course, some predictions, but there's just so many more that we wouldn't expect. Like the example you gave that wouldn't have come to our mind that this is something that people might be creating and trying to do. And that was definitely something where we continuously, even now when we create new models, we try to bring it to the entirety of the user base, learn from them and increase that. And it kind of goes in those waves where we have a new model release, we bring it abroad, then kind of the prosumer adoption is there and then the enterprise adoption follows with additional product, additional reliability, that needs to happen. And then once again we have a new step release and a new function and kind of the cycle repeats. So we tried to really embrace it through the history. The first one, the very first one was when we had our beta model. So that you were right. When we released it publicly, early 2023, late 2022, we were iterating in the beta with subset of users and we had a lot of book authors in that subset. And we had this like literally a small text box in our product where you could input the text and get the speech out. It was like a tweet length effectively. And we had one of those book authors copy paste his entire book inside this box, download it. Then at the time it was most of the platforms banned AI content. He managed to upload it, they thought it's human. He started getting great reviews on that platform and then came back to us with set of his friends and other book authors saying like, hey, we really need it. This is incredible. And that kind of triggered this first mini virality month with book authors very, very keen. Then we had another similar moment around the same period where we. That was one of the first models that could, that could laugh. We released this blog post that the first AI that can laugh and people picked it up like, wow, this is incredible. This is really working. We got a lot of the early users. Then of course the theme that you mentioned, which was a lot of the creators and I think there's like a completely new trend that started around this time where it shifted into no no face channels, effectively you don't have the, the creator in the frame and then you have narration of that creator across something that's happening. And that started going like wildfire in the first six months of the work where of course we were providing the narration and the speech and the voices for a lot of those use cases. And that was great to see. Then late 2023, early 2024, we released our work in other languages. That's one of the first moments where you could, you could really create the narration across other most famous European languages and our dubbing product. So that's kind of back to the original vision. We created finally a way for you to have the audio and bring it to another language while still sounding the same. And, and that, that kind of triggered this other small virality moment of people, people creating the videos. And there was like this, you know, the expected ones, which is just the traditional content, but also unexpected ones, where we had someone trying to dub singing videos which the model we didn't know will work on. And it kind of didn't work, but it gave you like a drunken singing result. So then it went a few times viral too for that result, which was fun to see. And then in 2025, at the early time now, and we are seeing kind of recurrently now, everybody is creating an agent. We started adding the voice to a lot of those agents and it became both very easy to do for a lot of people to have their entire orchestration, speech to text, the LLM responses, text to speech to make it seamless. And we had now few use cases which started getting a lot of traction, a lot of adoption. Most recently we worked with Epic Games to recreate the voice of Darth Vader, which players. There's just so many people using and trying to get the conversation of Darth Vader in Fortnite, which is just immense scale. And of course most of the users are trying to have a great conversation, use him as a companion in the game. Some people are trying to stretch whether he will say something that he shouldn't be able to say. So you see all those attempts as well. But luckily the product is holding up and it's actually keeping it relatively both performative and safe to actually keep him on the rails. I'm thinking about some of the dubbing use cases. One of the viral ones was when we worked with Lex Friedman and he interviewed Prime Minister Narendra Modi. And we turned the conversation, which happened between English through Lex and Narayanamodi spoke Hindi and we turned the conversation into English so you could actually listen to both of them speaking together. And then similarly we turned both of them to Hindi so you heard Lex speaking Hindi. And that went also extremely viral in India where people were watching both of those versions and in US people were watching the English version. So that was a nice way of tying it back to the beginning. But I think they especially as you think about the future, the agents and just seeing them pop up in new ways is going to be so frequent. Like both early developers building everything from Stripe integration and being able to process refunds through to the companion use cases all the way through to the true enterprise is kind of having probably a few viral moments ahead.
Yeah, say more about what you're seeing in voice agents right now. It seems like that's quickly become a pretty popular interaction pattern. What's working, what's not working? You know, where are your customers really having success? Where are some of your customers kind of getting stuck?
And before I answer maybe a question back to you, do you see a lot more companies building agents across the companies that are coming through Sequoia?
Yeah, we absolutely do. And I think most people have this long term vision that it's sort of a Heygin style avatar powered by an 11 Labs voice where it's this human like agent that you're interacting with. And I think most people start with simpler modalities and kind of work their way up. So we see a lot of text based agents sort of proliferating throughout the enterprise stack and I imagine there are lots of consumer applications for that as well. But we tend to see a lot of the enterprise stuff.
It's similar. Definitely what we are seeing both on the new startups being created where it's like everybody is building an agent and on the enterprise side too can be so helpful for the process internally. And taking a step back, what we think and believe from kind of the start is voice will fundamentally be the interface for interacting with technology. It would be one of the most. It's probably the modality we've known from when the human genre was born as the kind of first way that humans interacted. And it carries just so much more than text does. It carries the emotions, the intonation, the imperfections. We can understand each other. We can, based on the emotional cues respond in very different ways. So that's where our start happen, where we think the voice will be that interface and build not just the text to speech element, but seeing our clients try to use the text to speech and do the whole conversational application. Can we provide Them a solution that helps them abstract this away.
Yeah.
And, you know, we've seen from. From like the traditional domains and to speak for a few, it's like in healthcare space. Yeah. We've seen people try to automate some of the work they cannot do. With nurses, as an example, a company like Hippocratic will automate their calls that nurses need to take to the patients to remind them about taking medicine, ask how they are feeling, capture that information back so then the doctors can actually process that in a much more efficient way. And voice became critical where a lot of those people cannot be reached otherwise. And the voice call is just the easiest thing to do then very traditional. Probably the quickest moving one is customer support. So many companies, both from the call center and the traditional customer support, trying to build the voice internally in the companies, whether it's companies like Deutsche Telekom all the way through to the new companies, everybody is trying to find a way to deliver better experience. And now voice is possible. And then what is probably one of the most exciting for me is education. Where could you be learning through having that voice delivery in a new way? I used to at least be a chess player or like an amateur chess player. And we work with Chess.com where you can. I don't know if you're a user of Chess.com?
I am, but I'm a very bad chess player.
Okay. Okay. So maybe so. That's a great cue. One of the things is we are trying to build effectively a narration which guides you through the game so you can learn how to play better. And there's a version of that where hopefully you will be able to work with some of the iconic chess players where you can, like, have the delivery from Magnus Carlsen or Gary Gaspar for Hikaru Nakamura to guide you through the game and get even better while you play it, which would be phenomenal. And I think this will be one of the common things we'll see where everybody will have their personal tutor for the subject that they want with voice that they relate to, and they can get closer. And that's on the enterprise side, but then on the consumer side too, we've seen completely new ways of augmenting the way you can deliver the content, like the work of the Time magazine, where you can read the article, you can listen to the article, but you can also speak to the article. So you worked effectively during the Person of the Year release, where you could ask the questions about how they became Person of the Year. Tell me more about other people of the year and kind of dive into that a little bit here and then we as a company every so often are trying to build an agent that people can interact and see the art of possible. Most recently we've created an agent for my favorite physicist or one of the two with working with his family, Richard Feynman, where you can actually, he's my favorite too. Okay, great, great. I mean he's amazing. Such an amazing way to both deliver the knowledge in educational, simple way and a humoristic way. And just like the way he speaks is also amazing and the way he writes is amazing. So that was amazing. And I think this will alter where maybe in the future you will have his cultic lectures or one of his book where you can listen to it in his voice and then dive into some of his background and understand that bit better. Surely you're joking, Mr. Feynman, and dive into this.
I would love to hear a reading of that book in his voice. That'd be amazing for some of the enterprise applications or maybe the consumer applications as well. It seems like there are a lot of situations where the interface is not. The interface might be the enabler, but it's not the bottleneck. The bottleneck is sort of the underlying business logic or the underlying context that's required to actually have the right sort of conversation with your customer or whoever the user is. How often do you run into that? What's your sense for where those bottlenecks are getting removed and where they might still be a little bit sticky at the moment?
The benefit of us working so closely with a lot of companies where we bring our engineers to work directly with them frequently results in us kind of diving into seeing some of the common bottlenecks. And when we've started, let's think about a conversational AI stack. You have the speech to text element of understanding what you say. You have the LM piece of generating the response and then text to speech to narrate it back. And then you have the entire turn taking model to deliver that experience in a good way. But really that's just the enabler. But then like you said, to be able to deliver the right response, you need both the knowledge base, the business base, or the business information about how you want to actually generate that response and what's relevant in a specific context. And then you need the functions and integrations to trigger the right set of actions. And in our case, we've built that stack around the product so companies we work with can bring that knowledge base relatively easily, have access to rag if they want to enable this, are able to do that on the fly if they need to, and then of course build the functions around it. And the sort of very common themes is definitely coming across where the deeper the enterprise you go, the more integrations will start becoming more important. Whether it's simple things like Twilio or SIP trunking to make the phone call, or whether it's connecting to the CRM system of choice that they have, or working with the past providers or the current providers where those companies are deployed like Genesis. That's definitely a common theme where that's probably taking the most time of like, how do you have the entire suite of integrations that works reliably and the business can easily connect to their, to their logic. In our case, of course, this is increasing and every next company we work with already benefits from a lot of the integrations that were built, so that's probably the most frequent one. The integrations itself, knowledge base isn't as big of an issue, but that depends on the company. If we work with a company that we've seen it all from, how well organized the knowledge is inside of the company, if it's a company that has been spending a lot of effort on digitizing already and creating some version of source of truth, where that information lies and how it lies, relatively easy to onboard them. And then as we go to more complex one, and I don't know if I can mention anyone, but it can get pretty gnarly and then we work with them on like, okay, that's what we need to do as the first step. Some of the protocols that are being developed to standardize that like MCP is definitely, is definitely helpful, something that we also are bringing into the fold. You don't want to spend the time on all the integrations. If the services can provide that, that's an easy standard way.
Well, and you mentioned anthropic. One of the things that you plug into is the foundation models themselves. And I imagine there's a bit of a coopetition dynamic where sometimes you're competing with their voice functionality, sometimes you're. You're working with them to provide a solution for a customer. How do you manage that? I imagine there are a bunch of founders listening who are in similar positions where they work with foundation models, but they kind of compete with foundation models. I'm just curious, how do you manage that?
I think the main thing that we've realized is most of them are complementary to work like conversational AI and we're trying to stay agnostic from using one provider. But I think the main thing is true and, and happened over especially last year, now that I think about it, is that we are not trying to rely only on one, we are trying to have many of them together in the fold and that kind of goes to both. Like one, what if they develop into being a closer competition where maybe they won't be able to provide the service to us or their service becomes too blurry or we of course are not using any of the data back to them, but could that be a concern in the future? So kind of that piece, but also the second piece is when you develop a product like conversational AI which allows you to deploy your voice AI agent, all our customers will have a different preference for using the lm. But frequently or even more frequently, you want kind of this cascading mechanism that what if one LLM isn't working at a given time, go through and have that kind of the second layer of support or third layer to perform pretty well. And we've seen this work extremely successfully. So to a large extent treat them as partners, happy to be partners with many of them and hopefully that continues. And if we are competing, that'll be a good competition too.
Let me ask you on the product, what do your customers care the most about? One sort of meme over the last year or so has been people who keep touting benchmarks are kind of missing the point. There are a lot of things beyond the benchmarks that customers really care about. Is it your customers really care about?
And very true on the benchmark side, especially in audio. But our customers care about three things. Quality, both like how expressive it is in both English and other languages. And that's probably the top one. If you don't have quality, everything else doesn't matter. Of course the thresholds of quality will depend on the use case. It's a different threshold for narration, for delivery in the agentic space and dubbing. Second one is latency. You won't be able to deliver a conversational agent if the latency isn't good enough. But that's where the interesting combination will happen between what's the quality versus latency benchmark that you have? And then the third one, which is especially useful at that scale is reliability. Like can I deploy at scale like the Epic Games example, where millions of players are interacting with and the system holds up, it's still performative, still works extremely well. And time and time again we've seen that the kind of being able to scale and reliably deliver that infrastructure is critical.
Can I ask you how far do you think we are from highly or fully reliable human or superhuman quality? Effectively zero latency voice interaction? And maybe the related question is how does the nature of the engineering challenges you face change as we get closer and inevitably surpass that sort of threshold?
The ideal. We would love to prove that it's possible this year. This year, cross the Turing test of speaking with an agent and you just would say this is like speaking another human. I think it's a very ambitious goal, but I think it's possible. I think it's possible, if not this year, then hopefully early in 2026. But I think we can do it. I think we can do it. You probably have different groups of users too, where some people will kind of be very attuned and you will be much harder to pass the Turing test for them. But for majority of people, I hope we are able to get it to that level this year. I think the biggest question, and that's kind of where the timeline is a little bit more dependent, is will it be the model that we have today, which is a cascading model, where you have the speech to text, a lamb text to speech, so three separate pieces that can be performative, or do you have the omni model where you train them together truly duplex style, where that delivery is much better. And that's effectively what we are kind of trying to assess. We are doing both. We are. Now then the one in production is the cascading model. Soon the one we'll deploy will be a truly duplex model. And I think the main thing that you will see is the reliability versus expressivity trade off. I think latency, we can get pretty good on both sides. But similarly there might be some trade off of latency, where the true duplex model will always be quicker, will be a little bit more expressive, but less reliable. And the cascaded model is definitely more reliable, can be extremely expressive, but maybe not as contextually responsive and then latency will be a little bit harder. So that would be a huge engineering challenge and I think no company has been able to do it well, like fuse the modality of LLMs with audio well. So I hope we'll be the first one, which is the internal big goal. But we've seen probably the OpenAI work, the meta work that are doubling in there. I don't think it passed the Turing test yet. So hopefully we'll be the first.
Awesome. And then you mentioned earlier that you think of and you have thought of voice as sort of a New default interaction mode for a lot of technology. Can you paint that picture a little bit more? You know, let's say we're five or ten years down the road. How do you imagine just the way people live with technology, the way people interact with technology changes as a result of your model getting so good.
I think the first, like, you know, there would be this beautiful part where kind of technology will go into the background so you can really focus on. On learning, on human interaction. And then you will have it accessible through voice versus through the screen. I think the first piece will be the education. I think there will be an entire change where all of us will have the kind of the guiding voice, whether we are learning mathematics and going through the notes, or whether we are trying to learn a new language and interact with a native speaker to guide you through how to pronounce things. And. And I think this will be the first theme where in the next five, 10 years it will be the default that you will have the agents, voice agents, to help you through that learning. Second thing, which will be interesting, how this affects the whole cultural exchange around the world. I think you will be able to go to another country and interact with another person while still carrying your own voice, your own emotion, intonation, and the person can understand you. There will be an interesting question how the technology is delivered. Is it the headphone? Is it neuralink? Is it another technology? But it will happen and I think we hopefully can make it happen. If you read Hitchhiker's Guide to Galaxy, there's this concept of Babelfish. I think babelfish will be there and the technology will make it possible. So that will be a second huge theme. And I think generally we've spoke about this personal tutor example, but I think there will be other set of assistants and agents that all of us have that just can be sent to perform tasks on our behalf. And to perform a lot of those tasks, you will need voice, whether it's booking a restaurant or whether it's jumping into a specific meeting to take notes and summarize that in the style that you need, you want to be able to perform the action, or whether it's calling a customer support and the customer support agent responding. So that would be an interesting theme of agent to agent interaction and how it is authenticated. How do you know it's real or not? But of course, voice will play a big role in all three. The education, I think, and generally how we learn things will be so dependent on that kind of the universal translator. A piece will have Voice at the forefront. And then the general services around the life will be so crucially voice driven.
Very cool. And you mentioned authentication. I was going to ask you about that. So one of the fears that always comes up is impersonation. Can you talk about how you've handled that to date and maybe how it's evolved to date and where you see it headed from here?
Yeah, we started and that was like a big piece for us from the start, is for all the content generated Elevenlabs, you can trace it back to the specific account that generated it. So you have a pretty robust mechanism of tying the audio output to the account and it can take action. So that provenance is extremely important and I think will be increasingly important in the future where you want to be able to understand what's the AI content or not AI content. Or maybe it will shift even step deeper where you will run authenticating AI. You'll also authenticate humans. So you'll have on device authentication that, okay, this is Matty calling another person. The second thing is the wider set of the moderation of Is it a call trying to do fraud and scam or is this a voice that might be not authenticated, which we do as a company and that kind of evolved over time to what extent we do it and how we do it, but so moderating on the voice, on the text level. And then the third thing, kind of stretching what we've started ourselves on the provenance component is like how can we train models and work with other companies to not only train it for 11 labs, but also open source technology, which is of course prevalent in that space, other commercial models. And it's possible, of course, as open source develops, it always will be a cut and mouse game, whether you can actually catch it. But we worked a lot with other companies or academia like University of Berkeley to actually deliver those models and be able to detect it. And that's kind of the guiding, especially now that the more we take the leading position and deploying new technology like the conversational AI, soon a new model, we try to spend even more time on trying to understand what are the safety mechanisms that we can, that we can bring in to make it as useful for good actors and minimize the bad actors. So that's the usual trade off there.
Can we talk about Europe for a minute?
Let's do it.
Okay, so you're a remote company, but you're based in London. What have been the advantages of being based in Europe? What have been some of the disadvantages of being based in Europe?
That's a great question. I think the advantage for us was the talent, being able to attract some of the best talent. And frequently people say that there is like lack of drive from the people in Europe. We haven't felt that at all. We feel like these people are so passionate. We have like I think such an incredible team. We try to run it with small teams, but everybody is just like pushing all the time, so excited about what we can do. And some of the most hard working people I had a pleasure to work with and such a high caliber of people too. So talent was a extremely positive surprise for us of how the team kind of got constructed. And especially now as we continue hiring people, whether it's people across broader Europe, central, Eastern Europe, just that caliber is super high. Second thing, which I think is true, where there's this wider feeling where Europe is behind and likely in many ways it's true, like AI innovation is being led in us Countries in Asia are closely following, Europe is behind. But the energy for the people is to really change that. And I think it's shifted from over last years where it was a little bit more cautious over when we started the company. Now we feel the keenness and we want to be at the forefront of that. And I think getting that energy from people and that drive was a lot easier. So that's probably an advantage where we can just move quicker. The companies are actually keen to adopt increasingly, which is helping. And as a company in Europe, really as a global company, but with a lot of people in Europe, it helps us deploy with those companies too. And maybe there's another flavor and last flavor of that which is Europe specific, but also global specific. So when we started company we didn't really think about any specific region, like we are a Polish company or British company or US company. But one thing was true where we wanted to be a global solution. And not only from deployment perspective, but also from the core of what we are trying to achieve where it's like how do we bring audio and I make it accessible in all those different languages. So it kind of was through the spine of the company from the start, from the core of the company. And that definitely helped us where now when we have a lot of people in all of different regions, they speak the language, they can work with the clients. And that I think likely helped that we were at Europe at the time because we were able to bring a lot of people and optimize for that local experience. On the other side, what was definitely harder is in the US there is this incredible Community of you have people with the drive, but you also have the people that have been through this journey a few times and you can learn from those people so much easier. And there's just so many of people that created companies, exited companies, led a function at a different scale than most of the companies in Europe. So it's kind of almost granted that you can learn from those people just by being around them and being able to ask the questions. That was much harder I think especially in the early days to just be able to ask those like not even ask the questions, but know what questions to ask. Yeah, of course we, we've been lucky to, to partner with, with, with incredible investors for the years to help us through, through, through those questions. But, but that was, that was harder I think in Europe. And then the second is, is probably the flip side of, of, you know. Well, I'm positive there is the enthusiasm now in Europe. I think it was lacking over last years. I think us was excitingly taking the approach of leading especially over last year and creating the ecosystem to let it flourish. I think Europe is still figuring it out and that's whether it's the regulatory things that you AI act that I think will not contribute to us accelerating which people are trying to figure out. There is the enthusiasm, but I think it's slowing down. But the first one is definitely the bigger disadvantage.
Yeah. Should we do a quick fire round?
Let's do it.
Okay. What is your favorite AI application that you personally use? And it can't be 11 labs or 11 reader.
It really changes over time. But Perplexity was I think and is one of my favorites.
Really. And for you, what does Perplexity give you that ChatGPT or Google doesn't give you?
Yeah, ChatGPT is also amazing. ChatGPT is also amazing. I think for a long time it was being able to go deeper and understand the sources that was. I hesitated a little bit of the was is where I think ChatGPT now has a lot more of that component. So I tend to use both in many of those cases for a long time a non AI application. But I think they are trying to build AI application like my favorite app would be Google Maps. I think it's incredible. It's such a powerful application. Let me pull my screen. What other applications do I have?
Well, sorry, while you're doing that, I will go to Google Maps and just browse. I'll just go to Google Maps and explore some location that I've never been to before.
100%. I mean it's great as a search function of the ARIA too. It's great as a niche application. I like FYI, this is a William startup.
Oh, okay.
Which is like a combination of. Well, it started as a communication app, but now it's more of a radio app.
Okay.
Like when Curiosity is there. Cloud is great too. Like I use cloud for very different things than. Than, than like any deeper coding elements, prototyping. I always use cloud cloud and I love it. Actually no, I do have a real like more real recent answer which is Lovable. Okay. Lovable. Was do you at all for 11.
Labs or did you just use it personally to.
Ah, no, that's true. I think like, you know, the. My life is 11 labs. Like I. It's. It's a. So the truth is for all those applications. Yes, it's like all of these I use partly for big time for 11 labs too. But. But yeah, I loveable. I use for. For 11 labs but like exploring new things too. Every so often I will use Lovable, which ultimately is tied to 11 labs, but that it's great for prototyping and like pulling up a quick demo for a client. It's. It's, it's. It's great.
Very cool.
So related, I guess. Yeah.
All right.
Who. What was your favorite one?
My favorite one? You know, it's funny. So yesterday we had a team meeting and everybody, Everybody checked with ChatGPT to see how many queries they sub they'd submitted in the last 30 days. And I'd done like 300 in the last 30 days. I was like, oh yeah, that's pretty good. Pretty good user. And Andrew similarly had done about 300 in the last 30 days. Some of the younger folks on our team, it was a thousand plus. And so not. Not only I'm a big DAU of of ChatGPT and I thought I was a power user, but apparently not compared to what some other people are doing. I know it's a very generic answer, but it's unbelievable how much you can do in one app at this point.
Do you use cloud as well?
I use cloud a little bit, but not nearly as much. The other app that I use every single day, which I'm very contrarian on, is Quip, which is Brett Taylor's company from years ago that got sold to Salesforce. And I'm pretty sure that I'm the only DAU at this point, but I'm just hoping Salesforce doesn't shut it down because my whole life is in Quip.
We use Palantir. I Like quip Qwip was good.
It's really good. Yeah, no, they nailed the basics. Like they nailed the basics. Didn't get bogged down in bells and whistles, just nailed the basics. Great experience. All right.
Who is.
Who in the world of AI do you admire most?
These are like hard, not rapid fire questions. But I think I really like Demis Hassabis.
Tell me more.
It's, you know, both his the. I think he is always straight to the point. He can speak very deeply about the research, but he also has created through the years so many incredible work himself. And I was of course leading a lot of the research work. But I kind of like that combination that he has been doing the research and now leading it and whether this was the alphafold, which I think is truly a new. It's like everybody I think agrees here, but like a true frontier for the world and kind of taking what. While most people focus on part of the AI work, he is kind of trying to bring it to biology. I mean Dario Amadei is of course trying to do that too. So it's going to be incredible what this evolves to. But then that he was creating games in the early days was incredible. Chess player has been trying to find a way for AI to win across all those games. It's like the versaility of how he both can lead the deployment of research. Is probably one of the best researchers himself. Stays extremely humble and just like honest, intellectually honest. I feel like, you know, you were speaking with them as Sir Damas, you would get an honest answer and yeah, he's amazing.
Very cool. All right, last one. Hot take on the future of AI. Some belief that you feel medium too strongly about that you feel is underhyped or maybe contrarian.
I feel like it's an answer that you would expect maybe to some extent. But I do think the whole cross lingual aspect is still totally underhyped. If you will be able to go any place and speak that language and people can truly speak with yourself and whether this will be initially the delivery of content and then future delivery of communication, I think this will change the world of how we see it. I think one of the biggest barriers is in those conversations that you cannot really understand the other person. Of course it has a textual component to it, like be able to translate it well, but then also the voice delivery and I feel like this is completely underhyped. It's like nobody.
Do you think the device that enables that exists yet?
No, I don't think so.
It won't be the phone won't be. Glasses might be some other form factor.
I think it will have many forms. I think people will have glasses. I think headphones will be one of the first, which will be the easiest. Yeah, I mean, glasses for sure will be there too, but I don't think everybody will wear the glasses. And then, you know, like, is there some version of a non invasive neuralink that people can have while they travel? That would be an interesting attachment to the body that actually works. Do you think it's underhyped or do you think it's hyped enough? This use case.
I would probably bundle that into the overall idea of sort of ambient computing where you are able to focus on human beings. Technology fades into the background. It's passively absorbing what's happening around you, using that context to help make you smarter, help you do things, help translate whatever the case might be. Yeah, I think that absolutely fits into my mental model of where the world is headed. But I do wonder what. What will the form factor be that enables that? I think it's pretty. What are the enabling technologies that allow for the business logic and that sort of thing to work? Starting to come into focus. What's the form factor is still to be determined, but I absolutely agree with that.
Yeah, maybe that's. Maybe that's the reason it's not hyped enough that you don't.
Yeah, people can't picture it.
Yeah.
Awesome. Mati, thanks so much.
Pat, thank you so much for having me. It was a great conversation.
Been a pleasure.
More from Sonya
Building the GitHub for RL Environments: Prime Intellect's Will Brown & Johannes Hagemann
Building the GitHub for RL Environments: Prime Intellect's Will Brown & Johannes Hagemann
Context Engineering Our Way to Long-Horizon Agents: LangChain’s Harrison Chase
Context Engineering Our Way to Long-Horizon Agents: LangChain’s Harrison Chase
How Ricursive Intelligence’s Founders are Using AI to Shape The Future of Chip Design
How Ricursive Intelligence’s Founders are Using AI to Shape The Future of Chip Design
Training General Robots for Any Task: Physical Intelligence’s Karol Hausman and Tobi Springenberg
Why the Next AI Revolution Will Happen Off-Screen: Samsara CEO Sanjit Biswas
Why the Next AI Revolution Will Happen Off-Screen: Samsara CEO Sanjit Biswas