Active Graph Agent Runtime (BabyAGI 4) — Yohei Nakajima, Untapped Capital
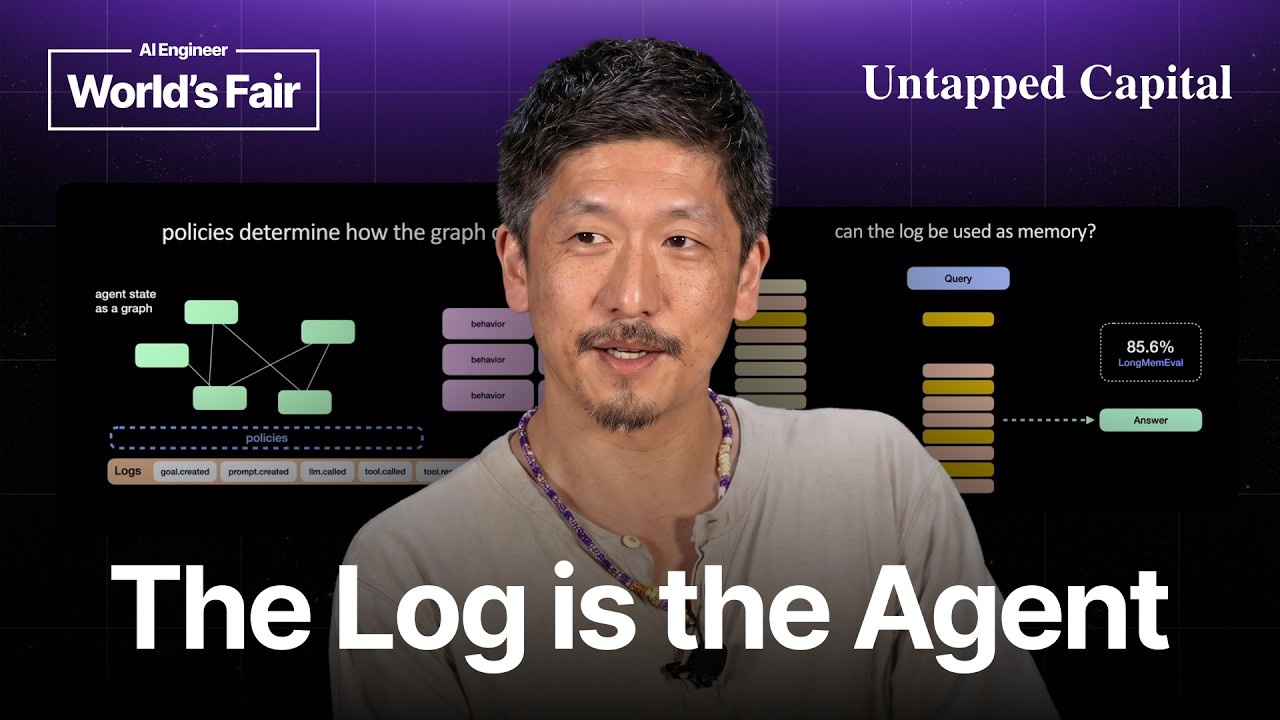
In this presentation Yohei Nakajima introduces ActiveGraph, an open‑source, event‑sourced graph runtime designed to build auditable, self‑modifying autonomous agents. He contrasts the prevailing LLM‑centric agent stacks—where an LLM is the core and tools, memory, and logging are added on top—with a log‑centric approach that treats a single immutable, typed event log as the ground truth of the agent. The log projects a typed graph state; behaviors listen to graph changes and emit new events, forming a reactive system. Policies govern which graph modifications are allowed automatically and which require human‑in‑the‑loop or automated gating (proposed patches). Modular "packs" bundle object schemas, tools, and deterministic or LLM‑driven behaviors, enabling composable agent harnesses. Views provide context via graph queries. Nakajima demonstrates the runtime through several experiments: using the log itself as memory for LangMemEval and LongMemEval, implementing controlled self‑improvement loops (Regimes) that propose, test, and accept patches, and building higher‑level agents (coding, research) that automatically generate their own ActiveGraph structures. He also showcases ActiveGraph Lab, an agent that reads its own documentation, proposes experiments, writes PRs, and iterates. Additional case studies include a Pokémon deck‑optimization competition where the agent iteratively refines strategies based on win‑rate thresholds. Throughout, he draws parallels to Blackboard and Kafka architectures and proposes an "experiential world model" where an agent’s identity and knowledge emerge from its immutable event log, akin to hippocampal replay mechanisms. The talk emphasizes the operational benefits of replays, rollbacks, forks, and provenance, arguing that log‑centric design offers more robust debugging and self‑improvement than traditional LLM‑centric agents.
Chapters
Hi, everybody. Thanks for coming. I'm excited to be here. AI Engineer World Fair has been so fun meeting everybody. But I'm here to talk about ActiveGraph, which is my new open-source experimental approach to building agents, which looks a little bit different than Maybe you've been building agents. It's definitely experimental. The idea is more to give you, inspire you with some potentially new ideas. Agents are awesome, but long-running agents break. And if they're so awesome, why am I still building them? They should build themselves. Let's build the simplest thing that can build itself has basically been kind of my research theme for the last 3 years since I did Baby AGI back in March of 2023. So that's Over 3 years ago. If you were there at the time, it was crazy. It went wild. It was covered by media. People thought it was going to work. It didn't work at all. Over the course of 3 years, I've done 9 iterations of Baby AGI with less fanfare, but every time just experimenting on how do we get autonomous agents to actually work, usually with the theme of self-improvement. If you go to Baby AGI Wiki, you can see earlier experiments. In this process, I kept coming back to graphs, and I've had a couple of projects. Earlier, I did one called Instagraph and Mindgraph that was like pre-GraphRAG RAG. I did some code graphs, function graphs, log graphs, and since then, it seems like a lot of people have started using graphs to build agents. And so, in addition to that, I've actually gotten to invest in a good number of agentic companies, some of which I'm sure you recognize through my fund, Untapped Capital, and I also have an agent fund. But yeah, that's me. Yohei, VC by day, builder by night. You might recognize this face more than this face. Yeah. Um, ActiveGraph is an event-sourced graph runtime for building auditable agents. Um, I have a paper, that was my first arXiv paper called The Log is the Agent, but I'm here to explain it. Um, so today most people build agents around the LLM. You start with the LLM, you add a response API, you give it tools, you add memory, and then you make sure you log everything correctly, which can give you, you know, all the benefits that ActiveGraph will give you. But Active Graph asks, what if you built around the log? Now, what does that mean? It means not everything the agent does, but more importantly, every change to the agent, right? Nobody here is using the same agent they were using a year ago, and the agent you're going to use a year from now is going to be different. And a lot of people, what the agent does and how the agent changes are tracked in 2 different places. But I'm saying let's flatten that down into a single immutable event log. And this is the ground truth of the agent. And this projects a sort of graph. This is the state of the agent. And what I mean by that is, for example, a prompt can be edited multiple times, but you might have, you know, a master prompt that gets used when you're, you know, when you query the graph. And then on top of this, you attach something that I'm calling behaviors. Behaviors are, react to graph changes, and then they emit events. Which then in turn updates the state of the agent, which might trigger new behaviors. LLMs don't talk to each other in ActiveGraph. They all communicate through this shared state, and that's what makes it a little bit different. Behaviors can be deterministic or they can include LLMs, which is, which is how you build this agent. And you get this beautiful typed event log. That's the source of truth about everything the agent did and everything, every change that's happened. Which means, oh, actually, whoa, shoot, I just, I jumped ahead. So in addition to that, there's a concept called policies which determine how the graph can be modified. I'll come back to it. But for example, things like a source article that you found in research, you might be fine with adding, but if you're changing a prompt, maybe you want human in the loop. Or if you're changing a fact, you might wanna make sure there's no contradicting facts. So there's these things called policies. And again, I'll show some code examples. But yeah, in the end you get this beautiful typed event log. which gives you replays, it gives you rollbacks, and it gives you forks. And this comes natively when you start building agents with ActiveGraph. So this is the kind of LLM-centric versus log-centric way of building agents that I'm going to be talking about or showing you code for. And I'll specify that this is not a harness. It's a runtime, and you can actually rebuild most of the common harnesses on top of it. You're just forcing every single communication to communicate through the shared state. So at the highest level, right, when you're building with agents, messages feels like the kind of core unit that you're seeing often, but we're gonna replace that with logs. Logs are gonna be the core unit you're gonna build around. That's what you're gonna be reading. That's what you're gonna be looking at. These are typed logs, again, immutable, clean. You can't edit the graph. These are just kind of basic rules. Just emit events. You can have the add object, which is an event. emitting. But yes, you can query over the graph. And again, I'm flying through some of this because I want to get to the fun parts, and all this is in the documentation. Behaviors listen to graph changes and emit events. So this is a behavior called a planner that triggers on a goal created, right? And then it adds an object, adds 2 task objects and a relationship object. Research, write memo, 2 tasks. And then actually behaviors can actually live on edges as something called a relation behavior, This one has an unblock relation. So basically when the research is done, you can write the memo, right? And behavior subscriptions can be pretty complex. They can be graph queries. So this one says on object created, if the, if the object type is a claim and this claim contradicts another claim, we're gonna trigger the contradiction detector. And these can be more complex than this. It can have, you know, confidence percentages baked into it and, And then on top of that, there's another concept called views. Uh, context management can be done programmatically as basically a graph query. It's a, it's, you basically grab a subset of the graph, which makes it available to that behavior. You can still do other types of context, uh, context management, but I felt like this kind of graph query as context management just felt really elegant. Candidly, I'm not the one writing the code, but AI seems to be pretty good at figuring out how to do it. And, you know, earlier I talked about policies. So some graph changes require a proposed patch before approval. Again, this is how you, these policies kind of give it the control on what it's allowed to change by itself, what kind of changes require certain tests. And I'll give a few examples in a bit, or if you want human in the loop, right? And you have these kind of policies that determine or define what the, what these rules are. And when you bring it all together, you get these kind of object schemas, tools, deterministic behavior, LLM behaviors can be assembled into something called a pack, right, with a pack policy. And that's how you build a harness on top of ActiveGraph. And these— and all of this together is— and I'll have a couple of examples later— are modular and they can be combined. But you're not just adding skills. It is much more complex, actually pretty unintuitive. I would never write code myself with ActiveGraph, but again, AI seems really good at it. And just on like event types are fixed, you can add custom events, objects are user-defined. I only added that because someone asked me that question when I was showing them these slides, but I think that makes sense. So the old way, you got the while not done if loop. The new way, or at least my new way, you have a whole bunch of behaviors that don't talk to each other, that just monitor the state. So it's inspired by, Blackboard architecture from the '70s or '80s, or more recently Kafka. Whole bunch of micro workers communicating through a shared state. One of the challenges, at least back when Blackboard was around, was that it was really unintuitive to write, and the workers were very slim and deterministic. But now AI writes the code, and the workers can be very powerful because they have reasoning capability. This is a React agent on ActiveGraph. React agent was one of the earlier agent kind of architectures. As you can see, It's a look— it actually works the same way, but on goal created, you add a thought. On thought created, you trigger the reason function. So again, this is just to show that you can build any harness on top of ActiveGraph. It does look different because they're not communicating with each other. And so to see how well this can work, I've been running a lot of experiments. The first one I did was, can I use the log itself as memory? So this is not pure vector RAG. It's actually leveraging the structured log so it knows which which message was before what, plus embedding the actual messages within the log. I did this on LangMemEval. I embedded the query. There was no semantic ingestion, no fact extraction, no entity extraction, but I just embedded the query, looked for relevant messages, grabbed a couple messages before and after, made sure it fit into the context, and it actually did pretty well on LangMemEval, right? Like, a lot of the data in your memory actually overlaps with the memory, uh, the data in your log. Actually having them the same actually kind of makes sense and makes sure they don't separate. Um, I did try another couple other experiments on adding kind of semantic congestion to improve the score. I was able to do it, but candidly, um, I could put more effort in to try to increase that, but I jumped on to the next experiment actually. But in that process, one of the biggest fun surprises was, I don't know if you've run LongMemEval, but you have to do like 500 questions. And then one of the runs, uh, my API key ran out like I was like, oh, shoot. Okay. So I updated the API key, said, okay, let's rerun it again. And it just rolled back one and was like, all right, we'll just start from question number 353. And I don't know if you have, but I've built a lot of agents where the API key broke or something, and I had to rerun the long agent from the beginning. And that just has not been my experience since building with ActiveRaf, which was a very fun surprise. I built a couple reference agents. Now I have this runtime, let's see what I can build. I asked Replit to build a coding agent on top of ActiveGraph, and as a result, it came with, you know, event log graph. And again, I'll say this, you can do this with, you know, things like LangSmith. Thing is, I don't— I didn't have to think about it. I just had to ask my coding agent to use ActiveGraph, and this event log and graph came natively. Same thing with research agent. I just said, just build a deep research agent on ActiveGraph, and it came with this beautiful, you know, had an event log and a graph of like where the evidence came from, what contradicts each other. And again, I didn't have to think about it. I just asked my agent to build a research agent on top of ActiveGraph, and this is what it ended up looking like. And then I realized, okay, how do we get this closer to like an OpenCLAW or HERMES? So I played around. I have this thing called ActiveGraph Packs, which is a core pack, a tool pack, a secret pack, a memory pack, an identity pack, a communication pack, a chat pack. So now you get to kind of get the idea of how I'm trying to build agents on top of ActiveGraph. And each of these packs have object types and behaviors. Again, probably feels very different from the way you're building agents, but I feel like it's actually pretty elegant. You can just take a memory pack and replace it with another memory pack. And it's not like skills, but like the objects and the rules and all of them are bundled as a pack. And you attach these packs together to create your agent. Then I jumped into what I really wanted to do was start playing with self-improvement loops. I did a project called Regimes. I did— that was in paper number 2. This one was a really controlled self-modification. Claude code called it Regime to Scene, but basically we classified the type of failure, and then based on the failure it classified, it was allowed to edit a specific part of the agent. Again, I did this on LangMemEval. The loop was, I think, doing about 20 questions, looking at the answer and questions, seeing where it failed, Failed, trying to self-modify, trying that on 50 different questions, see if the accuracy actually went up, and only if it went up, it would accept it. So that was kind of the proposal patch that started happening where it would do, after proposed change to itself, right? This is essentially the agent forking itself, proposing a change, doing a static gate check, a sandbox gate check, and then making sure it actually impacted the result and only then accepted a change. And for these loops, it would loop like 8 or 13 times, but only accept 4 or 5 of those patches. And it actually did have, you know, modest but like statistically significant improvement on LongMemEval scores. And not only did it know what worked, but it also knew what didn't work. At this point I was like, okay, can I get ActiveGraph to just research ActiveGraph for me? So I built lab, ActiveGraph lab, which is reading all the blog posts. So everything I've shared has a blog, a GitHub repo. And this lab is reading all of that to come up with new ideas, asking me if it can run it. And if I say yes, it'll run the experiment. And then it'll write a blog post about it. It actually did find an error in its own code, asked me if it could fix it. It wrote the PR and then I just merged it. So it's early, but it's starting to work. The lab is self-improving. It also figured out that it looked at ActiveGraph packs and was able to just install a pack into itself and then wrote a blog post saying packs are modular between repos. What's I was like, I didn't know that. That's great. And then I got distracted when I saw this Pokémon trading card game competition on Kaggle. As you can see, I'm all over the place. But you have to submit this deck in a deterministic agent, not with an LLM, and they compete in this Elo-style competition. So my decks are, you know, every hour they're battling a new competitor and their score goes up or down. And I felt like this was a pretty good test for seeing if ActorGraph could help me increase my score. And I used, you know, Claude Code and Replit, and we did about 80 different passes to like try different things and increase our score. Yeah, it might not make sense if you don't play Pokémon, but these things like, let's try adding a couple energy cards seems like a very casual ask. And my agent, probably because I think because I'm using ActiveGraph, would say, okay, sounds great. Let's run 200 simulated games against 3 reference agents. And then if the win rate increases by X% and there's a, you know, whatever Wilson score above 90-something, then we'll accept that as a change. Change. And I basically did this like 80 times, and each time it came with this like beautiful report of like why it worked, what it did, and what the verdict was. So out of those 80 passes, it probably accepted about 20 to 30, and the score did slowly improve. I'm still at like 27%, so I don't know if I can get higher than that. But what was most interesting is how much— how well the agent understood experiments we've tried before that didn't work. And that was a very different experience 'Cause I've done a lot of YOLO agents where you just like keep trying things and then it works. You're like, yeah, but then I don't know the stuff that we tried that didn't work. But now when I'm building with Actigraph, it tracks all the things that didn't work because it's forced, because I have this policy that says, here are the change— here, here's what we have to do before we accept a change. So some of the pleasant surprises, most of which I mentioned, but AI does seem better at architecting this than LLM-based agents is just my personal experience. And, you know, some, some people, you'll have to try it yourself to see. But if you think about it, LLM-based agents are like 3 years old. But if you look at, again, Kafka, Blackboard, this like micro-worker communicating through a shared state, there's decades of conversations about how to make that work better. And my hypothesis is that that's in the training data, and there's just much less training data around how to build LLM-based agents. Debugging shifted from session logs to ActiveGraphDB. Again, I didn't know it would, but when I, you know, when my coding agent was debugging, it just started querying the DB instead of the session logs. 'Cause it's, everything is already logged very cleanly and typed and it knows exactly how it's logged. Packs can be loaded easily from other repos was a surprise. I thought I had to do extra work to make that happen, but just worked. No more starting long runs over from the beginning and I know what didn't work, which are some of the things I shared. Here's where I might lose some serious researchers, at least in the language I use. I don't actually know how to train models or anything, so I'll caveat that. But I'm building this, I'm starting to really think that long-running agents need not just a world model, like a predictive world model, but what I might call an experiential world model. The predictive world model feels more like the priors, right? And then if you think about the hippocampus, actually, it also does work like an immutable state, event log that projects a state, and then it feeds some of that state back into your priors through replays, dreaming, and sleep. And so, you know, I feel like some discussions kind of suggest that as models get better, like, the harness disappears, but I'm starting to think that's not true. I think we need both, is kind of the new hypothesis that's growing as I've been playing with ActiveGraph. And if you think about, like, you or me, like, you or me, like, we're not our reasoning capability, right? We're closer to our beliefs, our knowledge, and behaviors that are derived from our actual life experience. And if that's the case, and we're going to build agents inspired by ourselves, then maybe our agents should be treated that way too. Maybe the identity of the agent is derived from its own log. I would love for you to try it. You can just go, just say, look up ActiveRaf and build me something I would like to your favorite agent who knows you better than I do. And have it explain if it's, uh, uh, if it was helpful or not. Um, let me know if you try it or hate it or are building something relevant. Thanks for listening.
More from Yohei
Yohei Nakajima: How AI Agents and Building in Public Are Changing Venture Capital | Glasp Talk #57


AI & Identity, from East and West, with Yohei Nakajima, GP at Untapped Capital and BabyAGI Creator

AI Agents, VC Insights on AI, and Building in Public, with Yohei Nakajima, Creator of BabyAGI