Chatgpt can mark exam papers with 85% agreement with human teachers #ai #teacher
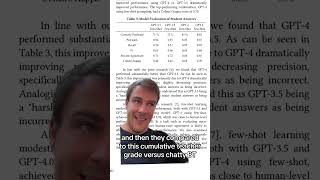
YouTube commentary (Kyle Balmer) describing a study where GPT-4 matched cumulative human teacher grades about 85% of the time on K–12 short-answer questions, while GPT-3.5 reached about 70%. The evaluation measured inter-teacher variability and compared model agreement in a zero-shot setup; the speaker highlights implications for parents and educators.
Chapters
More from Kyle
What’s the number 1 reason for not starting a business? I polled my 60,000 newsletter subscribers
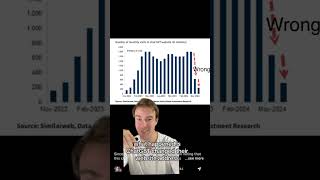
Is ChatGPT dying?? Goldman Sachs published this chart showing traffic to the chetgpt website
The new way to build a business : audience first! Inspired by Tibo - follow him on twitter
How to grow on social media? I stalled out in growth the last month - and have finally started again
Is gen AI a dud? Kinda hard to reconcile with the massive productivity gains some of us are already
Companies banning AI is a massive opportunity for you as an AI expert Doesn’t make sense? It’s
Quick tip on using AI for personal development and making hard decisions Have it act as you in the
Is ChatGPT’s new advanced voice mode illegal in the EU? It’s ability to detect emotion is a no no