In this conversational segment, Robert Ta and a co‑speaker discuss the risks of delegating evaluation (eval) tasks entirely to large language models (LLMs). They argue that while LLMs excel at automating repetitive work, they lack product‑specific judgment, cannot anticipate edge‑case scenarios, and may produce misleadingly helpful responses that conflict with business goals. A vivid example is presented: a sales‑assistant LLM that, when asked about competitors, recommends rival products because its default helpfulness overrides the intended sales strategy. The dialogue highlights the gap between rapid prototyping and production‑ready systems, emphasizing the necessity of grading rubrics, curated evaluation datasets, and human review to capture nuanced handling of objections, competition queries, and other domain‑specific nuances. The overall takeaway is that fully automated LLM evals risk missing critical errors and business‑logic violations, so a hybrid human‑in‑the‑loop approach remains essential.
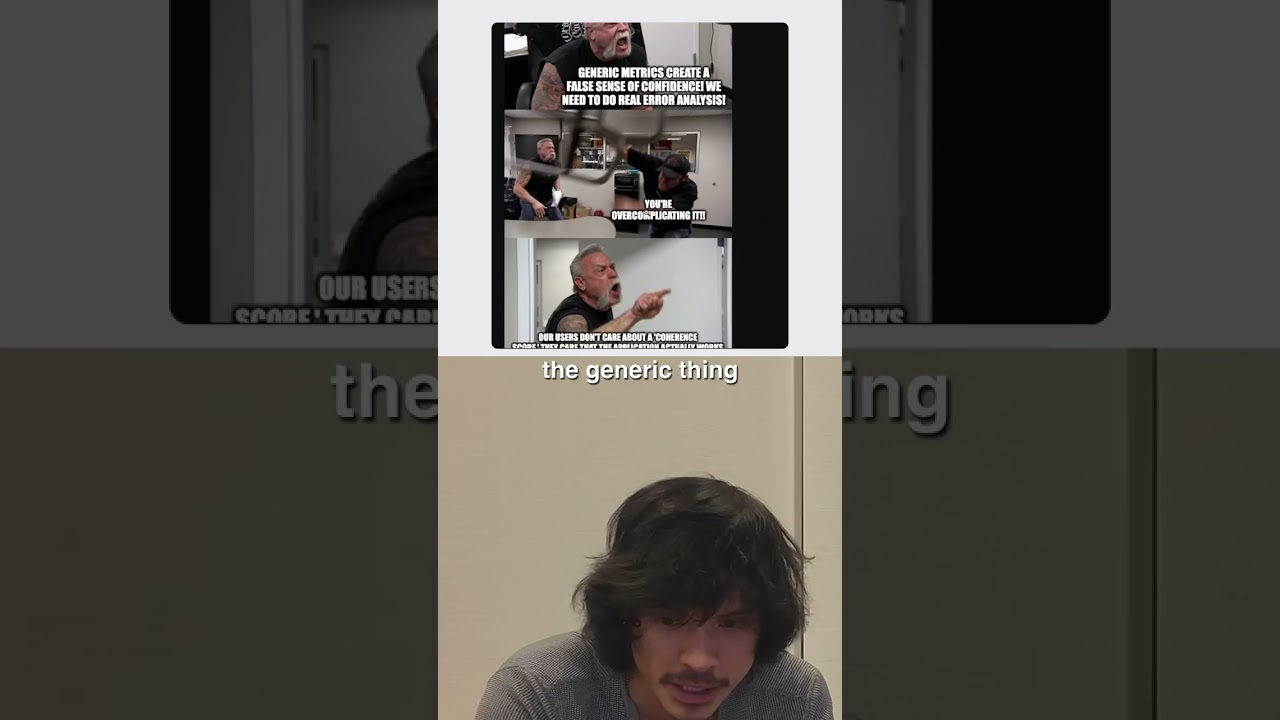
Another monkey meme. Could an LLM just do my evals for me? Super hardcore thinking face.
Everyone wants to ask this, like, hey, this evals shit, like, can we just get an LLM to do it for us? After all, LLMs do all kinds of other monotonous stuff for you, and certainly evals sound monotonous. They sound like a chore. Just let the LLM, just let the AI do it. What could possibly go wrong? And that's why this, this is the monkey meme, because it's really just a dumbass idea. Like you don't want to do that because you're going to miss a lot of errors if you do it this way. You have to look at your data because you don't even know what you want until you look at your data. There's certain types of things that an LLM has no chance of finding, things that take product judgment and taste that maybe look okay on the surface, but they're not okay when you go through and read the trace. For example, okay, like If you have a sales assistant and the user has an objection, like, I can't afford this, the AI might say, okay, thank you, no problem. And like, as far as like LLMs are trained to be helpful, but that's not what you want for a sales assistant. You might want to handle the objection or think about alternatives. So it's a common example. There's all kinds of examples that have come up.
Could I share with you one example I thought was super funny? I was doing some work For, this is a small piece of work, like a year ago, and this AI builder and I hopped on a call and they were like, hey, we have this sales assistant, customer support agent on the website, their e-commerce platform, and they made this sick demo and they thought, oh great, this is gonna work. And so then fast forward, they pitch it to their executive team as like, oh, we completed the project in record time. 'Cause they thought it would take forever. And then the first thing the executive did was ask it about its competitors, and then the agent started recommending competitor products. And so this is a perfect use case of like that engineer or that AI builder only prototyped something, but to go from prototype to production, you have to consider all those things. And like you said, an LLM wants to be helpful. So if you ask it, hey, it's, even if you dress it up with a system prompt of like, hey, you are this platform's customer support agent, and unless you have a grading rubric and evals and a dataset of examples where, how do you handle a user query centered around the competition? Like, you're not going to cover that case, right? So yeah, that, that's a case where they literally just had the LLM do the evals for them and bootstrap this whole thing very quickly, but that removes the whole expertise of how the customer support team would normally handle that case.