Why you shouldn't write 500 evals first

22 Oct 2026 · 1 min
0:53

In this brief discussion, Speaker A warns against the practice of creating a large number of hypothetical evaluation tests (e.g., 500) for a product or application. The main arguments are that evaluations are costly to maintain and validate, so time should be allocated to the most valuable tests. Speaker A advises prioritizing evaluations that reproduce actual user‑facing failures, which deliver immediate return on investment, rather than speculative scenarios. While it’s acceptable to keep some hypothetical use cases in mind, they should be turned into concrete, reproducible tests—especially if they involve competitor behavior—so the evaluation remains grounded in real‑world issues.

More from Robert

3:11
youtube.com

How To Decide Which AI Evals Are Worth The Cost

11h ago
1:04
youtube.com

Your LLM judge needs at least 50 human labels

11h ago
5:17
youtube.com

Why You Should Look At Your Data Before Writing Evals

1d ago
2:41
youtube.com

Why You Can't Hand Your Evals To An LLM

2d ago
0:52
youtube.com

This support bot recommended a competitor in the exec demo

2d ago
2:50
youtube.com

Why A 100% Eval Pass Rate Is A Bad Sign

3d ago
0:53
youtube.com

A 100% eval pass rate is a bad sign

3d ago
41:34
youtube.com

AI Evals Explained With Memes

4d ago
0:59
youtube.com

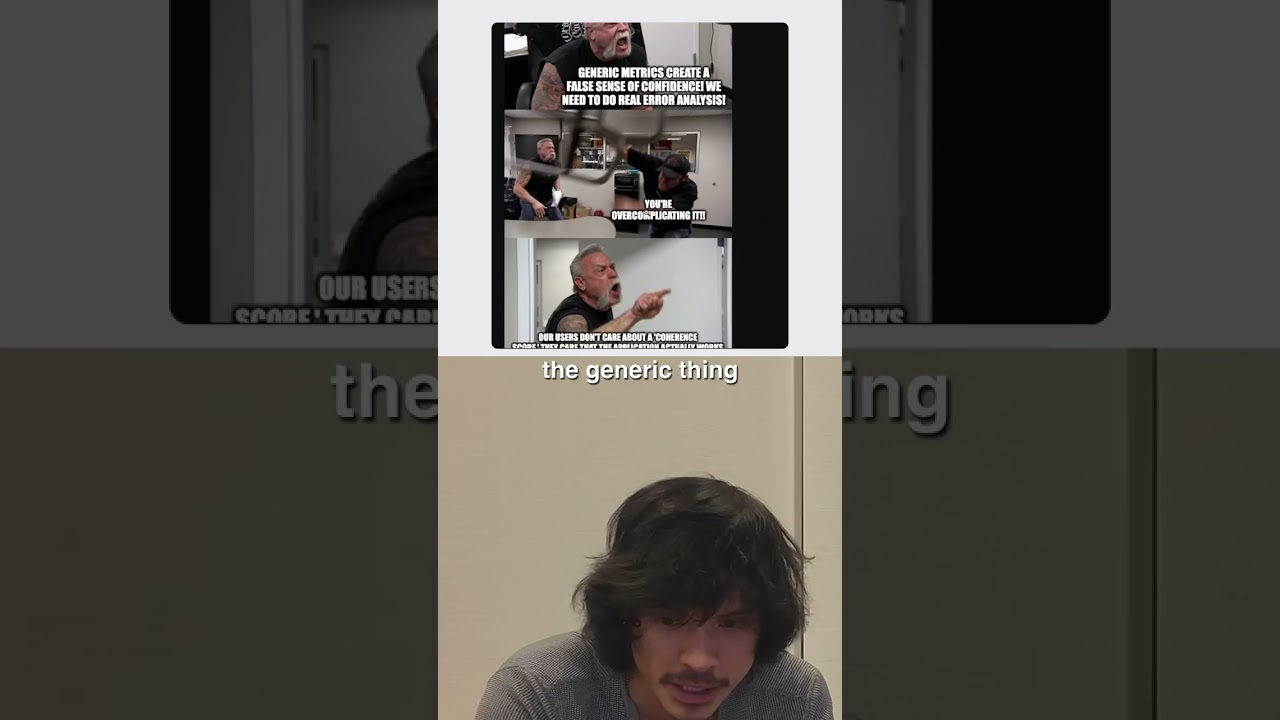
Your users don't care about coherence scores

4d ago
4:28
youtube.com

Why OpenAI Is Becoming the Power Company for AI Apps

5d ago
0:52
youtube.com

Beat big companies in the gap between 2 VPs

5d ago
See all content