
I Took Notes on Karpathy's 3-Hour LLM Masterclass — Here's Everything | part-6
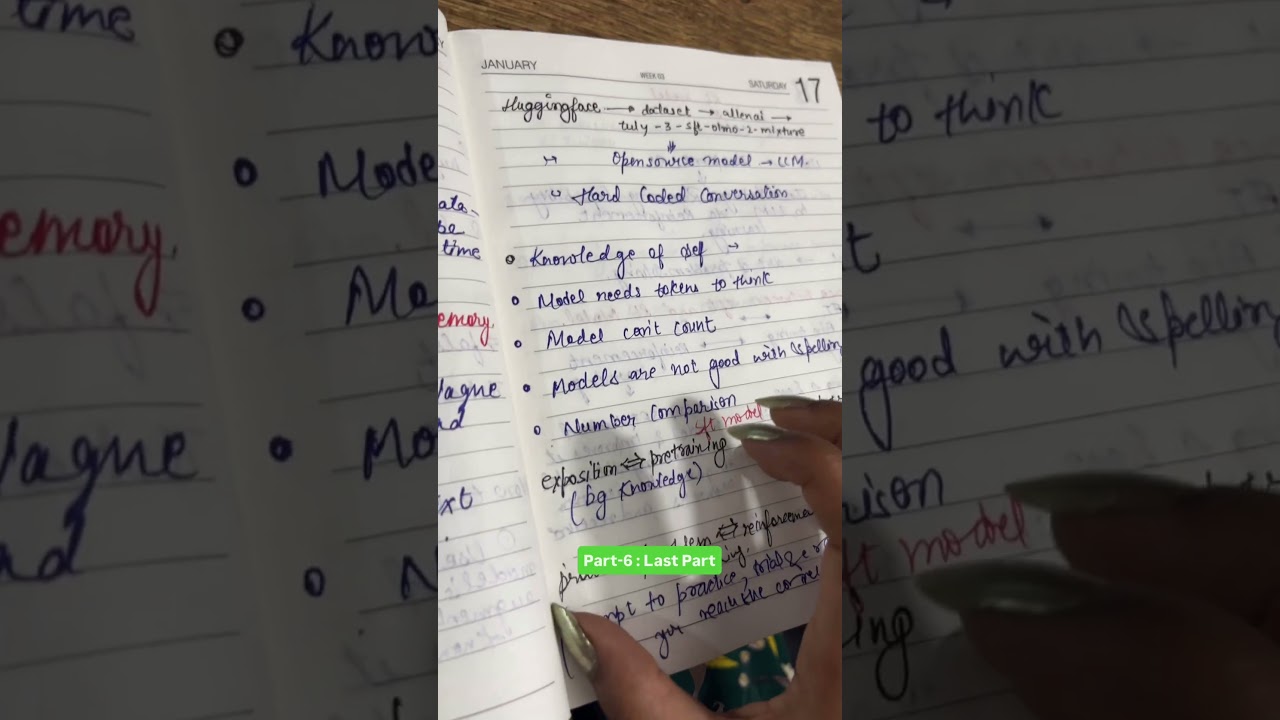
In this Hindi‑language monologue, the speaker reviews key take‑aways from Andrej Karpathy’s three‑hour LLM masterclass, focusing on practical insights for learners. The speaker explains that large language models (LLMs) have no self‑knowledge about their creators or internal state; they only understand token sequences, which limits their ability to count, spell, or distinguish numeric differences. To overcome these gaps, supervised fine‑tuning (SFT) is introduced as a two‑stage process: first providing background knowledge, then practicing with prompts and trial‑and‑error. The speaker contrasts SFT with reinforcement learning (RL), noting that RL relies on trial‑and‑error reward signals. Practical recommendations are given, including searching for the “DeepSpeed‑RLHF” paper on Google, using the “Art of Problem Solving” dataset to build a model, and visiting two websites (one for hands‑on experimentation and another for learning about LLMs). The video ends with a promise of additional resources at the end of the video.










