Andrew Feldman, Cerebras Co-Founder and CEO: The AI Chip Wars & The Plan to Break Nvidia's Dominance

In this in‑depth interview, Cerebras co‑founder and CEO Andrew Feldman discusses the company’s wafer‑scale engine, the trade‑offs between SRAM and HBM memory, and the engineering challenges of yield and power in massive chips. He contrasts the needs of inference versus training workloads, critiques algorithmic inefficiencies that waste compute, and explains how data‑center power constraints shape hardware design. Feldman also looks beyond the current transformer dominance, exploring synthetic data, future model architectures, and the role of AI in solving societal problems. The conversation touches on market dynamics, including under‑appreciated sub‑milliwatt chips for edge robotics, investment trends across the AI stack, and Cerebras’s competitive positioning against Nvidia. Business considerations such as cost structures, margins, the strategic G42 partnership, and long‑term vision for the next decade are also covered, highlighting Feldman’s ambition for Cerebras technology to power unseen applications and improve lives.
Chapters
Our AI algorithms today are not particularly efficient. In a GPU, most of the time it's doing inference, it's 5 or 7% utilized. That means it's 95 or 93% wasted. We won't be as dependent on Transformers in 3 years or 5 years as we are now. 100%. The fundamental architecture of the GPU with off-chip memory is not great for inference. Now, they will continue to do well in inference, but it can be beaten, and I think they know it. Ready to go?
Andrew Feldman, it is such a pleasure to meet, man. I've wanted to do this one for a while. I've heard so many good things from Eric for a long time. So thank you so much for joining me.
Harry, thank you for having me. I appreciate it.
Not at all. This will be a fantastic conversation. I have my pen ready. I feel like this is going to be a learning experience for me. I want to go back to 2015. What did you you and the team see in the AI landscape in 2015 that led to the founding of Cerebras?
We saw the rise of a new workload, and this is every computer architect's dream. We saw a new problem to solve, and what that means is maybe you can build a new machine better suited to that problem. And so in 2015, and the credit goes to Gary and Sean and JP and Michael, my co-founders, they saw on the horizon the rise of AI. And that what that meant was there'd be a new problem for computers. That what the AI software would ask from the underlying chip, the processor, would be different. And we came to believe that we could build a better machine for that problem. That's what we saw. You know, obviously we didn't see it Exactly right. I underestimated it. You know, this is my 5th startup and the first time I underestimated the size of the market by a lot. Um, you know, it, uh, but what we did get right was that this was going to be big and it would put a different type of pressure on a processor and that it would put pressure on the memory bandwidth. That it would put pressure on the communication structure. So that's what we saw. We dove in. Uh, it's been an extraordinary 9 years.
It's been an extraordinary 9 years. Can you just help me understand how does the movement into an age of AI change the requirements from a chip perspective of what is needed for a provider and how that then resulted in how you built Cerebras?
The way to think about a, A chip is, it does two things. It does calculations and it moves data, right? This is what a chip does. And sometimes along the way it stores data. And so what AI presented was a very unusual combination of challenges. First, the underlying calculation is trivial. It's a matrix multiplication. And an FMAC can be developed by any second-year electrical engineering student. So you say to yourself, holy cow, this has a huge number of very, very simple calculations. The hard part with AI work is results and intermediate results have to be moved a lot. And therein is the most complicated part. They have to be moved to memory and from memory. And they have to be broken up and moved among GPUs. And what we saw was that this was gonna be the hard problem. And that if we could solve for that problem, we would build an AI computer that was faster and used less power.
[Speaker:ANDREW FELDMAN] When we think about how we're gonna build and what we're building for, there's to me kind of a couple of core elements, which is like where you are gonna focus. Are you focusing on, you know, fine-tuning? Are you focusing on, you know, training? Are you focusing on inference? The three. You chose all three.
Yeah. Why?
And I'm sorry for my base questions, but I thought like GPUs were specialized towards training and they weren't specialized towards inference. Can you have a mono architecture that does three best?
The first step in, in computer architecture is deciding what you're not gonna do.
Right?
That's what are we not going to be good at is really the first important question. I think to answer your question, you say, is the computational work for training from scratch different from fine-tuning? And the answer is it's not different. It's approximately the same. Now, inference and training have some different requirements. And generative inference in particular has some very challenging requirements on exactly the communication dimension that I mentioned. In generative inference, you have to move all the weights from memory to compute to generate a single word. And you have to move them again to generate the next word. And again and again. So if you have a 70-billion-parameter model, not a giant model, and each weight is 16 bits, you're moving, what, 140 gigabytes of data to generate one word. This is an enormous amount of data movement across memory. And that's called— what's consumed, that needs, is memory bandwidth. And if you have an architecture like we saw in the GPU, that is your fundamental limitation. It's a fundamental architectural limitation. And that was what we went to Wayfarer Scale to solve. They use memory, a memory called HBM. It's a type of DRAM and it is phenomenal memory, but it's slow. It is slow and high capacity. And when they set the architecture for graphics, that's what you wanted. You didn't have to go back and forth to memory very often. SRAM, on the other hand, is unbelievably fast but has low capacity. And so we wanted to use SRAM, but if you build a normal-sized chip, you can't hold a model. And so by going to wafer scale, we were able to put down a huge amount of SRAM and get the benefits of speed and enough capacity. If you build a normal-sized chip with SRAM and you want to do a 400 billion parameter model in inference, you might need 4,000 chips. Or if you want to do a DeepSeq 671, you might need 6,000 or 8,000 chips. What an administrative nightmare.
I'm sorry, Andrew Feldman.
You can keep it on as much as you can on one wafer, two wafers, or four, or 10. You get all the benefit of the SRAM. And because you've been able to use the wafer, you get this tremendous capacity as well.
Can I ask you first, I totally get you on HBM and kind of the slowness of it. Why is it then that bluntly so much of the market just continues to use it and 40% of NVIDIA's revenue is using their, their chips for inference?
Look, uh, there wasn't really, unless you went to wafer scale, there wasn't really a credible other choice. Um, that this is the way GPUs had always been made. It's called a graphics processing unit, right? That's the way they were built. And it was part of their advantage against the CPU, was they were built this way. But now they're dedicated chips like ours. And what used to be their advantage is now their weakness. And that's a fun market to be in when over a very short period of time, what you're good at becomes your weakness.
With a market cap like they do, and with Jansen as good as he is, which I'm sure we both agree with, they must know that one of the great—
they do know this. They do know this. There's not a lot of choice. Well, I mean, look, A, they don't make memory, so they're a consumer of other people's memory, right? And that's SK, right, the Hynix guys, or Samsung. I mean, Micron— there are only so 3 or 4 or 5 companies that make huge amounts of of memory. Not many choices. But it's part of a complex architectural trade-off. You know, the flip side, you could say it's worked really well for them, right? Look at where it's taken them. But in comparison to those of us who do wafer scale, it's a small set. It's a set of one, us, right? We have real advantage against them on inference.
How do LPUs fit into this? We've got HBM, we've got SRAM with you and, Blatney having many more of them to make it work and scale. Where do LPUs fit into this mix?
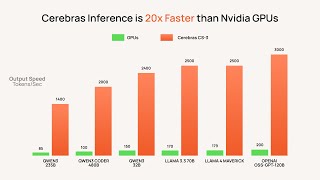
In our business, there are a lot of ways to skin a cat. And, you know, our way is different than NVIDIA's way. It's different than the TPU. It's different from Cranium. It's— they're different. Right now, and every day since August 26th when we launched inference, our way has been the fastest way across a whole set of models tested by artificial analysis and others.
Can I ask, when we think about kind of that speed, I am interested, you said that kind of you're one of one with wafer and kind of the architecture associated. What does that mean in terms of cost? With such efficiency, is it inherently more expensive? And what does that look like from a cost profile?
This isn't our first dance. We've been building computers for a long time. And when you make a choice like wafer scale, you have to weigh the trade-offs. We use less power. We use less power because one of the most power-hungry things on a chip are the I/Os, right? Are moving data off chip. And so if you are moving data off chip frequently, you're using more power than if you can keep it in the silicon domain on chip. So we knew we would use less power. We knew if you went to wafer scale that you had to solve some problems that people said were impossible to solve, like yield. So we had to invent techniques that allowed us to yield wafers. In fact, we invented techniques that allow us to yield as well or better than others who are building much smaller chips.
Can I just interrupt and ask, what is yield and why is it impossible to solve?
Okay, a wafer become— begins, it's a 12-inch diameter circle, a slice of silicon. And your chip is punched out of this the way your mother might take a cookie cutter and cut out cookie dough. And during the process, at some point, Just like your mom might have done, she lifts up the edges and all the little bits are removed, and what's left are just the cookies. Those are your chips. Um, now what happens is there are a set of naturally occurring flaws, and that's like your mother closing her eyes and throwing up a handful of, of M&Ms. Now, the bigger the cookie, right, the higher probability you hit an M&M. The bigger the chip, the higher the possibility that you have a flaw. And traditionally, what you did when you had a flaw was you threw away the chip, or you sold it as a less valuable part. You shut down part of the chip and sold it as a less valuable part, something called binning. So every wafer is going to have flaws. The bigger your chip, the higher probability you hit a flaw, and the more part of silicon is wasted when you throw it away. This is what everybody thought was known truth. And one of the things our team realized was that there are other ways to handle flaws. Like, what if instead You built your computer, you built your processor out of hundreds of thousands of identical tiles. And say there was a flaw. Say you just shut down that tile and worked around it. Say you had a row or a column of redundant tiles that when you needed them, you could just pull in. Now, that had been traditionally the, the technique used in memory making, and the memory yields are extraordinary. And so it occurred to us that if we could build a computer, build a processor built of hundreds of thousands of identical tiles, we could use redundancy such that when there was a flaw, we could just leave it there, shut it down, work around it and pull in one of the redundant tiles. And that had never been done in a computer before. And that's at the heart of our architecture. That allowed us to yield and deliver whole wafers. Nobody ever been able to do that in the 70-year history of our industry. Really, really smart people struggled. I mean, Gene Amdahl, one of the fathers of our industry, had a company called Trilogy that crashed and burned trying to do this. And we figured it out.
When you speak about kind of being the fastest and across all benchmarks being the fastest, what matters the most? Is it being the fastest? Is it being the most efficient? Is it being the least costly? How do you think about the stack of prioritization for your customers?
I think it varies. I think Look, if you go to get a cancer diagnosis on, God forbid, your mother or your wife, I think 93% accuracy is just plain not as good as 94% accuracy. And you pay a lot and wait another week to understand what the accuracy is, right? You pay a lot, right? Now, on the other hand, uh, if you want Llama 4.0.5b to generate data to help you tune Llama 7.0b, uh, maybe you can wait a few days, 3 days, a week, more. You don't— there's no urgency there. On the other hand, if you want an answer from Perplexity, right? You don't wanna wait 45 seconds for a search answer, right? You don't wanna wait in a chat, you don't wanna wait 3 minutes for R1 on GPUs to give you an answer. What we know is that in interactive mode, milliseconds matter. In interactive mode, what Urs Holz over at Google years ago showed was that you can destroy your user's attention with milliseconds of delay. So, being the fastest matters everything in that domain. So, I think what you have to do is be thoughtful and say, in some cases, being the fastest doesn't matter. We'll call those batch. Lots of maybe cheapest matters there. In other domains, there is no search if you got to wait 8 minutes to get an answer. That's not a product. When you go fast, a whole set of new opportunities open up. Netflix used to mail DVDs. That's what happened when the internet was slow. They'd mail DVDs. The internet doesn't—
I look young, Andrew. I'm not that young. I remember Blockbuster.
You remember Blockbuster, right? First, let's look at the history of that. You're exactly right. First, we used We used to drive to Blockbuster to get a DVD or a video. Then Netflix was mailing them to us. And then we got broadband. And there suddenly Amazon's a studio. It changed everything. And speed in inference does the same thing.
When we chatted before, you gave this great equation for inference. What was the equation that you gave for inference? Because it was really helpful for me in understanding.
It begins with the following. Um, training makes AI. That's how we make AI. And inference is how we use or consume AI. And so understanding how big the inference market is, is understanding the number of people who are going to use it, how often they're going to use it, times how much compute each use takes. And right now we are in this rare time where the number of people using AI is growing, the frequency with which they use it is growing, and the amount of compute used in each instance of use is growing. That's why you're getting this extraordinary growth. And that's why it's off the charts right now.
When we think about the distribution of resources between training and inference, what will that look like in 5 years' time? Because we've seen all focus go to training— well, not all, but a lot of focus go to training and not as much go to inference. What does that look like?
What we made until the middle of 2024, right? What we made in AI was a novelty. It wasn't very useful. Late in 2024, what we made began to be useful.
What was that check? What was the turning point?
I think the, if you look at the models, they, they became, I mean, ChatGPT was not really a technical innovation. It was a user, uh, user interface invention. And, but it gave more people access. But we, we didn't really right away know what to do with it. It was cool. Right? That's what I mean by novelty. Like, whoa, this is cool. But now if your marketing team isn't on an LLM, each person several times a day, they're not doing their jobs. That difference between novelty, it's cool, and this is part of everyday workflow. And that, that's what changed starting sometime in Q4 last year. And running into this year is AI became useful, not just to a select group in Silicon Valley, but to my dad, to my brothers, the doctors, to ordinary people, uh, who aren't buried in the, the Silicon Valley discussion. And when you get them, then the market is is ripping.
Do you not still think we are so incredibly early though? Going back to your point about how many— For sure. In 5 years' time then, where are we? Are we 100 times bigger? Are we 1,000 times bigger?
I think we're way over 100 times bigger. Yeah.
What does that mean in terms of what we need to equip ourselves to deliver? These are incredibly, uh, energy utilizing. It is incredibly difficult.
Our industry consumes a lot of power.
Yeah.
Yes.
And, and a lot of water.
Um, and some water too.
And we're seeing that come down. But are we equipped from an energy and a data center standpoint to deliver the inference requirements for a population that is as AI hungry as we are?
I, I think a couple things. I think the, the first thing is to admit that, that, that this is a power intensive problem. We, we consume, our industry consumes an enormous amount of power. The second thing to say is, therefore, the burden is on us to deliver exceptional value as an industry. I mean, that's— you take both the good and the bad, right? In order to make it worthwhile from a societal perspective to expend all this power, you better deliver the goods, right? We better use AI to find cures for for diseases. We better use AI to find a bunch of different— solve a bunch of different societal problems. So, that's the macro view. Do I think that we are equipped? I think we are in a very unusual situation in the US where we have plenty of power, but it's in all the wrong places. We have power in Niagara. We have power— what we don't have is power where you want to build data centers where we have good fiber. And what we don't have is a national way to relax the local regulations that make getting power difficult. And so, when you go to Silicon Valley, if you want to build a data center, you're dealing with local government and installed interests. And that is not an efficient way to decide if you want to build a power plant or put a new data center in. Especially if it's large. And I think those places that have ripped out some of that burden, in Texas for example, are getting a huge amount of data centers built.
You know, when I spoke to, you know, Jonathan at Groq before, he said there were a huge amount of data centers being built that were not actually really equipped properly. And that we've seen this massive supply of data centers that are really kind of done by tourists, so to speak. And that is a massive problem. And that the provisioning of these data centers isn't there. Do you agree?
[Speaker:ANDREW FELDMAN] I think the following. I think a data center is a construction project to begin. It's an access to power, and then it's a construction project, and it's got a design engineering component. I think there's been a huge push for new construction data centers. I think we will see, we don't know if they're going to be good enough. I think many of them will be fine. I think the guys who were there early were some of the Bitcoin mining companies, like TerraWolf, the guys at Crusoe and others, guys in Europe. They were early. Early in building buildings near low-cost power in order to run compute that used a lot of power. And they are some of the leaders now in some of the largest projects. Now, those are certainly not tourists. Those are extremely sophisticated data center builders. Now, sure, there's some tourists, but there are a lot of very, very knowledgeable data center builders building huge facilities right now. I mean, gigawatt-scale facilities, both domestically and internationally.
How do you think about how the cost of inference goes down with the surge of demand that we mentioned, you know, over 100x? Does the price reduce 100x? Does it follow Moore's Law continuously? How do we think about the ever-reducing price of inference?
Look, there are, uh, the cost of inference is built up of several pieces, right? There's the power and space that is consumed to generate the response, right? That, that's a data center cost. That's an OpEx item, number one. Number two, there's the, uh, cost of, of the, the computer. We can drive down the cost of the computers with each generation by driving up their performance, etc. But the other thing we can do is we can develop more efficient algorithms. Our AI algorithms today are not particularly efficient. There's a tremendous amount of room, uh, in a GPU. Most of the time it's doing inference, it's 5 or 7% utilized. That means it's 95 or 93% wasted. So over time, I think as an industry, we get better at things. We drive the cost of compute down, We can build more efficient data centers with lower PoEs. And our algorithms will get more efficient so that our utilizations on our now cheaper computers are higher. So you get a higher percentage of the maximum number of flops. You get more tokens per unit time for the same power.
[Speaker:ANDREW FELDMAN] When you look at the inefficiency of the algorithms, as you mentioned that, and what that means for the utilization of the chips, Why are people suggesting that we're at scaling laws already? That seems to suggest that there is so much room for improvement. How do you think about what you just said in conjunction with the idea that scaling laws, we're hitting this asymptote point? How do you reconcile the two?
I think that, uh, I don't think there's a lot of, uh, debate among, uh, sort of senior ML thinkers that we have tremendous room for algorithmic improvement. I don't think there's a lot of debate there. There's even debate about whether the scaling laws are over, whether we've run out of— ran out of mojo to keep making data or gathering data to fill these ever bigger models. But OpenAI's work on O-1 shows me that the scaling law, certainly for inference, are fully functional, right? The more compute you put on inference, the better answer you get. And so I think that, you know, many of the leading models are now MoEs, right? So they're not presenting all of the weights to each token. That's one way to do it. Present the important stuff, not the unimportant stuff. There are other ways to do it that we will invent and learn over time. But, uh, I, I think we know the— we have, we have sort of human models that aren't all-to-all connected. Many of our models today are all-to-all connected. That, that's a lot of unnecessary connections, connections that don't produce anything that we still end up doing math over.
I'm sorry, what does all-to-all connected mean?
In many of the layers in a neural network, every element is connected to every other one, and that's not the way actually the, the learning happens. Uh, some are more valuable and some are not valuable at all, right? And imagine you get— you're going to read 50 books, you want to learn something, you can read all 50 books, or you could read 3 books that are really important, or you could read summaries of the 3 books that are the most important. The problem is we don't know which they are at the beginning. And there's a process that you could learn. There's things called dropout and all these other techniques to, to use sparsity to help, help solve these problems. We are early in the evolution of AI. Plays right into this point that we'll get better at these algorithms. Transformers aren't the end of the world. We'll get better. Better will mean faster, more accurate, and more efficient. And I think that's what's exciting about an ever-changing industry. I mean, that's why I'm not in all these other industries that don't change quickly. Same 9 years ago as they are today.
But this show is kind of strange for me because I speak to a lot of people and they think about the three pillars and they're like, you know, compute algorithms and data. And, you know, actually a lot of the common refrain is that actually we're very far along in all of them. And that has been the refrain. And when I hear you, it's like, actually, it's very exciting. I think they're wrong.
I think they're wrong. I don't think we're very far along. And it's very difficult to say that we are early in an industry, but we're far along on all its underpinnings. Then what, right? I think we are early in all of them.
If we just take them one by one, in 5 years' time, how much synthetic versus human data will be used to train models? If you were to put a percent on it.
Almost all synthetic.
And the utility value of synthetic is the same as human?
I think this, I think when you teach a pilot to fly in a simulator, right, there is a lot of potential data. That isn't very useful in teaching her to fly. Right? They've spent a lot of time going straight, doing nothing as a pilot. Now, takeoff and landings are where you want to spend your time. And that's why when we put them in simulators, that's what we have them doing. And in simulators, we can create data where engines blow, where there are a whole set of problems where learning can take place. That's simulated data. And in the same way, as we think about creating data, whether it's for self-driving, whether it's for other forms of AI, what we want is the data that's hard to gather, right? Otherwise, we just have a bunch of data of people driving straight on a freeway. Not, not difficult. We've been able to do that for a decade. What we want is an unprotected left turn in the snow. It's snowing, it's hard to see, you've got an unprotected left turn. That's a difficult thing. And you want that thousands of different ways, millions of different ways. That's where the synthetic data comes along, is to use it to fill in the empty parts where it's really expensive or painful to get that type of data. Think of the pilot, right? You want them spending a huge amount of time on things that are rare in their training. Same with a surgeon, a huge amount of time on things that are rare. Most of the time, it's carpentry. But their expertise is only when it's rare. Something happens, the unexpected occurs. That's when their mettle is shown. And I think we will get better at synthetic data by a great deal.
[Speaker:RAOUL PAL] I love it. I get it from a consumer perspective and from an expectations perspective. If we move the needle on compute algorithms and data, what does that mean for the experience of AI?
It gets faster, cheaper, faster and cheaper. Faster and cheaper is the first answer. The second is, is when things become faster and cheaper, new applications emerge. So it, it's used everywhere, right? When, uh, when computers became faster and cheaper, suddenly they were in cars and then they were in your pocket. And then they were in your dishwasher and in your TV. And right, that's what happens. I mean, we— 30 years ago, you're like, I need a computer, my TV? You kidding me? I need one in my pocket. Now you've got powerful computers in your pocket, you've got them in your TV, you've got in your kids' toys, you've got in the car. That's what happens. Diffusion of innovation accelerates. When you make things faster and cheaper.
This is Jevons paradox and Thatcher's belief there, no?
Yeah, yeah, that— I know in the VC community, you got to cite 19th century English economists. I think Jevons— I'm English. I'm English.
Come on. If I'm not allowed to cite an English philosopher, what am I here for?
Look, I think—
Are you just like, oh, these fucking VCs, just being like, oh, Jevons paradox.
That's right. It's like, look, Make stuff cheaper and faster. There are no, there are very few examples in our industry, actually none in compute in 50 years in which by making things cheaper and faster, the market got smaller. Market always gets bigger. Um, always.
Can I ask from an architectural standpoint, you mentioned Transformers there. Is there a world where we move past Transformers? There is a world.
Transformers. 100%. We, we won't be as dependent on Transformers in 3 years or 5 years as we are now. 100%. They're not the end-all be-all.
Why is it? What will replace it? And what does that look like?
I don't know. I don't know whether they're going to be state-based models. I don't know whether they're going to be other types of models. But what I know for sure is that innovation doesn't stop. And that the transformer has some weaknesses that people are desperate to overcome. There's a quadratic effect in the attention head. There's all sorts of things that could be improved, but it's pretty darn good now. It's the best we have. And that's what you run with. You run with the best you have. And the minute it's not the best you have, you drop it in favor of the best you have. And I think that's what we're seeing. We're seeing— I mean, the number of innovative companies designing models is large. And what DeepSeq showed us is you don't need 5,000 people. And, you know, billions of dollars of gear. You can do it with 200 smart people and more gear than Deepseek said they had, but less gear than others had.
Were you very impressed with Deepseek, and what impressed you most?
I think it was a result of focused engineering, and that impressed me. It was designed to be better, and, uh, They weren't confused about being sort of model intellectuals, or they weren't confused about whether it was important to break new ground, or— they were interested in being better. And from an invention standpoint, that's a little boring. But from an engineering standpoint, That was sweet effort. They really built a model that was just plain better at many, many things, and that's cool. I, I like good engineering projects. Now, that they chose to announce it right around Trump's inauguration and the politics of it, that, that's all a separate matter, and, and we can talk about that later. But, um, is distillation wrong?
People—
no, I don't think distillation is wrong. I mean, is summarization wrong?
I'm a VC, are you kidding me? That's what we do.
If you didn't summarize, you wouldn't know anything, right? That's right. That's exactly right. I don't think distillation is wrong. And if distillation is wrong, then certainly using people's copyrighted data is wrong. Right. That's the problem. The problem is, Right? Is you gotta be a little bit consistent.
Uh, well, Sam's been a guest many times and we hope he will be again.
So I don't know why I'm getting these two. No, I'm, I'm, I, I think neither are wrong actually, but I think you have to be consistent.
Well, the thing was with it, bluntly, Deepseek is open. So everything that they did innovate on, OpenAI can learn from and take too.
That, that's, look, I think there are few examples of an open source anything having this sort of immediate impact that model had. I mean, that model had a giant impact in a technical community of really smart people. And there are very few examples of other open-source software projects that had that type of impact in that amount of time. Usually, you're in the business of betting on these guys. They ramp up and they, oh, look, 10,000, now it's 100,000. Users. It's now a million users. We better, better start a company around that, right? Get those grad students. But this had a loud boom in the industry immediately. It's like, whoa.
The thing I have to think as a venture investor is where is enduring and defensible value, simply, and how do I get in early and build that over time?
In hardware, Harry.
Well, this was my question, which is like, well, I mean, you have to be a very smart investor like Eric Rischier to do hardware. To be clear. But on the model side, do you think there is value when you look at the sheer number of players, all with relatively comparable models?
I think to, to demonstrate enduring value, you need both immediate value and a trajectory for more. Right. I think the problem is in some industries you are capable of demonstrating leadership position for a short period of time. Then someone else, maybe the next generation, they generate the next, and the next generation, the next. I think that ends up in the software world being, you know, you're competing against other people's release cadences. You're 4 months ahead, they're 6 months. If that's really where you are, there's not a lot of value. But if you can stay at the top over years, even if you're not the best, even if you're top decile over years, and the people above you are changing constantly, I think there's a lot of value. I think very large Silicon Valley companies have been built. With not the most compelling technology. It might have started the most compelling technology and then it got to a point where it was good enough. It was easy enough to use. That's when you're at the mature market. But we're a long way from there right now. Right now, we are in the early phases. You characterized my position exactly right. Data, compute, algorithm. I think we have a ton of room for improvement on all of them.
But you said that, you know, compute and hardware, that's where the value is. How does that value distribution shake out? You know, we've obviously got the £800 gorilla that is Nvidia. How do you think about how the distribution of value shakes out in hardware and in compute over the next 5 years?
Historically, um, One of the barriers to entry was the capital intensity of a project. And in the world of building chips, there's both scarce resources in expertise, and it's very expensive. And historically, it hasn't fit very comfortably in a software company. And the things that software, modern software companies value are not entirely conducive to chipmaking. And so, when I look down the road, I mean, I think who has endured in much of infrastructure tech People who build systems, Cisco, Juniper, endured. Chipmakers have endured. There's a reason that Apple and Nvidia are among the most valuable companies on Earth. There is, what they do is hard. And I think it's, that's why it's worth challenging, right? That's, if it weren't hard, if it wasn't enormous and difficult, You know, why spend time being the underdog and, and challenging it?
A lot of people place defensibility around NVIDIA's kind of CUDA lock-in. To what extent is that real versus hype?
In inference, it's not real at all. There's no CUDA lock-in in inference. None. Uh, you can move from OpenAI on an NVIDIA GPU to Cerebras to Firework Service on something else to Together to Perplexity with 10 keystrokes. I mean, anybody who actually uses AI knows there's no CUDA lock in it. I think there is— there was a fundamental effort to disintermediate CUDA first by Google with TensorFlow, and first by some grad students with Caffe and some of these early efforts, but later by Google with TensorFlow, and then Facebook, or Meta, with PyTorch. I think today most, most AI is written in PyTorch. You ought to be able to compile it and run it on, on your hardware. Uh, I, I think NVIDIA has many moats. I think when you are a dominant market share leader, that in itself is a moat. That you're the default solution is a moat. That everybody learns to think about AI in your structures, those are moats. The software, you know, it— compilers are hard, but they're tractable.
I completely agree with you in terms of kind of being the leader is a motion itself.
It is.
When you—
it's never talked about that way. And, um, I mean, look at it this way.
OpenAI, in that same— it is the leader. Everyone's mother knows ChatGPT.
Therefore, let's look at Intel, right? Intel has made— until hiring Lip-Bu, prior to that, nearly a decade of catastrophic decisions. And they still own 80% of the x86 market, 75% of the market. AMD has worked up to like 25% or 30% after a decade of screwing up. And you ask yourself, that's a moat. How big is my moat? I can make a bunch of bad decisions for a decade and only lose 20% share. That's extraordinary. The moat was just unbelievable. We'll see. I mean, I'm a huge fan of Lippe's. He's an investor in our company. I wish him well. And I think if anybody can change that company, he can. But I think we rarely talk about what being the market share leader means in terms of a moat. In, in the right context. Because as a challenger, we have to think about it exactly, because it's exactly that, that we need to— we need a bridge for, right? It's exactly these characteristics of the moat that we need to get over.
In 5 years' time though, is it Uber, or is it like AWS and cloud? And what I mean by that is like cloud is an interesting market where like, yeah, a couple of players or several players have relative segments, 25%, 30%, and it's shared relatively evenly between them? Not exactly, but relatively. Or is it one like Uber where Uber has 90%, Lyft has 5%, and then there's alternative providers with the other 5%?
I think it's going to be between those two. I think in 5 years from now, NVIDIA is going to have 60%, somewhere between 50% and 60% of the market. Right. I think right now they have approximately all of it. I think they will come down over time.
Of NVIDIA's usage, what percent will be training versus inference?
I think they will continue to have a meaningful business on both sides. I think they're exceptional at training. I think they will not roll over and play dead in inference. I think they are a really— look, they're a world-class company. I mean, they've had one of the great decades of any company in history. I mean, from 2014, they were worth, what, $10 billion? To where they are right now. It's one of the great decades in corporate history. And I don't think that they're going to roll over and, oh, yeah, we're not going to be in the inference market. That's not going to happen. They're going to have meaningful share. But the market's growing. And we'll have a piece. I think others will have a piece. I think there'll be some very big companies made in this 100x growth. Some very big companies.
Do you think chip providers will be far larger than model providers in terms of enterprise value?
In the 5-year timeframe? Yes.
How does that prediction change in a different timeline?
I think in a shorter timeline, I think, you know, when you price an option, variance and uncertainty increases the option's value, right? If you look at the way Black-Scholes works, or if you look at any option pricing model, uncertainty is a friend. Variability is a friend of the value of the option. And when people are paying these extraordinarily high prices for our Model Companies right now, I think part of that is this extraordinary uncertainty, is this wild variance. And so, in the shorter run, it might not be the case. But in the longer run, as markets mature, as we begin to understand the value of these models, we understand what their businesses look like, what their long-term net profitability looks like. What did Warren Buffett say about markets? In the short term, they're a voting mechanism, and in the long term, they're a weighing mechanism, right? At some point, the weighing kicks in, and, uh, usually it's in the public markets. And then investors say, which, which is likely to give me better growth in the future?
I mean, listen, you mentioned the word public there. I do want to just hone in on your business. You're cash flow positive in a world where everyone else literally bleeds cash. Help me understand, what do you do to make you cash flow positive when everyone else is bleeding or hemorrhaging cash?
Traditionally, your, your, your gross margins were a measure of, of your technical differentiation, right? And I think if you're running a negative gross margin business, I think you're— it speaks for itself. You're selling commodity. Your value creation isn't being recognized in the market. And so, I think our technology is creating an opportunity for us to maintain margins where some others can't.
A lot of your revenue is concentrated to the G42 deal. To what extent is that a strength or a weakness?
It's both. Look, the way you catch 3 large customers is to catch one first. The way you build 3 large strategic partners is learn to be a strategic partner. That's a learned skill. I think we didn't arrive knowing how to be a strategic partner at G42. And now that we've worked at it and worked at it, it's a muscle we can replicate. We could be a better partner to any of a dozen different companies in the world.
What have you learned in the G42 relationship build process that makes you now a good partner in the way that you work?
We've deployed tens of exaflops of compute, vastly more than anybody else that isn't AMD or NVIDIA, right? I mean, a huge amount of compute. We— our software has been hardened on some of the largest AI clusters in the world. We've gone through the growing pains of increasing manufacturing 2x and 5x and 2x again, I mean, through unbelievable growth in manufacturing. We've worked with our supply chain partners to be sure that they're ready for this extraordinary growth. We've— I mean, I think when you work with a strategic partner of this size, your organization comes out different on the other side. There are things you've learned and there are mistakes you've made. I hadn't done a big relationship in the Middle East. There was a huge amount to learn. I think you come out a much better company. And much better prepared to do business with a hyperscaler, to do business with another massive partner, to do business with another sovereign. But it takes real work. And your team has to learn.
You said you'd come out better.
Yeah.
Why go public when you did? When this happened, I was like, it seemed preemptive, respectfully. And my question now to companies is why go public at all? Bluntly, there is so much private capital. The Collisons have shown, I think, very clearly that you can stay for a lot longer than you plan to.
Databricks has certainly shown that, right? I mean, those were historically public market valuations. And, you know, the valuations that Anthropic and OpenAI and some of the others are getting are historically public market only valuations.
And like you said, your S-1's live. Anyone can read it. I wouldn't want people reading mine.
We have nothing to hide. I mean, I think—
No, but your competitors have got asymmetric information.
Yeah, we've got asymmetric technology, right? I mean, I think you have to be pretty— to be public, I think you have to be ready organizationally. You have to be ready with your processes. You need to be ready to forecast and predict. To be held accountable in a way that private companies historically haven't been. We think that there's tremendous value. We think that we will be among the first in the category. We think that some of our largest targets would have a stated preference for doing business with public companies. Large enterprises in the US have done that historically. Those were some of the reasons that led us to.
How many G42 relationships, à la G42, will you have in the next 24 months? How fast can you ramp them?
Um, that's a good question. Several.
Sorry, remind me, how big is the G42? It's 87% of revenue, I know that.
It was big. I mean, when we announced it, it was— some estimated it was North of a billion. Wow.
Well done. That must be a bit of a high five.
Look, I think, uh, come on, you know, for sure, right?
Million dollar.
First, first, there's tremendous excitement, and then there's sort of every entrepreneur's reality is I gotta make a lot more gear, right? I, I, I need to make it. I got— you get, you know, what— you make a list of your top 10 vendors and you fly it to them all and say, big orders are coming, be ready, right? You work with all your partners to get ready because you need to make a great deal more stuff. And that, that's one of the real differences between hardware and software is When we grow fast, the number of people you need to work with in your supply chain and the amount of collaboration that needs to happen is truly extraordinary.
I totally agree with you on that. Sorry, are Nvidia gonna have a clusterfuck of unhappy customers who bluntly have waited so long for chips, by the time they get them, the chips are outdated and they're going, What?
All of that's an opportunity for, uh, for us and others. I think that's, that's opportunity. I think being, uh, a market cheerleader isn't easy either. Um, but when you're late, right? Uh, when the bully falls, everybody wants to give him a kick, right? I mean, that's A lot of that happened at Intel. They'd been the dominant player, and when they fell, everybody was happy to jump in and kick them when they were down. And so, uh, I think there is a, uh, a real opportunity in the potential for NVIDIA customer unhappiness, for sure, for those of us who are competing with them. I mean, if you can't get your gear, you may as well test somebody else's. And that, that's a huge opening.
Head over to Cerebris and use the promo code Harry20 for your chips today.
Do that. Yeah, there we go.
I'm here for you, baby.
Influencer.
No, no, I appreciate it. Yeah, yeah, no, no worries. It's fine. I, I hope if we could do a 20% take and on the billion deal, I'm happy.
That's fine. I, I, I know this venture business isn't been so good to you, Harry, and you got to get shoes for your kids and the like. And yeah, we're happy to donate to the Harry Cost.
The $400 million fund in phase when I have no kids as well.
No, no, look, 2 and 20 is a rough way to make a living, Harry.
Dude, you don't get it, OK? You in hardware. You said about the complexity of hardware. Yeah. Are export controls being implemented properly? Do you think that is a good idea? You know, everyone was going with Deepsea.
Why?
How did this happen? They must have stolen chips. How could this be? What do you think about export control?
It turns out that they probably did use chips in Singapore. Um, I think the following. I, I think managing Managing software and managing hardware compliance are extremely different things because their vector of diffusion is different. There's different weights, right? If you sell a server that weighs 500 or 600 pounds, arrives on a pallet, you can go visit it, right? You want to deploy it in Kazakhstan, you can put a data center and you can have somebody from the embassy visit it. Take photos of it once a month. It's not going anywhere, right? You can keep track of who uses it and provide logs, and that's much, much harder with software. And open source is a whole nother level, right? And so, um, that's the first observation. The second is that we had— I got to know the the, the leadership in commerce in the previous administration. I didn't always agree with their policies, but it is a world of unintended consequences. You, uh, sought to limit Chinese access to EDA tools to delay the growth of a Chinese chip market, and so U.S. venture capitalists backed tons of Chinese companies in Shenzhen to build EDA tools. Right, right, right. That, that this is an unbelievably slippery, dynamic, challenging problem, and I, I don't know if it's a tractable problem. To delay another nation's progress, uh, on a technical trajectory is an enormously challenging thing. And I certainly came to appreciate just how difficult it was for well-meaning people to predict the impact of policy during the last 2 years, for sure.
Do you think this administration is better for AI than the prior administration?
I don't think there's any doubt that's the case.
What makes you say that?
I think the past administration lined itself up against big tech. And that was a mistake. AI is also in a different place, so it's easier to be for it, right? It's less scary now than it was in, I don't know, '21, right? We sort of have a better picture of the trajectory, both the risks and the the benefits. I think this administration sort of had the foresight to put in place an AI czar or leader to be a focal point for discussions. Yeah, I think it's probably net a fair bit better.
You said it's very challenging to kind of hinder a nation's development, adoption, progression of a technology. Respectfully, you chose to not sell to China. Yeah, why was that? And does that not go against the difficulty in hindering progression?
No, I, I think, uh, I, I have a, a very simple rule, and I encourage your team to, to use it. I mean, you don't need a, a big sort of handbook to help you make good decisions in a company. You just ask yourself, would my mother be proud? And would she be proud if I did this? Would she be proud if I explained exactly the situation? And would she look at me and say, I'm proud you're doing this, son? And I asked myself that, and I, I came to believe that, that the deal on the table was— wouldn't be used for good, and I wasn't comfortable with that. And I wouldn't have been able to explain to my mother. And that's a moral compass. And I think that's, uh, it wouldn't have been used for good.
I'm sorry, I'm just naive. They use it to what? Power Doyen and, you know, some of that—
do facial recognition to identify minorities, uh, for persecution, to build military equipment, to things that I either couldn't see, or what I saw didn't, didn't feel right. And so we— it's more important than money.
Do you think we fundamentally underestimate the Chinese capabilities?
100%. I, I think, and it is one of the most obvious and frequent, uh, errors in judgment, is that you underestimate the other side. I think you have to look carefully at what they're doing. And their investment in infrastructure has been extraordinary. The rate at which they generate engineering talent is exceptional. The government's ability to have a policy and implement it, that's not a democracy. They weren't designed to have checks and balances there, right? Um, the funding that flowed into the development of AI technology, that their venture capitalists were backstopped by their government, that, uh, they have national champion companies, that they've developed a belt and suspender strategy to sort of make much of the third world dependence on them and their technologies. I think they absolutely should not be underestimated. They have a lot of people, and we see a tiny fraction of it. I think they have produced industrial policy that has moved their nation forward.
What was the most significant, do you think?
I think they— the creation of economic zones like Shenzhen was clearly a visionary move. They had— they knew that their own system was in the way. And so they created zones that relaxed their own system.
Could the US learn from them in that way?
We did some of the same things in the Trump administration, right? What did we do? We relaxed our own rules in the development of vaccines. We, uh, we knew that in, in this time it would be very difficult to go through the steps that we always go through, and we tried to implement some thoughtful shortcomings or workarounds, rather. You know, why are they committed to trains as a mode of transportation and, and we can't build a decent train system in the U.S. or in California? Or why we have 3 different standards for train rails, and the rest of the world can, can build extraordinary high-speed trains linking important cities. Um, why— what are we doing wrong in the building of our infrastructure that, that our bridges and our freeways are in disarray? Um, I think those are our questions we got to ask ourselves when we see other people doing it differently. I mean, you know, if, if, if you watch a good football team and you say, whoa, that's an interesting offense, and you're not thinking to yourself, how could our team learn? What, what could we do? What— why did that work? What was it about the people they had, or the talent, or the structure, or something that made that a successful series of plays? And what can I take away from that? How can that inspire me to do better? I mean, I'm always looking for inspiration in others and competitors and partners. I think we have some of our partners at G42, I mean, the work ethic is unbelievable. Cool. It inspires me, um, and the, the scope of the challenge that they're taking inspires me. And I, I think I'm always looking for that.
Andrew, I could talk to you all day. I do want to do a quickfire with you, so I say a short statement. You ready?
Yeah, sure.
What do you believe that most around you disbelieve?
I think we're closer to peace in the Middle East than people believe, because I, I think, uh, there is a rise of a of a moderate business-focused Arab state that it wasn't there 25 or 30 years ago. And I think if you visit the UAE or Qatar, or even KSA, what you see is amazing transformation. And I think there is a desire for uh, to, to be included in the West in their own way, but also to, to, to enjoy the benefits of it. Um, I, I think it's, uh, yeah, I, I think there's, um, we are closer than, than maybe people think.
What's the most underrated threat to NVIDIA's market share dominance?
The fundamental architecture of the GPU, uh, with off-chip memory is not great for inference. Now, they will continue to do well in inference, but it's— it can be beaten, and I think they know it.
What's a crazy AI prediction you have that most people would call science fiction? Yeah, Dario at Anthropic said we'll live to 150.
I don't think we're going to live to, to, uh, 150. I don't think— what, 90% of our code will be written by machines? In this year. But I do think that within a year or two, AI's penetration will be approximately the same as telephones, cell phones.
What have you changed your mind on in the last 12 months?
Oh, there are lots of things. Many decisions I made turned out to be wrong. I mean, I, I think what was the most wrong decision? There are two ways you can be wrong. You can actively be wrong, or you can fight against what was right. Um, in, uh, 2016, JP, one of our co-founders and chief system architect, laid out a plan that would have us doing water cooling and for our systems, and nobody else was doing it, and I fought so hard And I was so wrong. JP was right. About a year or two later, Google announced that the TPUs were going to be water-cooled. We were first. And now, NVIDIA is only selling water-cooled parts. I mean, I was dead wrong and JP was right. I mean, I think many, many instances when you make a lot of decisions every day where you're wrong, I've been wrong about people. People I thought were pretty good turned out to be extraordinary. People I thought would be extraordinary were really smart, but couldn't finish projects and get stuff done. I think if you're not prepared to be wrong a fair bit, you ought not to be making a lot of decisions because it comes with the territory.
As a venture capitalist, I'm never wrong.
As a venture capitalist, you're wrong 9 times in 10, and everybody forgets. As long as you're really right.
And I get a picture of you signing the term sheet with me.
That's right. That's right. I mean, I think yours is a perfect industry in which nobody cares about the average. On average, you're wrong all the time. And what they care about is the occasional time you're really right. And that's what moves a fund. And I think that's different than being a CEO. I think we got to be mostly right most of the time. But if you're making a lot of decisions, you're still making a ton of mistakes.
This is your fifth startup. Yeah. I mean, you are a sucker for punishment, aren't you? I mean, really, like, five times. Like, Christ, Andrew, did you not get beaten alive enough? My question to you, though, is like, I believe in the value of serial entrepreneurship. I've spoken to many who don't. Respectfully, how do you think about the inherent benefits that you have having done it 4 times before?
Okay, I think if you are in a business in which running a business is a benefit, then experience matters a great deal. Uh, I think if you are in a business in which you look like your customer— there was a reason why social, social networks were started by people right out of college or in college, because dating is top of their mind, right? I mean, that, that, that's— and they look like their customers, and that was more important than knowing anything about running a business. And so in that environment, it will certainly select for people who are of the demographic that, that their customers are. They know that backwards and forwards. But if you want to have a business has manufacturing in it, that has a supply chain, that has you managing hundreds or thousands of engineers to a timeline, to a schedule. I don't think anybody would turn around your statement and with a straight face say, you know, what I'm looking for is an engineering leader with no experience. I don't want somebody who's led a team of 400 or 500 who has experienced the challenges of growth. What I'm looking for is somebody with no experience.
Naivety is a bonus here.
That's right. I think the people who sell that sometimes are consultants, right? Oh, look, my guys have no experience in your industry. They're not biased. Like, what? Right? Maybe a little bit of experience in the industry would help, right? I mean, come on.
Where are people investing today in AI across the stack? You can choose any part where you're like, What? Why is so much cash going to that part? I'm not saying that company.
I think part of the, the dynamic in your industry is, is sometimes money needs to find a home, right? Some guys have raised really, really big funds and they got to find a home for their money. Um, and some people don't like to be left out and they're willing to, to make investments for maybe for some status purposes or other reasons that don't seem to make sense. I don't know. I haven't thought about it. I mean, I think there's some underappreciated places of investment. I'd say in the chip world, the submilliwatt, really tiny, tiny little chips that live next to sensors that do inference. These are tiny little things that will only send back useful data is an extremely interesting market. And they will sell enormous volume. Now, it's not a part of the market I love to play in. I like to build bigger things and sell them to the data center. But I think that part is extremely interesting. I think they'll be fundamental for robotics. I think that's an area where I think it's extremely underappreciated.
If we think about Cerebras in 10 years' time, where do you envision the business in 10 years' time? If everything goes well, where are we in business having that conversation?
So 10 years ago, NVIDIA was worth $10 billion. So that's a, that's a long run in our world right now. I think in 3 to 5 years, I would like our technology to have been used to solve two important societal problems. I would like it to be used to have found a therapeutic, for an affliction that impacts more than a million people a year. I would like our inference to be powering a collection of apps that don't exist today. And I would like that when— that a meaningful portion of the population in the US and in Europe inadvertently uses our technology. So uses something that we power and that they don't even know it.
Andrew, I've wanted to make this show happen for a long time. As I said, I heard so many good things from Harry Feldman for many years. Um, there's been so many requests to have you on the show. My team is just like, just get Andrew on the show, Harry. I'm like, okay, okay. I like tweeted it, obviously, which is how we We got this. But thank you for joining.
You tweeted it and like 40 people sent me notes saying, how come you're avoiding Harry? How come he has to go tweet it? I was just like, all right, just call me. It's good. Send me a note.
Happy to come on.
Really thoughtful questions, Harry. Really thoughtful and interesting. Um, a really fun conversation.
More from Andrew
How Cerebras is Democratizing AI at Scale with Andrew Feldman, CEO of Cerebras
Cerebras CEO, Andrew Feldman on Why Raise $1BN and Delay the IPO & Why NVIDIA’s Worried About Growth
⚡️Raising $1.1b to build the fastest LLM Chips on Earth — Andrew Feldman, Cerebras
Andrew Feldman, Cerebras Systems | theCUBE + NYSE Wired: AI Factories - Data Centers of the Future
Andrew Feldman | How Cerebras Built the "Impossible" AI Chip Now Challenging NVIDIA