⚡️Raising $1.1b to build the fastest LLM Chips on Earth — Andrew Feldman, Cerebras
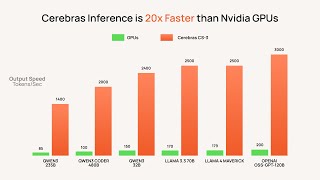
In this interview, Cerebras CEO Andrew Feldman discusses the company’s recent $1.1 billion fundraising round at an $8.1 billion post‑money valuation, highlighting the involvement of investors such as Fidelity, Atreides, Tiger Global and Valor. He reflects on Cerebras’ nine‑year journey from early meetings with OpenAI founders to shipping three generations of wafer‑scale chips, emphasizing the architectural choice of a massive dinner‑plate‑sized chip that integrates SRAM on‑chip memory, delivering up to 2,600× higher memory bandwidth than GPU HBM and claiming roughly 20× faster inference performance versus NVIDIA B200 GPUs. Feldman contrasts Cerebras’ approach with traditional GPU designs, explains why on‑chip SRAM and a single large chip reduce interconnect complexity, and positions the company against competitors pursuing many smaller chips. He outlines the dual focus on training and inference, noting strong demand for low‑latency inference across enterprise customers (Cognition, Mistral, Meta, IBM, AlphaSense, Mayo Clinic, GSK, US military, DOE, etc.) and the importance of supporting open‑source model trends, fine‑tuning, and emerging agentic workloads. The conversation also covers Cerebras’ cloud and self‑serve “Cerebras Code” offerings, the challenges of operating data centers that consume megawatt‑scale power, and the often‑overlooked engineering effort behind the team, compiler stack, and token‑routing infrastructure. Finally, Feldman shares a ten‑year vision centered on exponential growth of AI inference demand, relentless speed improvements, and continued relevance of transformer‑based models, while acknowledging the difficulty of long‑term forecasting in a fast‑moving market.
Chapters
Okey dokey. We're in the remote studio celebrating a big, big raise with Andrew Feldman of Cerebras.
Welcome. Well, thank you for having me.
It's such an honor to finally have you here. We've been sort of poking around this sort of Cerebras ecosystem for a while. I run the AI Engineer Conference. I run Latentspace. I'm friends with your entire marketing team, of course. And also more recently I joined Cognition, which is a big customer and friend of Cerebras. But here, I mean, let's, let's get the big news right out of the top. What are you announcing today for your fundraise?
So we announced a $1.1 billion fundraise that we had completed. It was done at an $8.1 billion post-money valuation, and it was led by Fidelity and Atreides Management. So we, we, we're announcing that we raised the most money on the highest valuation with the best investors in, in the category. And so it's a good day. I think when you raise money, a lot of excitement, and then you sort of put that down and move ahead to keep building cool things and executing. So that's today. We're doing our high fives, and tomorrow we go back to work and keep building cool things.
Yeah, I like— I love the spirit of the thing. So help me contextualize, you know, like billions of dollars is such an impossibly huge number for people to understand. How does a round like this come together? How do you contextualize this in the scale of what SiriBus has done?
Sure. I think we were founded 9 and a half years ago, and I, I think, you know, in, in early 2016, I don't, I don't think we could have imagined, uh, the, the AI market behaving like it is today. And I, I think we were, uh, you know, in 2016, we, we met with Sam Altman and Ilya Sutskever at OpenAI, and They were an idea and we were PowerPoint, right? That's amazing. And what AI was doing was identifying cats in pictures. And I think they ended up investing in us, both of them and many of their colleagues in our early rounds. But I think what happens is that you begin building things. Your vision is how can you make your customer's life better? How can you delight them with their experience or delight their customers? Right? How can your infrastructure play a role? And we, we saw early on that AI would be a monstrous market. We probably guessed wrong that it— we probably didn't think it would be as big as it is. But we, we, we thought that if you did extraordinary engineering, if you tried to do something that nobody'd ever done before, uh, you could do something really special. And from there, you know, we shipped our first product in, in 2020. We delivered the next generation a couple years later. We delivered the third generation a little less than a year ago. Customers around the world have been deploying and benefiting from our performance. Really focused on performance, both for training and for inference. You think 20 times faster than NVIDIA B200 GPUs, and it's been an amazing run. And so the way a round comes together is you decide you're going to go out, you engage at this stage with investors who do both public and investing. Like any other sales process, you go and you visit them and you tell them your story. We were massively oversubscribed and we were able to, to choose sort of the best of the best to, to, to be in our consortium.
Yeah. So I'm, I'm gonna flash up the, the announcement on screen. Mostly we talk to researchers and engineers, more, more technical podcast on our side. I mean, while we're at this, while we're talking about a fundraise, let's contextualize a bit. Fidelity's a big name. I, Atreides, I don't, I know less. What is a good investor to you? What makes a good investor versus a not so good investor?
I think it depends. There's no single rule. It depends on the stage. I think in your early stages, you need people who understand the risks and challenges of being an early-stage company. And in our Series A, we had Benchmark, who was perhaps the best in the business, along with Foundation Capital and Eclipse, extraordinary companies. I think in later stages, as you get close to IPO, you're looking for a very different type of investor. You're looking for an investor who primarily does public markets. You're looking for an investor who is extraordinarily thoughtful, is a leader in their field. And I think that's what we achieved with Fidelity. Atreides, Tiger Global, Valor. Each of these are leaders. They're looked to as extremely knowledgeable in the category. And, you know, people, people take notice when, when the smartest of the smart money invests behind your idea and your company.
Yeah, that's, that's amazing. And congrats on all those. Let's dive in more sort of the technical side, obviously, because we speak to it more to the engineering crowd. We talked about 20 times faster. That's obviously not like a strict number, but I've seen this chart evolve over time. Like you started out with the Llama number and then you sort of branched out into all the others.
That's right.
So obviously the growth of open source and the growth of these like really large open source models, mostly MOEs as well now, has really benefited you. You talked with Artificial Analysis, or I'm familiar with them too. I also had them for the AI Engineer Conference. Was it a surprise that you had like such much like higher performance numbers than the competition. Yeah. Tell, tell me about that.
So inference performance comes from memory bandwidth and the memory bandwidth is the limiting factor in inference performance. Remember, in order to, to generate a token, to generate a word, all the weights have to move from memory to compute. If you're constrained right there, your inference is slower. And we have 2,625 times more memory bandwidth than the GPU does. We use a different type of memory. We use SRAM, whereas they use a flavor of DRAM called HBM. And so we were built to solve this problem. We were built Every ounce of our design and our architecture was designed to provide huge amounts of memory bandwidth. Maybe the way to think about memory bandwidth, imagine you've got your cup of tea there, but imagine a cup that holds Coke. The cup is your memory capacity and the Coke you pour into, the Coca-Cola you pour into the cup is your data. Now the rate at which you can get Coke into your mouth is a function of the straw, right? It's not a function of the size of the cup. It's a function of the size of the straw. And GPUs have a very narrow straw between compute and memory. We chose a fundamentally different architecture. We got rid of the straw altogether. We built a chip the size of a dinner plate so we could put all the memory onto the chip. We could use SRAM. And this said, all right, we've got our Coke in our cup, get rid of the straw and just put it right on our mouth. And that's the way you get huge amounts of data. That's exactly right. That's exactly right. Moving. Were you just pretending to drink tea? Did you pour Diet Coke into a teacup? Is that what you're doing?
No, I didn't. I, I happen to have a Coke can next to me, but I, I'm actually, I'm actually sick. So this is why I'm drinking tea to, to stay, uh, to stay hydrated. But good to stay hydrated.
So we weren't surprised. Every ounce of our design, of our architecture was, was built to solve this particular problem enable the type of speed that your guys at Cognition have benefited from, the guys at Mistral in the closed-source world benefit from. We serve Le Chat for Mistral. Meta has benefited from, IBM benefits from, AlphaSense, and hundreds of other customers around the world benefited from this extraordinary speed.
Yeah, fun fact, I used to work at Senseo, which was AlphaSense competitor, and they merged into AlphaSense. So I'm also a shareholder.
Well, you've been at our customers your whole career. This is awesome. This is awesome.
So I mean, I think like you obviously made the right bet on the large chip. And, you know, there's a number of sort of people in the large chip sort of industry. You know, you're not the only ones. Like what has made you stand out so far? You know, I think like what has been hard for a non-hardware person like myself to understand is, you know, like a lot of people who are sort of competing with Nvidia and betting on like more on on-chip memory and all that. Like, it's hard to distinguish between what the strategies are. And I think over time as well, your different generations, you are developing more and more of an understanding of what the market really wants. So I just want to get a sense of like how you see this market, that the large chip market.
Sure. I think that the way to think about this is that there are really two types of memory. There is DRAM and HBM, which they can hold a lot, but they're slow. And that's what NVIDIA chose, and they chose that primarily because originally that was the right choice for graphics. Lots of capacity, but slow. On the other hand, there's SRAM. SRAM is the exact opposite. It can't hold very much, but it's blazing fast. And so what we, what we saw was that if we built the largest chip in the 75-year history of the compute industry, if we built a chip that was 56 times larger than the largest GPU, We could stuff it to the gills with this fast memory. All right. We could fill it with the fastest memory and thereby overcome its limitation of not having a lot of capacity and just benefit from its blazing speed. Now, if you build SRAM-based solutions based on little tiny chips, you, you need to use hundreds or thousands to do work. So if you build a normal size chip, say 800 square millimeters, right? The size of a postage stamp, and you want to support a trillion parameter model or 600 billion parameter model, you might need 4,000 chips. All right. That's a lot of complexity. That's a lot of wires. That's a mess.
Yeah. You need interconnects as well.
You need interconnects. It limits the things you can do. It makes all sorts of cool AI techniques like speculative decode extremely difficult. Whereas if you have a giant chip, you might only need a handful. And so I think that that's one of the ways to differentiate. I think also just go up and look at Artificial Analysis. Wherever we are, we're the fastest, not by a little bit, but by a lot. And the reason we like them as a, as a benchmarker is they go to your cloud, anonymously every day, do a little work, publish the results, right? There's no gaming. There's no months of preparation for the test that advantages big companies like MLPerf. Every day they go and this is exactly what your customers get. There's no gap between the benchmark and what your customers actually see.
Yeah, it's all, it's like, you know, MLPerf is kind of like the Olympics. Like you really prepare for it.
Absolutely.
And it's like a once in a lifetime, you know, and then, and like the artificial analysis is more like Apple Maps, like estimating traffic for you, you know?
Right. You know, like it doesn't really matter how fast you are at the drag strip if every day you go to the grocery store, right? You can, so that's the way we think about it.
So, and then a little follow-up on sort of the inference versus training split. I'm getting the sense that like most of these are just trained on non-Cerebras silicon and then inference on silicon, on Cerebras silicon. Do you see that persisting going forward? Are you specializing in inference? Do you want to, would it be a goal for you to have more training workloads or do you not care?
We support both training and inference and we deliver solutions on-premise and in the cloud. So we are perfectly happy for our customers to use ours to train or do inference and we do a great deal of work. With large enterprises in training, with Mayo Clinic, with GlaxoSmithKline, with the US military, with the Department of Energy, with our customers in the Middle East. We've trained leading models, language models in Arabic, in Catalan, in Hindi. What's happening in addition to the giant sucking sound for fast training is that these models are being used, right? I mean, we make AI with training and we use it with inference. And the amount of AI being used right now is extraordinary. It's just off the charts. And I think there is certainly an unquenchable demand right now for fast inference.
Yeah, I think that the numbers I had was something internally for Google with the TPU workload is something like a 2 to 3 ratio of training to inference. And I wonder, I feel like for Cerebras, it might be like, I don't know, 1 to 5 in favor of inference.
I think that's not an unreasonable guess.
Yeah. Okay, cool. Amazing. And then what do researchers tell you they want? Like, you know, I'm looking at these charts of Qwen3, Llama, Llama 4, OssGPT, and obviously there's more. The GLM just came out today, and I know there's a lot of work that's going on between our companies on that, on the open model side. What trends are you seeing and what do you need to support on the silicon side for those trends to happen?
I think while we design silicon, we also build the system and the software layer and Many of our customers, including Cognition, benefit from us via our cloud offering. And so it's a sort of a soup-to-nuts solution. The trends are pretty clear, I think, for sort of AI companies like Cognition, like all your competitors, like AlphaSense, like dozens of others. They are trying to replace closed-source models with very, very fast open-source models, and they're trying to drive the open-source accuracy dramatically up. And they're doing that with fine-tuning. They're doing that with all sorts of interesting ML techniques. I think the closed-source community has come to realize that being slow is not ideal. And that there's a very sort of interesting tweet by Paul Graham, and he said something like, "I'd use Google half as much if ChatGPT weren't so slow," right? And that's very interesting that if you make your customers wait, they leave you. Right? They go and use something else. And so—
Yeah, and they don't necessarily tell you about it too. It's just like—
No, that's right.
They're voting with their feet. Yeah. Yeah, they're voting with their feet and like, it's a slow, like, maybe like 20% of my work goes over. It's not the full thing. I'm not rage quitting. I'm just choosing more one over the other.
That's exactly right. That's exactly right. We see at the large enterprise level, particularly those who have large data assets, desire to train their own models and to go a little smaller, say in the 10 to 30 billion parameter category. I think especially the very large companies, enterprises have concerns about some of the data that was used in training some of the open source models. And so they want to take the architecture of the open source model, randomize the weights and begin again, and do that with datasets that their own legal teams have approved. So we see that in large enterprise category. I think areas that are of interest are sort of securing agentic work, right? I think when you spin off dozens of agents, the sort of attack surface of the solution expands geometrically. And so there's a lot of work being done to think about how one might secure an agentic flow like that. I think still the bulk of the models are in the transformer category for language. We continue to see innovation in diffusion for images. I I think many of the new models are tweaks to some of those core foundation architectures.
Yeah, it's weird how the transformer paradigm has stood strong for quite a long time. I do think there are some discussions. I just recorded a podcast with AI21 yesterday where they've been really exploring hybrid models, but I feel like at least the paradigm of deeper models or like, you know, like more MoEs, I think that that's not really going to go away. They might have some innovation in some part of the attention for variants that you might be using, but like nothing, nothing that you have to particularly take care of at the hardware level.
Yeah. I think, you know, we designed this architecture before Transformers were invented. And one of the, one of the hardest things in computer architecture and one of the first one of the first things you do is you decide what you're not gonna be good at. I'm gonna build a chip, what am I not gonna be good at? We're not gonna be good at general purpose compute, we're not gonna be good at graphics, we are going to be good at AI work. The second really hard question in computer architecture is what should I be general at and what should I be specialized at? And in 2016 and '17, as we were setting this architecture, we could have said what we wanna do is embed 3x3 convolutions into the circuits. And that would've made, right, 3x3.
You're very good at that. Yeah.
That's right. Very good. But you would've been, you would've been carrying a tax if you did a 1x1 convolution. You'd have been carrying a tax if you did anything other than a 3x3. We said that was not where we wanted to be specialized. What we wanted to do was work underneath that. We wanted to work at the linear algebra level. We wanted to accelerate sparse linear algebra. And what that did is that enabled us to support models that we had never seen when they came out, right? We'd never seen transformers. Transformers and yet we're the fastest at transformers by 20x. We'd never seen diffusion models yet we're the fastest at diffusion models. Getting that right is one of the very, very important decisions in computer architecture and one I can take no credit for whatsoever. Sean and Michael, JP and Gary, who are my co-founders, they got that right really early on along with the ASIC team.
Yeah. Awesome. So, and then finally, you know, I think you are, you were mostly selling chips directly to your customers until about a year ago when you basically started sort of your self-serve cloud offering. Now there's a dedicated effort on Cerebras Code, which is doing very, very well. How do you feel about that? Like you're kind of competing with your own customers a little bit?
You know, I think the following, the way we look at the market is as follows. Until about a year and a half ago, AI was sort of a novelty, right? You would, it was curious and it was interesting, but it wasn't useful every day. And about a year, year and a half ago, we began to see changes where it became useful in a very different way. And we dedicated resources to the inference side. We thought we could improve and stand up a cloud to deliver inference. And in sort of early September of last year, we stood up our cloud and we had an extraordinary reception. It was overwhelming. And sometimes too much good is a challenge too. You know, we had downtime and we had to fix that. And there was just so much demand. We had to get better. And so step by step, we improved and our quality jumped up and we did some of the right things. We did some of the wrong things and then fixed them. And step by step, and what we found is that there's just this aching demand right now for inference that doesn't make your customer wait. Now, when we did that, we saw an opportunity to continue to learn from our customers. So we stood up a Cerebras Coder. We have no interest in being an IDE. That is not going to play to our strength. That's your strength. That's the strength of you guys and your competitors. That is not who we are. On the other hand, one of the things we were really looking to do is get enough adoption so we could watch utilization. We could hear directly from customers what features we were lacking, what we needed to do better, and deliver to those who wanted sort of raw performance, maybe without the IDE, right, an offering. I don't think we have any interest in competing with, with you guys or, or your competitors. We, we're, we're not gonna be very good at that. What we're good at is the processing of tokens unbelievably quickly and the, the user experience and, and the engagement engine around that's for other app makers that, yeah, whether it's you guys or AlphaSense or, or Mistral or, or, or any of the others, that's that is really important that, that, that you guys do.
Yeah. Incredible. What do you wish people asked you more about? You know, like I feel, I'm sure you do a ton of these media interviews. I probably asked, you know, some of the same questions. I just have to, you know, uh, what do you, what do you wish people understood better?
I think I wish they asked more about the team.
I think they're always asking about me and I, I think, well, you're the star, you know?
No, I, I think, think I'm the thin edge of the wedge. I, I don't think that's the star. I, I think first there were, there were 5 founders, Sean Lee, Gary Lauterbach, Michael James, JP Fricke. They were the technical visionaries. I have market insight. I have product management insight. I have— they were the technical visionaries and what they put together is extraordinary. I think people don't ask me, well, where'd you get this collection of extraordinary engineers? And, you know, dozens of them have worked for us and with us before. And so we began with one of the world's leading chip teams. We built around them extraordinary talent. We added hundreds and hundreds on the compiler side and the software stack. People don't ask about that. And that's a pity because there's just an extraordinary amount of hard work that goes into building a product. I think those are some examples that people don't ask about. I think people don't ask about the complexity of standing up a data center that pulls as much power as a small city, right? I think that that's really interesting things are going on in the data center business. We just opened a new facility in Oklahoma City. It's our 5th in 12 months. And it's amazing the amount of power these data centers are pulling. And, you know, it's very easy to hear people talk about tens of megawatts or gigawatts. If you look at a city like Pittsburgh, it's a top 10 city in the US, it draws 3 gigawatts. So you're pulling sort of a third of Pittsburgh to 2 buildings. That's amazing, right? And the complexity, even like heating, heating gets to be a question, right? Heating, cooling, and the complexity there is extraordinary. And so I think people often sort of miss those things. And finally, I think the easiest thing to miss is sort of these collection of things that are on top of AI that are ease of use, that are unbelievably annoying if you don't get them right, right? I don't think prompt caching is an AI feature. I think managing your router where you distribute tokens to your partner and the technology involved in integrating your routing with your token processing partner, these are all things that are extremely interesting and have, can have a huge impact on performance that almost nobody talks Sorry, you have a router that is part of your offering?
Shouldn't that be our job?
Yeah, no, no, no, that is your job.
Okay.
Okay. Close it. No, no, no, it's not talked about enough. I think you're exactly right. I think the distribution of tokens and the techniques used so you don't crush your partner, the various techniques that can be used upstream of us is an area that isn't talked about enough at all. And there's a great deal of really interesting insight there and where a lot of data engineers work. And, you know, it's, it's sort of in the background rather than it should be in the front ground. We were doing work with, we were doing work with one of the hyperscalers and for a product they have, and they said, look, we used your, your system and it didn't make us that much faster. And so we said, well, that's a surprise because we're 20, 25 times faster on this workload. And what, what ended up happening is that other steps in their data processing slowed the whole system down.
And so they were not compute constrained. Yeah. It's always, it's always I/O bound, compute bound, I/O bound, compute bound. That's right.
There were other challenges that they had and that they had to work through. And by everybody assumed it was, was the token processing and it wasn't.
And so I think, I mean, honestly, that's a bad customer because they just didn't know what they were testing for. They blamed you.
I think that happens a fair bit in this world. Blame the new guy. I mean, that is, that is not uncommon.
Yeah, totally. Okay, so I'm already past time, but I'll ask one more question if you are in the mood to humor it. We're in an age of like very big infra buildouts. You know, I was at Meta Connect. I met with, with Zuck and Alexander Wang and like we talked a little bit about like the infra buildout that Meta's doing. OpenAI has Stargate, which is like basically terraforming Texas to be a data center.
West Texas. They've decided to annex West Texas. Yeah.
What is the Cerebras grandmaster plan for like, you know, like the next 10 years? Like what is the most ambitious version of where you're going?
Okay. I think that, you know, 10 years ago, NVIDIA was a $20 billion company.
Oh my God.
I mean, in 2014, yeah, 2014, they were $10 billion. In 2015, they were $20 billion. It's really hard to, to have a 10-year vision in this. And it's a very interesting question of when a market's moving very, very quickly, what is the right length of time to have a vision over, right? Because if the market landscape is changing extremely quickly, the longer your vision, the more likely it is to be wrong.
You have, you have to have a plan to plan towards.
That's right. So that's right.
It's more the action planning.
No, no, what you said is extremely smart. Rule-changing rules, plan-creating milestones. I think you're exactly right. Right. Look, we, we see the following. Number one, we see AI inference continuing to grow exponentially, and we know why. The size of the AI inference compute market is the number of people using AI times the frequency with which they use AI times the amount of compute they use each time they use AI. And what we know is that every week more people are using AI, they're using it more often, and they're trying to do more interesting things with that take more compute. We see no end to this, absolutely no end. And so over the next 3 to 5 years, we see extraordinary continued growth. That's number one. Number two is that for AI to deliver on its promise to be embedded in our lives, it must be fast. There aren't things that are embedded in your life that make you wait 10 or 15 minutes to get a good answer. Those are proof of concepts, but those aren't products. And whether it be on the coding side, whether it be on the Agentic side, whether it be on drug design, whether it's in healthcare, right? You want the results of that MRI quickly, right? You don't wanna wait weeks, right? You want, you want the results of your pathology test to, you wanna know whether you have bad news, whether it's cancer. You, you don't wanna wait weeks to get the results back, right? If you could get it back while you're at the office, That is a much better medical experience. All right. And it's true for the entire range of things that AI can do for us. And so we believe there will be continued phenomenal emphasis on speed. And finally, I think the transformer, the current architecture has a ways still to run. I think we will see that for several years more.
Yeah, totally. Okay. Well, those are great macro trends to hang our head on. I definitely co-sign that. Well, congrats on your huge fundraise. This is great first meeting for LinSpace. I hope we get to do this in person sometime, some other time. But thanks for taking some time out of your big day.
Well, thank you and the Latentspace team for inviting Cerebras onto your show. We really appreciate it.
More from Andrew
How Cerebras is Democratizing AI at Scale with Andrew Feldman, CEO of Cerebras
Cerebras CEO, Andrew Feldman on Why Raise $1BN and Delay the IPO & Why NVIDIA’s Worried About Growth
Andrew Feldman, Cerebras Systems | theCUBE + NYSE Wired: AI Factories - Data Centers of the Future
Andrew Feldman | How Cerebras Built the "Impossible" AI Chip Now Challenging NVIDIA
Fireside Chat with Cerebras CEO Andrew Feldman and former CEO & Chairman of Google, Eric Schmidt