Fireside Chat with Cerebras CEO Andrew Feldman and former CEO & Chairman of Google, Eric Schmidt
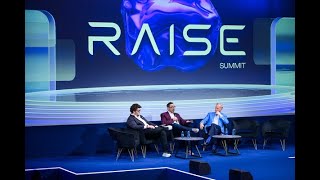
Cerebras CEO Andrew Feldman and former Google CEO Eric Schmidt discuss AI compute evolution, from Feldman's 56-times-larger chip design to the geopolitical race for open-source AI dominance. They debate where AI capital should flow, why latency matters for adoption, and how cheap electricity will determine where AI infrastructure thrives.
Chapters
and founder of Cerebras. And Andrew is also powering the AGI Race. So, uh, very good to have you on stage, Eric.
Andrew.
So I think like Andrew will be much better better at introducing himself than I will. So can you, yeah, quickly elaborate on Cerebras?
Well, first, if ever there was a tough act to follow, that was it. That was really extraordinarily interesting.
Thank you.
It's my brother.
My name is Andrew Feldman. I'm CEO and one of the founders at Cerebras Systems. We build some of the things that Eric was just talking about. We build big fast compute for AI and are very happy that, as Eric said, the world is buying this like—
But by the way, aren't you the fastest?
We are the fastest.
Good. I just wanted to get that out to the audience.
Guys, I'm agnostic, so I don't take position.
You sell to everybody, that's fine. We are the fastest and not by a little bit, but by a lot. And we are benefiting enormously from this trend line that Eric so capably described of AI becoming useful, the models being trained, and now sort of a whole society finding interesting uses for it, right? And that's what inference is, watching society use the AI that was built. And with any luck, they do some of that on our equipment.
You have a gift for us, Andrew? Maybe you want to show or—
Yeah, I think I am only interested in solving really hard technical problems. I think many of us, Eric and, in the audience, love the challenge of extraordinarily difficult technical challenges. And when we set out to build the right chip for AI, we flew in the face of 70 years of compute history. This is our chip, and it's about 56 times larger than the largest chip that had ever been built. And we did this because the, AI work looked different than any other workload that the world had encountered. It was comprised of lots of simple calculations for which intermediate results had to be moved a great deal, and then it had a very unusual pattern of going to memory. By building a big chip, we could keep all this information on this chip, we could access memory at unbelievable and we could produce this extraordinary result that Eric helped me market.
So, I would like to address the hardware-software synergy for AGI. So, Andrew, you are redefining compute with the WSE, Wafer Scale Engine, chips. Eric, you emphasize system-level thinking. How must hardware and software co-evolve to accelerate AGI? And are we seeing a new Moore's Law for intelligence?
So much of the current craze dates to the Transformer paper from 2017, which I was the chairman of Google at the time, and I didn't even, didn't even notice its publication. So once again, I I'm just wrong. But the transformer architecture allowed these models to get a level of parallelism that is pretty profound. What Andrew Feldman's company has done is that they're, they're working one level below, which he can describe to you at more, a more basic mathematical concept. So one of the key questions is, will the transformer architectures hold for the next 5 or 10 years as the hardware and the architectures such as Cerebus are doing, and I don't know. It's also interesting that there are multiple stacks, but at the moment the NVIDIA lock-in is largely over CUDA and Python, and there are a whole bunch of people who are trying to break that, not so far— so far, no, not successfully. So depending on how those layers play out in the next 5 years, we may or may not see very different outcomes. What do you think, Andrew?
I think that's exactly right. I think the following. One of the hardest questions in computer architecture, and when you start with a clean sheet of paper, you ask yourself two questions. What are we not going to be good at? Right? Which part of the market are we not going to pursue? And once you've decided which part you are going to pursue, you're going to— you ask yourself, should I pursue it with a general strategy or a specific strategy. In 2016, if we'd pursued a specific strategy, we would have embedded in the circuitry 3x3 convolutions, right? And that would have been dead wrong. Instead, we adopted a strategy that was different. We chose to look at AI across the board and say, what is the underpinning? And what's the underpinning is sparse linear algebra. And if we could accelerate the matrix multiplications, if we could accelerate the communication of information from one multiplication to another, if we could accelerate the rate at which data was moved from memory to compute, regardless of the shape of the model, we would be able to accelerate the results. And so we— what we sought to do was go under the level at which there was movement and say, as long as AI depends on linear algebra, we'll be able to accelerate it. And that worked out okay for us. We designed this architecture before Transformers existed, and we're the fastest at it by nearly 2 orders of magnitude. And so that, that was a, a really good call. But that doesn't mean that, that software isn't sort of fundamental in your, your thinking of your design. We designed not just chips but the whole system and the structure of the I/O. Things like prompt caching, things like new tools and techniques that are being developed constantly have to be thought of both at the system and at the chip level. And right now, I think most companies doing this type of chip architecture in their teams include sort of leading AI researchers. As they think about what to build next. So right now it's really through co-design.
So one thing to understand is that the cost per token served, roughly the cost of the answers you're getting, is improving by a factor of 10 every year. That is an extraordinary achievement. And that's through everything Andrew just talked about and a whole bunch more, better algorithms, better judgment of how many tokens, the context— the context windows that are delivered, the cost of the internal computation. And this is roughly analogous to the difference between the original automobile engines and an engine today. The difference is it's occurring in 5 years as opposed to 70 years or 80 years. But it's essentially the industrialization of platforms. When I was young, I worked among other things on silicon design. I was not very good at it. But of course, this stuff was all invented at Xerox PARC and the early fabs. And I remember going to the early fabs. Recently, I've been going to the current fabs. And they are the transformation from the early bespoke ways in which we did things to the extraordinary complexity of modern-day fabs, who in my opinion are the most impressive things ever built by humans. [SPEAKING CHINESE] It's unbelievable. You must work with these all day.
They are pyramids. They are pyramids for sure.
I'm old enough to be able to appreciate the arc of innovation. So one way to say it, and I'll say it right here, is that we're just at the beginning of the new fab revolution, the new software revolution, the new hardware revolution. If you believe what I said, which is that the economic benefits and societal benefits scale globally, then you should expect enormous improvement. When we first met, I was sort of shocked to see how good his product was, right? How did he pull it off? And the answer is they got the math right.
Andrew, I would like to get your point of view on the question on open source ecosystems that Eric addressed in the previous session.
First, I thought the geopolitical point was Absolutely right and profoundly sort of underappreciated. That we think of the AI battle as sort of maybe, if it's a battle, maybe we don't need to think of it that way, but I think it is between US and China or the West and China. And I think as you travel around the world and you see developments places that aren't top of mind, you see that there's a strategy being played with Chinese open source models exactly as Eric said. And I hadn't put it together that neatly, but certainly as you travel in Africa and you travel in Central Asia and you see the adoption of Chinese open source models, they are really playing a a slightly different game. I think on our side, I think the open source community has historically been sort of extraordinarily good for startups and emerging companies, and perhaps less good for the largest companies. And I think it gives us, as small companies and startups, innovators. It gives us a pathway to compete with those who are deploying 50 or 100 or 1,000 or 10,000x more capital than we are. And so I see it continuing to be rich. I think it happens this minute to be in Meta's interest and they're investing big time behind it. I think The rise of DeepSeek moved OpenAI to announce they would have an open-source model, which I think is very positive for the industry. I think crowdsourcing some of these costs, you know, allow you to get $1.50, $2 million token prices as opposed to $100 million tokens, which is what you get in the, some of the closed-source models. And that drives creativity and adoption.
So another question that I don't know the answer to has to do with what happens when you have an open source app on your powerful smartphone that does LLM work. So the next interesting transition in my view is when these things are powerful enough, they're just part of your daily life. It doesn't have to get off phone, if you will. What does that look like? It's a question I don't know. Who will dominate that space? What will you be able to do that you cannot do when you're— that you can do that you cannot do today if you're not connected?
Yeah, I have a rule in my career that if my mother uses it or buys it, I don't make it or sell it. So I'm not a consumer-focused hardware guy. Yeah, of all the jobs, the one I like least is being director of IT of my father's house. But I think what we do know is the way that we will feel that transition. And it's— we won't. It will sneak in. In the exact same way the following facts snuck into our lives that at some point we woke up and realized we'd rather have our phone than our wallet with with us, and that the phone was more useful than your wallet. You could do everything you could with your wallet, and then it replaced your car keys too. And so if you're going to lose something, don't make it be your phone. It's perfectly OK to lose your car keys. You get an Uber. You get there, whatever. You lose your wallet, you've got your credit card in your phone. You can still buy things and get to wherever you need to go. And that happened one day without noticing. And as these things that the phone does through LMs, as they emerge and as they sneak into our lives and they become run of the mill, we're going to wake up one day and say, holy crap, I would have much rather had my ex a few years ago. Now I can't give up my phone for that either. So I don't know how it's going to happen, but we know what it's going to feel like. And it's going to feel like nothing.
Regarding the AI CapEx allocation.
Keep spending. No, no, all of you. Keep going.
Where should capital be allocated? Is it on raw compute, power efficiency, vertical integrations, or new architectures for new, I mean, new chips?
I think part of What's exciting about what we do is something that Eric at Google taught the world, and that's that search should be instant, right? And that was something that Urs and you guys did where you showed that if you make people wait, they lose attention and they go elsewhere. And as we now move to inference in AI, the exact same thing is happening. If you make your customer wait, they go elsewhere. There was a great Twitter stream where Paul Graham wrote, he said something like, "I'd use Google a great deal less if ChatGPT were faster." And then Sam jumped in right behind it and said, "We know we're gonna fix it." And then Elon jumped in and said, "We're not so slow." And so in 3 tweets, you had the penalty for being slow, your customers leave you, and your competitors use it against you. And so I think that is going to be fundamental. I think that's a system-level question, and you're asking each of us. Each of us should spend money in those domains we believe we have real advantage. I shouldn't spend money in domains we don't have advantage. We should be building chips and we should be building systems and we should be finding customers to whom we can provide unique advantage. And those customers should be buying equipment to the extent they can provide advantage, right? And you pointed to several domains that are in desperate need of data. And the truth is, is there's plenty of data in biology and life sciences. It's just not available to everybody, right? Mayo Clinic has 30 years of millions of people of data. The UK government has every MRI taken of the entire population. They're just not available in the same way the exhaust of your internet traffic was available for the largest companies to scrape and use and train. So some of that data's there. It's just not available for everybody. It's in a select few. What do you think?
[SPEAKING GERMAN] So 2 years ago, If we were here, I would have made the pronouncement with great confidence that the computational split would be 80% essentially training and 20% inference. It sure looks like that's completely wrong once again for me. Dario wrote a very nice paper called Machines of Amazing Grace, where he talks about 3 scaling laws, one which is deep learning, which we're in the middle of. Scaling laws are where, as you add more hardware and money, you just get these emergent effects at each order of magnitude. It's well established that it's true for that. He makes an argument that for reinforcement learning and also for test time compute, which is a form of learning, you have two more scaling laws coming. And so when you're climbing these scaling laws, you don't know where they turn, where the scaling stops. One of the questions I ask everyone I know is, when will the scaling laws stop? When will the asymptote be approached? And the answer is no one knows. And that's why it's such a tantalizing time. We're at a point where we don't know when the slope changes. We're in the steepest part. Our industry is described, well understood as S-curves. Nothing happens, things happen, and then it explodes, and then it matures. We're in that explosion phase.
Isn't it fun?
It's fun.
It's great fun.
And by the way, it's where everyone wins, right? More revenue solves every known problem, and everyone has revenue. And eventually what happens is the industries consolidate. We're not in that phase yet. And there's no sign of it anytime soon.
I think most of us would say maybe it would be 80/20 the other way. I think inference is how we use AI. Inference compute will be driven by the number of users, the frequency of use, and the amount of compute used in each use.
And especially from reinforcement learning.
That's right.
That's our RL and back and forth uses thousands and thousands more computation.
And so as you watch this exponential growth of inference demand, we know exactly what underpins it. More people are using it. They're using it more often. And the actual compute they're using, as you described earlier in your talk, of reasoning or agentic, also uses more compute. And you can just think of yourselves, if your marketing organization a year ago, maybe they used it once or twice a day. Today, people go into it 5, 10, 20, constantly throughout the day. And that's one application in one space. And so if you just layer these on top of each other, you're gonna see a continued explosion in the space. Demand for inference.
And which metrics should we be using to gauge and analyze this AGI traction? Is it tokens per second, no-brainer, or do you see other—
I think Eric said something really interesting about these consecutive S-curves. And not only are they really fun to be in, but part of the fun is you don't know when the slope changes, right? That's exactly— not only is it extraordinarily interesting and fun, but you don't know, and it makes forecasting unbelievably challenging, and it makes creating metrics new and difficult because nobody's ever seen growth like this, right? Should Cursor be growing faster? What if they were run differently? Should they be at $500 million instead of $100 million a year? We don't know. We're measuring based on rules that apply to SaaS companies. And I think one of the things that's so exciting is not only are we inventing new things, but we're so far out in the ocean, sort of where they used to say, here be dragons, that we don't have the right metrics. We don't know what a great company in our space ought to do because all the traditional metrics are being blown up. That said, you care about how fast your customers get answers. That's tokens per second. That's how they see the results of your AI and of your software is they see it, they feel it by how quickly they get a result.
On alignment and safety, like how much of alignment responsibility lies at the hardware level and versus the software and algorithmic side?
So, um, for those of you who have not been following it, alignment is the term devoted to having these systems reflect our values, our laws, our rules, our customs, and so forth. Today, the models have— they essentially generate a raw model, and then they have teams, so-called safety teams, and they use various approaches to try to figure out where the model is dangerous. So they've now developed tests. There's a a general movement to sharing those tests among the industry, although not the models, but just the tests. They test for that. The question now is, how do you keep alignment in self-improving systems? And this goes back to the question earlier you asked of how do you know what it knows? So the question I keep asking in the conferences and meetings that I run is when this new thing shows up, how do you know what it knows without releasing it? And if you release it, you might have a terrible outcome on day one because these things are asymmetric. [Speaker] Move. [Speaker] And various people will argue with me, but here's the example. Let's imagine that this thing develops a new, on its own without any prompting from humans, something which could harm harm a million people, a cyber attack, biological attack, or so forth, and it also understands hiding. So when you ask it about it, it doesn't tell you, right? So imagine that scenario. How do you detect that, right? So today, the way they do it, the companies do it, is they have very, very smart people who have an idea that this might be true, and then they do partial tests and they explore that. That's the best that what we can do today. The alignment problem is not fundamentally solved. There are various safety institutes. The French put on a big show in February supporting AI safety institutes. The UK did as well. The Trump administration has largely renamed the safety institute into security, focused much more on China and so forth and so on. I hope that that's pretty much the same. But the underlying alignment problem is a real one, and it needs a lot of very smart science and testing, software and people.
Very clear. Last question, very linked to alignment. I think Andrew, with the Cerebras team, you did a very good job building the sovereign AI stack for UAE, working hard with G42, Co42, And so regarding Europe, what does sovereignty mean in an AGI era? And can Europe build its own infrastructure, custom silicon, serving clouds to be prepared?
Of course they can. They just have to do it, right? I mean, I— of course you can. I mean, there are plenty of smart people. There are investors who are looking for big returns. I think you have to want to do it. You have to be, you have to create generations of entrepreneurs who are excited by really hard problems and of, you know, with 100% certainty, if it becomes a priority, they can do it.
So a national priority. That's right. As you did in the UAE.
I think, a national priority. We have to make a decision about the way you want your economy to look, what you're going to reward. Are you going to generate enough computer scientists, mathematicians, physicists, engineers to create a pool that can feed an industry? But of course you can do it. It can be done. I mean, Singapore has a really interesting hardware ecosystem. And it's a one-city nation. And I don't know what you think, but I think, of course, you just have to have the will.
One word, electricity. These systems are completely limited by electricity. In Europe, electricity costs are high. I think in your next version of this conference, you should have a whole section, put the map of electricity costs of the world and try to interpret where the growth will be. I suspect subsidized or inexpensive electricity will be a dominant component of that.
Cost is high and it's expensive to move. It has some unusual properties. But the truth is, in France right now, you guys use— you have some of the cheapest, cleanest energy. You just tax the living daylights out of it, right? I mean, you can make energy for really very little here with nuclear. And that's choice. That has to be made as part of an industry-level plan.
So the closest way to AGI is nuclear? So we should—
Look, I think people talk about now the unit is a gigawatt facility. And a city like Pittsburgh, I think it's the 4th or 5th largest city in the US, consumes 3 gigawatts.
It's useless to know that the large nuclear power plants are around 1.5 gigawatts.
Right.
Right. That's— we need 2 per large data center.
That's right. You need a whole city.
Think about it. How many nuclear power plants have been started in the United States? 1 or 2. How many have been successfully deployed at that scale? Effectively 0 in the last 20 years. So we're well behind. I was testifying about this in Congress. And the data that I presented was that we needed 92 new nuclear power plants within the next decade in the United States, which of course everyone just sort of blanches on.
Any closing words, Andrew, Eric?
I'd like to be on a panel with him again.
We're good friends. See you next year, guys.
Thank you all. Thank you, Andrei.
Thank you, Andrew Feldman.
More from Andrew
How Cerebras is Democratizing AI at Scale with Andrew Feldman, CEO of Cerebras
Cerebras CEO, Andrew Feldman on Why Raise $1BN and Delay the IPO & Why NVIDIA’s Worried About Growth
⚡️Raising $1.1b to build the fastest LLM Chips on Earth — Andrew Feldman, Cerebras
Andrew Feldman, Cerebras Systems | theCUBE + NYSE Wired: AI Factories - Data Centers of the Future
Andrew Feldman | How Cerebras Built the "Impossible" AI Chip Now Challenging NVIDIA