Andrew Feldman, Cerebras Systems | SC24
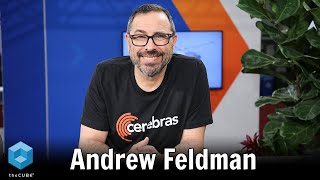
Cerebras CEO Andrew Feldman demonstrates a 46,000 mm² chip that runs Llama inference at 969 tokens/s, 75 times faster than comparable NVIDIA Azure instances. The company's wafer-scale approach uses tiled architecture with redundancy to turn defects into usable resources, serving customers like G42, GlaxoSmithKline, and Mayo Clinic.
Chapters
Welcome back, everyone, to The Cube's live coverage here in Atlanta for Supercomputing '24, SC '24 as it's called. I'm John Furrier, host of The Cube with my co-host Dave Vellante, also the co-host of The Cube Pod every Friday. Check it out. We're recording it this Wednesday because we're traveling. Our next guest, Andrew Feldman, entrepreneur, co-founder and CEO of Cerebra Systems. Andrew, welcome to The Cube because We've been talking about for now 3 years about this whole systems culture, systems revolution. You are not only living it, you're building it, you're rolling it out. You have the big chip.
Yes, I'm— that we do.
Thanks for coming on The Cube.
Thank you for having me. I really appreciate it.
So first of all, before we get started, show the device because I think this is super important. It's a big— it's a chip. Explain what this is.
This is the largest chip in the history of the computer industry. So this is a chip that is 46,000 square millimeters. As you guys can see, it's the size of a dinner plate. Traditionally, chips are the size of a postage stamp. A chip this big processes more information in less time using less power. And that's the goal. What we do is we don't sell the chip.
Can you flip it around?
Yeah, sure. We don't sell the chip. Okay. We use it. In a system we built to deliver extraordinary compute performance, both for training and for inference.
Awesome. And I bring this up because I want to set the table with the size of the chip first because, you know, traditionally smaller, faster, cheaper was the old way. Okay, now we've got bigger and better with these clustered systems. We've been writing about it on SiliconANGLE. Dave's heading up our research team and I've written research notes that it's the systems of servers together, Ethernet networking components interconnect, you're seeing bigger chips because they're optimizing.
That's right.
Core performance that's needed. And GenAI is requiring massive resource. This is a fact. People now, it's no debate. That's just fact. Now, okay. Now the next level question is that what software runs on this? How does it change the existing configurations of the classic— I call the holy trinity of the compute industry: storage, networking, and compute. And then now you got connected cloud, on-prem, edge, full distributed computing environment at scale. This is the internet. This is where we are. What's the significance of this? How does the chip size matter? What kind of software's coming? I know it's a big question, but span.
Well, it is a big question. It's an everything question, right? I think obviously big chips aren't right for everything. They're wrong for your cell phone and they're probably wrong for your car. But in AI, We're not interested in the behavior of one chip. We're interested in the behavior of tens of thousands of chips. And tens of thousands of little tiny chips creates a tremendous complexity trying to tie them together again.
Yeah.
All right. And that's— remember, when chips start, they start as a wafer. They're cut up into little pieces. All right. They're put in different machines and then we tie them back together again to get them to behave. You know, we put Humpty Dumpty back together again. Our view is why are we cutting them up? What if we could yield the largest chip in history? What if we could keep more information on the chip? We would use less power, we would produce results in less time, and we would make it vastly easier to program. And that was our vision 8.5 years ago at Cerebras. And it's been a phenomenal run since we have deployments around the world. It's been an extraordinary run.
I remember I first I mean, I first heard of Cerebras, you know, in the news, but then Anastasia on Tech did a deep dive. She's amazing.
She is amazing.
And she talked about the power efficiency, the performance, the number of transistors, the more efficient software capabilities that you have. And she also talked about the yields. And you just mentioned yields. And I thought, well, maybe the yields are going to be worse, but you had yields of better yields. And explain how you achieve that with such a large form factor.
Sure. So many people told us this couldn't be done.
Right.
And the first, the first reason, and you know, the world is filled with people who say it'll never work. It can't be done. Right. We have no interest in doing business with them. Those aren't our people. Our people are, are the engineers who say, if he says it can't be done, I want to do it. All right. Those are, those are our people. The first thing, those with a mouthful of it'll never work. What they said is you'll never yield. And that's because every wafer has some flaws that are inherent to it. And traditionally, as we put little chips on them and then we cut up the wafer into little die, we tested each die and if they had a flaw, we threw it away.
Right?
That's right. Right. And everybody said, well, you'll never have a full wafer this big that doesn't have a flaw. How are you going to yield a part? And what we knew was that there were other ways to manage flaws. And in fact, in memory, they manage it very differently. In DRAM, they have almost perfect yield. And they have almost perfect yield because they have a repeated tile design. They have hundreds of thousands of bit cells, each identical. And they have redundant rows and columns.
Whoa.
And when they have a flaw, they map it out use one of the redundant cells and keep going.
Oh, okay.
And so we came up with the idea, mostly my co-founders, JP and Michael and Sean and Gary. They came up with the idea that if we built a repeated tile design with hundreds of thousands of identical tiles, if one was a flaw, we could have some redundant ones layered in. And we could shut down the flaw and use the redundant tile. So the whole idea was built to withstand flaws, not need to eliminate them. And we yielded it right away. It took us about 18 months, about $10 million to solve a problem everybody in the industry said could never be done.
I mean, I think about log structured file back in the storage days. This is obviously, you know, in real time.
That's exactly right. That's exactly right. I think that was That's some of the magic of doing work that other people say can't be done.
Talk about some of the examples you guys have in production right now because the research that we're seeing in the marketplace relative to your value proposition is that technical people love this. If you go to the MLOps folks, people who are grinding right now, then you got an onboarding wave of developers coming in. We do. You guys had great benchmarks. We just covered it on SiliconANGLE this week. News, talk about the news of the performance gains, record numbers, and talk about the efficacy of the benchmark.
Sure.
And if you can comment on the— I won't say whitewashing the benchmarks, but I mean, you could kind of fudge the benchmarks if you throw more power at it. I mean, like, anyone can get more anything if you— so talk about, like, how should we evaluate benchmarks? Talk about the news and the benchmarks.
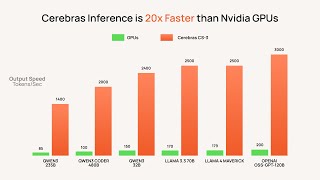
So at the show, We launched inference support for Llama 4.0-5B. This is the largest open source model, and we launched performance numbers of 969 tokens per second. To give you an idea, Azure NVIDIA running under Azure is at 13 tokens per second. All right. So we're more than 75 times faster than hyperscalers are offering NVIDIA. Product. This is the fastest in the industry, bar none. And so we were— we're really proud of that. And today, since we launched our inference services in August, we were the fastest and have been the fastest every single day at Llama 8B, Llama 70B, and as of yesterday, Llama 405B. We're so fast that it changes the way you can use Llama. 405B and you can use it to compete effectively with the largest closed-source models. So that's the first answer to your question. We do both inference and training. We have partners around the world. Our largest strategic partner is a group called G42. And with them we have deployments that have built supercomputers measured in exaflops, built them in Santa Clara, California, built them in Dallas, Texas, and now we're building them in Minneapolis, Minnesota. We've trained leading models right now. The premier Arabic-English model, LLM, is a model that we worked with G42 together to train, and it's now being used by hundreds of millions of native Arabic speakers. We've trained models in Catalan, in Kazakh, in, in Hindi, all of which is in our training business. In our inference business, business is exploding.
Yeah.
Remember, Training makes AI and inference uses AI. And right now people want to use AI like crazy. And what we're seeing is overwhelming demand for inference.
And the technical people like to talk about the inference as the killer app because training is like going to school. I don't go back to 4th grade. I train and then I get— maybe I reinforce my learning, but I infer and try and solve for X. I go to school, I get trained, and then I graduate and I infer in the real world. That's like AI brain. And then I reinforce it. This is that— this is AI. AI is very brain-like. How do you guys do on inference and how do you sell to your customers? Because is it— I mean, I can see Amazon and Azure. I want to build my own system. So where are you guys targeting? I know you're going right after NVIDIA. You guys are pretty clear on that. The big red, the big green machine, I call it. What is the killer app for inference and how does that compare?
NVIDIA is a great company and nobody's done better over the last 10 years. I think in 2014 they were worth $10 billion. And today they're worth, what, $3 trillion? I mean, an extraordinary run. But this is a very big market and there's room for a lot of winners. And we're going to do our best to put ourselves in front there. So we're one of those winners. I think high-performance inference is a game changer. What OpenAI recently showed is that you can use performance to get better accuracy. What we all want is more accurate models. And what they've shown is through techniques like agentic models and through techniques like chain of thought, you can use speed to ask the model to improve itself, right? In a train of thought flow. And the accuracy of the model improves. And when you're 10, 20, 50, 70 times faster than the competitors, You can use some of that time to improve the accuracy of the model. You can give the user a better answer and they won't even notice. And so what we've, what we've pioneered is the fastest inference bar none.
So I want to come back to a couple of things. So it seems to me that, well, of course, the economics of training LLMs are just horrendous, right? Have you got a—
it's an expensive process if you have to adhere to the scaling laws.
And you look at the cost per token, price per token, it's just painful.
It's expensive.
So you help with that problem.
We do help with that problem.
Okay.
It's still a huge problem.
Even a huge problem. There are two parts of the problem. There's the capital that goes into buying the equipment, and then there's the operating expense, which is almost all power, using it, right? The power used at the data center. And we cost less to buy and we use less power to generate blocks. So we help on both of those tokens. But even then, training giant models is expensive.
Okay. And then the other is I've talked to financial institutions that say they don't want to use a closed LLM, proprietary LLM. They don't want to use Llama because they're afraid of the fine print. And so they said, we're going to build our own. Now we'll see. They used to say that about the cloud.
They did.
But they have money and they're talented. And a couple of them have said, well, we're bringing this Cerebras and we're going to build our own model. And so that's another opportunity. I know you can't name names, but is that a trend?
I'm happy to name names. I mean, customers like GlaxoSmithKline have trained their own models on our machines. Customers like Mayo Clinic, we've announced, trained their own models on our machines. We've announced customers like TotalEnergies, We signed an MOU with Aramco. And as I said, our work across the G42 companies, including Core42, MBZ UAE, and a collection of others in the United Arab Emirates that are leaders in their field, all of whom are using both open source and training their own, using their own data to create advantage through AI.
And I know of at least two others that you didn't mention, so I won't. Well, but so and then The third piece is on the inference side. Our vision of Agentic is that these agents, you know, people think these agents are like, you know, God agents. No, they're worker bees.
They're worker bees.
But they will learn from human reasoning traces.
They will.
And they're going to need like really powerful inferencing to do that. And that's how we're going to automate that long tail of processes that are unautomated today. That's a multi-trillion dollar opportunity.
You know, that's right. In 2017, the guys at OpenAI published a paper. I think Ilya Sutskever, one of the founders, published it. And what he said was that they were able to identify a scaling law, a law that said as you added compute to an infer— to a training problem, all right, the accuracy would improve and they could see no end.
Listen, seconds.
Now, over the last 5 years, the amount of compute we've needed to train a frontier model's improved, increased by 40,000x. Now, a few months ago, they announced they found the same thing for inference. That as you add more compute, exactly as you said, as you ask it an answer and ask it for an answer and then ask it again and ask it to improve it again, it continues to improve as you add more compute. And this is what's led many to say inferencing by itself, separate from training, is going to add Millions of acts of compute required.
I don't want to ask you because people think it's an either or, and it's not an either or.
It's not.
But correct me if I'm wrong, that paper, I remember it. But aren't there diminishing returns? You not only need compute, you need data, you need parameters, and you have to— all three have to scale together.
All true.
And is it true that basically they're running out of data and the synthetic data is maybe an answer to that? But that synthetic data is not going to be able to replicate JP Morgan Chase's proprietary data. So that's a huge opportunity.
I think there's a tremendous opportunity in the creation of synthetic data, but I think also there's an opportunity for those companies that have spent the last several decades marshaling and husbanding their data. Right. Mayo Clinic has one of the great medical repositories of data, patient records, MRIs, film, tissue samples, genetic data. There's a huge amount of insight there. Now, these aren't companies that scrape the internet for their data. There's a place for that too. But these are companies like Total who have seismic data. All right. Or Aramco or ADNOC that have billions of dollars worth of data that has been collected. GlaxoSmithKline, Novo Nordisk, they have spent unbelievable amounts of money gathering data over the years. And now there's an opportunity to use these tools to find insight in that data.
Yeah.
All right. And I think there's a tremendous opportunity there and we're just beginning to scratch the surface.
We wrote a post on SiliconANGLE, Dave, authored with George Gilbert and the team. And what we said was that title is a little bit salacious to get the— we don't really do clickbait.
It's not true. It's not true. The headline wasn't designed for—
no, we usually don't design for salacious headlines, but in this case it was designed to get attention. And they said in the headline, Jamie Dimon is Sam Altman's new competitor. Basically to make the premise, hey, the enterprise has data and they're not going to go to OpenAI to do it. They're going to build their own OpenAI for themselves, meaning their own language model. To your point, this is what you're squarely going after from what I can tell, right?
We are going after people who have interest in datasets and who wish to find insight in them through the use of models they design, through the model— use of models we help them design. Or through third-party models that they pay for. I think those are absolutely the bullseye for us and we've done really well with them.
Okay, so you sold me on— I love the big chip, so I'm a believer, obviously been for a while. I think that's the right way to go. So I think the enterprise is a huge opportunity.
So does NVIDIA, by the way. Right. I mean, NVIDIA in 2015, their chip was 400 square millimeters. 5 years later, right, their chip's 800 square millimeters. Now they're big chips. Now they've gone from 1 to 2.
Trying to recreate what we've done with our big chips, with big shared S, which brings other challenges.
Big chips, big chip. It's a big game with big chips.
That's right.
Okay, so I'm sold on the big chip. So I buy that in the architecture. Now the conversation now goes into the power law of big, and then you have medium and small chips and small language models. So you start to see the evolution of distributed computing.
Sure.
I can't put a big chip on a camera.
No.
To do computer vision. So How do you see your vision as you look at the architecture emerging where I'm going to have to do inference at the edge? How does that system work? Take us through the vision because again, you mentioned earlier things are connected, right? What's your vision there?
I think there will be a tremendous opportunity for little chips at the, at the consumer electronic edge, right? I mean, in, in your phone, right? We're going to put a little bit of inference there.
But those are big chips, too, by the way.
These are bigger chips.
Apple.
That's big chips. We're going to do a little bit of inference here.
Compared to the big— their chip is small.
That's right. Maybe in the car you can have a little bigger chip because you have a bigger battery. All right.
Okay.
But what we saw in the Arm x86 world was the rise of compute in the phone didn't diminish the rise of compute in the data center. In fact, it accelerated it.
Absolutely.
That people wanted to use apps on their phone, but when heavy work needed to be done, The call went back to the data center and the exact same thing is going to be happening with the car. We're going to do inference in cars as we are already with the self-driving cars, but that's not where the model is going to be trained. That's not where the QA is going to be done. That's not where new things are going to be developed. Those are all going to be worked on in the data center. And so I think they work together and far from sort of nibbling at each other's pie, they make the pie bigger. The more applications that are at the consumer side that use AI, the more need there is to train models in the data center, the more need there is for inference at the data center as well. It's a flywheel.
Yeah, it's awesome.
That's why one other thing, it's really important that you're able to do both training and inference. I think if you want to be a player in this market, it simply isn't enough just to do inference. Yeah. Your customers are going to want, once they've got their model going, want to fine-tune it.
Yeah.
They're going to want to improve it via training with new data. So you need both.
And that's why it's not an either or. By the way, Jensen agrees with you.
I think we agree on many things. Some we don't.
Yeah. And then one thing that you both agree on, that's the software coming to beat GenAI, to be on the winning side of history is you got to have your— you got to have the machines and the architecture. And this is a big point around the systems thinking.
This is a system problem, right? I mean, in 2015, 2016, When we started the company, we were going to build systems from day one. This is my 5th startup and all previous companies were system companies. We love that. We're system builders. I don't want to sell chips. We want to sell systems. Now at that time, all right, everybody else is selling chips or chips on PCIe boards. All right. NVIDIA saw the light. They moved to building systems like the DGX. Right. Recently, what did AMD do? AMD acquired ZT, a system company.
Yeah.
Because once you build a race car engine, right, you don't want to just hand it to some random carmaker and say, make me a race car. You want to build the entire race car.
Yeah.
And if you do, you can make it fast.
Yeah.
But you can optimize it.
You can optimize every aspect of it.
Yeah.
Every aspect.
Clustered systems. Welcome to the new era. Andrew, thank you so much. I wish we could do an hour on the podcast. We'll have you back on for podcast appearance on our Friday show.
Happy to be back anytime. It's really fun talking to you guys. Thank you so much.
Yeah, we are living in a systems revolution. This is the new era is here. The old era is gone. The new way is coming. Architecture, systems, software, and it's going to repeat itself in a virtuous circle. So TheCUBE will have all the coverage here on TheCUBE. Thanks for watching here live from Supercomputing 24. I'm John Ferriero with Dave Vellante. We'll be right back.
More from Andrew
How Cerebras is Democratizing AI at Scale with Andrew Feldman, CEO of Cerebras
Cerebras CEO, Andrew Feldman on Why Raise $1BN and Delay the IPO & Why NVIDIA’s Worried About Growth
⚡️Raising $1.1b to build the fastest LLM Chips on Earth — Andrew Feldman, Cerebras
Andrew Feldman, Cerebras Systems | theCUBE + NYSE Wired: AI Factories - Data Centers of the Future
Andrew Feldman | How Cerebras Built the "Impossible" AI Chip Now Challenging NVIDIA