Cerebras AI Day - Opening Keynote - Andrew Feldman
Andrew Feldman argues AI's bottleneck is distributing training across thousands of GPUs. Cerebras built a single wafer with 900k AI cores and 4 trillion transistors to hold entire models on one chip. The CS-3 system adds memory and scaling fabric, letting companies like Mayo Clinic and G42 train without distribution overhead.
Chapters
Look, ladies and gentlemen, please welcome to the stage one shot, the one, the only, CEO and co-founder of Cerebris. Andrew Feldman! Thank you guys for coming. It's so nice to see so many people here. In 2016, in March, 5 guys got together and we thought we could build a company. We thought that AI would be an interesting workload. We were wrong. It's not an interesting workload. It's not the most interesting workload of our generation. It may well prove to be the most interesting generation in the history of the computer industry. And that's where we're going right now. Now, AI— The expansion of AI, as everybody in this room knows, has produced unprecedented growth. And it has sort of fundamentally altered computing. We've moved from a world in which software was running on a single computer to supercompute performance. This has a really interesting ramification, and we can see it taking shape right now. It's creating haves and have-nots, those who can and those who can't, those who can afford big clusters, those who can't, those who can afford giant teams of AI practitioners and those who can't. And we'll talk a little bit about how that unfolds and how at Cerebras we're here to solve that problem. AI developers are struggling with distributed compute. And I don't want you to believe me. I know it's unusual for a guy to stand up and say, don't believe me. All right, just read what used to be Twitter, right? Read the smartest software and ML guys you know of. Ask your teams, all right? Ask them if they're frustrated every day trying to do big distributed compute to get their big models over hundreds or thousands of GPUs. Nobody smarter than Andrew Karpathy. He's a pioneer in our field. It's hard for him. All right, it's hard for your teams, it's hard for our teams. This is a painful problem. Yi Tei, also not a dope. Ivan Zhao. We could put hundreds and hundreds of these up of people who are practitioners, are the best at their business, and struggle. But I don't want you just to listen to what they say. I want you to watch what they do. Okay, this is GPT-1. It was 120 million parameters. 4 people trained it. 4. Now GPT-4, 240 people were involved in training it. 35 just for doing distributed compute and just for supercompute wrangling. Okay? And this is for a very, very simple reason. It's hard, and it's hard because big models don't fit on GPUs. Okay? It, it's not complicated. It's when your model doesn't fit on a GPU, What do you have to do? You have to cut it up. And when you cut up models, what does that mean? That means you have to spread them out over GPUs. And what does this do? This means you gotta write a lot of software to allow them to communicate with each other, to tie back together. And what have you done? You've turned an AI problem into a parallel computing problem. You've taken AI, right, and made it distributed compute. And you've turned compute infrastructure into supercomputer infrastructure. And this is brutal. Now what does it mean to your teams, to the people who are doing this? What it means is they go from what fit on one processor, about 600 lines of code, to tens of thousands of lines of code, right? This is to be avoided at all costs, right? This is the death of productivity. All right, this is what you never need to do with us. This is why we exist at Cerebras, is to help you avoid the problem of distributed compute. And how do we do that? We do that by building chips that are big enough to hold the entire problem. It's just that simple. Build really big chips, except nobody's ever done it before, that can hold the entire problem. So this is why we announced last week the largest chip ever made, not by a little bit, by a lot. Thank you. I want you to notice that I'm not doing this. All right? Everybody see what I'm not doing? All right? This is 46,000 square millimeters of silicon. This is 4 trillion transistors. It's not 2 chips taped together. All right? This is a single wafer with the largest square possible cut out of it. This is 900,000 AI cores. This is 125 petaflops of AI compute. Now, as students of history and no longer being young, we can take a big view. And every chip in the last 52 years has followed the same trajectory. Okay. They followed the trajectory of Moore's Law. Except us. All right, every chip for 52 years is on the white line, and we're on the orange line. Now, if you'd like to know where NVIDIA will be, all right, in 10 years, I can show you. It's where we are now. All right, that's Moore's Law continuing on to get them 4 trillion transistors. All right. Now what we're going to do is just pause and stare at my favorite slide of my career. So we're just going to stand here for a little while and we're just going to admire this slide. This is our chip. This is an 80-billion transistor, sad, small, lonely GPU. Now, we don't just build chips, we build systems. And to go build a system, you have to put together a package, you have to cool it. And we became experts over the course of the last 8 years in packaging and cooling. And this is the saleable unit, the CS3. Now, the CS3, has some unique characteristics and includes some technology that is not in the original chassis. It includes a memory appliance called MemoryX. It includes a fabric called SwarmX. Now the memory appliance allows us to go from terabytes to petabytes of memory, even on a single machine. It allows us to go from one machine to more than 2,000 machines in a cluster. It allows us to go from 125 petaflops to 256 exaflops in a cluster. That's a quarter of a zettaflop. It allows us to go even on a single machine from 1 billion parameters to 24 trillion parameters. Now, exascale performance. Is cool. But single device simplicity is a theme you're gonna hear throughout today. You program whether it's 1 machine or 2,000 machines, you program it as if it were a simple single machine. All right. This is why not only have we been able to build supercomputers at a tremendous rate, Here's one. Here's a different one. And we'll talk a little bit about a third. Anybody know what you begin with when you build a supercomputer? Anyone? Electricians. Electricians. All right. That's what you see here. This is Stockton, California. This is a facility of ours. And you begin with electricians. And then you bring in truckers who are moving pallets and forklift operators. Let me show you a little bit about what it looks like to build a 4x axoflop facility. American rock and roll. 64 systems, CS-2s, 4 exaflops of compute, Stockton, California. Now, what we announced last week was we had just started with our strategic partner G42 an 8 exaflop supercomputer based on the new part in Dallas, California— Dallas, Texas. Dallas, California would be an interesting political environment, wouldn't it? Maybe we give them Orange County. In 9 months, we'll have stood up 2 4-exaflop supercomputers and an 8-exaflop supercomputer in Santa Clara, in Stockton, and in Dallas. Now, we then use this compute to do interesting things. And we use this compute with all the benefits we're bringing to our customers. We train not tens, not hundreds, but thousands of models. And here's an example. Working with G42, we trained the world's leading Arabic-English model. There are 400 million native Arabic speakers. There wasn't a model for them. Okay, we trained this model. It outperformed any other model every competitor by heads and shoulders. Microsoft has taken it. It's now the foundation of their Middle Eastern service served off Azure. We've also partnered with Mayo Clinic, and they will be here in a little bit. You'll hear directly from them to build models to drive better outcomes in healthcare. Right, healthcare, 17% of GDP. If we can't use AI to do better there, what are we doing? Working closely with, with Mayo, they have some of the great data sets, medical data sets in the world. We achieved HIPAA compliance so we can work directly with this extraordinary patient data sets. We're doing extraordinary work with them. Energy, energy's 12% of the economy. Our partnership with TotalEnergies, has dramatically improved their exploration function. And you see here, we were able to do just a little bit faster than their existing GPU infrastructure, right? Orders of magnitude, not one, two. Oh, this is Tony. Tony was president of KAUST. This was a world record in this case. Our team worked together with them. They borrowed 48 of our systems and we outperformed 37,000 GPUs in the largest supercomputer on Earth in Frontier. 48 of our machines. So whether it's extraordinary models, whether it's world records, right? These are the results you get when you have huge compute that's easy to use in the hands of people who are driven to produce interesting results. And this is why last year we booked a quarter of a billion dollars. You can clap at that. OK, so what we're going to do for the rest of today, you're going to hear from our customers. You're going to hear from my co-founder, Sean. And we're going to dive deeper and hopefully have a little fun afterwards, all right? All right, thank you for coming. And now we'll turn it over to Sean.
More from Andrew
How Cerebras is Democratizing AI at Scale with Andrew Feldman, CEO of Cerebras
Cerebras CEO, Andrew Feldman on Why Raise $1BN and Delay the IPO & Why NVIDIA’s Worried About Growth
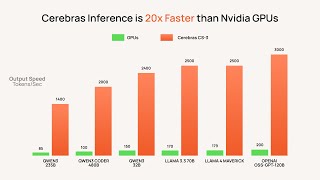
⚡️Raising $1.1b to build the fastest LLM Chips on Earth — Andrew Feldman, Cerebras
Andrew Feldman, Cerebras Systems | theCUBE + NYSE Wired: AI Factories - Data Centers of the Future
Andrew Feldman | How Cerebras Built the "Impossible" AI Chip Now Challenging NVIDIA