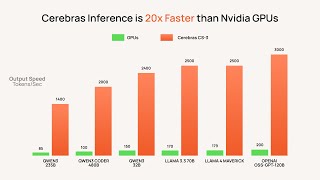
In this keynote, Cerebras CEO Andrew Feldman argues that inference speed is the decisive factor in AI product success, likening rapid AI to the disruptive impact of fast internet on entertainment. He presents benchmark data showing Cerebras’ wafer‑scale engine delivering up to 20× faster inference on models such as Llama 4, Mistral, and Anthropic compared with GPU solutions, and highlights token‑throughput gains across a wide range of models. Feldman explains the engineering philosophy behind the third‑generation wafer‑scale chip (over 200 billion transistors) and how its size enables low latency and high output token rates. He outlines Cerebras’ expanding deployment footprint—data centers in Sunnyvale, Stockton, Dallas, Oklahoma City, Minneapolis, and upcoming sites in Montreal, Atlanta, and France—delivering the hardware via on‑premise systems and a cloud service. Partnerships with Meta (API service), IBM Cloud, and customers ranging from large enterprises like GlaxoSmithKline to tiny startups are showcased. Finally, Feldman shares the company’s long‑term vision: using the hardware to solve two humanity‑scale problems that affect millions, positioning speed and scale as the engine for that impact.
Chapters
One of the few great joys of being a CEO is you get to pick your own walk-up music. So thank you for coming. Um, about once a year we, we like to gather our friends and community together to share a little bit about our thoughts of what's happening in, in the AI ecosystem. And it's a, it's a pleasure to see you guys here. We are participating in something extraordinary. And AI is the fastest growing technology in history. And it is dwarfing what we used to think of as fast. 3 years ago, there was no market for tokens. LLMs weren't being served. And right now, Microsoft reported that they delivered more than 50 trillion tokens in March. That's extraordinary. And like other transitions, we know that speed matters. We know that speed creates markets. Now I see some of you, not many, remember when Netflix used to send DVDs in envelopes. Right? Right. And before that, where'd you go? You went to Blockbuster. Or you went to that crappy little You had a video store around the corner. You had maybe a card, right? What the fast internet did is it turned Netflix into a movie studio. It moved Amazon from being a bookseller not just to being a movie studio, but to buying MGM. It changed the nature of entertainment completely. This is what speed does. And conversely, this is what slow does. Now, it's rare that you get a chance to see in an extreme the entire reason you started a company. But what Paul describes here is a simple rule. And for those of you who are our friends and who are building companies, I think about this again and again that if your inference is slow, your customers leave you. Right? And there is no better example than this. Now, Sam knew this. And Elon knew it too. And so I think we can add to this, if your inference is slow, your customers will leave you and your competitors will use it against you. All right? And this is why we started Cerebras. This is why we've invested so much of our time and our blood and sweat and tears. This is in every bit of our DNA, is to deliver fast inference and training. And for those who measure and keep track on everything we do, we are the fastest bar none. So we have our friends from Meta here. We are 20 times faster on Llama 4. This is a cool chart, and I love charts, but What does it look like to your customer? What does it look and feel like to your user? So what we'll do is on the left, we'll have the Cerebras Cloud powered by us, and on the right there'll be a GPU solution. Same prompt. Let's see how it goes. All right, we're done. You're going to have to clap for like 30 seconds because I'm going to make you suffer through this whole thing here. There you go. Thank you. This isn't just the case for one model. This is the case across a swath of models— reasoning, non-reasoning, larger, smaller. That before Cerebras, everything sits sub-200 tokens per second output. And after us, on every model, you have vast improvements, order of magnitude improvements. And what this allows you to do is deliver something special and different to your customers. What I'm gonna show you here is on the far right is gonna be Mistral. And in the middle is gonna be Anthropic on GPUs. And on the left is gonna be OpenAI on GPUs. Now Anthropic, uh, Mistral is much smaller. Their model is much smaller, but their inference is much faster because it's powered by Cerebras. This is how you compete with people who are bigger and have more money, by being faster. Even I don't have the patience to make you suffer through all of the ChatGPT. It's that fast. 50 seconds. How do we do this? We do this with a relentless commitment to bottoms-up engineering, to a fearless approach to tackling extraordinarily hard problems. We began by designing the industry's largest processor. Just to give you an idea, This little one on, on the right, that's the B200, a paltry 208 billion transistors. The one on our left, of course, our third generation wafer-scale engine. We put this chip, this wafer-scale chip in a system and then we deliver it to you, our customers, either on your premise or through our cloud offering. And what this gives us is a fundamental and unique advantage. On the x-axis, I've put output speed, and on the y-axis, I've put time to first token. That means you want to be in the green quadrant. You want to be quick to your first token, and you want to have huge numbers of output tokens. Okay. The entire GPU community, all right, is packed sub-200 tokens per second. All right. This is not our graph. It's from artificial analysis. It's a visual— it's sort of a picture of what's called the memory wall. None of the GPU-based solutions can move to the right. Good software, interesting work can drive them down to lower latency, but they struggle. To get you output performance. Where do we fit in? Over here. In fact, we were so far to the right that people were missing us, so I had to put in the orange arrow. All right. Some of you joined us last year. For our first event like this. And we spoke a lot about speed. And we said 2024 was going to be the year of speed, and it was. In 2025, it's the year of scale. We began the year with two facilities, one in Sunnyvale and one in Stockton, California. We now have data centers in Dallas, Oklahoma City, Minneapolis, through collaboration with our, our partners, G42. We're building out in Montreal, in Atlanta, in France. Huge amounts of capacity are being brought to bear. Billions of tokens per second can be served. I know not all of you love hardware like I do, but these are really cool. And if you go back and watch an old episode of Silicon Valley, there's a funny episode where the software guys go into a data center and it does nothing for them. To this day, I go into a data center that's filled with our gear and I am so proud. This is Dallas, Texas. This is Minneapolis, Minnesota. This is our new facility coming online in Oklahoma City. And not only are, are you gonna fill these facilities with your work, but so too are our new partnership with Meta announced a week ago where we will power their new API service. For the largest open weight community in the world. We followed that up a few days later by announcing we would also provide inference services behind IBM's cloud, reaching the other bookend of the business demography, right? The largest 100 or 150 organizations in the world to whom IBM services. And over the course of the year, our customer base has grown by leaps and bounds as large companies like our friends at GlaxoSmithKline, who you've heard earlier, 300-year-old pharma companies, as well as 4-person startups have jumped on our cloud and enjoyed the benefits of blisteringly fast inference. Now, I'm often asked, w-w-what do you want for the company in the next 2 or 3 years? We have some of our investors here, and I know what they want. Um, I, what I want for our company is that our hardware be used to solve two important problems for humanity, two problems that impact more than a million people. And that the thinking and the work, the research and the innovation is done on our equipment and the benefit accrues to millions of people. This is why Sean and Gary and Michael and JP and I st— started the company. This remains our vision and our goal. And it's entirely possible that in this room we have the people who, who can help make that vision come true.