Cerebras’ Wafer Scale Engine AI Chip with CEO Andrew Feldman
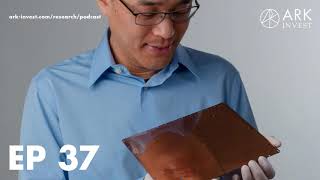
Cerebras CEO Andrew Feldman explains why his company built a 1.2-trillion-transistor AI chip the size of a full wafer instead of following traditional scaling. The WSE has 400,000 cores and a 33,000× faster inter-core fabric than GPUs, designed to handle the explosive growth in AI compute demand that Moore's Law can no longer support.
Chapters
Welcome to FYI, the For Your Innovation podcast. This show offers an intellectual discussion on technologically enabled disruption because investing in innovation starts with understanding it. To learn more, visit ark-invest.com.
ARK Invest is a registered investment advisor focused on investing in disruptive innovation. This podcast is for informational purposes only and should not be relied upon as a basis for investment decisions. It does not constitute either explicit explicitly or implicitly any provision of services or products by ARK. All statements made regarding companies or securities are strictly beliefs and points of view held by ARK or podcast guests and are not endorsements or recommendations by ARK to buy, sell, or hold any security. Clients of ARK Investment Management may maintain positions in the securities discussed in this podcast.
Welcome to FYI, our weekly podcast on innovation and technology investing. This week I talked to Andrew Feldman, co-founder and CEO of Cerebras Systems, a Silicon Valley startup building the next generation of AI processors. At Hot Chips 2019 conference, Cerebras unveiled the Wafer Scale Engine (WSE), a chip 50 times larger than Nvidia's most powerful GPU. If it works, the WSE could be the most significant semiconductor breakthrough in decades. In this episode, we delve into why large chips are needed for AI, the problem with GPUs, the competitive landscape of AI chip startups, and how large the AI market could ultimately be. Thank you first of all for taking the time. I'm sure you've been inundated with outreach and press and things after the Hot Chips conference, but it's just great to connect and would love to chat about chips, about AI market, everything that I'm sure you guys are already excited about.
Sure, happy to do it.
Okay, cool. Well, as a starter, maybe— I know I've read a lot about your technology and what you've built, but for our listeners who maybe haven't followed the details as much and who are not chips geeks kind of by default, maybe could you give a high-level description of what Cerebras has built and why it's so different from any computer chip to date?
Sure. A couple weeks back at the Hot Chips show, we announced that we built the largest chip ever designed. It was 1.2 trillion transistors, 46,000 square millimeters of silicon with more than 400,000 cores optimized for artificial intelligence. And to give you some idea of the scale and the scope, the largest chip that had been previously built was 21 billion transistors and 815 square millimeters. So that's about the size of a postage stamp. And ours is the size of a dinner plate. And that gives you an idea of the scope of the step forward. It's more than 56 times larger than the largest chip previously built. It has more than 1.175 trillion more transistors. It has 78 times as many cores, and the cores are the work engines that do the calculations in artificial intelligence. It has order 3,000 times more memory on the chip. It has 10,000 times more memory bandwidth. And its fabric, the fabric that links the cores, is order 33,000 times faster than, than the competition. So this is a big step, not just for artificial intelligence, but for the semiconductor industry and the We'd solved a series of problems that hadn't been solved in the 70-year history of our industry.
In semiconductors, especially in this era, in the twilight of Moore's Law, we're not accustomed to major improvements. We're accustomed to just eking out a new node maybe every 2 or 3 years. And Cerebras is a startup with, you know, not a humongous amount of funding that's made this breakthrough. Why have you guys built this this incredible technology when the folks at Intel, TSMC, NVIDIA, people with orders of magnitude more resources and expertise and experience and even their own fabs, why did they not build this? And why did Cerebras build this?
I think you put your finger on the heart of the issue, and that's the slow death of Moore's Law combined with the complete death of Dennard scaling. And that combined with the rise of artificial intelligence as a workload and the exponential growth in the compute demanded by artificial intelligence. Moore's Law said once that we got about twice the transistors per unit area every 18 months. Now that hasn't held in a decade, but we get about twice the transistors every 3 or 4 years. But if you look carefully at the AI workload, Between 2012 and 2018, a study by OpenAI showed the demand for artificial intelligence work grew by 300,000x. That's a doubling every 3.5 months, or roughly 25,000 times faster than Moore's Law at its peak. So what do you do? And we thought very carefully, and we saw that if you couldn't get more transistors per unit silicon, we needed more silicon. And we didn't need a little bit more silicon, we needed a lot more silicon. And we needed to solve one of the fundamental problems, which is when you leave a chip's boundary, your communication slows by somewhere between 1,000 and 10,000x. Communication on chip is fast, communication from one chip to another chip is unbelievably slow. And given that the artificial intelligence is a communication-heavy workload, we knew that we had to solve this problem of bringing more silicon to bear on the problem while allowing extraordinarily high-speed communication. And that led us to build very large chips. We're not the only one who saw this. If you, if you looked at one of the leading manufacturers of graphics processing units, Between 2013 and 2019, they increased the size of their graphics processing unit by 50%. So they saw the same things, bigger chips for this work, process more data, and they do it more quickly, producing answers in less time. So that was the motivation. We were extremely bold, and it's a pleasure to lead a collection of nearly 200 fearless engineers. And our guys are not afraid of, of invention. And I think sometimes that's not the incentive structure at large companies. And I think as these projects at large companies get more and more expensive, as they get layers of management, as leaders throw people at the problem rather than throw talent at the problem, you end up in a cycle of becoming more and more conservative rather than more and more fearless in your engineering. To deliver this part, we invented technology and we partnered with TSMC, and they're our fab, and they listened to a company that at that time had 60 people. They recognized the power of our inventions and immediately began working with us, and 2+ years later, we're building the, the largest part ever made by a lot.
Andrew, when you founded Cerebras, did you already know you wanted to tackle the AI problem using a wafer-scale approach? Around 2012 to the current times, I'm tracking maybe 60 to 80 reputable AI chip startups or more in totality. Every single slide, everyone's setup slides are the same. Neural networks, extremely compute-intensive, compute bandwidth, very bandwidth-intensive, you need more flops, you need more gigabytes per second of transfer of data, and the setup The concept is the same and everyone, a lot of the proposed ASICs arrived at a similar kind of architecture in spirit, similar to something like a Nirvana or a Volta. You need tensor cores and you want these high-speed interconnects between chips to allow the training for models that are large. Graphcore went kind of one step further and said, we'll just get rid of external memory because we want everything to be on chip, almost like in the vein of what you guys are doing. But no one kind of looked at the problem and said, well, we need to solve a semiconductor manufacturing problem. Only Cerebras really went that far. Did you know that was the approach you were going to take from the outset?
Well, we knew a couple things. We knew, and I agree with most everything you said, a couple points just to clarify. We— there are a lot of startups, but very few were aimed at training. Most of the 60 or 80 that you're describing chose consumer-facing silicon. Chose inference and a small chip for inference in the phone or at the heavy edge, maybe the car, but they were primarily inference chips. And I think as you look out over the past 15 or 20 years, consumer silicon has been a hard place to be. Mm-hmm. And it's been a very hard place to be in a phone because your phone maker is trying to design you out as fast as they can. It's been a very challenging market for startups. And we looked at that, and that's not where we want to play. We love building things for the data center. And we love solving the hardest problems. And so to begin, we were aiming at training in the data center, and there were only a couple companies that did that. When you build parts for the data center, you have two choices: you can build chips, and you can put them on a printed circuit board and attach them via PCIe and place them sort of as power-sucking aliens in someone else's server. And that's also a strategy that has failed again and again. It's hard to think of a startup that was successful in building a chip, putting it on a, on a PCI board, plugging into other people's servers and building a big business with that. Maybe you go back to Fusion-io who crashed and burned miserably. It's a very challenging strategy because you're in a Dell or an HPE slot, and you've only got a few hundred watts, and you've only got a certain amount of cooling, and you've only got a certain amount of power, and you only have a certain amount of fabric bandwidth delivered to you by somebody else. We knew that that also wasn't for us because we love building systems. And if you look at the companies that have gone public in the data center, whether it's Pure or Nutanix or this collection of others over the past 10 or 15 years, they build systems. And our view is if you're gonna build a Ferrari engine, it's not very good if you put it in a Volkswagen and expect to get Ferrari performance because you don't. If you're gonna build a Ferrari engine, you wanna build the whole Ferrari. And that was our approach from the get-go. And there are only really two other companies that have chosen that. I mean, NVIDIA built the DGX where they saw the same thing. You wanna build the whole machine, not just the chip, but you wanna build the system. And Google. And they build not just the TPU, but they build the entire cluster. So when we look out at the market, we see a small number of companies that decided to go after the data center and training. Of the startups, we were alone from day one knowing we were gonna build a system. And when you build a system, you have a great deal of flexibility. It's harder, it requires more money, but your advantage is vastly larger if you do it. You can control the amount of power delivered to the chip and the way it's delivered. You can control the I/O. You can design a fabric. You have vast flexibility inside your machine. Those were things we knew we needed to create massive advantage. And we knew two things about this problem, that training is a feedback loop and that training, to accelerate training, you have to move things through this loop, move inputs through the loop more quickly. And what's in the loop? There's only calculation and communication, that's it. And so if you wanted to accelerate training, you needed to accelerate calculations and communications. And that meant more cores, that meant more memory close to cores, and that meant vastly faster communication. Which we felt was best solved with a very large chip.
Could you talk a bit about the system architecture?
That was a long answer to a simple question, huh?
Of course, of course. That makes sense. I guess really quickly, when you were already creating the founding team, did you already have in mind that you wanted to do a wafer-scale chip or did that emerge later?
We had in mind we wanted to do a very large chip. We, uh, the founding team is built of my co-founder Gary Lauterbach, who was my co-founder at our last company, who's one of the world's premier computer architects, JP Fricke, who is one of the world's leaders in system and package design. Sean Lee, who's an extraordinary hardware architect. Michael James, who's pioneer in algorithms and software architecture. And we'd all worked together at, at C-Micro, our last company, which we sold to AMD in 2012 for a little over $357 million. We knew what we were good at, we knew what we weren't good at. We knew what we wanted to do. We wanted to do a— to solve a big hard problem and move an industry. We didn't want to be a little bit better. We didn't want to be twice as good as a GPU. We wanted to be 100 or 1,000 times faster. And to do that, we set out to be extraordinarily ambitious. And that was in the system design, that was in the chip design and architecture, that was at every stage of our thinking.
At the beginning, when you were first putting the designs on paper or whiteboarding it, Was it obvious that solving manufacturing for a large chip was the way to go, or did you have some more, I don't know, regular-sized chips and thinking more along the lines of the startups doing training of that era?
I think it's very hard to beat big powerful incumbents if you limit your thinking to their form factor. I think they buy silicon for less than you. They have their top 10 customers at the same fab you're going to. Yeah. So they, they get access to more aggressive nodes more quickly. Right. And so I don't think that the right approach is to be a little bit better. In fact, I think for startups, it is the most dangerous place to be. When you are a little bit better, your competitor, the large incumbent, can come at you with pricing action. They can come at you with bundling. They can come at you with all the tools that, that advantage large companies. When you come at them with something that is 50, 60 times larger, that is 100, 1,000 times faster, right? The range of response is much narrower for them. And I think that for startups, you want to do as aggressive engineering as you can in order to pursue the largest possible advantage. And I don't think 1.5, 2, or 3x is going to get the job done. In beating big powerful incumbents.
Tell me about your relationship with TSMC, because this technology is bound very, very closely with what the fab is able to provide. How are you able to convince them as a startup to devote resources to build something that really is quite a revolutionary process in terms of making a chip as large as a wafer?
Yeah, I think they get a huge amount of credit for recognizing that good ideas come from many places. And that to their sales team that knew us and for whom we had partnered with for, for decades in selling TSMC chips, right? This isn't the first time we've worked with TSMC. We've worked with TSMC for, for decades and for understanding the power of our idea and getting us in front of their senior leadership and their senior leadership immediately recognizing the power of our ideas. And those included how you could cross radical boundaries which hadn't been done, how we were going to solve the, the yield issue, how we were going to package a part. You know, when you're 50 or 60 times larger than any part previously made, there isn't an off-the-shelf package, right? There isn't an off-the-shelf cooling cold plate or off-the-shelf anything. And each of those we'd explain that we'd thought this through, and they listened, and they said, "These are guys that we want to do business with, and these are people who have ideas that are very powerful," and they began implementing our ideas. And it was really an extraordinary thing to partner with a big company and have them recognize that your ideas are powerful and could yield something that was very different than had ever been delivered before.
Now, you mentioned in, I think, your white paper that you have some patents and certainly some exclusive technology to make this happen at a fab level. How exclusive is the technology from TSMC's perspective? If a fabless semiconductor firm wants to work with them to build similar larger than reticle size chips, would they be able to do so?
We don't think so. I think like TSMC recognized, we have extraordinary ideas. I have great faith that there are other smart guys out there with good ideas too. I believe TSMC will be a good partner to them as they were a good partner to us. But the amount of invention that we brought to TSMC and TSMC recognized was ours, the amount of patents we have around that, TSMC brought a huge amount of their technology and they should profit from their technologies and their insights born of deployment of hundreds of billions of dollars in manufacturing equipment and fabs. And they're, in our view, among the best in the world at doing that. And so I don't think we're looking in the rearview mirror worrying that someone's gonna chase us. This took years and years of work, work not just with TSMC, but with a whole collection of vendors. And it involved us inventing materials and involved a vast number of acrobatics without a net. And we love this industry. We hope people continue to innovate. And we hope they try and push the boundaries and are not constrained by the reticle limit. I mean, our CTO had a wise saying. He said, you know, the right size for your chip is a function of your workload. It's not a function of the size of a reticle or something ASML invents, right? The right size for the chip is a function of the workload and characteristics of the relationship between I/O compute, it's completely unrelated to fab technology. And that's, that's really interesting observation and one we, we took very seriously in our thinking of what was the right size for, for an AI processor.
Now for the size you picked, ultimately it's basically the square portion of a wafer. Is the single WSE engine, is that large enough to fit the largest models today out there, whether it's a BERT or a GPT-2?
Yeah, I think in our conversations with the mega data center customers, with the leading researchers at the prominent universities around the world, with customers in all sectors, we can handle today the largest models. And that feels, that feels good. And we can accelerate them, we can run them with vastly lower power consumption, taking up vastly less space, and do so in a tiny fraction of the time it takes clusters of other equipment to do so.
One notable— when you compare kind of the NVIDIA Volta next to a WSE, you know, the specs are just 100, 1,000 times faster on your end, except for memory capacity, it seems. If you compare to the GPU's DRAM, which is not the apples-to-apples, but at least that's where they store their parameters, you know, Volta gets up to about 32 gigs, a single WSE is 18 gigabytes. Why did you pick 18 gigabytes as kind of the memory size when you can clearly choose to have more or less? If a Volta doesn't fit certain models today, why is it that they would fit inside of a chip from Cerebras?
Well, we use memory very differently than the GPU does. That's the first observation. Memory on chip is really the memory that matters. And you can have a lot of ice cream at Safeway, but when you're sitting on the couch, it doesn't matter what's at Safeway. What matters is what's in the fridge and what you can get to quickly at a commercial. And so putting large amounts of memory far away and forcing your cores to wait for it isn't very helpful in this type of work. This work— it is helpful in other types of work, and the design of the graphics processing unit is the perfect design for processing graphics. That's why they call it a graphics processing unit. But for this type of work, it has some very, very specific characteristics in the way memory is used. And in neural networks, the weights and the activations are local, and they have very little reuse, which means the compute elements doing one type of work need specific data, and other compute elements, other cores, don't want that data, don't need that data, need other data. And that's very different from graphics work. That's very different from traditional work for large core CPUs in the x86 world where you take a chunk of data in that world, hold it on your chip, and you let all your cores use it. It's called your cache. In this world, in the AI world, you want some of your cores, a fraction of them working with one bit of data. And you want other cores working with other data. And what that means is, is you can't bring big blocks of data from Safeway into, all right, your kitchen because everybody in a different room wants different things. And that's one of the observations that just about everybody who's looked at this problem has tried to get more memory on the chip. Rather than off the chip. And that's uniform in design for this work. And the graphics processors have done that too, by trying to make bigger chips. They've tried to increase the size of the memory on the chip. The memory off the chip, they don't make, they buy. I mean, that's just what your HBM providers can deliver. There is nothing special about that. So That's the first observation. The second observation is the ability to use memory is really a function of two things: the amount of memory you have and the memory bandwidth between your memory and your compute, right? The number of lanes and the speed at which things can move over those lanes. And just about everybody who's ever used GPUs for training complains about they run out of memory. And what they really mean is they run out of memory bandwidth as all these little tiny cores, you know, 1,000 or 2,000, are trying to get out off the chip onto memory at about the same time. That's like everybody trying to go to Safeway at halftime. At the Super Bowl, right? Suddenly on your cul-de-sac, there's a bottleneck. On the on-ramp onto Safeway, there's a bottleneck. At the cash register at Safeway, everyone's trying to get that ice cream so they can get it back and get into their fridge. And that's been a punishing limitation of the traditional graphics processor.
I hear about memory complaints, memory bandwidth complaints for sure, but I also hear that the models are so large now that they don't even fit in the HBM memory even at 16 or 32 gigabytes. Is that size— if a model doesn't fit in a GPU's HBM, is it smaller when it's laid out in kind of the Cerebras way relative to your 18 gigabytes?
It is. It's smaller in that we hold different things in memory than they do. One can imagine a model that has more parameters than we can hold, right? One can posit one. But remember, our memory is doing different things. Our memory is basically holding parameters. That's not what their memory is doing. Their memory is holding the shape of the model. Their memory is holding the results of the batches. We use memory rather differently. And so we haven't found models that we can't place and train on a chip. We expect them to emerge, and that's why we support clustering of, of chips and systems. That's why we do it in what's called a a model parallel way where if you put two chips together, you, you get twice the memory capacity. That's not actually what you get when you put multiple GPUs together. When you put multiple GPUs together, you get two versions of the same amount of memory. You actually don't get twice the memory. And I see you smiling here because you, you know, that's the problem of the way they try and solve the architectural challenge. It's called data parallel. They want to run twice the analysis sort of once on each of the two chips. Whereas with us, if we support 4 billion parameters and you add a second wafer-scale engine, now you support 8 billion parameters. And if you add a third, you support 12 billion. That's not the way it works with GPUs. With GPUs, you just support two chips, each with, I don't know, a few million, Tens of millions of parameters.
I think this is a great time to talk about the system architecture for Cerebras. This is something that I've gotten a lot of questions on. You've described the chip in a lot of detail. How does— could you walk us through, in— I don't know what level you're willing to at this point, but how that chip is, I guess, interfaced to some PCB and how that builds out to a server or a rack? What is the, I guess, system architecture, and what is the unit that your customers in the end will be buying?
Sure. I'm sure one of the reasons you've received a lot of questions is because we haven't announced the unit, but we are a system company. We'll be selling a full server, right? A complete system with I/O and power supplies and a metal enclosure, and it will look like a big fast server. I will say the following. I think there were really 5 problems to be solved. In delivering the largest chip ever. The first was cross-die connectivity, and the second was yield. And those two problems had broken every previous effort. And it's a little bit like when the first guys got halfway up Everest and they stopped and came back and they told everybody it's really hard. And then the guys got all the way to the top and they turned around and said, you know, that first half, that's not the hard part. And the problems we encountered and the engineering problems to be solved, cross-die connectivity and yield, we solved very quickly. There was thermal expansion, which is the fact that as you heat up your wafer and the printed circuit board that it's attached to, those two things expand at very different rates. And if you build a big chip, and you've got a big, big motherboard and you try and connect the two— connecting two things that expand at different rates under, under heat is a very challenging problem. And we had to do a great deal of invention there. The next item was packaging and assembly right there. There wasn't a package. You couldn't go to Amcor or you couldn't go to a packaging house and say, give me a package, or Kyocera and say, give me a ceramic package. Nobody had ever made a package this large. And doing physical design work, doing packaging design work, is something that is sort of a lost art. There are not so many people who know, who have those skills anymore, certainly not here. Um, a lot of them are in Taiwan, parked right next to TSMC. And so we had to think about the packaging, and it, it took us— we didn't just have to think about the packaging, but there were no machines that could handle a chip this large. We had to invent machinery. We had to invent processes and tools and process software that allowed machines that we designed to handle a chip that was 60 times larger than any chip that any machine had previously handled. And so that was a huge amount of effort. The final piece was power and cooling. It's not enough to build very large chips, but you also have to power and cool them. And our chip consumes a lot of power, but per unit compute, it is vastly more efficient, 10, 15, 20x times more efficient than alternative approaches to artificial intelligence work. And that's one of the reasons why we saw opportunity here, was that not only could we deliver vast amounts of compute, we could do it much faster, but we could do it using less power and less space, driving down operating costs. As you can see, if you're gonna build, make inventions at the chip level, make inventions at the physical design to produce yield, if you're going to package your part If you're gonna design tools to assemble parts and design power and cooling, right, you're building the whole Ferrari. You're not dropping, you're not just doing a chip and dropping it in somebody else's Volkswagen.
Is it safe to assume that the overall server appears pretty recognizable to an existing researcher working on standard GPU gear?
Oh, absolutely. Absolutely. The idea was to keep the magic under the hood, You program us with TensorFlow or PyTorch, or in Japan it'll be Chainer or any number of these of the standard Python-based machine learning frameworks. And so we take the researcher's model unchanged and we ingest it and do work on it and send back trained parameters.
This is a, I guess, an x86 server in the end?
No, we have no x86 parts in our machine. Huh.
Okay. Is it possible to talk about what is the CPU or what is the rest of the system look like?
I think we should do that down the road after we've announced it. I'm happy to come back and share with you and your audience in painful detail choices we made up and down the stack. I'm sure I can bore them to tears with decisions and rationale for the approach. But I think right now, what we announced is— we thought that was enough, that we solved the problem that for the 70-year history of our industry, nobody had solved.
I see. One, I guess, when you talk about so much on-chip I/O capability, that's all great once you have all the data on chip. Is it a bottleneck though at this point to bring the data onto the chip given just how large and high capacity this chip is? Was that a major challenge? I mean, I found it interesting that was not one of your 5 problems that you had to address.
I think the first problem in architecture is what not to build, right? Which workload to ignore and not worry about, because that helps you think very clearly about how focused you're going to be on this workload. We don't also do graphics. We don't also do 64-bit double precision supercompute work. And when you bring a part that does other things to a very special market, you bring with you a tax, silicon area that's taken up for things that this market doesn't need. And so we thought very hard about building a specialist. The second question is, once you're a specialist in the range of use cases, what is the right ratio of I/O to compute? And there are small neural networks and there are large neural networks. There are some neural networks that like very large inputs. There are others that like very small inputs, but lots of them. And thinking very carefully about how you can solve for the widest collection of those led us to a balance. We bring in, uh, onto the chip 1.2 terabits per second of data. And yeah, that's a lot. You know, one could imagine order a million images a second, plus or minus. And we, we felt that would give us tremendous range and enable us to, to not throttle the amount of compute we had because we couldn't feed it with data. But that's a hard— it's a hard question in architecture. How much I/O is the right amount for the amount of compute you have is not an easy question.
Now, you've been testing the chip for a while now internally. What is the, I guess, constraint? Now, there's, when a chip comes back, you run the benchmarks, there's always— it's either constrained by bandwidth or cores or heat. What is the constraint now for the Cerebras architecture as it stands?
Well, I think we are soon to be delivering to customers. I think we feel like we're in very good shape there. I think by way of constraints, I think with a new product, there are always rough edges and burrs. You want to get your user experience polished, but you've only had a dozen or so customers on it, and most of the hours it's been used have been your engineers. And so early shipments of software and hardware have some rough edges and you get it in customers' hands and you get thousands of hours of use across multiple customers and you listen carefully and you improve. That's the cycle we're in right now, is filing off the rough edges, making it easier to use. Those are things that this last phase before, before customer delivery is really well suited for.
Okay. I spoke to the good people at NVIDIA recently and asked them about the wave of AI chip startups competing against them. And their position was that other than Google, who started fairly early with TPU and on their third iteration now, NVIDIA basically started in earnest with Volta, and they've plowed so many billions of dollars of R&D into this across hardware and software that it's basically the train's left the station in kind of their view that chip startups—
Yeah, what would you say if you were them?
I mean, that's what I would say, I guess. I, of course, best—
That's right. I mean, it's convenient. It's convenient that that's what you'd say. Here's some things they're not going to say. Say anymore. Right? If you go back and you listen very carefully, for years, chip companies have been broadcasting the number of transistors and the size of their chip. They're not going to talk to you about that. Why is that? Because now they've got a small chip. I think their marketing spin, that's their business. You know, we don't have much to say about that. Our job is to go out and take customers. Our job is to demonstrate to the community that we are training faster with less power, taking less space. You know, if you're trying to build a large cluster of GPUs, it will take you months to deploy. Months. You deploy us in 10 minutes. Rack us, plug us into 100 gig Ethernet switch, go. I'm very comfortable that It's not words in this market that will matter in the end. It's can you build it? Do your customers like it?
I am interested in kind of the question of is it possible with—
you know, just one more note. I mean, these guys also for a while were saying that ASICs were unflexible, and for those of us in the industry, we found that comic. The GPU is so inflexible it requires two Intel processors to run. I mean, that's laughable, right? That's the definition of inflexible— when your part can't run on its own and requires your largest competitor's parts to do its heavy lifting to boot. So I think you should ignore marketing spend. You should listen to customers. I think that's the best way.
I guess just to me is one thing—
I see you're smiling. I mean, that thought has crossed your mind too, right? It's like, holy cow.
I mean, I worked there for 9 years before joining ARK. So I'd said they're certainly very apt at marketing and then I was, well, part of that effort. But I'm very interested in just the truth of things, which is there are two kind of general lines of dialogue out there. One is that it's extremely capital intensive. To start a semiconductor firm, even a fabless one.
That is true.
And two is just this empirical observation. I track the AI startups and the table is getting so long I can't fit it on a single screenshot. And you've received over $100 million of funding. Graphcore has received $200 million of funding. And Horizon Robotics has received, I think, hundreds of millions of dollars, maybe a billion dollars of funding. It's kind of crazy. So is it— I mean, which one is it? Is it that a small With no— these sums of money, it's not even plausible to build something that can beat a Volta? Well, or is it the other way around?
Oh, of course it is. No, no, no, of course it is. I think when we look at startup guys, what large companies spend and brag about spending on building a chip, I mean, it takes your breath away. I mean, they were immolating investor capital, right? I mean, big companies spend billions of dollars to make chips. We spend tens of millions of dollars to make chips. Why is that? Well, we have about 30 layers less of management. We do not depend on breaking the problem up into tiny little pieces that you then assign to lots of people requiring constant interfaces, right? I mean, you're nodding because this is exactly what you saw when you worked there.
Sure.
How big companies do it. And we rely on small numbers of extraordinary people.
[Speaker:TREVOR_BURRUS] And you don't have to research graphics problems and HPC problems?
[Speaker:ANDREW_FELDMAN] That's exactly right. We're not trying to solve a graphics problem also. We're not trying to solve an HPC problem also. We're trying to build the perfect AI processor. And we are free to be bold and innovative. We are afraid of mediocrity. We're not afraid of being bold. And I think the academic community who studies companies keeps asking, you know, Shouldn't Intel have been able to build a cell phone processor?
Sure.
Shouldn't Nvidia have been able to build an ARM processor for gaming? What can we learn about the inabilities that we saw there? Weren't they well positioned? Didn't they have world-class computer architects and didn't they have fabs? Empirically, big ideas seem to come from startups.
That's certainly true.
Big, bold efforts come from startups. Incremental improvement year after year, small improvements, those come from big companies. That's been the experience in the Valley. I mean, I don't think— I think, James, you'd agree with me, right? That's what we see.
I agree, except for maybe semiconductors where it's a little less obvious. In software, you can go from nothing to Snapchat very quickly.
Why couldn't Intel build a— I mean, it's not just Intel couldn't build a an ARM core or even a super lightweight x86 for the cell phone part, why couldn't they build a graphics part? I mean, NVIDIA beat them on the motherboard and that's their home turf.
Yeah, yeah. I think NVIDIA is probably the last truly great—
I agree.
Semi startup, right? Because yes.
And they're a great company. I mean, I don't want for a minute— I mean, they're my competitor. I mean, nobody else has beaten Intel on the motherboard like they did. And that's an extraordinary thing.
It is.
Extraordinary. And they get huge credit for that and they get huge credit for making hay while the sun shined in AI. And they did and they saw it coming and they marketed the living daylights out of it and they brought a part that was repurposed and moved the industry forward. I think they get huge credit.
Andrew, do you have a hard cutoff at the hour, or can we go a bit over?
I don't. I can keep going.
Okay, awesome. Um, one thing that I saw both you guys mention, and I saw this kind of first mentioned from Yann LeCun, director of AI research at Facebook, is that hardware informs software. And all the neural networks that we have and love today that seem so exotic are really, uh, kind of created within the invisible constraints of, of the GPU architecture.
Look, Yann LeCun understands this better than most, and perhaps better than almost everyone else except a handful. But our view is exactly that. It's that the universe of algorithms that learn is very large. The subset of that universe that works well on GPUs is very small. And that's the only part we've been able to study. Between what Yann LeCun said and what Geoff Hinton said when he said, "Look, if it takes longer than a month to train, don't even bother doing the work. It takes too long. You can't test your ideas. Don't do the work." Well, that means there's this huge body of work that's not being done containing all sorts of interesting findings that we can't do because it just takes too long to train. And we ought not to bend our research, our pursuit of insight, around these learning algorithms to a particular computer architecture. We should, quite honestly, do the opposite— build computer architectures that allow these researchers to explore all sorts of ideas. Extremely sparse networks, very wide shallow networks, whatever network they can, extremely deep networks, whatever ideas they have, we ought to build hardware that allows them to explore those. Can you give some And that's, I think, well, that's, I think, when you get these big jumps forward. I think to date, we've made good progress, but a lot of it's been in making fast the models of Hinton and LeCun and Bengio and this collection of sort of the fathers of the field that their work in the '80s and '90s pioneered, but with new hardware, the GPU, with the wafer-scale engine, with huge clusters of those, you're going to see new models that do new things, that do exactly what, what LeCun said, which is allow us to explore more of this universe of learning algorithms unconstrained by the GPU.
What are some examples of things that the Cerebras chip is able to do that I guess is more programmable, more flexible, that would be basically going through gymnastics on a GPU?
Oh, extremely sparse networks. Networks that are extremely sparse. So a GPU is what's called a dense matrix machine. It's designed to multiply matrices together. And it's designed so that every cell in the matrix has a non-zero number in it. Why? Because in graphics, there's never a zero value. Now, in artificial intelligence, we have a lot of zero values. And if you blindly multiply two matrices together, and they both have a lot of zeros in them, you're doing a lot of multiply by zero. And that's an utter waste of time and power, because no new information is made. Our system and our cores are designed for sparse linear algebra. That's the fundamental building block of artificial intelligence. And we never multiply by zero. We never propagate a zero across the fabric. And so if you imagine multiply by zero like running in place, if your matrix has 80% zeros, 80% of your steps towards your goal are done in place with no forward progress, right? That's not good. We never do that. Every single multiply, every single step forward, every step we take, every centijoule, every picajoule, every unit of energy we consume is producing forward motion towards the finish line. That's just one example.
Right. And I guess apples to apples, if researchers wanted to do the sparse style on a GPU, they would have a lot of wasted computations.
Huge amount.
And the end effective model size would be quite small. And Really, the effective model size on doing the same thing on your chip would be much larger.
Exactly right.
What about connections between different layers? Right now, the connections are kind of uniform. I think some researchers wanted to have arbitrary connections between different layers. Is that something that would be supported?
Well, I think absolutely. I think the GPU, I mean, a great example of what LeCun was talking about, of the the computer architecture driving the model and the techniques rather than the other way around is mini-batches. Mini-batches exist because at batch size 1, the graphics processing unit runs at roughly 0% utilization.
132 MHz.
And right, exactly. And so by having it work on the same data, what's called data parallel, giving it the same data and then averaging, this technique emerged, but there's not a lot of theory that says this is the right technique. And what if you want your arbitrary layers to interact? Well, if you're doing them sequentially, if layer 1 is all done, like in a the graphics processing unit, and then save to memory, and then Layer 2, and save to memory, and Layer 3. What if you want Layer 1 to communicate with Layer 4? The complexity of that is enormous. That's not our approach. We use a spatial data flow technique. So if you want more communication between Layers 1 and Layers 4, that's something our compile stack understands. And what it does, the placement, it will allocate more resources, more bandwidth, or low latency links between layer 1, layer 4. And for us, every model, when it moves to our compiler stack, it gets a unique layout on our chip optimized for that exact network. That's flexibility, right? You get a different configuration of the fabric for WaveNet as you do for BERT, as you do for ResNet-50, as you do for Seq2Seq, whereas GPUs and CPUs on the chip, they're hard-coded. There's only one approach regardless of the shape of the network.
So the chip almost—
That strikes us as unlikely. That strikes us as unlikely is that you've got the one perfect perfect architecture for all chips. That's why we are an array that is programmable.
It almost sounds like it takes on characteristics of FPGAs.
FPGAs have some very attractive characteristics.
They have some hard problems, but ours is an extraordinarily flexible approach, and we thought that the right way in a field that's still so early in its development I guess when I think about it, the FPGA is designed to be programmable down to a very fine grain, and you have basically an ASIC approach, but your size is so granular that at almost like a medium scale, you can basically program the data flow like an FPGA.
You are exactly right, and that's a very thoughtful comment. The class of computer architecture we're in is called coarse-grained data flow machine. And it's a spatial coarse-grained data flow. That's exactly right. We are able to, because we have 400,000 cores and our compile stack controls the communication path across this landscape of compute, we can build the perfect placement for your specific network. and that was very much by design. I mean, these things are called networks for a reason because that's the interesting part about them, right? The calculation, the multiply and accumulate isn't the interesting part. The interesting part is which part communicates with whom and how often. By way of architecture, that was the very hard problem to solve and from where you get a huge amount of performance gain. Is improving the communication.
I'd love to close off with just a discussion on the business side and the market for AI silicon right now. When you started Cerebras, I'm sure you had a market size in mind for how big the AI training market is for a new entrant and for everyone else. And over the course of the next 4 or 5 years, the market has grown tremendously, and we've seen it through NVIDIA's data center revenue segment. It seems to have taken pause this year. How do you think— I guess, what were your initial and current thoughts on the size of AI training market, and what do you think will be your go-to-market strategy? There is a huge debate right now among kind of equipment maker kind of companies whether, you know, there's a market in the enterprise or the market is in the cloud. And if it's in the cloud, we're starting to see some of this insourcing of silicon from hyperscale vendors, similar to consumer, just kind of how Apple kicked out Samsung, now we're seeing Google kick out GPUs to some extent from their data centers. So how do you think about those dynamics?
I think this is an enormously complicated market. I think there are a large number of customers worldwide who have huge data assets and do not want to put them in a public cloud. That's number one.
And why is that?
Well, for any number of reasons. The cloud is not cheap. The cloud isn't designed for you to move quickly and easily across clouds, right? Google and Amazon, I mean, their goal is to create stickiness in their clouds. Yeah. And that's the cloud business. I mean, and they are sort of the best in the world at doing that. And, you know, if you go Amazon, Microsoft, Google, they are at running enormous data centers. I mean, they're among the best in the world. Now, they charge you a fair bit for using that service.
Sure.
And I think, you know, when we look out at the market and in our discussions with hundreds of customers over the past several years, the guys we're talking to aren't falling over themselves to jump on the cloud. Now the cloud is going to do a huge business in AI, making— enabling you to buy by the SIP in training and inference. But we see a vast demand. I wouldn't call them traditional enterprises, but I'd call them a select group of enterprises that have vast data resources and real expertise. In, in infrastructure. Number 2, I think inside these massive companies, these data center companies, uh, there are several different constituencies. In our experience, there's an internal demand for AI compute for their researchers, for their applications, and for things that they want to sell as an inference service, And that is a very different market than their cloud business, where they're looking to build multi-tenant infrastructure that allows customers to buy in small pieces and grow as they, as they need to. We have seen tremendous demand in government. We've seen tremendous demand in the auto industry. We've seen companies who don't like to share data, their own data, across different geographies, let alone with third parties. There are demand in oil and gas and pharma. We've seen a huge amount of demand. I don't always know how, how to do the big macro market size that the analysts do that produce large numbers, but I can compare this with This is bigger than the switching market by far. I think this is tens of billions of dollars will go into this category.
Just for training alone?
Oh yeah, for data center training. Among your customers? The other thing we've had some people ask us a question like, well, won't people train their model and then be done? And that's not a— no. They won't, because their competitor will train the model and keep training and continue to eke out gains in accuracy and keep improving and modifying and beat you. That's the truth, that what we find is people who train models and who use the results of that training to generate revenue, they are passionately focused on improving those models and they improve it with constant innovation and with more data. They want to keep training and training and training.
How many companies do you think fall under that style of business model today? It seems like it's mostly the really competent internet companies out of Silicon Valley. I don't really, I guess, see most of the economy operating that way.
I'm not sure. I think we've got data that points in two directions. And here's what I think we need to be wary of. The publication space is cluttered with internet data centers. People are always talking about what Google and what Facebook and what Amazon and what the first-rate cloud at Microsoft Azure and what's being done at Tencent and Baidu and Alibaba. They contain vast amounts of mindshare and they're hurling themselves at publications. They're putting hundreds and sometimes thousands of people trying to publish AI. There are all sorts of other industries that are using AI that aren't publishing like crazy and are staying out of the press and are doing just fine and are using artificial intelligence to solve real problems in their work, but haven't made marketing that progress a priority. And so it's really important when my newsfeed every day tells me yet another thing that Google has done with AI to remember that the guys in pharma have been using machine learning for a very long time. The guys in oil and gas who are vastly larger than the entire segment that is advertising. One of the senior guys at And one of the oil and gas companies said, "Yeah, we look at Google and we look at the advertising market." That's the market they play in and say, "They're a few percent of the economy and we're 13% of the economy." And so it's easy to get fooled because in the Bay Area, we don't talk about oil and gas, but maybe in Houston they do. And similarly, we don't talk a lot about pharma. They do in Basel, Switzerland, right? They do in those locations where they're hubs for those technologies. And so I think it's really important that we not get confused with the amount of marketing being done by some of these large internet companies, not discounting their tremendous work, their focus, but also that they're not alone in the pursuit of meaningful applications of artificial intelligence.
Do you think these vertical, these very powerful and, and, uh, vertical industries that require a lot of compute, are they— do you think going forward they will continue to build out their own on-premise infrastructure, or, or also will they kind of get sucked up into the cloud?
They'll do both. All right. One of the, one of the problems with the cloud for this type of problem is moving this amount of data is punishingly expensive. And the cloud's pricing models have frequently been designed to get your data in their data centers and make it very expensive to move it away. And these are huge datasets, hundreds of millions of images, thousands of years of video. And so I think there's a real strategic decision that these large companies have about what's it cost if they put their data there to move it. We use the cloud for many things at our company. We're not anti-cloud at all. We very much hope to sell thousands of systems into cloud vendors. But I think it's too easy to say, oh, that's the only market. That's not been our experience.
That's good feedback. Okay, I guess to wrap up, Andrew, I think you've made a few announcements in terms of what to see, what the public will expect to see next from Cerebras. Just tell us a little bit about that. I think you'll be at Supercomputing.
We look forward to talking about substantial progress in third week of November. I think that's the week that the Supercompute Show kicks off. I think that's a good forum. It's become a forum not just for high-performance compute or for supercompute, but for big fast compute in general. And those of us building big infrastructure, we have no place at CES, right? You know, nestled among the wearables or the eatables or the machines that make bread or whatever. A show like SuperCompute is a super show for those of us passionate about big fast compute.
A year from now, could we expect to see your name on some of the MLPerf leaderboards?
Oh yeah, I think that obviously would be great. I'd much rather have taken some of the largest customers from my competitors. I think we forget that the reason you have benchmarks is so you're your customers can compare. The other way they can compare is on their actual workloads. So we, we very much hope to be a part of the community and participate there. At the same time, we're allocating resources to solving real customer problems in their infrastructure and selling them gear.
Okay, awesome. Andrew Feldman, it has been such a pleasure talking with you today. I wish—
I want to thank you for your blog post. I think there were a lot of posts and follow-up after our announcements, but the only one I wish I'd have written was yours, as an absolutely thorough understanding of the choices we made and why we made them. And so that's really nice to see.
I super appreciate that. I look forward to following your news at Supercomputer this year.
That would be great fun. Thank you so much for organizing this.
Thank you, Andrew.
Bye-bye.
That's it for this week. You can find the full ARK team on Twitter. We'll catch you next week.
ARK believes that the information presented is accurate and was obtained from sources that ARK believes to be reliable. However, ARK does not guarantee the accuracy or completeness of any information, and such information may be subject to change without notice from ARK. Historical results are not indications of future results. Certain of the Some of the statements contained in this podcast may be statements of future expectations and other forward-looking statements that are based on ARK's current views and assumptions and involve known and unknown risks and uncertainties that could cause actual results, performance, or events to differ materially from those expressed or implied in such statements.
More from Andrew
How Cerebras is Democratizing AI at Scale with Andrew Feldman, CEO of Cerebras
Cerebras CEO, Andrew Feldman on Why Raise $1BN and Delay the IPO & Why NVIDIA’s Worried About Growth
⚡️Raising $1.1b to build the fastest LLM Chips on Earth — Andrew Feldman, Cerebras
Andrew Feldman, Cerebras Systems | theCUBE + NYSE Wired: AI Factories - Data Centers of the Future
Andrew Feldman | How Cerebras Built the "Impossible" AI Chip Now Challenging NVIDIA