Jon Krohn Live on Shally's Alley
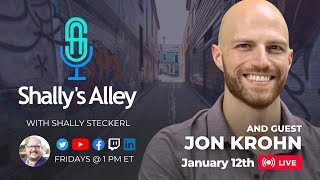
In this live interview, Shally Steckerl welcomes Dr. Jon Krohn, co‑founder and chief data scientist of Nebula and author of Deep Learning Illustrated. The conversation covers a wide range of topics: the fundamentals of deep learning and neural networks, the historical roots of artificial neurons, the role of GPUs in scaling models, and how modern word‑embedding vectors enable sophisticated talent matching beyond traditional keyword search. They compare Shally’s manual word‑cloud approach to Nebula’s vector‑based system, explaining how stop‑word removal, attention mechanisms, and large language models (LLMs) improve resume search. The discussion then shifts to the nature of current generative AI—its strength as next‑word prediction rather than true reasoning—and introduces the emerging Q algorithm as a possible step toward step‑by‑step reasoning. They outline AI capability levels (emerging AGI, narrow superhuman AI, etc.), discuss the limits of scaling (hardware, data‑center economics, GPU allocation), and speculate on future breakthroughs and the timeline for the singularity. The episode ends with thought‑provoking questions about life after work and suggestions for future guests.
Chapters
Hey, all right, all right, all right, what is up, people? I am coming at you live on Shelly's Alley. It is Friday, January 12th, at roughly 1 PM US Eastern Standard Time, or GMT minus 5 for those of you that are world citizens. And it is our second episode of 2024. Can you believe that? Already second episode of 2024. And man, I am so glad 2023 is over, uh, and in the rearview mirror, man. That was just—
I, I heard that from you opening up your preceding episode.
Oh, every Every single anything that was in any kind predictive was wrong about last year. All predictions were wrong. All models were wrong. All estimates— I had my crystal ball and I made a couple of predictions that did come true at the end of the year towards this year, but that was really predictions about this year. All my predictions about last year were wrong. I mean, everybody was wrong, but it was just the weirdest I don't even know what to say about it. So I'm totally glad that it's over and we, uh, we're starting a new year. Uh, man, it was a very eventful year too. Lots of stuff going on. So anyway, folks, you are in the presence of royalty today. I have the very spe— no, there's got to be another way to say— I have the extra special honor of, um, bringing you as a guest today Dr. That's right, Dr. Jon Krohn. Dr. Jon Krohn is, believe it or not, a real, you know, PhD doctor. He is the chief data scientist for a company you probably have never heard of called Nebula. And it is— their website is nebula.io, nebula.io, for those of you that are interested. I'm going to put that up on the screen here. And what is Nebula? Well, it's, um, it's software in our industry, but we're not here to plug Nebula right now. We'll talk a little bit about that. The key thing is that Dr. Krohn also is the author of a best-selling book on deep learning. Deep Learning Illustrated is the title of it. So Deep Learning Illustrated, because it's basically, um, A comic book on deep learning, right?
I actually— there's a couple of Amazon reviews that are scathing.
No way!
Because it isn't that. It does have this over 200 illustrations in the book.
And it's not a comic book.
Yeah, it's not a comic book. I was being ironic.
Yeah, yeah. But so it's a book about deep learning. You check it out on Amazon. No, I don't make any money. I don't have any stock in Amazon. So go ahead and buy it. He also is the host of the Super Data Science Podcast. So he's a fellow podcaster. What do you talk about on the show, on the podcast?
So we're the most listened to podcast in the data science industry. And so we talk about machine learning, we talk about AI, and we talk about other stories that a data science practitioner like a data scientist or a machine learning engineer might need to know. Data visualization, data storytelling. But of course, because of all the developments in machine learning and AI, it ends up being very ML and AI heavy. We do also have non-technical listeners on the show. So if you're out there listening and you're not a hands-on practitioner like a data scientist or an ML engineer, there are still many episodes of the show that you would enjoy. So at the beginning of every episode, I say who the kind of the target audience is for this episode. Some of them I say, hey, you know, this is going to be a really technical deep dive into this one programming language or something. And so maybe, you know, if you're not a hands-on practitioner, this isn't one for you. But lots of the episodes, I start off by saying, you know, this is going to be great for anyone who wants to stay up, uh, on the latest in this particular sector or this particular kind of technology, how machine learning is being applied there, that kind of thing.
Oh wow. All right, folks, if you have a, um, uh, an inclination to listen to advanced stuff on data science, it is literally just Google Super Data Science, one word. Super Data Science. Say it really fast. Super Data Science. Super Data Science. So, all right, now what are you doing here? So this is what happened, guys. I was— I got an email from some random sales guy. And one of my functions, one of my jobs, both at work and also in my off hours, is to constantly investigate and experiment with new technology in our industry, or just simply new technology that might have an effect on our industry. Like, for example, recently I've been toying a lot with Vortimo. Hint, hint, wink, wink, that's coming up in another episode. And, you know, so I'm constantly discovering, and so I'm usually kind with salespeople. Sounds interesting, sure, you know, tell me more. And I and I tend to take the first meeting and, you know, I start out by saying, hey, listen, I do a lot of these, I see a lot of these, let's just kind of not do the long-winded one, let's just kind of go in and jump in and I'll ask questions. And if they respond to that, great. If not, then, you know, it kind of ends there, right? And every once in a while, I do get sales pitches that are just really just bland. But anyways, the point is that total cold outreach. So folks, cold outreach does work. And I was like, Sounds interesting. I, I'm like, I pushed back a little bit because they were saying— I don't know if you remember this because this is like before you and I met— they were saying something like, um, you know, we're, we're the, the machine learning, um, mixture between, you know, we can help you identify profiles that you've never, that you'd never think of finding. And I'm like, right, I'm like, really? Yeah, okay, wink wink. But sure, let's do it. And so I set up a call, I went through the demo and I'm like, holy crap, this is actually pretty cool. And I'd never seen anything like that before. And so they gave me a demo account and I went in there and I used it for a little while, kicked the tires, and then I gave them some feedback. And so they threw John at me. They said, wow, this is interesting feedback. Would you mind getting on a call with our, you're the founder?
I'm a co-founder of the company and I'm the chief data scientist.
The co-founder. Okay. So yeah, they were like, they were like, do you want to sit with a guy? And I'm like, oh sure, okay. And then they're like, he's the data scientist. And the reason they wanted to bring you on board is because during the demo I was talking like a data scientist.
That's right.
And they're like, you need to talk to John because he speaks your language.
I was blown away when I met you because you were on exactly the same page with I was able to get very quickly into some of the details. So the thing that distinguishes Nebula from the incumbent platforms out there is that the incumbent platforms are driven by a keyword-based search. They're matching strings. Sometimes you'll know this, Shelley. Shelley knows this very well, that some of these keyword-based searching platforms, they're very sophisticated about it. So they might map things like they might programmatically say, you know, if somebody has, if, if somebody's looking for someone with a computer engineering background, they have this very specific mapping of that also to computer science or something. So these, so some of these keyword searches, searching platforms, which basically all the incumbent platforms use, they can be more than just matching that exact character, but it is still highly restrictive. And you have humans creating those mappings. It's laborious, it's clunky. And it doesn't work like you think it should.
And it doesn't adapt very quickly because you have to constantly update the dictionary. So I was on there poking holes at the product saying, are you guys using an ontology, or do you have, you know, is it a logic tree? Are you using, um, you know, a dictionary? And or stuff like that. And then that's where, like, you can talk to John. And so when I started, I got on the call with John and I started asking the same questions, John was like, oh, oh, it's gonna be like that, okay. Um, then, you know, you were like, now that you're asking those kinds of questions, let me tell you what's really going on. And that's when I got blown away. I was like, at first it was the sales pitch of like the, oh look, the magic. And then I tried it for myself and I saw, and I saw the magic. And then I'm like, okay, this is definitely something different. So, um, I was so impressed with, with with what is happening behind the scenes that, um, I begged and pleaded for a seat in the board of directors, which they still haven't given me. We're still—
we're just stuck in the paperwork.
Yeah, right, stuck in the paperwork. And I wanted to bring him on the show to talk about some of the things, some of the things that we talked about, not specifically about the product. I— look, I, I highly— I endorse the product. Check out nebula.io. I wish I was a shareholder. I wish I could afford to use it right now. It's one of those things like it's timing. We had already bought something else, but I always like to keep my eye on the product. Definitely endorse it. Here's the thing though. I wanted to talk about the myths about generative AI, what's possible and what's not, what's here, what's near, and what's coming because I'm, when ChatGPT blew up and became a thing, a lot of people just started using it without realizing the danger of it, the risk and the danger. And people just kind of got enamored with it. And it wasn't until very recently that the, the foibles and the failures of it started becoming evident. And it's exactly that that I was objecting to with Nebula, and you had answers about that that were very down to earth. And of course, you wrote the Deep Learning Illustrated, Deep Learning for Dummies, so it makes sense. So I want you to, if you can kind of re-summarize in a layman's terms, what is really happening right now and why it's really not AI as we think of it?
Well, so AI is—
It's not an artificial intelligence, basically, right? Is what we talked about. It's not like a— what was it that you called it? Something specific. You said like an independent thinker or like it doesn't think for itself or—
Yeah, so it's fundamentally—
General intelligence, I think is what you called it.
So the, the AI systems that we have today are amazing pattern recognition tools, right?
So learners, they're deep learners.
Yeah. And this idea of deep learning. So we've had, since the 1950s, there have been researchers specifically, there's a researcher at Cornell in the 1950s who was funded by the US Navy. And there were New York Times articles at the time in the '50s. Saying this Cornell researcher funded by the Navy, he's coming up with a machine that's replicating human intelligence. So in a few years, we're gonna have machines that can do everything a human can do. That was in the 1950s. And what that guy was doing was he was taking our early understanding of the way that brain cells work, and he was writing a computer program that loosely mimics the way that a brain cell works. So brain cell, you can call it a neuron. So this guy was inventing this algorithm, this computer model of a biological neuron called an artificial neuron. And these are very flexible. So you can link artificial neurons together into a network so that information flows from one into others. And so in that way, it's like your brain, your nervous system.
It's like a biological neural network where people Just interjecting, people now, that's the neural network, is that one of the beginning foundations of it? Anyways, just explaining.
No, exactly. Yeah. So when people talk about neural networks, this is something that's been around since the '50s, but it's become powerful in the last decade because finally we've gotten to a point where data collection, data storage, compute cost, all of these things have now become affordable. And so it turns out that this neural network theory, which has been around for over 70 years, it hasn't changed very much in terms of the theory. What we were missing was scale. So now the reason why NVIDIA's share price is so astronomical is because they're the kings right now of being able to offer affordable scaling of neural network computation.
The GPU.
The GPU, um, graphic processing unit. So originally NVIDIA and these GPUs, they were intended for rendering 3D graphics on a computer screen, particularly in video games.
Visualization, that's right.
Visualization, video editing. So GPUs are—
But then they were like, hey, there's all these unused cycles, let's use it for something else. Yeah, they're now— GPUs process a lot more than just the graphics rendering.
Well, it's, it just depends on the application. So if you are playing like a, a high-end video game, you could be using all of your NVIDIA GPU for that video game. But then you can use that same— so what these GPUs do is they have thousands of parallel processing on very simple, um, multiplication operations basically. And that ends up— so it's in the same way when you're trying to like imagine you're playing like a first-person shooter video game, you're walking down a corridor and you turn a little bit, there's a lot of parallel— you need thousands of parallel simple computations to figure out how should the screen render so that the hallway moves slightly depending on how you're moving the joystick in the video game? So that same kind of calculation ends up being these neural networks that we've had around since the '50s. It's simple math. And so we can send that to the GPU and be doing thousands of these simple math operations. So we can be supporting calculations at thousands of these artificial neurons in parallel, which allows the modern deep learning systems, deep learning just being a synonym for deep neural network, to run efficiently. And just really quickly, this idea of deep learning or deep neural network, all that it is, is you're stacking a bunch of these artificial neurons on top of each other. And so to give you an example that's relatively easy to understand, to visualize, and that we do a lot in my book Deep Learning Illustrated, is that if you're thinking about You know, look, you can look around the room right now and your visual system is processing all the things that are around the room around you. The way that your visual system works, the raw light information, the photons of light hit your eyes, and then it's transported to the back of your brain. And the first layer of brain cells that process that information, it can only— they can only look for straight lines. Artificial neural networks, the exact same thing. They're only looking for straight lines.
It's the fastest thing that they can do first, fastest, easiest thing.
And then the second layer of processing, whether we're talking about your visual system in your brain, or we're talking about an artificial neural network, the second layer takes those straight lines and can combine them into corners and curves. And then the third layer can take those corners and curves and turn them into more complex, more abstract shapes until several layers of artificial neurons in, Right, you can represent Shelly's face or my face or your grandmother's face or whatever with your brain or like peeling back the layers of an onion.
And it's kind of the same thing as, as we do, we just aren't really aware of it. And it's what makes it possible. For example, I, I was reading about this, um, where when you're playing, uh, um, catch, for example, where we have the ability to put our hand where the ball is going to be. If we had to, if we were a robot and we had to track the ball's trajectory, it would be impossible to catch the ball because we wouldn't be fast enough to put, you know, to track the ball the entire trajectory. So we do all these calculations, the linear one, the speed one, and then we think it's going to be here. right? And you can get more accurate at that. So it's, it's a, we are essentially a predictive engine. We are predicting it's going to be there, which is pretty accurate. And sometimes we miss. We don't have the, we don't have the reaction time for adjusting it last minute. If say, for example, a gust of wind comes at the very last second, you can't move that fast. Your brain can't see it that fast. So it's the same thing. And what you and I talked about in this deep conversation we had about deep learning and AI was I brought my example of Watson and the very, very first iteration of their approximation engine when they were doing— they had learned this machine learning program to take a guess whenever it had enough information that the there were 70% possibility that it was right. So essentially Watson was like, well, 70% of the data says it's this, so it just answers with confidence and says it's this, which is also the same thing we do.
Yeah, so we, we don't—
we're not 100%.
Yeah, about everything. Not— no, not about everything. And the interesting thing with machines is we can actually, we can get that estimate from 0 to 100%. We can have that be output. And so we can actually use that to our advantage then when we're building these kinds of automated systems, say in talent acquisition or in recruiting. We can use our understanding of these probabilities, just like in that Watson example that you gave, to be like, okay, this is, you know, in a medical circumstance, um, you've got to be very sure that you're, you're catching, say, a breast cancer tumor, you don't want to be like, uh, you know, it seems like there's probably not one here. You're going to err on the side of, okay, let's have a lower threshold, a lower probability threshold to make sure that— so, you know, maybe if you're only— if, if the algorithm only thinks there's a 30% chance, it's still a good time. You're like, okay, let's flag it.
Or maybe if there's a 5%, it can be really aggressive with a prediction or you can be really conservative with the prediction.
Exactly.
The same thing with these, with these models. And so what I, what I thought was a really interesting problem space and kind of got us into the next level on the conversation is, in particular, people's profiles, your bio, your resume, it's, it's extremely difficult to predict that because it's non-homogeneous. So for example, if you have a database full of resumes, if you have a folder that is nothing but resumes, there's 10 million resumes in there, you can generate some patterns, but they're not going to really necessarily be that accurate. However, you can do a lot better than if you have a database with 10 billion documents, some of which are resumes, the rest could be recipes or whatever. So the problem with Google that I've always had from the very beginning when I started using Google, you know, garage days, right, is that it's a non-homogeneous database. So there's no way to structure or categorize it. And you and I talked about how do you categorize a resume? There's an HRXML consortium that tried to make like HR standards, like this is the body, this is the— that never happened. And nobody could ever agree. There's no CV standard. There's no resume standard. So even if you had a database that's just resumes, which Nebula.ai has a database of people profiles, even in that homogeneous environment, it's extremely difficult to make these predictions. Yet this is where my mind was blown. You did. You made those predictions. I've only ever been able to do that manually. I've never been able to do that with a machine. And the example that I gave you, you wanna talk about the word cloud?
Absolutely. This was, you are easily the most sophisticated customer or prospective customer we've ever spoken to because of the things that you've been doing. So yeah, describe the way that you have been manually hacking your way into the kinds of matching that we do.
And then you'll translate it for the way you do it? Okay, good, good idea. All right. So I start with 10 resumes of incumbents, people that have done the job, used to do the job, team members, ideal candidates, people that have passed final round, etc., for the position. I need to have at least 3, 5 is better, but I always try to get 10. So 10 is my goal. If I can get, if all I can get is 3, it's like, it's not going to be that great, but it works. So let's say I have 10, then I put all 10 of them, I literally copy and paste the whole thing, being careful not to copy and paste from LinkedIn header content and footer content that's repetitive, just the resume content. I copy and paste it all into a word cloud generator that has some simple rules, like for example, um, don't merge plurals. So it says manager and managers, it counts them as two separate words, not one. So it doesn't truncate or stem, for those of you that know what that is. That's one rule. It eliminates common English language words, so it doesn't repeat the, and, September, October, November, you know, all these. So the word cloud is only picking out words that are nouns and verbs that are significant, right? And then it gives me a list of all the ones that are the most repetitive in the commonalities between the 10 documents. And here's the really interesting thing, the magic of it is, Most often, 9 times out of 10, when I do that, these words— I'll pick the top 10 words and I'll drop them into Google and I'll get resumes. 9 times out of 10, these words are completely innocuous, non-skill-specific words. And it's— so it's not, you know, Java, C++, software engineer, programming, object-oriented. It's not. It's these other words like manager, managing, software, technology, you know, whatever. It just so happens that when a resume has all 10 of these common words, it's another one of those resumes. That's the, that's the example. So I'm finding people that I've never found before because I'm not searching using the keywords that some people don't use, right? Not everybody uses it. And further, especially in technology, I used to be a programmer, um, You, when you're a current contemporary programmer, you're always learning another language or, you know, another set of libraries or whatever. The one that you're learning is the one you're interested in. The one you've mastered is the one that's on your resume. So if a recruiter calls you and says, hey, I'm interested in talking to you about a Java role, and you're like, dude, that was like, I, I'm done with Java, I'm working on, you know, um, Python now, right? And that— go, exactly. And that's not on my resume. but with these 10 words, I can find you because all the other nondescript words. So here's the thing. As a human being, if I read those 10 resumes, I don't find those words. I've always depended on the machine because it's stupid, because it doesn't think. I've depended on the machine to tell me which ones are repeated, and then I can use manager and managing and manage together because when those 3 appear, it's part of a pattern. That was the dumb way to do it, and then you guys came up with a much smarter way that is a different vector into the same problem. So your turn.
Yeah, it's interesting that you use the word vector because vectors are key to exactly how this works. So fundamentally, it isn't all that much different from what you're describing. Um, that's happening except for layers of processing.
Yeah.
So, um, so going back to that analogy that I had of the way that your visual system works and the way that machine vision systems work, where the first layer is looking for lines, second layer combines those lines into curves and corners, third layer into combinations of curves and corners. So we have more complex, more abstract shapes. And then as we add more and more layers of processing, more and more artificial neuron layers, we can have more complex, more abstract visual things in that analogy. That you can identify. Well, we could do something. You can't visualize it in the same way, but we could do the same thing with language. So we can take a job description or resume, or in our platform, the Nebula platform, you can come in and you can type, I'm looking for a data scientist in New York with 5 years of experience. However you represent the natural language, our model can take that And then we have a first layer of processing that will, in kind of the same way you're talking about manage, manager, managing, and eliminating, uh, words like, you know, in your case, months don't matter, but we're able to take those individual words.
The year might, but the month doesn't necessarily, unless you're looking for years. But yeah. Yeah. But you're eliminating all these like filler words that, you know, are, are not useful.
We do eliminate filler words. Um, it's kind of like a separate process, but once those are out and we call them stop words, Um, all of the other— actually, that is actually— it's actually interesting. That's actually talking about a way that we would have done things a few years ago, is we would have eliminated stop words. We're actually now, in the last year—
that's what, that's what Google does.
That, that is, um, although even so, there's been this shift. And this is why, you know, we came here to talk about generative AI. I'll get into that in, in a second. We'll talk about generative AI and how that's different from the way that things have been done. But let's talk about how we did matching and how Google did searching up until very recently, where you eliminate the stop words and then you take whatever words are left and you map them into, um, a space. We call it a vector space. You can imagine it as a 3-dimensional space. Uh, it looks like a cloud, like a cloud, like a 3D cloud. You can imagine it spinning in the computer. It actually typically would be hundreds of dimensions, but we can't visualize that, so let's just pretend it's 3. And you could have a location in the space where it's all months of the year. So January, February, March, they all end up together. And then nearby that point in the space, you'll find days of the week, Monday, Tuesday, Wednesday, right? Because those are also for representing time. So you kind of have this like time region.
So then you have the time region, right?
Yeah. But then somewhere else in the space, you've got programming languages. And within that programming language region, you've got an object-oriented programming language. Subregion. And within that subregion, you've got specific—
compiled and non-compiled languages.
Yeah, yeah, yeah. And so this, um, this vector space of all of the word meanings, what we can call a word embedding space, that is trained on our training data. So we use hundreds of millions of job descriptions and resumes to train the space, to train this model. And so, um, where those other kinds of the incumbent systems we were talking about might be manually creating these maps between related words or related professions, in our system it happens fully automatically. And so all of the words—
And it's self-learning. And that's the thing that a lot of other, you know, ontologies and ways to structure didn't do 'cause they had to be manually updated and manually trained. Yeah.
And so new terms come up, new technology, some new JavaScript framework for the programmer, or the word COVID. I mean, 5 years ago, that wouldn't have been an important or meaningful word in a lot of resumes, but now it is. And so our system can automatically, as these new words come up, we can assimilate it into this word embedding space. But that's just the beginning of the magic because that's just our first layer of processing in this multi-layer neural network, in this deep learning system. As you go to deeper layers, we're able to do deeper abstractions and we're able to recombine, um, the information more, um, into more complex, more abstract meanings until you can represent the whole resume. So kind of in the way that you were describing having, say, taking 10 resumes and averaging the important language from those into a location in Basically, your word count, your word cloud is kind of like what we end up at our most abstract level, at a document level. We have this same kind of, again, you can imagine it as a 3D space, but actually it's hundreds of dimensions. A region of that space will be programmers and data scientists won't be far away from the programmers. But then in some completely other part of it, there's salespeople. And then accountants are in some completely other space. And so we have this map, this high-dimensional map of all people and all the different kinds of jobs.
And connections between them.
Actually, no. That actually doesn't, that it doesn't actually factor in connections.
So like it doesn't say, all right, this is a programmer, this is a salesperson, this is a salesperson that sells programmers.
So that ends up being represented in this space not by connections, but where they are in the space. So you could end up, um, I, I don't know exactly how it is, shortest distance between two paths. Yeah, exactly. So you'd have, you'd have either, so probably within the sales region, within the sales region you'd have some subregion of salespeople who specialize in tech. Um, and so it, everything is represented by, um distance between points. You don't actually worry about, um, connections between points. Um, but yeah, so fundamentally what that allows us to do is it allows us to automatically recreate the kind of thing that you were doing with your word clouds and have it work in an automated way. And so we can be totally flexible with— somebody can come into nebula.io and they could copy and paste in one job description of the kind of person that they're looking for, Or they could paste in 10, or it could be a mix and match of like you were doing 10 people, that would also work very well, or 3 people, 5 people, or it could be a combination of job description and resume language. Or you could even, and this is something that we've just had in the past year, and so this is leveraging on the generative AI thing, is I gave this example earlier, but you could come into our platform and you could type, find me a data scientist with 5 years of experience in New York. Our now, um, so we're now using something called a large language model. So when people are using ChatGPT, um, or other kinds of generative AI models like that, the, the deep learning model that's running in the background, that's running on OpenAI servers, is a large language model. And this is essentially a very large deep learning model. So, uh, GPT-4 is rumored to have over a trillion of these artificial neurons. And so that trillion neurons allows GPT-4 to have all of the sophistication in the apparent understanding, but just very sophisticated pattern recognition that it's doing.
And it's doing what I would do by reading 10 resumes much faster and better. Because when I'm reading the 10 resumes, I don't make connections between the same words because sometimes I ignore the words because they don't seem like they're important, but the machine detects them as important, and I completely miss them.
Yeah. And so, so what's new about what's happened in the last 10 years with these large language models, with, um, with generative AI, is that with our system, with our Nebula AI system, for the first time, we are also, um, the word sequence matters. So with old versions of our algorithm, word sequence might have not mattered at all, where really was like kind of your word cloud system system happening in this vector space embedding way, but fundamentally very similar to what you're doing. Now we have the ability for this, and the way that the generative AI system works, it has something called attention. So it's able to, just like when you read a paragraph and say it's an email from a client of yours and, you know, it starts off with, "Hi Shelly, how you doing?" You kind of just ignore that right away. You're like, you get into it, it's like They're like, hey, I've got this new role that I'm trying to fill. It's a software engineer. They're in New York. They're gonna need to have 5 years of experience. So there's those specific terms like New York, software engineer, 5 years of experience that you're going to attend to specially. And a lot of the email is just kind of, you're just gonna ignore it otherwise, right? These generative AI systems, these large language models like ChatGPT and like Nebula.io's current model is able to do that attention to just the really important things, and it pulls those out. And so we can automatically— we will, if somebody did that search in our platform and say, I'm looking for a data scientist in New York with 5 years of experience, we will use that to automatically apply filters so that people must have 5 years of experience, they must be within a certain radius of that geographical location of New York, and then we'll use a separate generative AI model to take this, whatever small amount of information you give us. So in this case, all I said was data scientist, but we will use that to generate the most kind of generic data scientist skills, related job titles, a bit of natural language description. So we'll build that out into a chunkier, like, paragraph that's rich with lots of skills and relevant job titles.
And then it's like one of the things that we do with ChatGPT in recruiting is we go to ChatGPT, give it a term, and say expand, and then it gives you a list of exactly that.
Exactly. And then we can use that expansion to do a great search instantly over all the publicly available data on people in the US and rank them for your job. So all of a sudden, in a couple of seconds, you've typed in this phrase, find me a data scientist in New York with 5 years of experience, and our generative AI models have used that to set filters for you on 5 years of experience or more, on location around New York, And we've expanded out just that term data science into a, into a larger query, which you can look at. You can see all the stuff that we generated for you and you can check that our assumptions were right. But then we, we rank everyone who meets your filter criteria in the US for your job instantly. And, um, so there's tons of different ways that generative AI is powerful here. And, and, and just as another example of why this nuance is so powerful is that let's say you didn't just write data scientist. Let's say you said data scientist with machine vision experience. Now all of a sudden, the way that we expand, like you were saying there, it can be more targeted to that thing you were looking for. So if you provide us, the more information you provide us, every little bit makes it, yeah, obviously we can do better on our search, but we can give you a great result just on the information you provide by expanding and guessing what you might like us to look for.
So this guessing engine based on a corpus of data, in your case, a corpus of data on profiles and people, which is homogeneous to a certain degree, becomes more and more accurate and more and more able to do what humans would already be able to do, but extremely fast. And it's starting to do things that humans can't do because they miss some of those details, 'cause we're predicting where the ball is going and got distracted by the tiger that's jumping at us, you know? So, but so that's today, all right? Two things, tell me what's not possible. That people think is put. So tell me where people are wrong or their expectations are off. What is not— what can't you not do? What can you not do now is one thing. And then I also want to talk about what, um, is near— what is going to happen, you know, what's next, right? But let's talk about what you can't do right now. What's not— what's a myth?
Yes. So generative AI systems, at least ones that are publicly available today, are not able to do— like, the most sophisticated AI systems that we have today at the time of us doing this livestream are publicly available ones: GPT-4 by OpenAI, Claude by Anthropic, Gemini by Google. And in terms of open source, the closest contender to those three is Llama 2, which was open sourced by Meta. And so those kinds of models, those are the most sophisticated AI systems that we have today for dealing with natural language, uh, for, you know, that are able to output text. And that text can be natural language, it can be code, but regardless, that these are the most advanced AI systems we have. And going back to your point like half an hour ago about how it isn't really artificial intelligence, all that these systems are, are very good Next word predictors.
Yep.
So they aren't fill in the blank reasoning. Yeah. They're just, it's, it's autocomplete reasoning.
Oh my God. That was the word I got stuck on at the beginning of the show. That's right. These AI systems cannot reason. That's the word. Yeah. Yeah.
They don't reason. They just predict the next word and they're amazing at it. So because like, say GPT-4, which is very useful.
It's very cool. It's very helpful, but it's super useful. It is what it is.
So there are rumors, and you can check out, um, of my podcast, I did an episode on this, this algorithm called Q*. Have you heard of that, Shelly? No. Um, so episode number 740 of my pat— of my podcast, uh, which was released on December 15th, so Super Data Science Podcast episode number 740, I talk about this algorithm called Q*. Now, Q*Star, this is a step in the direction of being able to reason, and it's rumored to be so powerful that, that it potentially played a role in Sam Altman being ousted from OpenAI because the board of directors at OpenAI, they actually— the way that the remit was going into his ousting, they were responsible for society at large, not for shareholder value. And when the rumor is that somebody on a research team working on Q* sent results to the board, and supposedly that might have been a factor. I don't know, there's lots of rumors, but that, you know, a couple of weeks before that, Sam Altman was in a public talk where he said, a few times in my career, I've had the opportunity of being in the room when some crazy breakthrough happens. And he was like, this happened just the other day. And supposedly that was also him seeing Q* working. And so we don't know exactly how Q* works, but that term Q* gives us a lot of clues because it relates to a specific mathematical term in this subfield of deep learning called deep reinforcement learning. And basically, through patching together some public— and there's more on this in my podcast episode— through Through making inferences from things that Google— sorry, that OpenAI have published on, we can infer that the way that this Q* algorithm probably works is that it goes step by step through a problem. So with a mathematical problem, for example, this is easiest to, to, um, to break into parts. They, they created a data set of, um, hundreds of thousands of step-by-step problem, uh, step-by-step steps through solving a mathematical problem. And, um, and so with these hundreds of thousands of steps, you can then say— you can say to the algorithm, okay, here's a math problem, you know what the right answer should be. Um, and an existing large language model today, with its predictions, it's not going to be able to, for a sophisticated math problem, be able to guess that answer. But with this Q* process, what it does It's still using a generative AI model, but it does it in very short steps. So you, you break the mathematical problem into a sequence and you say, okay, the first sequence, let's try it a bunch of times and then we'll take what is probably the best answer at that first step. And then let's try the second step and get the best answer there. So this is starting to go in the direction of more like what our human reasoning is. And so this is very exciting research. I don't know, we might even see something in 2024 publicly. Locally that is in the step of this reasoning, but still in 2024, at least, I can't say for 2026, but in 2024, we won't have a machine that is able to do all of the kind of reasoning that a human can do.
Yeah, that's what people usually think of when they think of artificial intelligence is a machine that can essentially reason or think for itself. So it's just literally a matter of semantics. We're calling it something that it isn't. I like machine learning. I like large language models because that makes sense and I understand it. But for common vernacular, people just want to say AI and really mean generative AI. So we now know what the limitation is with it. It's not going to think for you. And on the show, we've had guests that have given us very good examples of what you can and shouldn't do. Probably the best Kat Kibbon was probably the person who best described the easiest, fastest way to get to how to use these generative AI systems, which is you either want to use them to get an idea, so you brainstorm. It gets you 30% of the way there from 0 to 30%, and then you take it from there. But it can only help you brainstorm a bunch of ideas based on these patterns. It's not going to create the whole solution for you, doesn't think. Or Kat said, you do the last 70% where you have something that's 70% done and you use generative AI to clean it up, do things like expand or change the tone, things like that. That's the difference. It's a good place to start and it's a good place to end, but it's not a good place to do the whole thing. Kind of how she described it.
Exactly. So the episode of my podcast that I released today— so we release 2 episodes a week, um, and so we release them on Tuesdays and Fridays. Tuesdays tend to be long, uh, they typically tend to be interviews. Fridays are shorter interviews. Sometimes they're just me going deep into a topic. And in today's episode, number 748, um, in that episode I talk about these kinds of levels of AGI. So Um, this is, um, I'm summarizing research from Google, but they broke, um, AI capabilities into 5 levels, and they define level 1 as emerging AGI, where the AI system is equal to or somewhat better than an unskilled human, um, on a very broad range of tasks. And so all those models that I talked about earlier GPT-4, Llama 2, Gemini, Claude by Anthropic. All of those models are examples of emerging AI. So they're equal to or somewhat better than an unskilled human at a very broad range of tasks. Those same systems are also what they would consider level 2, but not level 2 generally, level 2 narrow. So at each of these 5 levels, They say, is there, you know, let's break it into generalized versus narrow. And so these generative AI systems that we have today, they are level 1 emerging level generally. And like those examples that you just gave at things like brainstorming, they are competent, they're level 2, but narrowly. So, um, they define level 2 as at at the level of at least 50% of skilled adults. And at things like brainstorming, absolutely. When you use ChatGPT, especially GPT-4, you're going to get brainstorming that is above the 50% of skilled adults, but just on that one narrow task. And so, um, I think that this is kind of an interesting way of thinking about where we are. Um, and it's, it's, it seems like it's still gonna be some way to go to their level 5 on general applications. But interestingly, There are AI systems today that are— they're top level 5 superhuman AI on narrow tasks. Um, so it is amazing our machine systems are getting to be super powerful, superhuman, um, even if it is on just a narrow set of tasks today.
So that's the, that's the difference. That's where we're headed now, right, is what you're saying?
It's, it's— I mean, so we have today So if you think about, um, like a, like a, an Excel table, um, with 5 levels of capability, but then imagine there's 2 columns. So, um, and, and the reason, so we have those 2 columns is to break into general models that are capable on a very wide range of tasks versus narrow models that can only do some tasks very well. So We are, in terms of those general models, we're just at level 1 emerging AGI, right? But in terms of—
in the surface.
Yeah, exactly. But in terms of narrow applications, we do have today some specialized systems that are— that outperform 100% of humans on some tasks. Um, so an example of that for that narrow application area, um, Google released this out, this algorithm called AlphaFold, which, um, predicts the structure of proteins. So biological proteins that do work in your body, it predicts those protein structures from the sequence, um, the, the one-dimensional sequence of information that those proteins are made up of. And humans cannot do that, but this, uh, Google AlphaFold system can do it extremely well, extremely fast, and extremely accurately. So it is a superhuman AI system, but it is narrow AI because all it can do is that one protein structure folding task. It can't drive your car and—
A robot that can hammer nails is going to hammer nails faster, better, more accurately than a human, but don't ask it to make you a scrambled egg.
Exactly.
Yeah, that makes sense. What's in the near future then is what's really going to pop— If ChatGPT isn't really as revolutionary as people think, because essentially it's an evolution of these large language models, And like you said, neural networking existed in the '50s. And I was going to go back and say, I don't know if you remember this, Carnivore in 1998.
What is that?
A film or what? No, Carnivore was a software that the FBI used to monitor all network traffic and do mass recognition of— Surveillance. Exactly, surveillance. It was later replaced by Narus Insight, which is currently in use now, but it's the same idea. However, it's been doing the same pattern recognition. The models now are more sophisticated and better at recognizing common English tasks. They were looking for very specific terrorism, fraud, things like that. These other models are just not, they're not just hammering nails. But knowing that, what's going to be the next closest evolution now? Is it going to be— Yeah, I'll let you answer that.
Yeah. So the only thing that I've disagreed with in anything you've said on the show and anything I've ever heard you say, actually, Shelly, period, uh, was you said that GPT-4 isn't revolutionary. And for me, it is. So even though it is, even though it is—
I'm sorry, let me rephrase. It's not as revolutionary as people think. It's not like, oh my God, they invented something. It's really an evolution, not revolution.
It is. It's absolutely an evolution.
I stand corrected.
No, you're absolutely right. And so what they've done from, from GPT-1, GPT-2, GPT-3, GPT-4 over the years, they took this same deep learning idea, specifically this, um, way of, uh, putting artificial neurons together into the structure called the transformer. So the T in GPT is transformer. And so they— the transformer was invented in 2017 by 6 researchers at Google. Model and it's open source. People can use that however they want. That transformer allows the kind of attention we were talking about earlier when I was talking about that sentence, find me a data scientist in New York with 5 years of experience. It's that transformer that allows the model, the deep learning model, to attend to, okay, you know what's important here? Data science is important. 5 years of experience is important, and New York is important.
The transformer detects the, or not the, it, it, it determines the attention.
It determines the attention. It is, it is, it is a It is a neural network architecture. It is a deep learning architecture designed specifically for doing attention. And if people are really interested in digging into this, the paper that announced this transformer architecture from 2017 is called Attention Is All You Need. So I read that.
Yeah.
Yeah. So attention is right there in the title. And the case that they're making there is for natural language tasks. Attention is all you need. All you need is this one thing. You don't need other kinds of neural networks. But what OpenAI did, they didn't have— so Google had the science breakthrough with the transformer, right?
Okay.
What OpenAI did, they had an engineering breakthrough by saying, let's take that transformer idea and scale it up, the sort of GPU stuff that you were talking about. Exactly. Get, get thousands and thousands and thousands of these GPUs running billions. Ultimately now with GPT-4, now we're talking about a trillion of these artificial neurons inside many, many thousands of these transformers, maybe millions of these transformers.
But there's not a building somewhere with all that, is there? Yeah, there's a building with like all these, not all these, all these GPUs processors with it.
Oh, okay, for sure. And so that's why the partnership with Microsoft— so Microsoft took this 49% stake in OpenAI. And the reason why OpenAI needed that is because now Microsoft, with their Azure data centers, they're able to provide OpenAI with the hardware that they need for training GPT-5. Because so with each of these steps, GPT-1 to GPT-2 to 3 to 4, and now the 5 that they're training, it's an exponential step. It's an exponential increase in the number of GPUs that you need, uh, in the size of the model. And so we're just scaling up. So OpenAI were— Google had the science innovation with the idea of the transformer. Then OpenAI had the engineering innovation of let's put as many of these together as possible, see what happens. And each time with GPT-2 and then again with GPT-3 and then again with GPT-4, the researchers themselves were completely blown away by the emerging capabilities. Because you, you just don't know. And so that's what scares some people, like AI safety people who are like, wow, like what if GPT-5 or GPT-6 is smarter than all humans and we won't even know? So there's now, so there's lots of safety researchers trying to figure out what, how much compute would we need? Is it gonna be GPT-6 or is it gonna be like GPT-12 or 20?
So this, so the upper limits of that, and I'm getting really curious now. So the upper limits of that would be one of like physical logic, right? How many computer, how many GPUs can you put in a room, or how many rooms can you network together? So there is a limit.
They— it's more engineering feats now, Shelly, because with things like GPT-5 and also Google's Gemini, a big part of the engineering feat is Google's Gemini was trained over multiple Google data centers, multiplexing in different parts of the world potentially.
That's where I was going with that.
Yeah, yeah.
So the next generation— so that we're talking about beyond GPT-5, the next generation is get it out of the data center and get it into the cloud. Another term that—
Well, they're the same. They're one and the same in this case because you are—
Right. But it's no longer my building. It's now a bunch of other people's buildings. Right.
Yeah, exactly. And so, you know, so that's why only these really big players like Google, like Microsoft, maybe like Alibaba, you know, there's going to be very few companies that have enough GPUs that they can be doing this kind of training. And then also do the inference time. If you want to then use the model, it's actually, it's 99% or more of the lifetime compute of this model. It isn't the training, it's the people who then come onto ChatGPT and type queries every single time. That's going to require tons of compute too.
It's not like the processing of all those queries. Yeah.
Okay. So it still needs all of those GPUs to do the processing too. Um, yeah.
So what, um, hmm. At what point does this exponential growth become capable of being creative?
Well, so, um, I guess it depends on a definition of this word creative.
So a reason, invent, come up with something that hasn't— come up with something that isn't an omelet of everything that came before, right?
So Some people hypothesize that maybe in some way these kinds of things are even happening in GPT-4, because in order to be able to kind of build an understanding of the world, you might be requiring the algorithm to develop this kind of understanding that allows it to make some kinds of simple extrapolations about the world.
So the current understanding may potentially be coming up with predictions of something. Yeah.
So, so even though all these GPT models are doing are predicting the next word, mm-hmm, it could end up being the case that because of what they're doing in the backend, in those now trillions of model weights happening in the backend, it might be mixing together information in a way that it's predicting, although it's not, not just a word, but an idea. Yeah, potentially. So some people think that there may be a little bit of that happening and it might happen more with GPT-5 and then GPT-6.
Right. Okay. So wait, that's possible.
It's possible, but in order for it to be more robust and certainly more like compute efficient and like just reasonable economically, it's probably gonna, going to require some complete rethink of how these things work. Like the Q* example I was giving you earlier where we're breaking things down into step-by-step processes, not just generating, uh, text, but breaking things down step by step. So different— it's probably going to end up being the case that 5 years from now, it's probably maybe going to be something other than Transformers and just scaling them up that is getting us to the next state-of-the-art in AI capabilities.
We have a very important question from the audience. Um, Garrick wants to know when the singularity will occur based on—
yeah, great question. So I mean, thank you, Robert.
Kurzweil. He said it was going to be, what, in 12 years from now or something like that?
Yeah, Ray Kurzweil, uh, he— so the singularity, for people who aren't aware of it, this is when, um, we have an algorithm that is generally smarter than all humans on the planet. And so, um, not all put together, but like, because there is no—
there's no all humans thinking about the same thing possibility. So you're saying Yeah.
Yeah.
So all then, then any other human is what you're saying, right?
Yes. Uh, well, it depends who's defining it. So that is, if we go with the paper that I was, that I was talking about today on my podcast, episode number 748, the way that, um, that Google defined it, we're talking about that level 5 in the general column. Um, that would be artificial superintelligence. And so that would be the realization of It's a single algorithm that outperforms 100% of humans on a broad range of tasks, on just generally on intelligence tasks. So that would be when the singularity comes about, though there are other people, and Ray Kurzweil may be one of those, don't quote me on this, who believe that this artificial superintelligence actually could be smarter than all humans combined.
Ah, and so I looked it up. It's 2045 is his date. Kurzweil's date of when the singularity was. So, Garrick, it's 2040, 2045.
There you go. Predictions are easy, right? You got all of your 2023 predictions right.
Kurzweil's predictions have all been right. I mean, this guy's, you know, I'm not saying he's some kind of Mephistopheles or anything like that, but, but sorry, going back to John, you're saying it's possible that, you know, 2045 might be when it's smarter than all humankind, but before then, it's probably going to be smarter than a human. Sooner than that, at least in some ways, at least in the ways of predicting the next.
It's all, it's not. So this, the singularity.
So we could ask a question of the system and have it actually give us an answer that is much more general than just piecing together a bunch of text.
Yeah, but that could happen. I mean, that's supposedly this Q* breakthrough is along those lines. And so that could potentially mean, okay, maybe in, in 2024 we'll have public systems that can do that to some degree on some kinds of problems.
And so I'll start believing. Yeah.
And so this is also why for me, you know, you talked about earlier we had our, uh, our big argument, Shelly, about our biggest fight ever, our biggest fight ever about GPT-4 and whether that's a breakthrough or not. And the reason, so the capabilities of GPT-4 for me personally, as somebody who has been working. On these kinds of machine learning problems for 25 years. I was skeptical before GPT-4. So GPT-4 came out in March of 2023.
Okay. I was skeptical too. So what you're telling me is I need to stop being skeptical now.
It's me personally.
I heard it from you.
Yeah.
I was skeptical today, February 12th, February 12th.
January, January 12th.
Oh my God. January 12th. Of 2024— what the hell year is this— January 12th, 2024, at 2:04 PM US Eastern Time, Shelly has ceased to become skeptical.
Okay, well, yeah, it has been done. Anyone who knows me knows that's a huge statement and that it's true. I've infected you with my now, I guess, optimism.
Well, I was on the verge because I was like thinking about, all right, how— at what point does this prediction of text, this fill in the blank, become big enough where it starts coming up with things that are not related because that's what I was doing when I was doing the resume matching. And then your technology took that and came up with resumes I had never would have found because it found patterns that I never found, even with the same data set. So I said, here's 10 resumes of that Braze engineer. And Braze is a software package that is very, very new, and a lot of people put it on their resume. And I was coming up with bumpkiss. I mean, very, very few. And in your system, your, your system was able to match dozens of people, none of them had Braze on their profile, but they were all spot on. And they told me what I should be looking for, which is an email engineer. I didn't even know that existed. It never— none of the patterns, none of the keyword searches, none of the job— nobody anywhere ever was ever able to tell me that an email engineer existed until I was— until I read 10 resumes on Nebula and I read email engineer and all of them, I'm like Oh, that's a thing? An email engineer? I'd never heard of that. And now I can search for Braze engineers because they're email engineers.
Yeah, that's an amazing example.
It's an amazing example. And that— so that I was on the verge of not being skeptical anymore, but now we— I haven't seen ChatGPT-4 in, in enough, um, and I'm gonna have to check out this other Q, uh, Q* enough. But that— so There is, I mean, job well done, I'm convinced, which is a lot to say, but there is something, it's kind of related to what Garrick was asking about, and going back to all of the, you know, so GPT-5 using more GPUs than what's in one building, or, you know, kind of the distributed, the next exponential growth of the neural network, which is beyond the cloud. He's asking, what if we were able to leverage all the unused cycles of all the, like, my computer, your computer, my phone, all the phones, all the, all the electronic digital computing capable devices that are currently online? What if we were able to use all of those, not just specifically dedicated machines that are, that are being, you know, assigned to that?
What if—
is that possible? Could it happen, or is that not realistic?
Sorry, repeat the question one more time. My mind wandered.
Yeah, sorry about that.
It's not you, it's me.
I was going to— no, it's probably me. I was going to ask, this datacenter that Microsoft provides, the Azure datacenter, while the CPUs are computing the GPT transforms, They must be giving up computing something else. So my question was going to be, what are they not doing when they're doing this?
I mean, they're not training their own gigantic large language models.
Oh, sorry. I thought it was like, sorry, I misunderstood.
So no, no, no. So, so like Microsoft, for example, like they're saying, okay, OpenAI, you use our data centers to train yours. Right. And as far as I'm aware, Microsoft doesn't have their own internal initiative to be trying to compete, right, like Google is with Gemini.
But is that processing power being to give to ChatGPT, is it being taken from other applications, or is it just literally idle processing power that was not being used?
So, uh, we're getting into some pretty complex economics here, but this is fundamentally what you're talking about is NVIDIA's share price. So NVIDIA's share price is astronomical because everybody, whether it's the big cloud compute companies like Microsoft, Google, Amazon. It's also small companies like mine, Nebula. And there's, you know, probably tens of thousands at least of companies of, of Nebula size trying to do things with generative AI. And all of us need GPUs, in particular NVIDIA GPUs, to be doing all of this training and inference. Because remember, it's not just the training, it's also 99% or more in the lifetime of that model with GPT-4. GPT-4, it's all of the millions of people using GPT-4 that are really the cost at the most Microsoft data centers. So, uh, I mean, that's why Nvidia's share price is so astronomical because they're the only people. And so there's other people trying to get into this game. AMD is trying to also get people onto the, onto their GPU bandwagon. They're probably number, they're definitely number 2 there, but they're a very distant second, um, in the GPU race.
So I'm a machine, right? Pretend I'm a machine with a bunch of GPUs in it. Located somewhere in the middle of nowhere, and I normally am processing this kind of information, whatever it is, and then along comes ChatGPT and requests me to process their data. Am I processing their data in lieu of whatever I normally do, or do I have enough capability to process their data and whatever I was doing before, say helping a teenager win at World of Warcraft or something?
So whoever, whoever the You would have it happening on separate GPUs, but basically, okay, you know, in the case of training GPT-5, Microsoft would just have to be mindful. They'd have to say, you know, maybe they say to OpenAI, look, you can only train the model on weekends or between these hours on the weekdays, right? Because otherwise we just don't have enough processing power.
Okay, so that answers my question. It is the model is using idle time. Non-economically viable cycle time. It's not taking cycle time away from people that are paying rent for using those GPUs elsewhere.
Yeah, I mean, it's like, it's in, to some extent, I mean, like OpenAI is paying the rent by giving away 49% of the company. It's like, they are basically like, it's an allocation thing. It's like, it's an allocation. I wouldn't call it idle.
Dude, that was exactly, it is an allocation thing. You just nailed it. That's the answer I wanted to know. I didn't have the answer to that. So this chip has an allocation to GPT that used to be allocated to whatever else is now going to—
Yeah, it's new because they were like, hey, we're going to need to buy a million more of these because they're going to need to be—
But it is not multi-tenancy. It is not a parallel allocation. In other words, now I'm connecting it back to Gary Chan's question. Could you use a portion of all the processors in the world? Um, like my Mac right now, I'm on a Mac. My Mac, if I open the Activity Monitor, um, I'll tell you exactly. Yeah, it's only using, according to the Activity Monitor, it is only using, uh, third, huh, 42%. Yeah, so if it's CPU, can I give the other 60 or 50%?
You could. The problem is that it would be very, very— if you were to say, or just 5% of it, let's— yeah, so let's say hypothetically OpenAI is like, hey, you know, um, we, in order to train GPT-5, we're going to need some help. So everybody in the world, we'll pay you some kind of OpenAI token to like open up your computer to us so that we can do compute on it just like Bitcoin mining or whatever. Um, theoretically that would be possible. The problem is that that transfer time of the information would make it extremely inefficient. So part of what allows these really state-of-the-art GPUs to work well is their proximity, is their proximity. And they, even within the chip itself, they have become very specialized at having the information flow very quickly within the chip, within surrounding chips, within the data center.
And so, um, so maybe in the future, but right now they've got to be close enough together to make it economically viable for them to talk to each other.
And the people who are engineering those would be mindful to try to be using 100% of the GPU on all of those GPUs wherever they can be. So there would not be like, there would not be idle processing That makes sense.
I was kind of thinking like mining cryptocurrency, you know, how people would like leave their machine on overnight to like, yeah, you know, calculate.
It's different because where with the cryptocurrency, the problem can be solved on a single machine.
Yeah, so this is not— no, I— now I understand. That would have been like one machine solving the problem. This is, you know, and it just— so you would, you would lock up all these people's machines or have to find a way that um, you know, you could do that without. So anyway, um, yeah, that's— that definitely answers my question. Sure, what they, they're giving up essentially. So wow. Um, okay, well, so monumental occasion for me. We're definitely a little bit over time, but that was definitely worthwhile. I, I always have to— I can't leave the show or close the show out without asking my two questions that I always ask. Okay. Um, and if you haven't listened to my my show before, you're probably going to be surprised.
I haven't gotten to the end yet. Sorry about that.
Yeah, so there's two things that I like to ask everybody. First, um, what would you like listeners to think about? So I consider myself a thought provoker, so I want you to leave us with a provoking thought about what we talked about, anything else, just not an idea. Don't tell us what it is, but okay. Ask us a question.
In 2045, when none of us need to work anymore, how are you going to fill your time and get meaning from life?
If you had a microphone, you would just drop it right now. I mean, like, we could end the show there. All right. Damn, that has to be the number one— in 200 shows, it has to be the number one thought-provoking thing because it's just so— massive on a world scale. Um, all right, and the second question should relatively be easy compared to that one. Who should be our next guest?
Oh wow, so I guess, are you looking for people— what kinds of guests are you looking for?
That's, uh, I think should be our next guest. I mean, you know, don't say Bill Gates because I don't think he'll be on the show. There's got to be some reasonable expectation that they might want to be on the show.
Um, well, I might be willing to kind of roughly in our space. Um, there is a gentleman named Kian Katanfarouche. He's the CEO and founder of Workera. He's also a Stanford lecturer. And so he, um, is fairly well known because Andrew Ng is a big AI guy. Do you know him?
No, it's spelled K-I-A-N.
Uh, it's Andrew— his last name is Just NG, uh, there's no vowel. Um, and so, uh, it's a Chinese name. I probably— however, I— when I say Andrew Ng, I'm probably terribly butchering his last name, but he's a— he's an extremely famous— he's one of easily one of the top 10 most famous people in data science. And, uh, Kian, uh, lectures in Andrew Ng's Stanford course, so he was kind of He's kind of well known on the internet for that because he, um, so this Stanford course by Andrew Ng, Kian is the lecturer in that course, um, in, in many— last name, uh, Kian Kitanfarouj. Um, so he's the CEO of Workera. It's probably the easiest way to find him. Um, and, uh, he's an absolutely fascinating speaker, and his platform Workera is Yeah, specifically about helping people upskill while they stay in their jobs. So it's related to work. Somebody else that comes to mind for me is Diana Rao. And so again, I might be butchering a last name there. I'm gonna have to— I'm definitely, I'm butchering some of that because I just tried to type it name into LinkedIn. I didn't even get—
I can find it—
who I was looking for, but, uh, I'll find this. I'll find the person for you after the show. She's an extremely well-connected person in the, um, in the, uh, in, in a space in like talent acquisition because she set up a network called Veterati for finding vets jobs specifically. So it's like a platform for U.S. veterans to find employment opportunities. And, ah, um, yeah, Diana Tsai. T-S-A-I.
Got it. Perfect. Awesome. I'm gonna reach out to both of them. UpWage, that sound right?
Yeah, so now she's the co-founder and CEO of UpWage, so she's moved on from Veterati. And yeah, UpWage is her her next big thing.
Awesome, awesome, awesome, awesome. Well, thank you so much for being on the show. Uh, this has been lots of fun, very exciting. Um, and man, I, it's— I don't know what else to say.
Well, it's been great having you on. I've been looking forward to this for a couple months. We booked this a while ago, and I have been super excited to be on the show. Shally, you're a brilliant guy. I knew that from the instant we started talking, and so just to be able to share this time with you, uh, would have been enough. But to know that there's people out there listening is a super added bonus. Grateful to have the opportunity, Shelly, and I'm looking forward to the next time. Don't hesitate.
There's at least 4 people listening, I know, besides us 2, right? Um, definitely. All right, thanks everybody. Have a great weekend and be kind to yourself.
Bye-bye.
More from Shally
Scaling Talent at Hypergrowth: Leadership, AI, and Hiring Excellence with Cindy Nicola