Coding agents need orchestration, not specialization - Louis Knight-Webb, Co-Founder of bloop
Louis Knight-Webb discusses Vibe Kanban, an orchestration platform for running multiple coding agents like Claude Code and Gemini CLI in parallel. The team builds 90% of the product with the product itself, and uses features like per-task setup scripts and lightweight sandboxing to manage dozens of agents running simultaneously.
Chapters
When we started the company, the world was a very different place. There was no GPT-3, there was no Copilot even. Coding agents were moving in a way that really benefited more general purpose approaches rather than more specialized coding agents. Almost 90% of Vibe Kanban, at least certainly in the last 3 weeks, has been built using itself. It's such a great thing to be able to dogfood your product like that.
I think this is probably the tightest feedback loop in history, potentially, certainly in the technology industry. Each time you write a line of code, you're actually getting some level of feedback on the product itself. I'm here with Louis Knight-Webb. Super excited to have you on. We've known each other for years at this point. I have some very exciting projects that have come out recently. I've seen them on social media, but, you know, making the rounds on GitHub, etc. And I'm super excited to learn about your perspective on agentic development and orchestrating large groups of agents, the best practices around doing that, and what the future of software has in store for us. So I think a great way to start here is can you introduce introduce the project that you're working on recently and sort of the meandering path you've taken in order to get here.
Yeah, so how much time have you got for the meandering path? I mean, it has been almost 4 years since we started the company Bloop. And when we started the company, world was a very different place. There was no GPT-3, there was no Copilot even. And so we started with code search that became enterprise code search. So helping very large companies navigate very big code bases internal to them. That became one of our customers loading in a COBOL codebase into that code search tool, and us realizing that a lot of organizations wanted to modernize COBOL, and spending 18 months working on that problem, and building a kind of fully automated end-to-end pipeline coding agent experience, and also kind of services on top of that for large enterprise. And then realizing that actually coding agents were moving in a way that really benefited more general purpose approaches rather than more specialized coding agents. And in that world, it kind of felt appropriate to start looking at, okay, well, what is the layer above that of orchestration around general-purpose software development agents? So we have been working on something called Vibe Kanban. It's got a bit of a, I guess, controversial name. You know, it's kind of playing into the vibe theme, but actually it's just basically a way to orchestrate Claude Code, Codex, Gemini CLI, AMP, and other coding agents at scale. And what we mean at scale is the types of problems you face when You're trying to spin up hundreds of these things. The first thing is like, how do you run these things in parallel? Because if you're just doing this sequentially, you're spending a lot of time looking at CoolCode, other agents doing their thing and just reading agent logs. So what if you can move those to the background and that frees you up to then think about, okay, well, what other things could I be working on? That's a backend task. Why don't I spin up the frontend task in parallel and plan that? And oh, look, another task has finished. Why don't I go and actually review that work. And then by the time you finish with that, maybe the first thing you started has finished off. So it is a bit of context switching, but that's actually the problem we're addressing is how do you make it easy to context switch when you're juggling working with different threads going on at the same time with coding agents.
That's fascinating. So I'd love to double-click on everything related to Vibe Kanban. But first, I think a really interesting point that you brought up is that it sounds like you started working on a vertical-specific solution that somehow integrated earlier generations of models like maybe GPT-4. And in the interim since then, you've sort gone away from that. I'm curious to get your perspective. Do you think that there is a place in the ecosystem for vertical-specific solutions, even with the advent of more generalist coding agents? Or do you think everything will sort of trend towards the bitter lesson— I know that's overused— but everything will just be solved by one centralized super agent?
I think it depends on what level you're trying to compete. So for enterprises, they have a lot of requirements that are actually non-technical. So when selling COBOL modernization, we had to help the customer migrate their database, and we had to spend a pretty spent a decent chunk of time just sitting down, helping them architect, okay, well, we're gonna go from some batch system to something with Kafka and things like that. These are things that Cloak Code and other agents are not gonna solve anytime soon. They're the kind of, the complexity of a project is integration. It's not just the coding part of it. I think there's a place for companies to exist that are vertical-specific, but what are those companies using under the hood? Are they building a software development agent that calls the Chat Completions API, or are they just wrapping, you know, the general purpose models provided by the labs? I think that's maybe the tension that, you know, Claude Code has created, at least on benchmarks like Sweetbench. It kind of is like the best coding agent out there because these model providers have the ability to do much more than we can do at the application layer because they can bring things like, you know, RL into the process. And that's where most of the gains from coding agents seem to be coming from these days.
Very valid point. I think it seems to me like we have, a new primitive that has emerged, which is effectively the language model embedded in CLI that can run around on a Linux machine and execute various bash commands. And that is something that increasingly the foundation model labs want people to build on top of. Anthropic has their Claude Code SDK. I'm sure we can imagine the Gemini CLI, which is fully open source, will have something like this soon. It might end up being the case to solve a lot of the business integration challenges like you mentioned a second ago. That's going to be a separate problem. And there won't be a coding agent that is specific to doing COBOL. It'll just be the general purpose one. However, all the other businesses' challenges will be solved by, you know, some things that are external to the agent. I share that vision of the way this is going to go.
Exactly.
Yeah. Awesome. Will you show us a demo of Vibe Kanban, or is there something we can show?
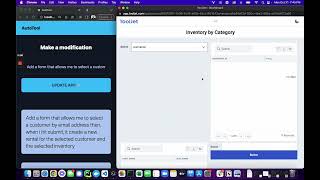
Yes. So this is Vibe Kanban, and this is actually how we have built Vibe Kanban. I think almost 90% of Vibe Kanban, at least certainly in the last 3 weeks, has been built using itself. It's such a great thing to be able to dogfood your product like that. I think it's meant that we've been able to kind of squash a lot of bugs very quickly because we discover them before anybody else discovers them. Essentially, the starting point is a familiar Kanban board that you'll be used to working in. And what we can do is create tasks. So actually, what I'm going to do first is go to the GitHub and just have a look and see if there are any issues that we can work on. So dark mode start. OK, this is one I actually opened yesterday. But we can work on this. So I noticed on dark mode, there's a glitch with GitHub authorization. I'm going to go ahead and create a task. Create task. So fix dark mode styles. The GitHub auth dialog has dark text on dark background. Please make this more readable. And what we can do is either go ahead and hit create and start, but I'm actually going to hit create task so we can see some of the configuration options that you get. First thing is there's different agents. There's Claude, which is just Claude Code. There's Claude Plan, which is Claude Code planning mode. AMP from Source which is great, Gemini, Charm, OpenCode, SST OpenCode, and then Cloak Code Router as well for people that wanna see that. Personally, I use a lot of AMP. We're gonna do this off main, and we're gonna go ahead and hit start. Now, the first thing this really does differently from running Cloak Code in your IDE or in your terminal is you can run a setup script. So what that means is every time we run a task attempt, we are essentially creating a new Git work tree. And that means that you don't end up with your dependencies. It's a clean, basically clone of your repository. So we need to run some setup scripts. I've got like cargo build, pnpm i just to get my environment set up. And then I copy some dev assets across as well. We've also got other scripts that we'll see later on. So there's the dev server script, which means you can launch a dev server really quickly from the interface in one click. And there's also cleanup scripts as well. So after my agent runs, I want it to be able to lint all of the code that it's just changed. And so I just get it to run cargo-format, but this could be Prettier or any other static lints that you've got. It's kind of similar actually to, um, Claude hooks, but I guess the good thing is that you can use it across different coding agents. So if you want to pick up something in Gemini tomorrow, those setup scripts, cleanup scripts are still going to work even though you've changed your agent. What we can do while we wait for this to load is go ahead and actually work on another task as well. And this is kind of the, the, the magic of Vibe Kanban is, is the multitasking aspect. So allow task reordering. Now this is something that we've been asked for a lot. I've already made one attempt at it, but actually the code base has moved along quite a lot since I started that. In this case, I'm actually gonna ask it to plan how to make this change, and then I can follow up, uh, and actually get it to make that change. So I'm gonna go ahead and start that, and what we can see is now we have two tasks running in the background. So I can go ahead and create some more, but at this point, I basically just need to filibuster until the agent actually completes its work.
I give a lot of agent demos as well, and I can confirm you end up having to tell a lot of jokes in that 2 or 3 minutes while you're waiting for it to iterate. Although it looks like this is a setup script that's running currently. Is that right?
It is. Actually, the slowest part is Rust at this point. Like, we've added a lot of dependencies, and I was explaining before, this, I literally went out and bought one of the M4 Max laptops, which I'm sort of in the process of switching to, but that's not this laptop. So the setup scripts are still pretty slow.
So I noticed it looks like this is running locally and I see you have the worktree path seems like it's in a local directory. So is it true to assume that all of these CLI agents are actually running on your physical machine that's sitting in front of you?
Yeah, that's right. So we can go ahead and open that in our favorite IDE, you can click on the VS Code button and that'll just take you to the worktree path. But yeah, what's happening in the background in your temporary storage somewhere, we are essentially just creating worktrees. And you can see here, you know, it's, it's just a copy of the repository as you'd find on GitHub or anywhere else. And that's like a layer of sandboxing, which is much more lightweight than running Docker on your local machine. And we did try that approach actually in, in the first instance, but after 2 or 3 task attempts, when you're building Docker images constantly, you just find that your laptop starts becoming a space heater. And so, you know, you don't get the full isolation. Callcode can still do some pretty questionable things, and it has, you know, dropped databases here and there if you give it full permissions. So it's kind of a trade-off. And I think, you know, where we'll probably end up is actually bringing in some kind of way to configure what commands Callcode can and can't do rather than having this like dangerously allow all default, which we currently do, which will improve the sandboxing there.
That makes a ton of sense. You know, it's interesting you brought this up a minute ago. So it sounds like you've built most of Vibe Kanban using Vibe Kanban itself and Claude Code and a fleet of other agents or AMP here. I think this is probably the tightest feedback loop in history, potentially, certainly in the technology industry with people building, you know, Vibe coding apps where the vast majority of Claude Code obviously is going to be built with Claude Code. You can imagine the Cursor team is using Cursor in order to build their own your own product. And each time you write a line of code, you're actually getting some level of feedback on the product itself. That's never really been the case before. Obviously, you've had previous dev tools, but the velocity at which they're moving has not been the same. I'm just curious, what's your experience been with that? Do you feel like it gives you better insight into the things that you need to fix on the product? And are there any hangups that you have or issues you run into as you use your product to build your product?
Yeah, 100%. So, what I've got here, so this is the list of closed PRs. The velocity slowed down a bit because we actually have another branch with a massive refactor going on at the moment. But essentially, Anything that is postfixed by Kanban has been built with Vibe Kanban. Probably two-thirds of the PRs that we're closing now, at least on some days, and depending on what type of issue, are being closed with Vibe Kanban. Now, I'd say I don't actually expect that we would use Vibe Kanban for 100% of tasks. There's a split between tasks where you need to be very aware of the codebase and probably be in VS Code looking at things to understand how they work because you need to have opinions about what the architecture is going to be. Then there's everything else which are small things. There's a good example here. There was a bug with the tooltip that shows whether your dev server is running or not. Let's see, it's a 73-line change. This is the thing where I don't really need to be in my IDE before the task starts. I think it's actually more efficient to let it go and run and kind of just look at the results. So I don't know what the split is, it's maybe like two-thirds to 50% of tasks probably can just happen entirely within Vibe Kanban and be completely dogfooded. And then for the other 50%, a decent chunk of those we're just doing using in-IDE tooling, you know, Cursor, CodeAMP, whatever. For things like more refactoring, that's still quite manual.
So it seems like what we're describing here is you are the daddy agent and you're sort of delegating tasks to other agents. You're moving them across the board or you're specifying the work that needs to get done in the first place. And I think one obvious implication here is that you could give, uh, AMP a tool which is create vibe Kanban task and let it sort of be its own self-orchestrator of sorts. Or you could allow it to spontaneously self-assemble a multi-agent system. So I'm curious to hear your thoughts on that. Is that where the future is going? Do you think there will always be a place for the human to be moving these tickets across across the board? How do you see it?
Yeah, so we, we do already actually have a kind of a prototype MCP server that you can add to your coding agents, and this will enable you to kind of write things in Cloak code, like, please break down this task into 10 more tasks, and, or do task management and things like that. To be honest, the human element of review is very difficult to replace, and I think that's actually the big bet with Vibe Kanban, is that ultimately the, the bit in the middle, the coding, can get much, much better and will, but the bits around the edges, like choosing what work to even get done, and I could stop sharing that, actually, and go back. The bits around the edges, like what work should even be done, has it been done to a suitable standard, that stuff that I don't think is going to go away anytime soon. And so, if we're spending all of our time, or if development time just went from 25% review and planning to 95% review and planning, it just feels natural that there should be new tools that kind of optimize that flow. And the review is really different. Review in a traditional sense is me looking at your code, but now it's like me looking at my code and, you know, you looking at my AI-generated code as well. And also tasks are being completed in 10 minutes instead of 2 days. And so the cadence is much higher. And the types of issues that you are looking for are quite different. It's like, has it been implemented in the right way? Does that button, when I click it, do the right thing? So, things like code review and code quality versus, you know, actually testing the interface, there's different expectations. I think when a human is working on a task, you actually do a lot of the testing during the process of development. And so, you know, there is a much bigger burden when you get to the end of that. So really it's about, you know, bringing everything into one place where a human can just easily see, yep, the code looks good. Yep, I ran the dev server and tested the feature out. And yeah, I've had a look at the agent logs maybe to just get familiar with, you know, why the agent chose to make that decision.
Yeah, that makes a ton of sense. Do you think that in the— I guess I'm curious to hear your timelines on how long will it be until you can actually entirely eliminate the human from the loop of inner development to develop something as significant as, say, Vibe Kanban. The agent itself will just be able to create the tickets and QA its own work and assess the positioning that it needs in order to do well on GitHub and all the other things involved in making a project of that level of substantiveness.
The one that I see all the time at the moment is DocuSign cloning. And I think where there are good examples, maybe you can already do this today. And the first thing anybody tries out when a new big model drops is, can you build a Snake game and then combine it with GTA 10? And you get some good examples of that. But that's because there's loads of precedent for those ideas. Is. Vibe Kanban fundamentally is something new. And so, really, there is no— if you think about the alignment between the model's preferences and decision-making and your own, it's actually much less aligned because when I say Vibe Kanban, it's not written down anywhere what that means versus, like, build me a Snake game where there's 50 examples and everybody knows what Snake is. So, I think for novel things, I think we're a long way off being able to really get to the next level of making great decisions. And humans are still very much needed to direct the agent, to tell it, you know, this is what I want. And it's going to get better at filling out the middle. And then we're still going to be needed for the review stage as well.
So gentle pushback on that. Vibe Kanban, it seems as though it's a combination of a couple different factors. You've got the actual Kanban board, you've got task management, you've got logs that actually stream the action of the agent as well as the environment setup and teardown and dev preview servers. All those are things that exist in App applications today. And obviously there's going to be hundreds, if not thousands or millions of examples of that on GitHub. And one of the premier capabilities of language models is sort of mixing and matching or interpolating between multiple things it's seen previously. So do you think it's true that there's fundamentally new technology required in order to build Vibe Kanban? Or alternatively, is it the case that even though all these different components exist today, a model would have difficulty stitching them together in a coherent manner?
I think that's a great point. So, uh, and this is actually like one of the biggest bits of feedback that we get from launching on Reddit and places like that, which is, why can't I just use existing project management tooling to do this? And, you know, I firstly, I would say I don't really know anybody who, you know, I don't think there's like a clear winner from the project management space that has managed to get people to work, you know, as with agents as their default. Let me rephrase that. I don't think there's a project management suite that has really won the agent integration, you know, or has figured that out fully yet. And I just think that it's actually about the workflow more than the interface. Like, yes, Kanban exists, but what has changed is the tasks are being completed in 10 minutes rather than 2 days. And so, you know, the information you need, you need a much deeper vertical integration with the work that's being done than traditionally you would have had in project management software. So, you know, instead of project management just being, here's the task and there's the description and maybe some comments, it's like, it's much more of like a fusion of what would've been in GitHub and in, you know, project management and in your IDE and in your terminal, all in the same place. And like, yes, you can kind of get, you know, language models to fuse these things together. But I don't think it's got a good intuition as to how a human would work through that workflow on a daily basis. And therefore, it's not going to make great decisions autonomously about how best to optimize that until I write a blog post about how my workflow exists. And then that gets trained into Claude 7, and then it probably can.
Yeah, well, it's interesting. I think that there are many blog posts like that online where somebody explains, this is how I work effectively with the Gemini CLI or something along those lines. A remarkably good way to figure out how people feel about something is to tell Claude, you are a 40-year-old developer sitting in the United Kingdom. Tell me about your workflow. And it ends up producing something that looks very similar to that blog post. So it's interesting to hear that you think that it would not be able to replicate the ideal sort of UX for a developer like that, despite having been trained on the entire internet of human expressed preferences.
Yeah, I just think at this point in time, everybody I meet has a different setup for working with coding agents right now. I don't think we've really converged on what the best tools are, and, you know, not just coding tools, but the stuff around it as well. And so I don't think, you know, the model is gonna try and take an average of something that has very wide distribution at this point in time. And to be honest, VibeKanban has been built with a lot of very strong opinions by our team based on how we use it. And it just turns out that tens of thousands of other people enjoy working in that way as well. And that's why, you know, VibeKanban has taken off. But I don't think it'd be obvious what that, you know, if it was if it was that obvious what that workflow is, there would be 50 Kanbans out there. But the fact that, you know, we've had the most growth is kind of representative, I think, that we have an intuition that is non-obvious, and we've executed on that.
Well, so let's talk about that. I think workflow is going to be relative to the type of work that you're doing, or it's going to change. So, if you're in an enterprise context, you're going to, you know, be using a different toolset than if you're working on, you know, Jay's very cool Next.js application. Do you have a point of view on where the right place is to start there if you're trying to be a generational company? Building a code tool and how the workflows for each of those different segments will change over time. Will it converge on something like VibeConBot, or is that not actually your ambition? And you think that you're going to focus more so on downmarket, upmarket, something along those lines?
So is this about the interplay between different levels in the kind of the, the, the AI coding toolkit, or, and how they're going to converge over time?
Sure. Yeah, sorry, I did not phrase that question particularly well. So I think that you discussed a minute ago the workflow workflow for successfully building code with coding agents has not become apparent yet, the best one. And I think that we're probably going to end up in a scenario where there's different types of work and those different types of work have ideal workflows suited to them that are actually quite different, potentially. And so for example, in an enterprise workflow, if you have a very large codebase or you're trying to migrate a COBOL mainframe for a bank or something like that, there's actually a much higher barrier to getting a pull request across the line, merged and deployed in production than if you're working on some type of a, you know, vibe-coded lovable.dev application or something like that. And so I'm curious where your ambitions lie for this project specifically. Are you going to, you know, today it runs on your computer. And so I'd imagine that the primary user is somebody who's not necessarily migrating a COBOL mainframe, you know, into a Java application. Do you think that the high watermark for what you're capable of accomplishing in something like Vibe Kanban will go up over time and everybody will adopt a flow like this? Or do you think it actually will remain quite separate workflows for people who are working on, you know, much higher barrier to merge merge codebases, they'll have a different flow than something like Bob Coleman?
I think it's a really interesting question. I'm kind of amazed, having spent a lot of time talking to big banks, how many of them have only just rolled out GitHub Copilot, right? Like, that's the level that most of these very, very large companies are operating at. They're still way behind. We talk about things like Cloak Code and other agents, but this is really valley bubble stuff, you know, a lot of the time. The reality is a lot of very large companies are still very concerned concerned about quality of code and review, and the bar is gonna be much higher. In fact, that was the big thing with COBOL, to be honest. The conversion is the easy part. Maintaining that consistency between what you've converted and the new thing is what kills these projects. You may look at 6 months to convert and then 2 years to actually test and get into production. And I think, you know, you probably see that as part of the reason why they've been so slow to adopt a lot of tools. And I think I think, therefore, so the question is, would they adopt different tools? Do the tools have to be designed to be different? I mean, very possibly. I think you probably have, like, multiple stakeholders within these large enterprises. We talked to one team at a large bank who have, like, more QA. They've got, like, 30 QAs and 20 developers working on this one team. And it seems nuts to me. Maybe some kind of specialized test automation type of software is actually what they want, rather than something that's more, like, application-specific. But to be honest, I think we're prioritizing what we can really have high conviction on ourselves. And with this kind of type of small company moving quickly, trying to adopt Claude code, you know, that type of workflow and what we can dogfood, because we just believe that, you know, we can move more quickly if we really optimize that flow. And it turns out there's a lot of people that are in that bucket. Will we one day have to figure out the enterprise version of this? This, possibly. In fact, to be honest, by the time this is out, we may have even shipped cloud. It's like, it's half working, and by the end of this weekend, it should have launched. And that's something that specifically people working within a company environment, a corporate environment, have been asking for. So yes and no.
Amazing. What are the challenges to pulling off a cloud version of this?
Many. So how do you get Claude code running on a Docker image provided by a client is our current bugbear. And then there's a load of other things just around, you know, How do you kind of sandbox these things in the right way? It's really like figuring out what the use case is as well. Is this for less technical users? I call them technical adjacent, so PMs or designers. Actually, it's crazy. Some of the emails we receive from users, if you look at how many tasks they're creating, are actually these technical adjacent roles where maybe they're familiar with React, but they're really a designer, or maybe they're a technical PM who has been building in Retool for a few years, but now they're getting hands-on with coding agents. That could be a massive market. It's kind of a funny one because it's not who we are. We're software engineers, and we built this for our use case. But the cloud version where you really, you know, you don't need to know what a Git work tree is when you're using the cloud version of this. And you don't need a file system. You just, you know, create a GitHub repo and link it, and maybe we'll have boilerplate projects as well and bring in a web browser. And so, you know, it's thinking about the user type maybe changing slightly when we go to cloud. But there's also power users as well. We had one user who, bought a massively powerful OVH box and, like, deployed the open-source version of Vibe Kanban on that. And so, you know, we'll cater to the power users as well.
Do you see a specific type of task being performed primarily with Vibe Kanban? So you mentioned earlier, maybe non-technical users, they're probably not going to be, you know, doing heavy backend logic refactoring. It's probably gonna be more something on the UI layer. Do you have any thoughts on that?
Yeah, so the tasks that we do ourselves, I would say things that are— and really, I guess the question is, like, what would you use Claude Code for today? That you would expect would take less time than if you were to do it yourself or kind of in, in some, in a more human-in-the-loop way, maybe with cursor, for example. I say those tasks are essentially the ones where you, you have already defined the interface to something and you're asking AI to do something because there's already a pattern for it. So for example, we have already got a model for projects, tasks, and configuration in our models folder. And each of those are very clear SQL queries in them. So, if I ask it to go and generate model number 4, which maybe is about users, it's gonna do a fantastic job of doing that. And if I ask it to implement the frontend and all of the routes for that, it's gonna go and do a fantastic job of that because there's already prior information about how to do that. Then there's, like, the middle ground, which is where if I ask it to do a completely new thing, like, okay, well, now let's go and implement background runners that check for GitHub pull requests to see if they've been merged. Okay, well, there's no concept of a, of a kind of a thread being spawned yet. So, I actually think there's, it's probably 50/50, it's coin flip, to be honest, as to whether Claude Code is gonna figure that out first time or not. And then there's things like refactoring, which is what I've been looking at today, which is how do we split this into kind of local and cloud and shared libraries? And I've sat there for half a day and I tried to get coding agents to do it because I hate refactoring and we couldn't get anywhere with it. So, it's gotta be fully manual. I'm not even using GitHub Copilot for that. It's literally fully raw dogging it. VS Code, unfortunately.
And so it sounds like there is actually a high watermark for you at this point of things that Claude Code or Cursor or whatever AMP are not capable of doing. And it taps out at splitting up large packages. I'm curious how you see that progressing over time, given the fact that, you know, probably around this time last year, Claude 3.5 came out. Personally, I can certainly say that, you know, Claude 3.5 kind of enabled this whole generation of zero-to-one app builders like lovable.dev, etc. That was crazy when that came out. And the fact that it actually works was incredible. And then 3.7 came out and it's like, oh, suddenly you have this thing that can take 300 steps and actually still put together a coherent pull request, even if it ends up fixing a bunch of like linter errors in extraneous areas. How do you see the competence of these things developing over time? And do you think it'll actually cap out?
I would say anybody looking at the progress progress this year or since— was it— it was Claude Sonnet 3.5 v2, which first added the str_replace. And so it was the first time we've really seen multi-tool calling coding agents really get good. And that was less than a year ago now. That was 9 months ago. So I don't know how anybody can look back at 9 months of insane progress on all benchmarks and just vibe and just using these things and adoption just going through the roof of these tools. And imagine that that's going to end tomorrow. Like, it will end at some point or it'll just become diminishing returns. But I think it can be difficult as well to visualize what GPT-10 or Claude 10 is going to do better than what these things can do today. I would say something very simple is they'll just be instant. Like, everything you can do with these models What if it just, you hit enter and instead of going and running 50 or 500 tools for half an hour, what if it just completed and you could look at the result? How would that change your development flow? So, you know, what is multitasking? And, you know, maybe you don't even need multiple agents running in the background because they're completing faster than you can even context switch. So, you know, I think these things, I think the UX will continue to develop. Develop, and these models can get a lot better, they can get a lot faster, there's evidence that they will. I'm expecting things to change.
If that is actually a reality where you have some type of, you know, coding diffusion model that within 3 seconds just produces you the entire Vibe Kanban codebase, I'm curious, how does the interaction with Vibe Kanban itself change in order to take that into account? Are there different design decisions you would make?
So, specifically, if it was instant, I think you're still reviewing a lot of work, and so you probably want to pull in roughly all the same things you did before, but you're probably not as interested in the Kanban part. And maybe I regret calling the project something Kanban, because we might be stuck with that. Maybe there's a more general question under that question, which is, how do you even build in a world where things can change that radically in a short space of time? And, you know, I used to think I think that building a company, you know, we thought about AI coding on a kind of 10-year horizon. Like our very first pitch deck back in 2021 had at some point in like 2031, users being able to type in natural language or like talk to their computer to build software. Obviously it just happens so much faster. I think taking like these very big strategic bets is really risky, especially when most of the power to really move things forward is actually concentrated in the model labs rather than at the application layer. And so focusing on what is still relevant today, what can we optimize today, and the intersection of that with what do we think will still be relevant in maybe 12 months from now, I think is a great place to be building. And so, you know, 5 Kanban, I'm very happy with the level it's positioned at and the problems that it's trying to solve, especially around parallelization today. And I expect at some point there will be, you know, these things will become instant and Kanban will be completely irrelevant because there'll be no concept of multitasking because they'll be so But I actually think that that is probably beyond the 2-year window where I really care. I can still build a massive, you know, project and solve a lot of problems in that period of time. And that's what's important to me.
Love to see it. One more question for you. Are pull requests still the right abstraction? So, forget about this idea that you could generate an entire project in 3 minutes. We're still seeing a massive increase in the amount of code that's being produced. And the GitHub pull request interface really kind of assumes assumes that you're going to do this methodical review of code. It takes a while to do it. You're going to read all of it. It seems to me like in a lot of projects, especially vibe-coded ones, which the significance of them or how substantial they are is going up over time, it's kind of a waste of time. You should probably just yeet code or merge it in and then move on to the next. And really the pull request review is interacting with the application and QAing it. And even that might actually be primarily done by models with browser use in the future. So I'm curious to get your thoughts on the PR as a checkpoint. Maybe it's still part of Git, but you just go ahead and merge it in directly. Do you think that there's a better way that we could go about actually facilitating the merging of AI code into the codebase, et cetera?
Yeah. Well, we do have YOLO mode. You can literally just merge things in and skip the whole PR process with Vibe Kanban if you want. And that, to be honest, for the first 2 weeks of Vibe Kanban's life, that was basically what we were doing, is just seeing, it was an experiment, how quickly can you build something? And we were spending zero time doing code review. But at the point at which things are now maturing, we find the velocity is kind of slowing down because of some of the code quality issues that have kind of become apparent through doing zero code review. I would say we think about this like, don't compete with what Anthropic are trying to solve themselves. And code review or making these things more accurate is obviously something that they are going to spend a huge amount of resources in. It's probably the biggest problem with, with Cloak right now is the fact that it just produces, like, pretty shoddy code some of the time. I could imagine, like, Playwright MCP, if you're not using that already, like, everybody should check that out. That's like a glimpse into the next frontier for, you know, how these things get really good at review. So when we talk about, are pull requests dead, I think mostly about, like, code review and code quality rather than the actual functional review of things. Um, and I think the agent logs is something that is maybe lacking from GitHub pull requests. So I'd love to see a summary of everything Claude Code tried to do, and especially the forking moments where it like edited a file and then like re-edited its code because it realized something, or maybe it made a tool call and then it made some kind of contradictory tool call. You know, those are the, the highlights that I want to see pulled out to me, and, and those probably map quite nicely as to where there could be code quality issues that I can go back. These models also, the, the system prompts ethical code has been published on GitHub, and people can go and look that up. But they are prompted to be pretty lazy. They're prompted to get the thing done as quickly as possible, not to create new files. And the result is you have to, like, work hard to get them to produce great quality code. And that's maybe, like, a trade-off with how long they're running for. Like, if they run quicker, maybe we can afford to have them edit more and look more at the codebase. But They make mistakes and they are lazy. And so, humans have to be able to review that code better.
I love the idea that you would somehow store or at least display agentic actions that led to the actual production of a pull request in that interface. And I think that naturally leads to this idea of potentially the agentic actions are actually part somehow of the Git artifact that ends up getting contributed to the codebase. So, you can see, here's the full thought process behind this. It would be amazing if every developer committed into a cursor/thought process document, what went through their heads as they were producing a pull request, and there's perfect documentation. I think the chain of thought that led to producing a pull request is actually arguably that. You probably don't want to have it be stored in some place that, you know, would kick off CI every time you modify that. But I can totally see a version of this where there's sort of like an additional dimension to Git that stores the thought process that led to creating some code.
100%. I think it's as important as the change itself for understanding understanding why something went wrong and how to resolve that is to see some kind of— you don't want to read through 500 agent logs, but just the highlight, the match highlights, basically, of what Claude code has been doing. So that's something we're adding to Vibe Kanban soon. And hopefully, that'll reduce the review burden for all that AI-generated, Vibe-coded stuff.
Yeah, there's this interesting idea. We call it rose tinting at CodeGen. The idea is you take an agent and you look at its trajectory or the rollout, the sequence of actions that it took. And you look at the past through rose-tinted glasses and you say, if this agent had made zero errors and it had just beelined to the solution, what would it have looked like? So it's sort of like a blemish-free agent trajectory that would have produced the same output. And obviously you can feed a Claude code trajectory into Claude and say, hey, please clean this up for me. And it will just sort of have a revisionist history version of the actions it took. I think that if you store that alongside the actual pull request, there's a huge upside in showing future agents the right way to go about doing something. So instead of just showing the code changes, you show it, here's how to go about discovering the right content in the codebase. And it should be able to potentially rag through those, retrieve previous trajectories that were successful. It's sort of consulting your ancestors to find the right way to go about accomplishing a task on a codebase.
100%. Again, I think it's just in the crosshairs of if I was PM number 1000 at Anthropic, would I be trying to build that into the core loop of Claude Code and probably into the training loop somehow as well, and 1 million percent. And so we could spend time trying to think about that and there would be a short-term opportunity, but I don't know, things move so quickly. It's difficult to compete on things like that. It reminds me of my favorite BoJack Horseman quote, which is, "If you look at the world through rose-tinted glasses, all the red flags just look like normal flags.
Love it. Well, that is a fantastic note to end on. So let's ignore all the red flags that are, you know, apparent in the, the Vibe Coding space because we're so excited about what's to come in the future. Thank you so much for taking the time to hop on with me here. Really appreciate it. And good luck. Excited to see what comes out next with Vibe Con Bond Cloud and everything else you guys are launching here.
Cheers, Jay.
Alrighty.
More from Jay
AI UX needs more innovation, right now it’s embarrassing - Jeff Huber, Founder and CEO of Chroma
Coding startups can't beat Anthropic at their own game – Harrison Chase, Co-Founder/CEO of LangChain