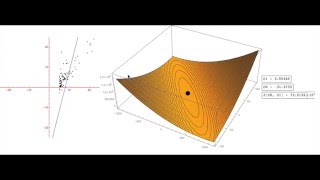
A walkthrough of how gradient descent minimizes a cost function by repeatedly updating a parameter θ using the rule θ←θ−α·m, where m is the slope of the curve. Negative slopes push θ upward, positive slopes push it downward, and when the slope hits zero the algorithm stops. Step size shrinks as you approach the minimum, preventing overshooting.
Chapters
Gradient descent. So this blue curve here is the J function, and this is for one-dimensional gradient descent when there's only one theta to be minimized. So as we change theta, as we change theta along the theta axis or this x-axis, the slope of the corresponding slope of the J function changes. All right, all right, so m is the slope. The slope, or the gradient, is represented by m. This m, it controls alpha for step size, m_alpha. The gradient, otherwise known as the slope, controls the descent, how fast the descent is, and what direction of descent. And what I'm In gradient descent, you're changing this theta. And what is the theta but a position on the, this x-axis or the theta axis? And so when the slope is negative like now, the theta goes— the theta updates positive because it's this equation. So this theta is, is updated, and the update— it's updated by subtracting an alpha, which is controlled by subtracting an alpha. [MUSIC] The size of the alpha is controlled by the slope m. So the gradient controls— so the slope controls two things. Its sign indicates the direction theta has to move. Now I'm going to explain that. So when the slope is negative, theta has to— see this little dot here? That's theta. Theta has to move up this way. And when it's positive, well, then theta gets reduced by ma, and it goes this way. And when the slope is 0, it stops because it can't update when the slope is 0. So you update it an integer number of times, like 1,500 times. And the left— for the last 500, it'll probably just do nothing because when it reaches 0, it does nothing, or it'll do less and less and less and less and less, almost 0 each time until it runs out of steps. Alright, the second part of the story is that the magnitude of the slope parameterizes or controls the alpha, and the alpha is the step size. So back to this point, and we see that the magnitude of the slope changes from minus infinity to plus infinity. And as the slope gets smaller, the magnitude gets smaller and smaller and smaller, the step size decreases.
So, whee! So, stop. So, whee!
But it will never go backwards unless you make your steps like stars.